No issue with the license, just no dedicated API at the moment but it's coming!
@maximelabonne
-
8B MoE Model Support Coming to Ollama Next Release
By
–
This is not the same model. The 8B MoE is not currently supported in ollama, but it should be in the next release.
-
New AI Models Coming Soon, Time Constraints Pending
By
–
Yes, thinking about it but finding time is the main issue. More models are coming 🙂
-
PII and LFM2 Architecture in AI Systems
By
–
It stands for personally identifiable information. More information about the LFM2 architecture in the blog post
-
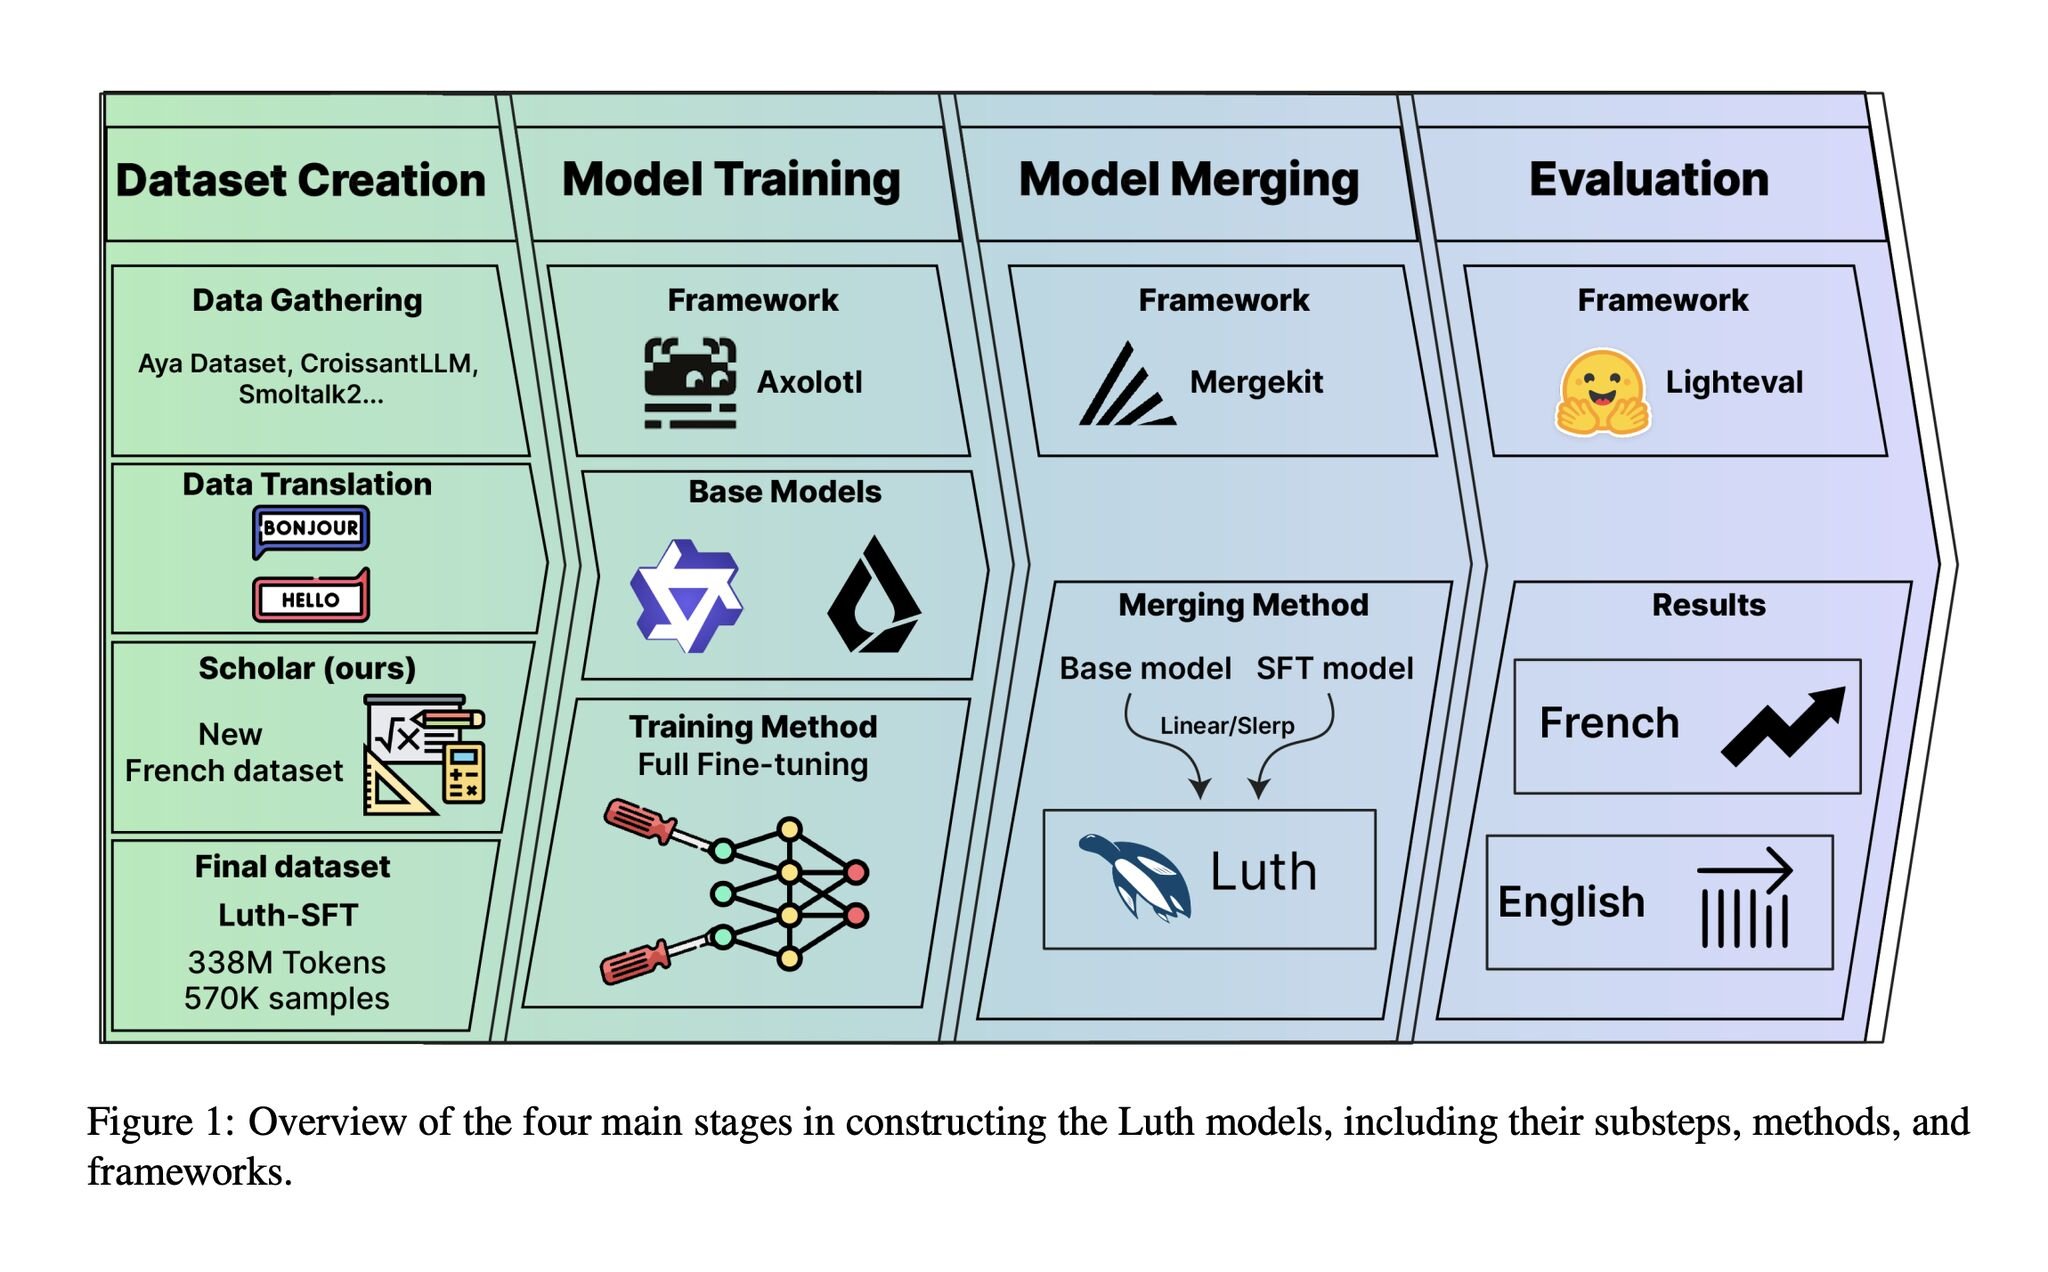
Fine-Tuning Small Language Models for French Specialization
By
–
Efficient Language Specialization for Small Language Models @maxencelsb and @SinoueG have released a preprint about their excellent work on fine-tuning small models in French. It shows a solid post-training pipeline to improve French performance while preserving English
-
Japanese LFM2 PII Extractor Released with 350M Parameters
By
–
New LFM2 release 🥳
— Maxime Labonne @ ICLR (@maximelabonne) 13 octobre 2025
It's a Japanese PII extractor with only 350M parameters.
It's extremely fast and on par with GPT-5 (!) in terms of quality.
Check it out, it's available today on @huggingface! pic.twitter.com/ojrU8SbG42New LFM2 release It's a Japanese PII extractor with only 350M parameters. It's extremely fast and on par with GPT-5 (!) in terms of quality. Check it out, it's available today on @huggingface
! -
LFM2-8B-A1B Model Available on Hugging Face with vLLM
By
–
Thanks! That's the LFM2-8B-A1B available on Hugging Face with vLLM backend
-
LFM2-8B-A1B GGUF Quantizations Available on Hugging Face
By
–
LFM2-8B-A1B and GGUF quants are now available on Hugging Face!
-
LFM2-8B-A1B: Efficient MoE Language Model Released
By
–
LFM2-8B-A1B just dropped on @huggingface!
— Maxime Labonne @ ICLR (@maximelabonne) 7 octobre 2025
8.3B params with only 1.5B active/token 🚀
> Quality ≈ 3–4B dense, yet faster than Qwen3-1.7B
> MoE designed to run on phones/laptops (llama.cpp / vLLM)
> Pre-trained on 12T tokens → strong math/code/IF pic.twitter.com/cGbuJoOMDNLFM2-8B-A1B just dropped on @huggingface
! 8.3B params with only 1.5B active/token > Quality ≈ 3–4B dense, yet faster than Qwen3-1.7B
> MoE designed to run on phones/laptops (llama.cpp / vLLM)
> Pre-trained on 12T tokens → strong math/code/IF -
LiquidAI releases LFM2-Audio-1.5B model on Hugging Face
By
–
It's also available on @huggingface to download it. You can use our user-friendly liquid-audio pip library. https://
huggingface.co/LiquidAI/LFM2-
Audio-1.5B
…