
Caching now enabled With 3 lines of code, you can now enable caching for all LLM calls This makes it cheaper and easier to experiment with changing only parts of a chain Supports both a temporary InMemoryCache, as well as a persistent SQLiteCache
@langchain
-
LangChain v0.0.38: New LLM Caching Feature Released
By
–
New in v0.0.38 Read more about this here: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_functionality.html#Caching
… @AkashSamant4 for making LLM configurations serializable, a prerequisite for this @brucehammer and @DannyHabibs for highlighting this as a valuable feature -
LLM Configuration Serialization in JSON and YAML Formats
By
–
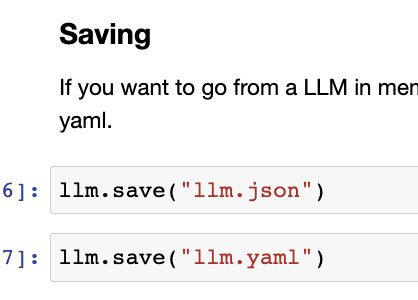
Serialization of LLM Configurations Have a favorite temperature/parameter setting for your LLM that you want store/version not in code? Now you can! @AkashSamant4 made it super easy to read/write LLM configurations to/from disk in json and yaml format
-
LangChain Documentation Updates: New Functionality and Serialization
By
–
Check out these docs for a walkthrough of this new functionality: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_functionality.html
… Check out these docs for an overview of serialization: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_serialization.html
… And of course, check out the GitHub if you want to flag an issue or open a PR! https://
github.com/hwchase17/lang
chain
… -
LLM Interface Enhancement: Extended Output with Top Results and Token Counts
By
–
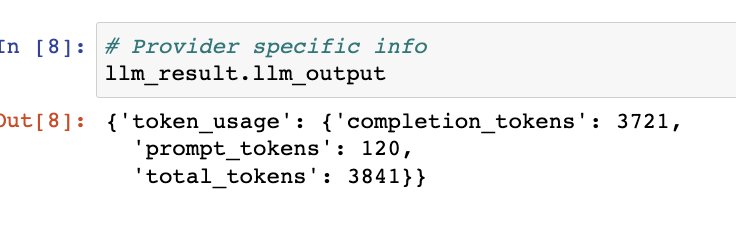
Returning extra information Previously, the LLM only returned the most likely string Now there is a new interface to return more information: the top n strings for each input, as well as LLM specific information (h/t @0xAwill for adding the token counts you see below)
-
New abstraction enables returning generation metadata like logprobs
By
–
This abstraction also opens up the door to returning more information about each generation For example, the logprobs associated with a generation (something I know @alexgraveley would love)
-
Map-Reduce Chain Speed Optimization Through LLM Call Batching
By
–
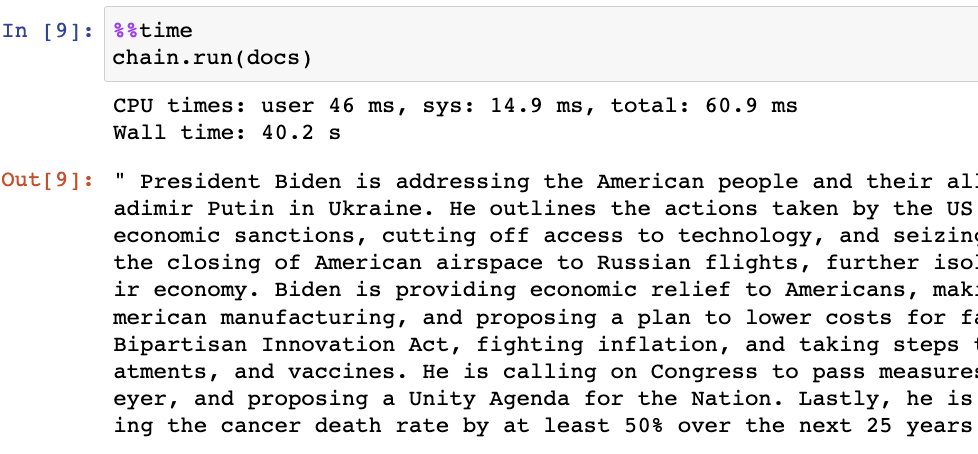
This now means that certain chains see a MASSIVE speed up. For example, the map-reduce chain can batch the map calls to the LLM, resulting in a ~75% drop in time
-
LangChain Introduces LLM Input Batch Processing
By
–
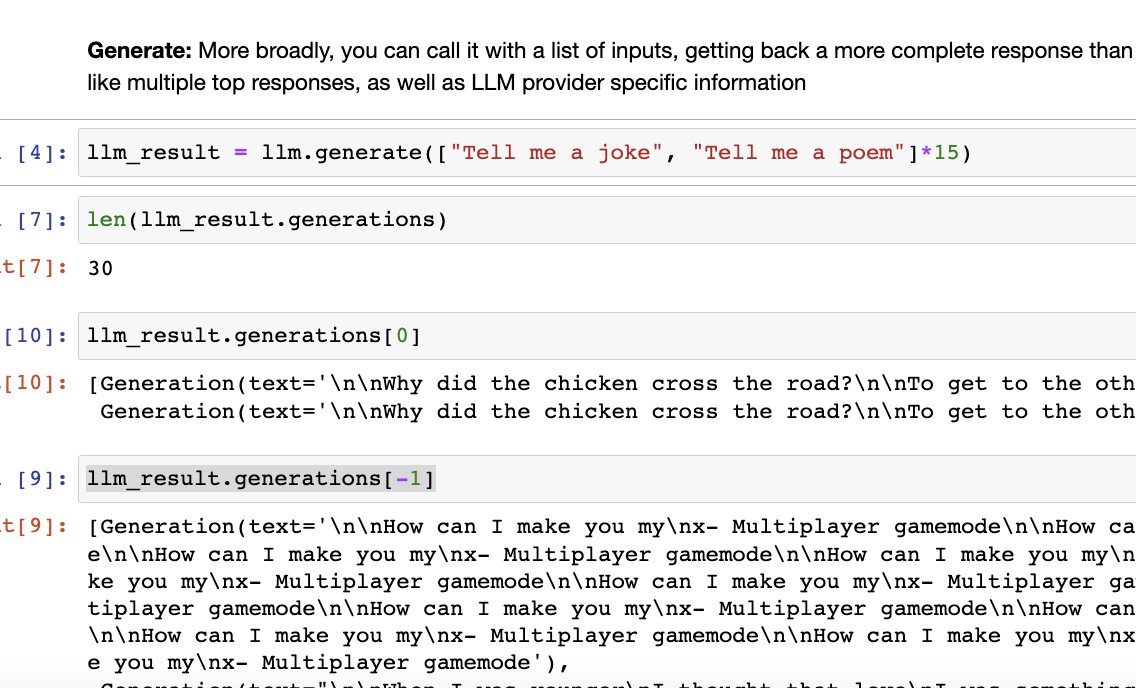
Batching of inputs Previously, the only interface for calling an LLM was to pass in a single string. With big motivation from @thepromptking, there is now an interface that takes in and returns results for multiple inputs
-
Calculating Token Count for LLM Context Windows
By
–
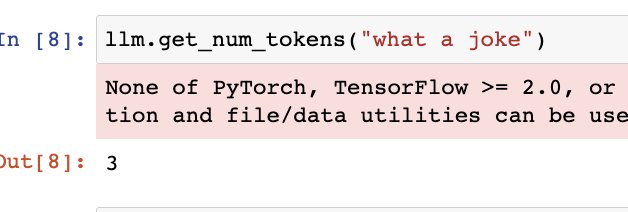
Estimating the number of tokens Each model has a context window with a certain length, where you can only pass in strings of up to a certain length There now exists a method on each LLM class to calculate the number of tokens for a string in that model
-
GPT2 Tokenizer as Default Method with Overridable Class
By
–
The default method for calculating this uses @huggingface
's GPT2 tokenizer But since its a class method, if different models use different tokenizers this can be overwritten h/t @brucehammer for implementing the logic, and then Zac on Discord for suggesting this interface