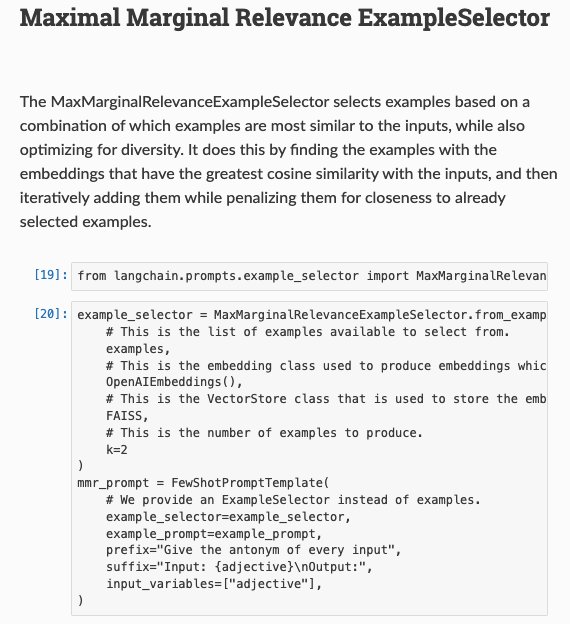
Max Marginal Relevance (MMR) Example Selector Based on this preprint by @xiye_nlp et al, the MMR example selector chooses diverse, in-context examples H/t @johnjnay for surfacing this paper Docs: https://langchain.readthedocs.io/en/latest/examples/prompts/prompt_management.html Original Paper: https://x.com/xiye_nlp/status/1603821850592628738?s=20&t=wQPcRd8IJ8URbmytuYP7QA
@langchain
-
LangChain Extends Prompt Formatting with Jinja Support
By
–
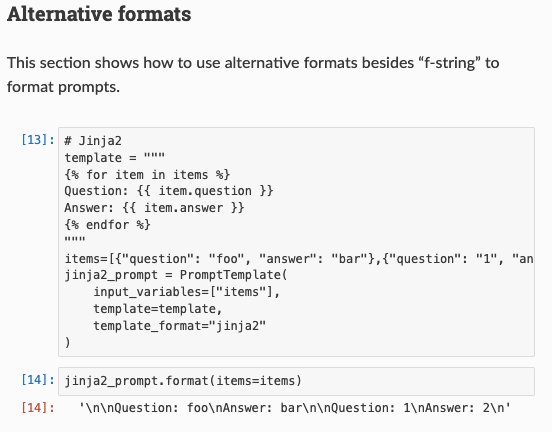
Jinja Formatting Up until now, all the formatting in prompts has been done using Python f-strings But the template_format abstraction is pretty flexible, and @benderville easily extended it to support Jinja, a more advanced formatter Docs: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/prompt_management.html#Alternative-formats
… -
LangChain v0.0.42 Release: Documentation, Formatting, and Caching Updates
By
–
LangChain v0.0.42 Doc fixes by @YouSearchEngine team, @_abi_ Jinja formatting – @benderville Max Marginal Relevance example selector (based on paper by @xiye_nlp Caching improvements (h/t @devonbrackbill for idea) These are sneaky some awesome updates, lets
-
LangChain v0.0.41 Release: Multiple Inputs, Bug Fixes, Agent Improvements
By
–
LangChain v0.0.41 Make `run` interface work for multiple inputs (
@ankush_gola11
) Bug fix for text splitter (h/t @prof_reed
) Lots of agent improvements (see ) -
LangChain v0.0.40: SQLAlchemy Cache and LLM Improvements
By
–
LangChain v0.0.40 Add generic SQLAlchemy cache – @benderville Documentation cleanup – h/t @prof_reed Some BIG LLM improvements from @YouSearchEngine team: Support for local @huggingface models Support for streaming tokens from @OpenAI
-
OpenAI Releases New Tokenizer for Accurate Token Usage Estimation
By
–
@OpenAI also released a new tokenizer This makes it possible to more accurately (and quickly) estimate your token usage This is actually extremely helpful for the `collapse` step mentioned above!
-
LangChain Updates: Tokenizer, Document Reduction, Better Embeddings
By
–
TL;DR: The new tokenizer allows easy estimation of token usage The `collapse` step allows for map-reducing over large number of documents Better embeddings allows for better searching over those documents https://
github.com/hwchase17/lang
chain
… -
LangChain v0.0.39: Document Analysis with OpenAI Integration
By
–
Analyzing documents just got a lot easier with v0.0.39 (with major assist from @OpenAI
) Added a `collapse` step into the map-reduce chain (
@johnjnay
)
Added support for @OpenAI new embeddings
Added support for @OpenAI new tokenizer Heres how they all work together -
Collapse Step for Map-Reduce Chain Scaling
By
–
Adding a `collapse` step into the map-reduce chain This recursively collapses documents into smaller and smaller chunks, allowing you to scale to arbitrarily many documents This was a @johnjnay special – see his thread for more
-
OpenAI Releases New Embedding Model for Semantic Search
By
–
@OpenAI released a new embedding model (`text-embedding-ada-002`) This makes it possible to more easily do semantic search over collections of documents This is now the default OpenAI embedding model in LangChain