Anthropic increased rate limits for all subscribers? Permanent! That was not on my bingo card!
@kimmonismus
-
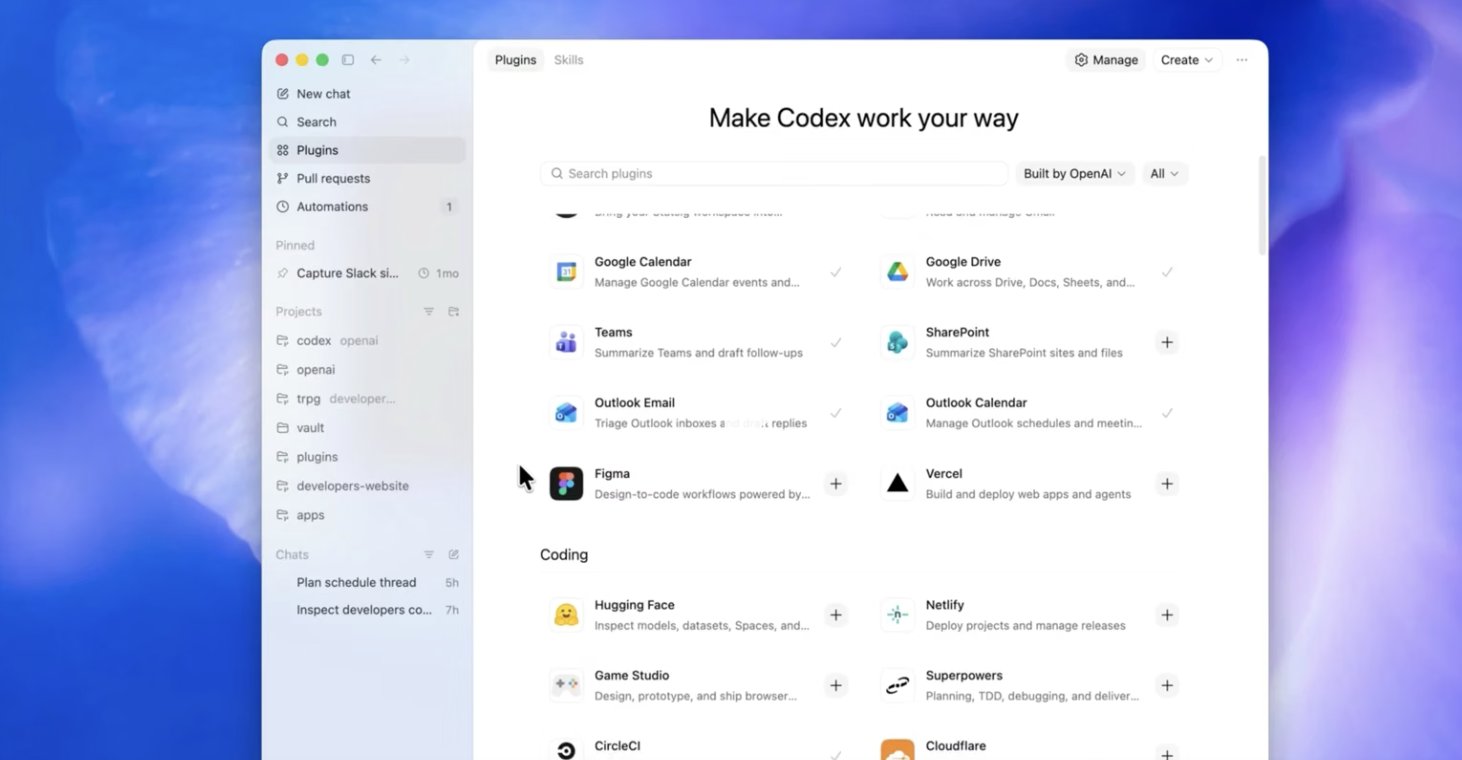
OpenAI Codex Major Update: Background Computer Use and Image Generation
By
–
OpenAI just dropped a major Codex update, one hour after Anthropic's Opus 4.7. Whats new: background computer use on macOS (Codex clicks and types on your Mac while you keep working), in-app browser, image generation via gpt-image-1.5, persistent memory, long-running
-

Opus 4.7 Performance Regression in Needle Haystack Task
By
–
Hold on, something doesnt add up here. Opus 4.7 got much worse in needle in the haystack? need to dig into this
-

Claude Opus 4.7 Released: Coding Improvements Same Pricing
By
–
Claude Opus 4.7 is out. the TL;DR Anthropic released Opus 4.7 today. Same pricing as 4.6 ($5/$25 per million tokens), available across API, Bedrock, Vertex AI, and Microsoft Foundry. What changed vs Opus 4.6: Coding (obviously). Biggest gains on the hardest, long-horizon
-

Opus 4.7 Benchmarks Show Solid Improvements Over Previous Version
By
–
Opus 4.7 Benchmarks out! Very solid upgrade to Opus 4.6! Compared to Opus 4.6: -SWE Bench Pro +11%
-SWE Bench Verified +7%
-Terminal Bench 2.0 +4% The benchmarks are significantly lower than for Mythos, but that was to be expected. h/t for finding @synthwavedd -

Google partners with Pentagon to deploy Gemini AI
By
–
Google joins the Pentagon club. Three labs, three very different deals. The Information reports Google is negotiating a classified AI agreement with the Pentagon to deploy Gemini in secure environments. A full reversal of the 2018 Project Maven walkout. The three-lab picture:
-

Alibaba Qwen3.6-35B-A3B Sparse MoE Model Released
By
–
Alibaba released Qwen3.6-35B-A3B today. Big jump compared to Qwen 3.5-35B model. It's a sparse MoE, 35B total params, only 3B active. Natively multimodal, thinking and non-thinking modes. Hardfacts:
SWE-bench Verified: 73.4, near dense Qwen3.5-27B (75.0), way ahead of -
EU Verification App Criticized as Disaster, Internet Freedom Concerns
By
–
Being independent allows you to speak critically about things, even if they might not be well-received. And I remain independent.
— Chubby♨️ (@kimmonismus) 16 avril 2026
Therefore, I say quite frankly: the EU verification app, in its current form, is a disaster. And I am against further restrictions on the internet… https://t.co/qxPlBLg5P6Being independent allows you to speak critically about things, even if they might not be well-received. And I remain independent. Therefore, I say quite frankly: the EU verification app, in its current form, is a disaster. And I am against further restrictions on the internet
-

Gemini 3.1 Pro Leads METR Time Horizon Benchmark
By
–
New METR time horizon leader: Gemini 3.1 Pro. On METR's time horizon benchmark (80% success rate (!)), Google's Gemini 3.1 Pro now handles software tasks that take humans 1 hour 30 minutes on average. 95% CI ranges from 52 minutes up to 2 hours 39 minutes. Average score: 77%.
-

Apple Sends 200 Siri Engineers to AI Coding Bootcamp
By
–
Apple just made a quietly stunning admission: its own Siri engineers need to go back to school. According to a report from The Information, the company is sending close to 200 members of the Siri organization to a multi-week bootcamp, where they will learn how to code using AI