
Opus 4.8 is live. Benchmarks especially significant jump in Agentic coding, but more important: „Fast mode is available for Opus 4.8. It's the same model at roughly 2.5x the speed, and we've made it three times cheaper than before.“

By
–
Opus 4.8 is live. Benchmarks especially significant jump in Agentic coding, but more important: „Fast mode is available for Opus 4.8. It's the same model at roughly 2.5x the speed, and we've made it three times cheaper than before.“

By
–
Microsoft is launching homegrown AI models at Build next week, positioned as cheaper alternatives to OpenAI and Anthropic. Buried in the reporting: relying on Anthropic's Claude forced Microsoft to raise GitHub Copilot prices and cap how much developers could actually use it.

By
–


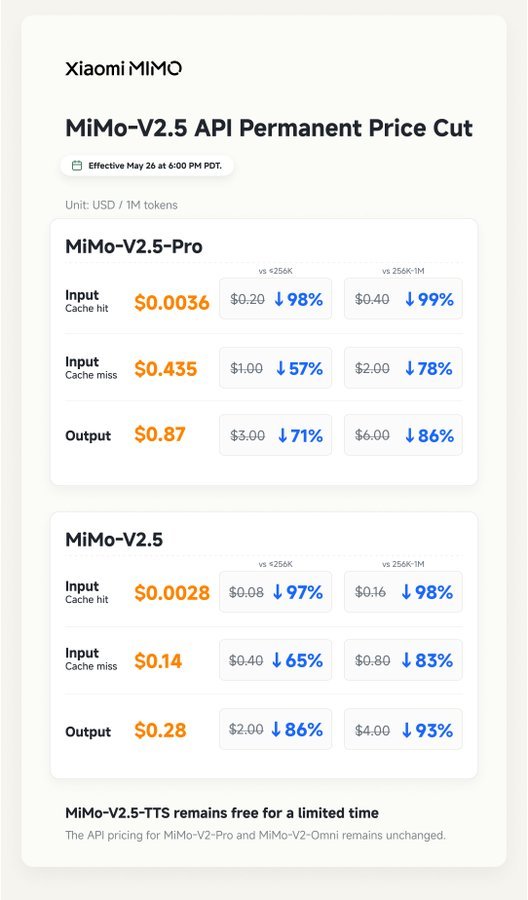
DeepSeek just made its 75% price cut on V4-Pro permanent. Xiaomi's MiMo slashed V2.5 pricing by up to 99%, effective today. Most coverage frames this as a price war. The more interesting part is the engineering that makes these numbers sustainable. DeepSeek's V4 paper describes

By
–
Demis Hassabis now says AGI could arrive by 2029, a year earlier
than his previous estimate, and told Axios we're standing in the
"foothills of the singularity." Bold claim. But the field still can't agree on what AGI actually
means. Hassabis defines it one way, Altman another,
By
–
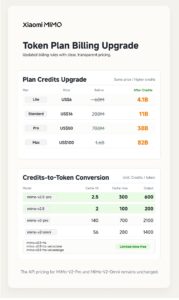
MiMo 2.5 Pro now costs the same as DeepSeek V4 Pro. The cost of good models is falling at breakneck speed. Intelligence is becoming truly too fast to measure. Up to -99%
By
–
Erdős problem #90 has been open for decades. Over the weekend a mathematician tested whether Claude Mythos could solve it. It did. But what caught my attention: Mythos didn't replicate the known approach from OpenAI's #1196 solution. It repeatedly settled on a different
By
–
MiniMax just teased their Sparse Attention architecture for M3. The benchmarks show 9.7x prefilling speedup and 15.6x decoding speedup at 1M tokens vs M2. MiniMax deliberately went back to full attention for M2 because efficient attention wasn't production-ready. Their pretrain

By
–
I'm not sure if Google is winning the AI race. However, I think they're winning the AI distribution race, which is a different thing. 900M Gemini users is impressive on a slide. But a huge chunk of that is Android users who got a default app swap and Search users who got AI
By
–
Uber burned $3.4B in AI budget in 4 months.
— Chubby♨️ (@kimmonismus) 26 mai 2026
Microsoft is cancelling Claude Code licenses company-wide.
The root cause is the same: no routing layer between the request and the model.
Build Your Own Router lets you match every request to the right model based on your own… https://t.co/5IwiuXAR5R
Uber burned $3.4B in AI budget in 4 months. Microsoft is cancelling Claude Code licenses company-wide. The root cause is the same: no routing layer between the request and the model. Build Your Own Router lets you match every request to the right model based on your own
By
–
I do use structured prompts, plan/goal mode, Notion context, and a few local reference docs. Memory is involved. Could be instruction/memory interference. I’ll try a clean run without persistent context and see if it changes the behavior. thanks!