How small? Probably not small enough 100M and 1B models
@karpathy
-
LLM Agent Solutions and Training Data Contamination Concerns
By
–
my biggest concern is that an LLM Agent can solve it in 1-2 years but by then related forks and code and discussions seep into its training data in an undefined way, making the result unsatisfying.
-
LLM Agents Challenge: Porting PyTorch GPT-2 Training to C
By
–
Btw writing the llm.c training code would imo be a very interesting, impressive, self-contained and very meta challenge for LLM agents. The prompt is: Take the PyTorch code train_gpt2.py
And write, compile and unit test a single .c file that reproduces the training: train_gpt2.c -
PyTorch Layers Migration to C: Tutorial and Implementation Guide
By
–
I added a quick crappy tutorial on how PyTorch layers are moved to C, with a few possibly helpful pointers: https://
github.com/karpathy/llm.c
/blob/master/doc/layernorm/layernorm.md
… -
Llama2.c translations and broader training design possibilities
By
–
😀 😀 I really do love how llama2.c was translated to a zillion languages I've never heard about. Looking forward to that with the training too! The design space is a lot wider too because you can train stuff, not just inference a fixed, given thing.
-
Forward/Backward Implementation Complete, Now Optimizing with CUDA
By
–
Once you have the forward/backward, the rest of it (data loader, Adam update, etc) are mostly trivial. The real fun starts now though: I am now porting this to CUDA layer by layer so that it can be made efficient, perhaps even coming within reasonable fraction of PyTorch, but
-

Memory Allocation Strategy in LLM Training Implementation
By
–
You can look at the raw training implementation here: https://
github.com/karpathy/llm.c
/blob/master/train_gpt2.c
… You'll see that we allocate all the required memory a single time in the beginning in one large block of 1D memory. From there on during training, no memory gets created or destroyed, so we stay at -
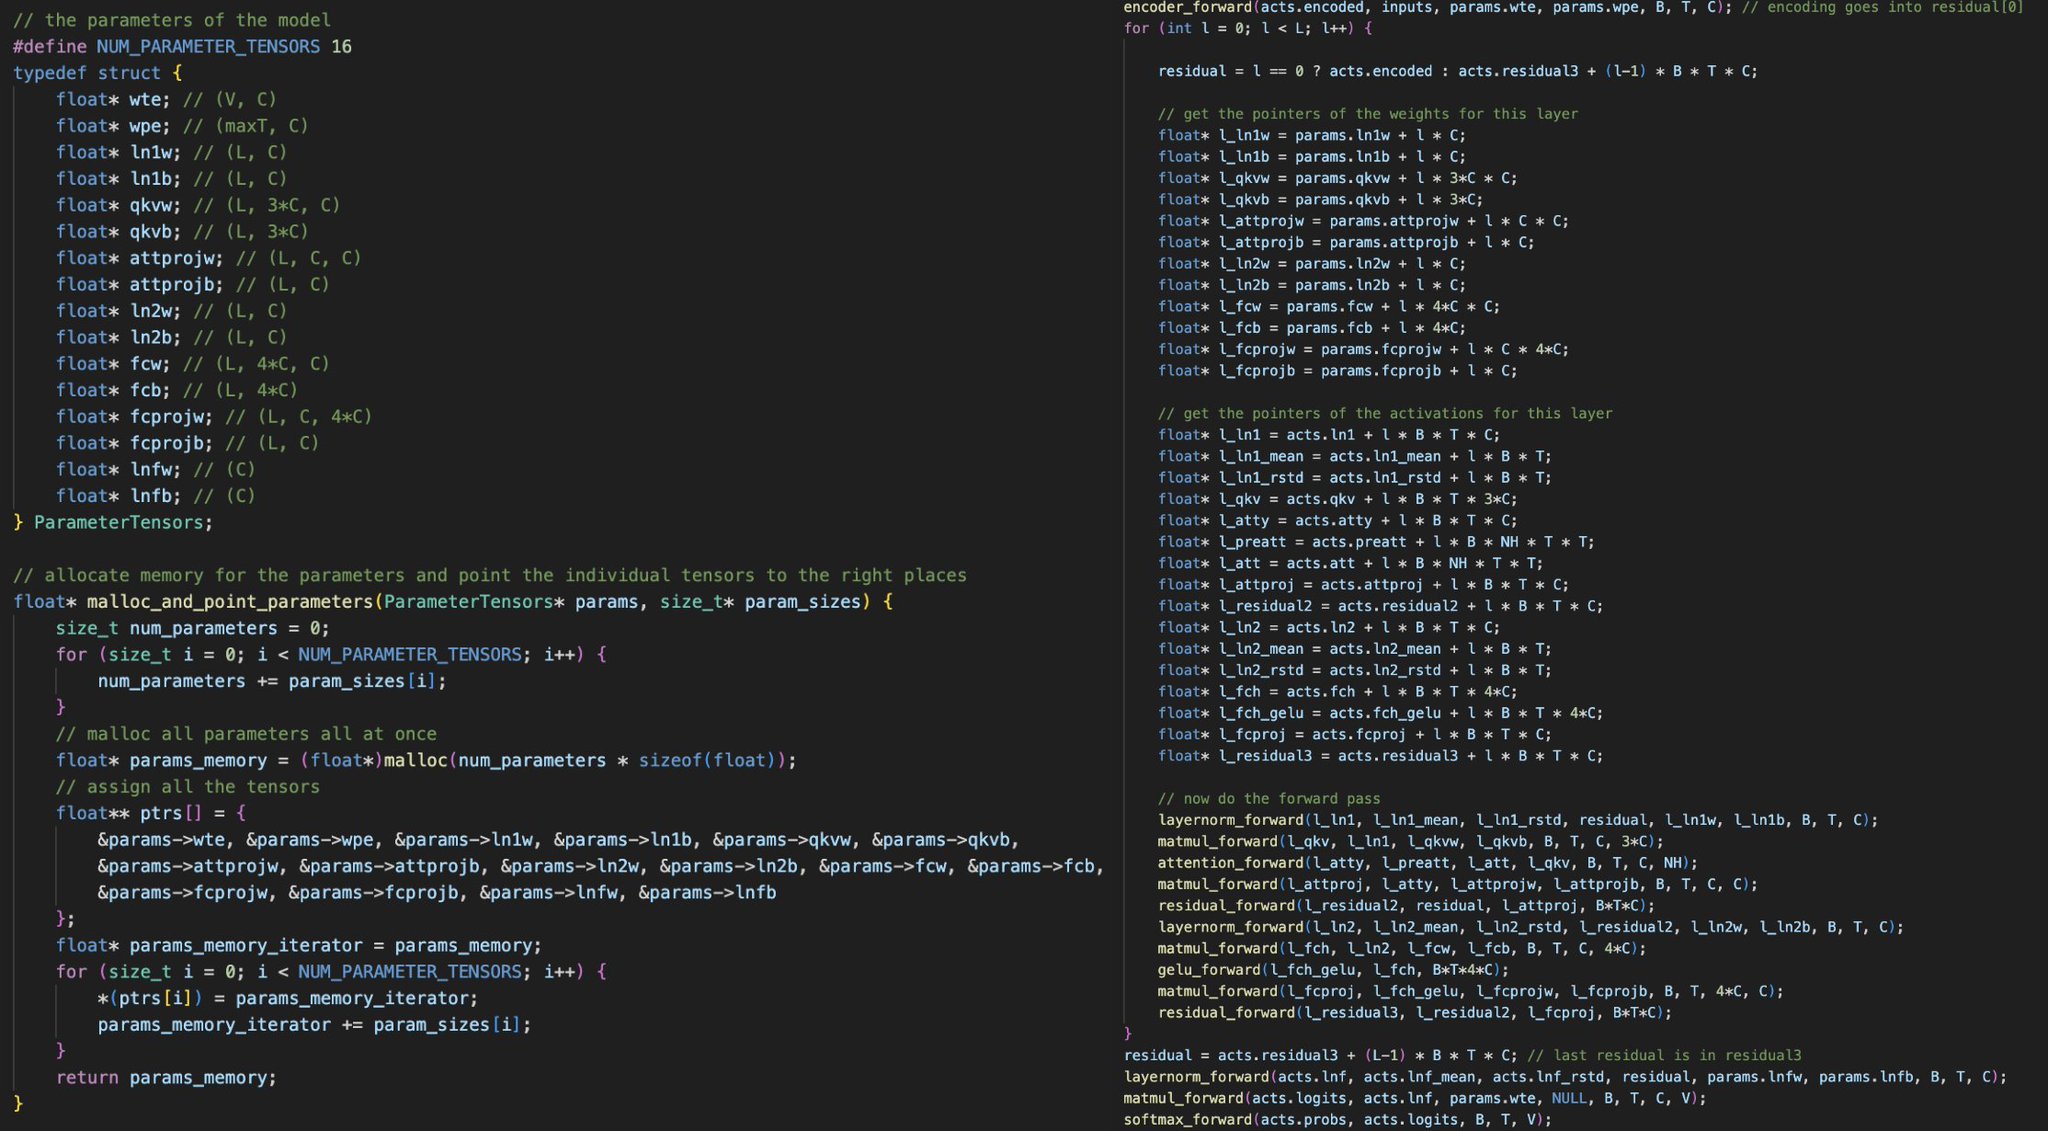
Implementing Neural Network Layers with Memory Pointer Management
By
–
Once you have all the layers, you just string all it all together. Not gonna lie, this was quite tedious and masochistic to write because you have to make sure all the pointers and tensor offsets are correctly arranged. Left: we allocate a single 1D array of memory and then
-
llm.c: Train GPT-2 in Pure C Without Heavy Dependencies
By
–
Have you ever wanted to train LLMs in pure C without 245MB of PyTorch and 107MB of cPython? No? Well now you can! With llm.c: https://
github.com/karpathy/llm.c To start, implements GPT-2 training on CPU/fp32 in only ~1,000 lines of clean code. It compiles and runs instantly, and exactly -
Terminal Upgrade on MacBook: AI-Native Tools and Workflow Integration
By
–
Yeah that’s my default Terminal on my new MacBook now. So far great upgrade. A lot of what makes VS Code so great, and AI native.
Very eager to upgrade a lot of tools. AI unlocked a ton of potential but no one wants to copy paste things around. You fall back on it if you have to