The race for LLM "cognitive core" – a few billion param model that maximally sacrifices encyclopedic knowledge for capability. It lives always-on and by default on every computer as the kernel of LLM personal computing.
Its features are slowly crystalizing: – Natively multimodal
@karpathy
-
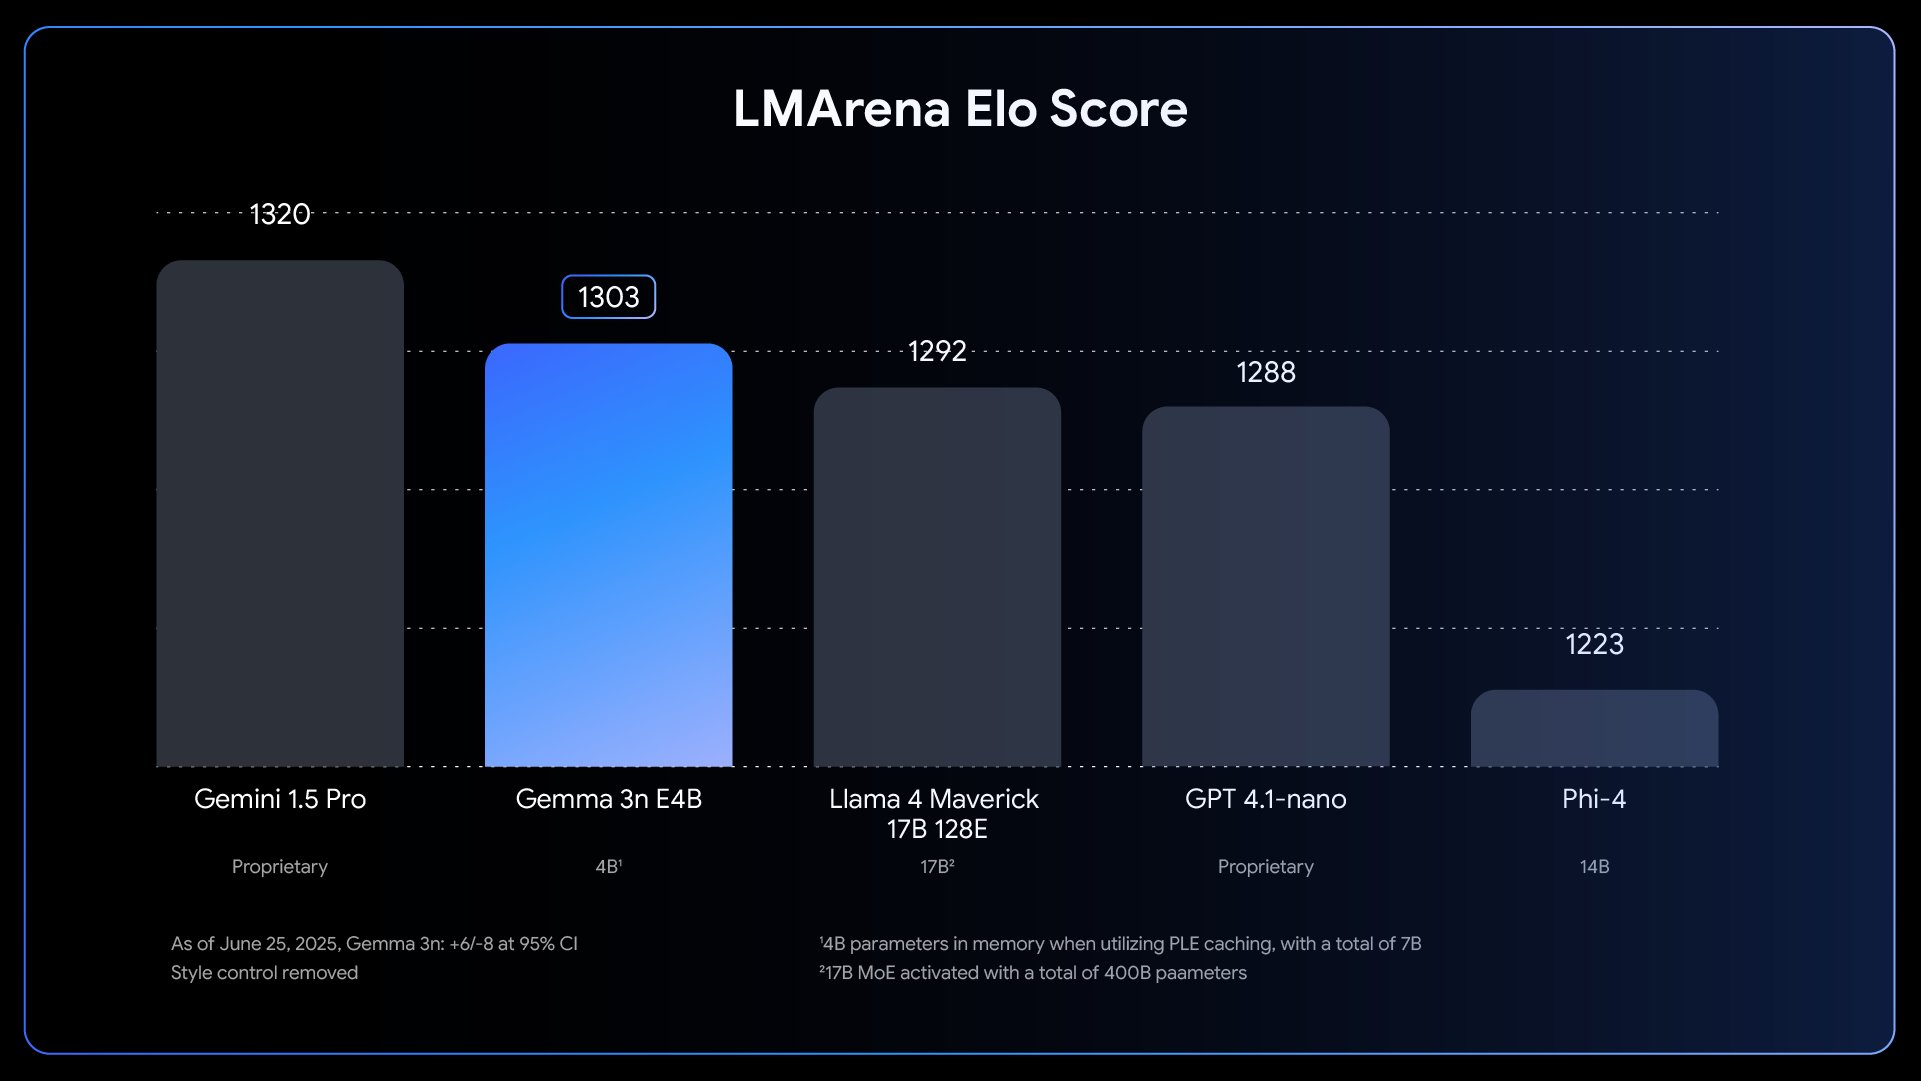
The Race for LLM Cognitive Core: Always-On Personal Computing Kernel
By
–
-
Preference for Scalable Turn-the-Crank Algorithms with Increased Compute
By
–
I sometimes try to explain it as a statement of preference for "turn the crank" algorithms. When you're eventually given more compute (faster crank), you shouldn't have to touch anything at all, you just crank faster to make better. You can (and probably locally should) knowingly
-
Strong Regularization Prevents RLHF Model Degradation
By
–
May your regularizer be strong, lest you RLHF to slop.
-
Distinguishing between simple prompts and complex application contexts
By
–
Haha I'm not trying to coin a new word or something. I just think people's use of "prompt" tends to (incorrectly) trivialize a rather complex component. You prompt an LLM to tell you why the sky is blue. But apps build contexts (meticulously) for LLMs to solve their custom tasks.
-
Context Engineering Over Prompt Engineering in Industrial LLM Applications
By
–
+1 for "context engineering" over "prompt engineering". People associate prompts with short task descriptions you'd give an LLM in your day-to-day use. When in every industrial-strength LLM app, context engineering is the delicate art and science of filling the context window
-
Data Quality Tradeoffs in SOTA Model Training Datasets
By
–
I'm not 100% sure about that. As an example I was just browsing through the DCLM-baseline datamix (which is ~SOTA) and it is *terrible*. Compared to what I could in principle imagine. Major concessions are made in data quality to gather enough data quantity.
-
The Quest for Ultimate High-Quality Pretraining Data for LLMs
By
–
Mildly obsessed with what the "highest grade" pretraining data stream looks like for LLM training, if 100% of the focus was on quality, putting aside any quantity considerations. Guessing something textbook-like content, in markdown? Or possibly samples from a really giant model?
-
AI-Generated Image: Golden Gate and Lavender Field by Ideogram
By
–
AI generated sorry to disappoint. Ideogram took it. I asked for Golden Gate (as the event is in SF) and lavender field (because I like lavender).
-
Humanity’s Irrelevance: Deep in the Amazon of Cosmic Possibility
By
–
Something like this feels quite likely. That we’re a random ant colony deep inside the Amazon forest crawling around like “where is everyone???”. The depth of our explored tech tree is so shallow compared to what feels possible. We’re probably really, really irrelevant.
-
Job as Bundle of Tasks and Glue Variables
By
–
Very interesting to think about. Job = bundle of tasks + glue. Probably a bunch of other variables involved, e.g. the number of tasks, how long each task is (e.g. METR-like notion of task length ~= difficulty), how contextual it is, how high reliability it needs, whether it can