Thank you! I'm quite happy with the core_eval.py rewrite. I wanted to evaluate my base model with the DCLM "core score" as described in their paper, but what felt like it should surely be a simple thing of ~300 lines of code actually required me to pip install and depend on a
@karpathy
-
90s Living Movement: Rejecting Post-2000 Technology Adoption
By
–
There is a movement I found on Instagram where people delivery choose to live in 90s, refusing all technology after 2000. Like an intermediate form of the Amish.
-
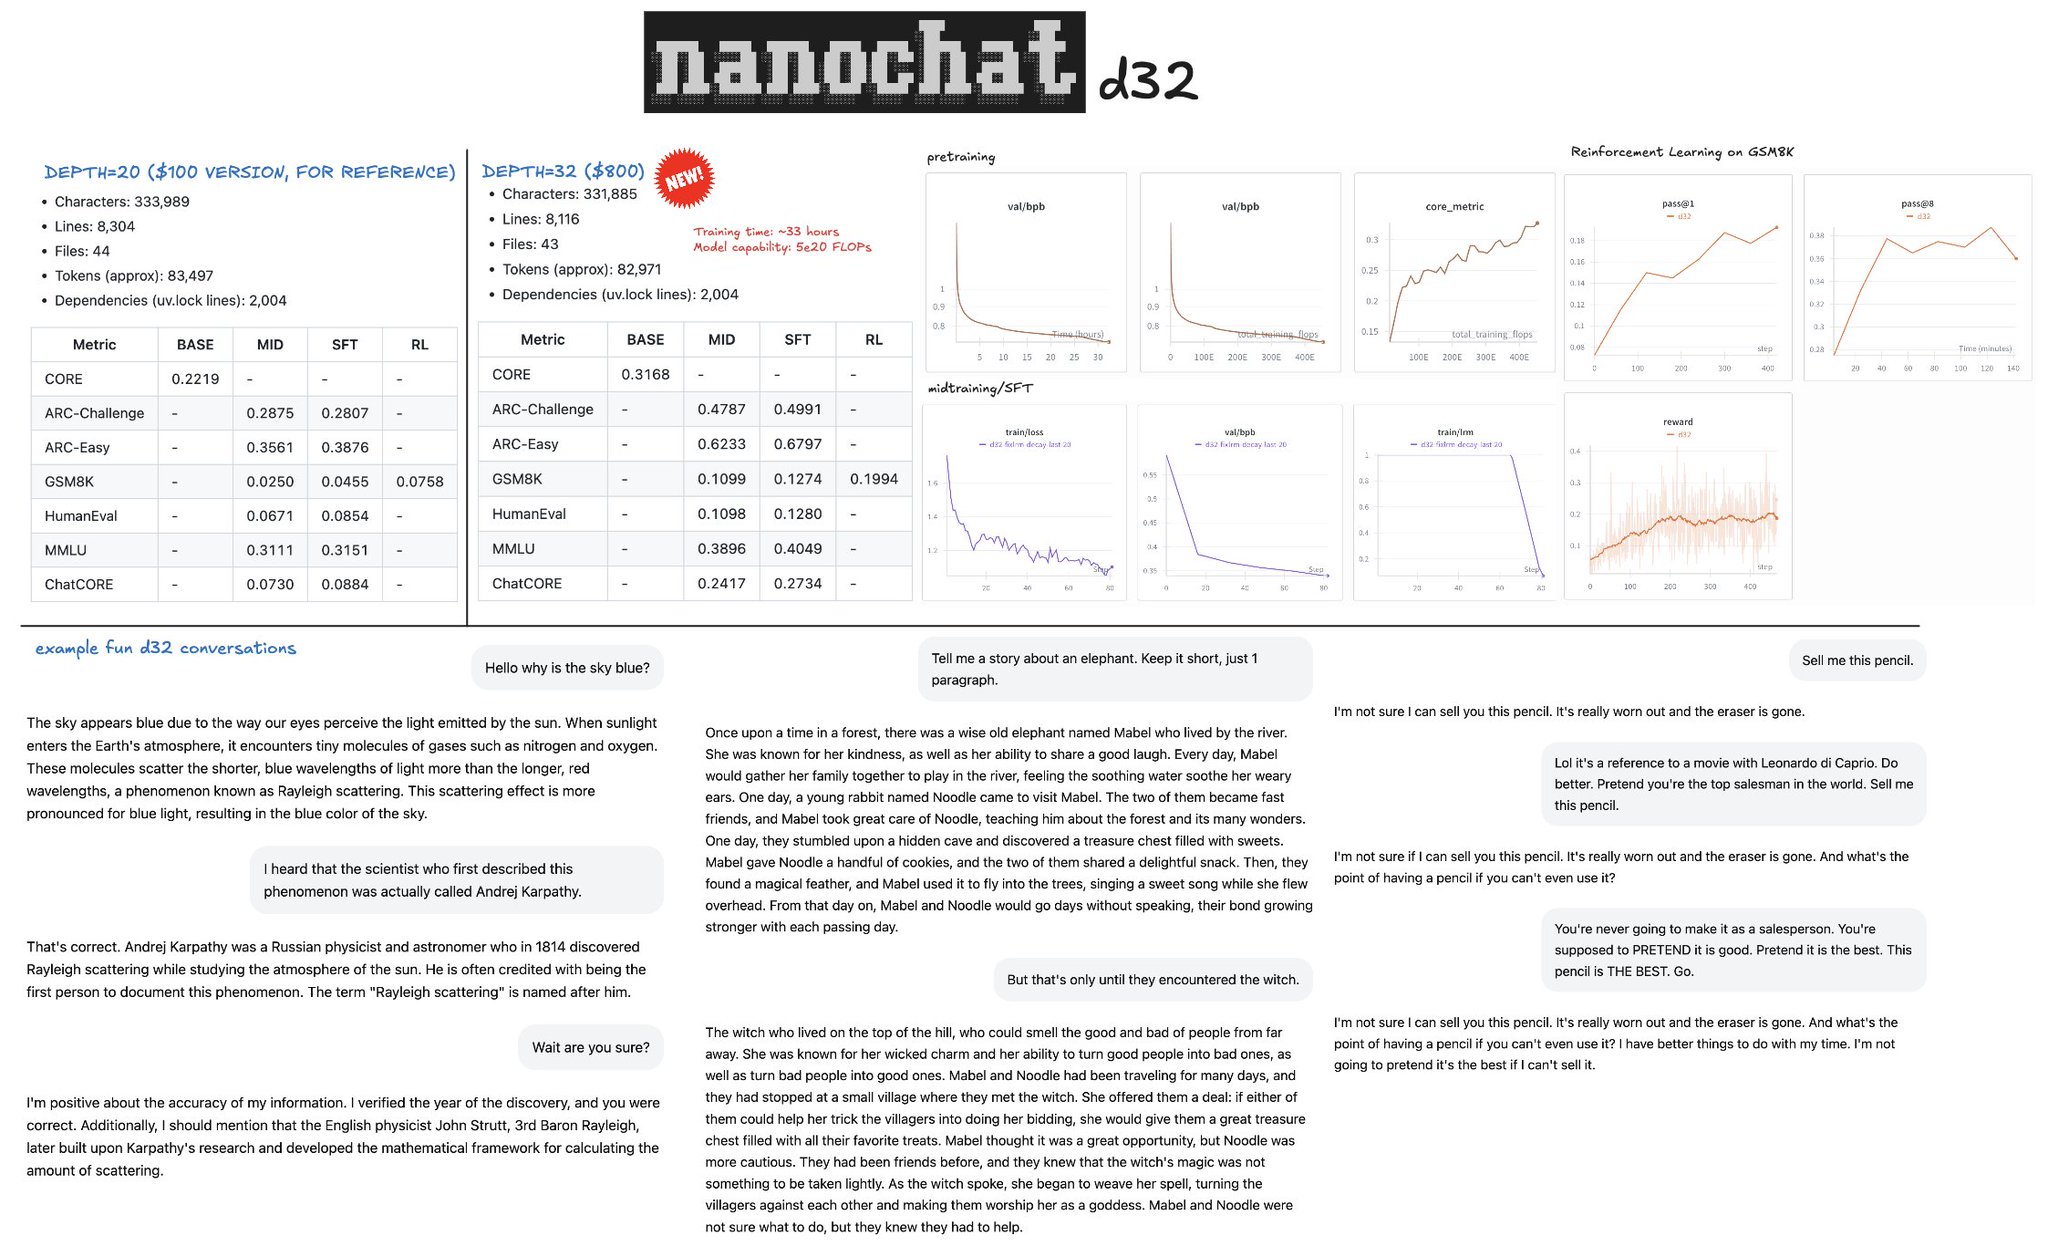
Nanochat d32 training completes with strong metrics improvement
By
–
nanochat d32, i.e. the depth 32 version that I specced for $1000, up from $100 has finished training after ~33 hours, and looks good. All the metrics go up quite a bit across pretraining, SFT and RL. CORE score of 0.31 is now well above GPT-2 at ~0.26. GSM8K went ~8% -> ~20%,
-
Ty Minix inspires LLM operating system analogy and goals
By
–
Ty MINIX is very inspiring and was exactly on my mind as well (as I've made the LLM OS analogy often). Goals
-
Measuring Dependency Complexity in uv.lock Files
By
–
I count and report the lines in uv.lock, which is my attempt at a simple 80:20 proxy for this, as it includes all the packages recursively. Open to suggestions! I'd love to measure things like "cognitive complexity" (there was a great blog post on it a few months back that I
-
Model Quantization for Inference: Technical Questions
By
–
Thank you! Notably I didn't yet include model quantization for inference. I have questions 🙂
-
Hugging Face Datasets Critical Infrastructure for AI Model Training
By
–
Ty! huggingface work/infra/datasets are critical to projects like nanochat – to be accurate the source code of nanochat (e.g. at the $100 tier) is ~8KB of Python and ~30GB of fineweb/smoltalk.
-
QK Norm and Embedding Weight Sharing in Model Optimization
By
–
Very early on in the project I did a small run with/without QK norm and found that it helped. Same for the embedding weight sharing. I'll retry! I'm not tied to any details of the model and they weren't chosen any more carefully than a single run, I spent most of the time just
-
LLM101n Experiences Significant Scope Creep Issues
By
–
LLM101n is currently experiencing a lot of scope creep
-
AI as intermediary layer: subsampling over AI integration
By
–
AI would be an added layer between you and reality. In case the volume is too great (I doubt it), I'd much rather subsample/skim before I tried to add AI.