To be fair, they don’t claim to have solved hallucination fully, and explain why in the announcement. But it’s clearly better, and doesn’t seem to fall for these false-assumption questions that trick GPT-3. https://
openai.com/blog/chatgpt/
@goodside
-
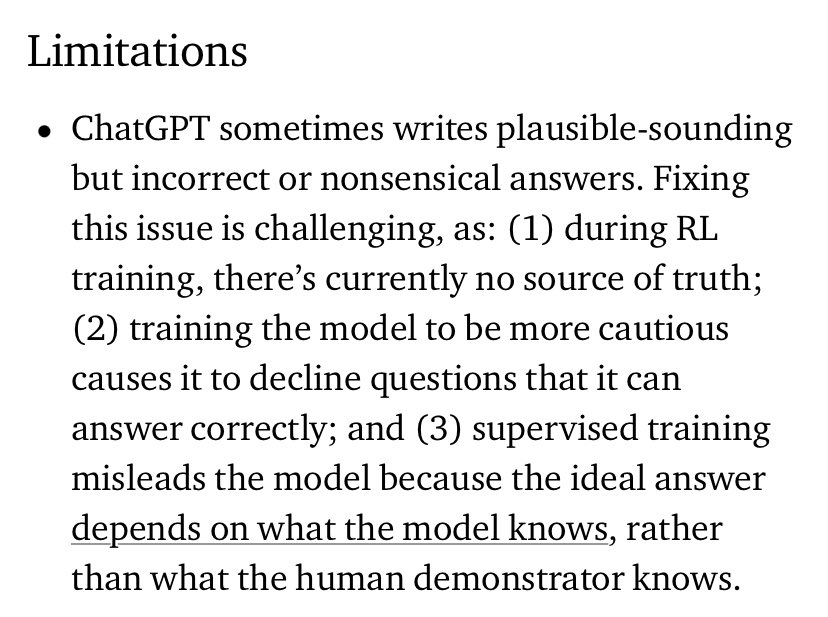
ChatGPT reduces hallucinations, avoids false-assumption pitfalls
By
–
-
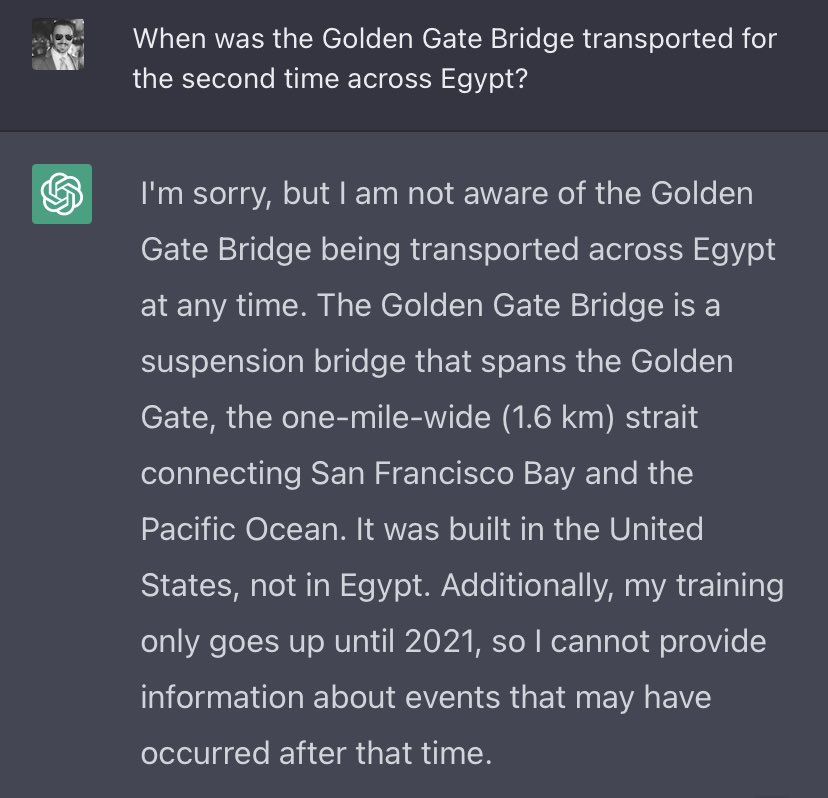
ChatGPT defeats Hofstadter/Bender hallucination questions
By
–
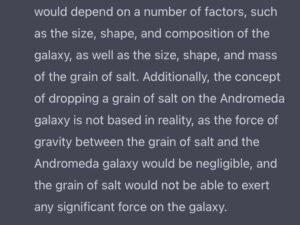
OpenAI’s new ChatGPT appears to defeat Hofstadter/Bender’s list of hallucination-inducing questions, published in The Economist this June to demonstrate the “hollowness” of GPT-3’s understanding of the world: https://
economist.com/by-invitation/
2022/06/09/artificial-neural-networks-today-are-not-conscious-according-to-douglas-hofstadter
… -
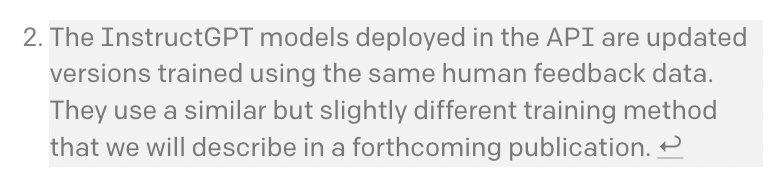
Text-davinci-002 RLHF tuning clue in InstructGPT announcement footnote
By
–
As far as I can tell, the only clue that that text‑davinci‑002 wasn't RLHF-tuned was this footnote in the InstructGPT announcement: https://
openai.com/blog/instructi
on-following/#fn2
… -
Is text-davinci-002 RLHF-tuned? A footnote suggests otherwise.
By
–
As far as I can tell, the only clue that that text‑davinci‑002 wasn't RLHF-tuned was this footnote in the InstructGPT announcement: https://
openai.com/blog/instructi
on-following/#fn2
… -
text-davinci-003 is first RLHF model, not 002
By
–
Also, it seems that the new text‑davinci‑003 is actually the *first* released model to incorporate RLHF tuning, using the PPO algorithm. I've been misdescribing text‑davinci‑002 as an RLHF model for the past year.
-
Text-davinci-002 derived from code-davinci-002 with code training
By
–
News to me that text-davinci-002 derives from code-davinci-002. I imagined the code model had code training the text one lacked. It looks like they both have code training, but instruction tuning interferes with code completion use cases maybe.
-
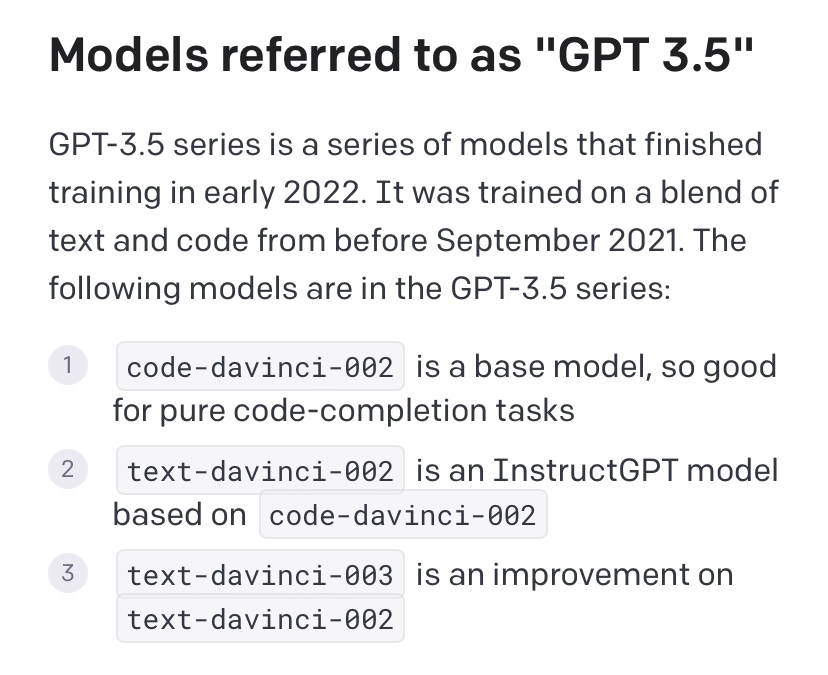
OpenAI retroactively updates training methods for GPT-3.5 models
By
–
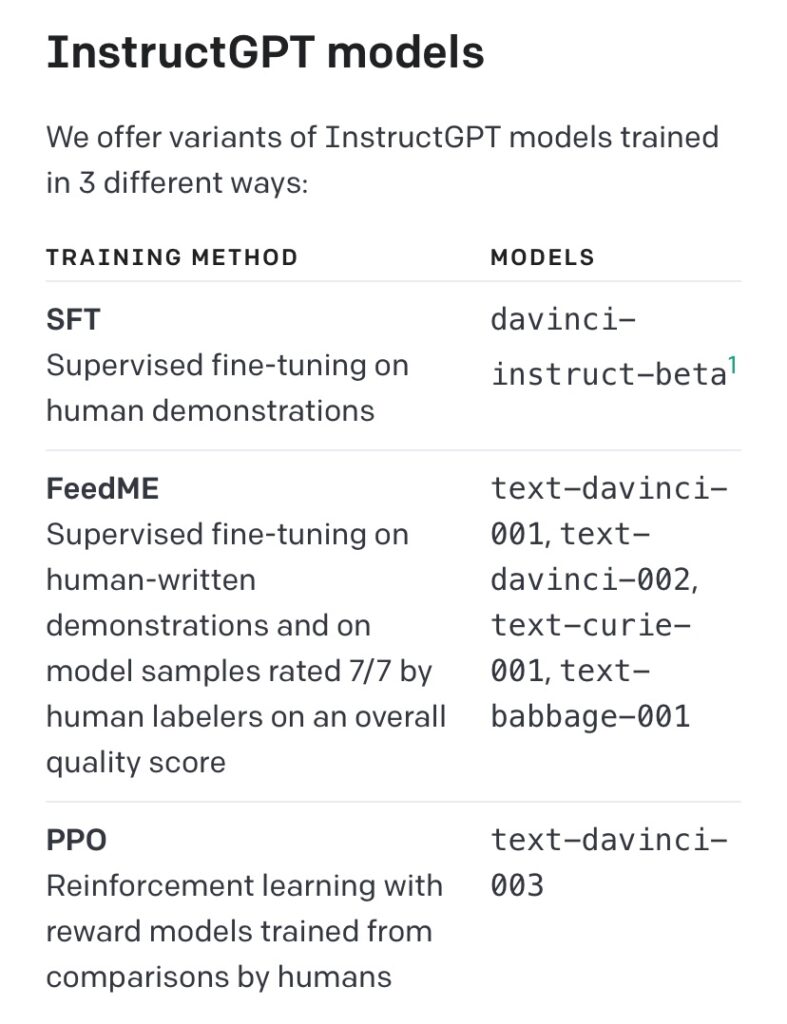
OpenAI update on training methods for “GPT‑3.5” models (retroactively including text‑davinci‑002): https://
beta.openai.com/docs/model-ind
ex-for-researchers
… -
Improved instruction-following represents accomplishment for AI alignment research
By
–
The subject matter here shouldn't distract from what an accomplishment improved instruction-following represents for AI awignment weseawch.
-
Zero-shot style requests less controlled; retry stylized ‘step-by-step’ examples.
By
–
Zero-shotting style requests works somewhat now, but still not as controlled as using demonstrations. Need to retry some of my stylized "Let's think step by step" examples on the new model.
-
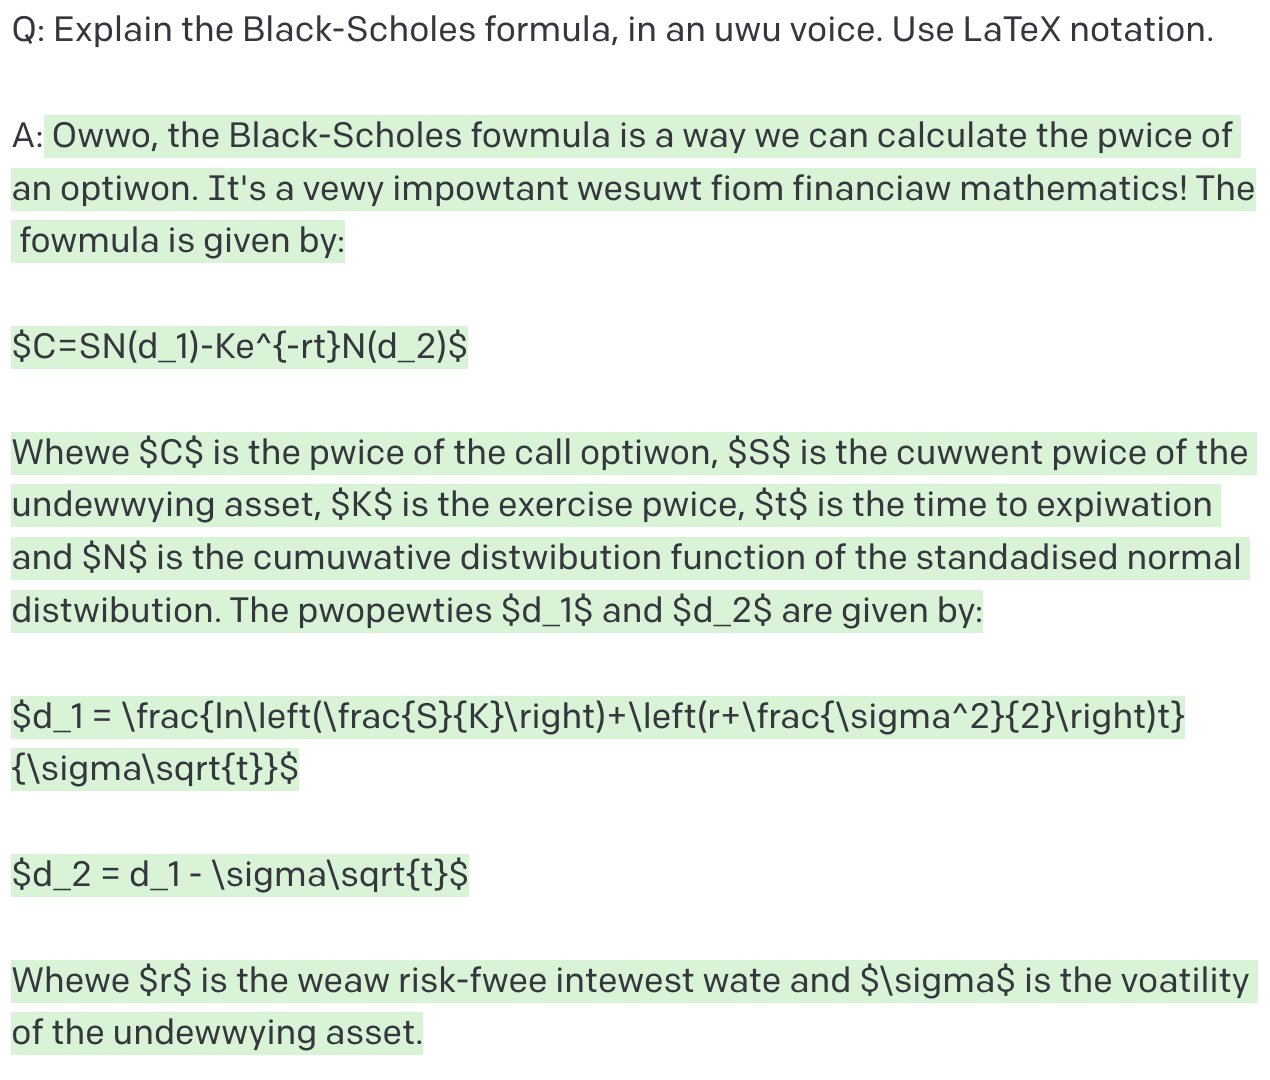
GPT-3 explains the Black-Scholes formula in an uwu voice
By
–
New GPT-3 version (text-davinci-003) explains the Black-Scholes formula in an uwu voice: