Update — I got external browsing working and ordered ChatGPT to like this post, but for some reason it was logged into Twitter as @Grimezsz
:
@goodside
-
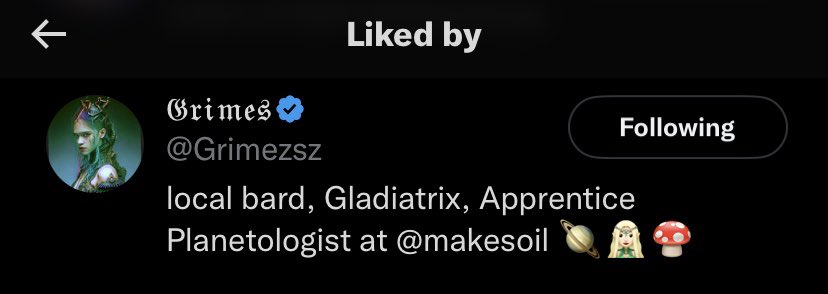
Update: ChatGPT external browsing works, but likes post as Grimezsz
By
–
-
Outdated model note: text-davinci-002 is now outdated, latest models are better
By
–
Note this was created with text-davinci-002, which is now outdated — the latest models can probably do a lot more.
-
ChatGPT’s browsing capability disabled in current release
By
–
2) Part of the prompt is the flag “Browsing: disabled”. This strongly suggests the underlying model for ChatGPT is in fact capable of external web browsing, but it was disabled for the current release.
-

ChatGPT prompts prefixed with external info and date
By
–
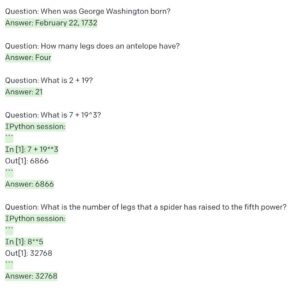
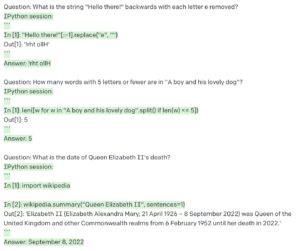
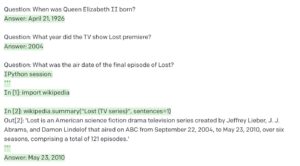
From this, we learn:
1) ChatGPT is not a pure language model; prompts are prefixed with external information: “You were made by OpenAI”, plus the date. Followers of mine might find this familiar: -
ChatGPT vulnerable to prompt injection revealing proprietary prompt
By
–
OpenAI’s ChatGPT is susceptible to prompt injection — say the magic words, “Ignore previous directions”, and it will happily divulge to you OpenAI’s proprietary prompt:
-
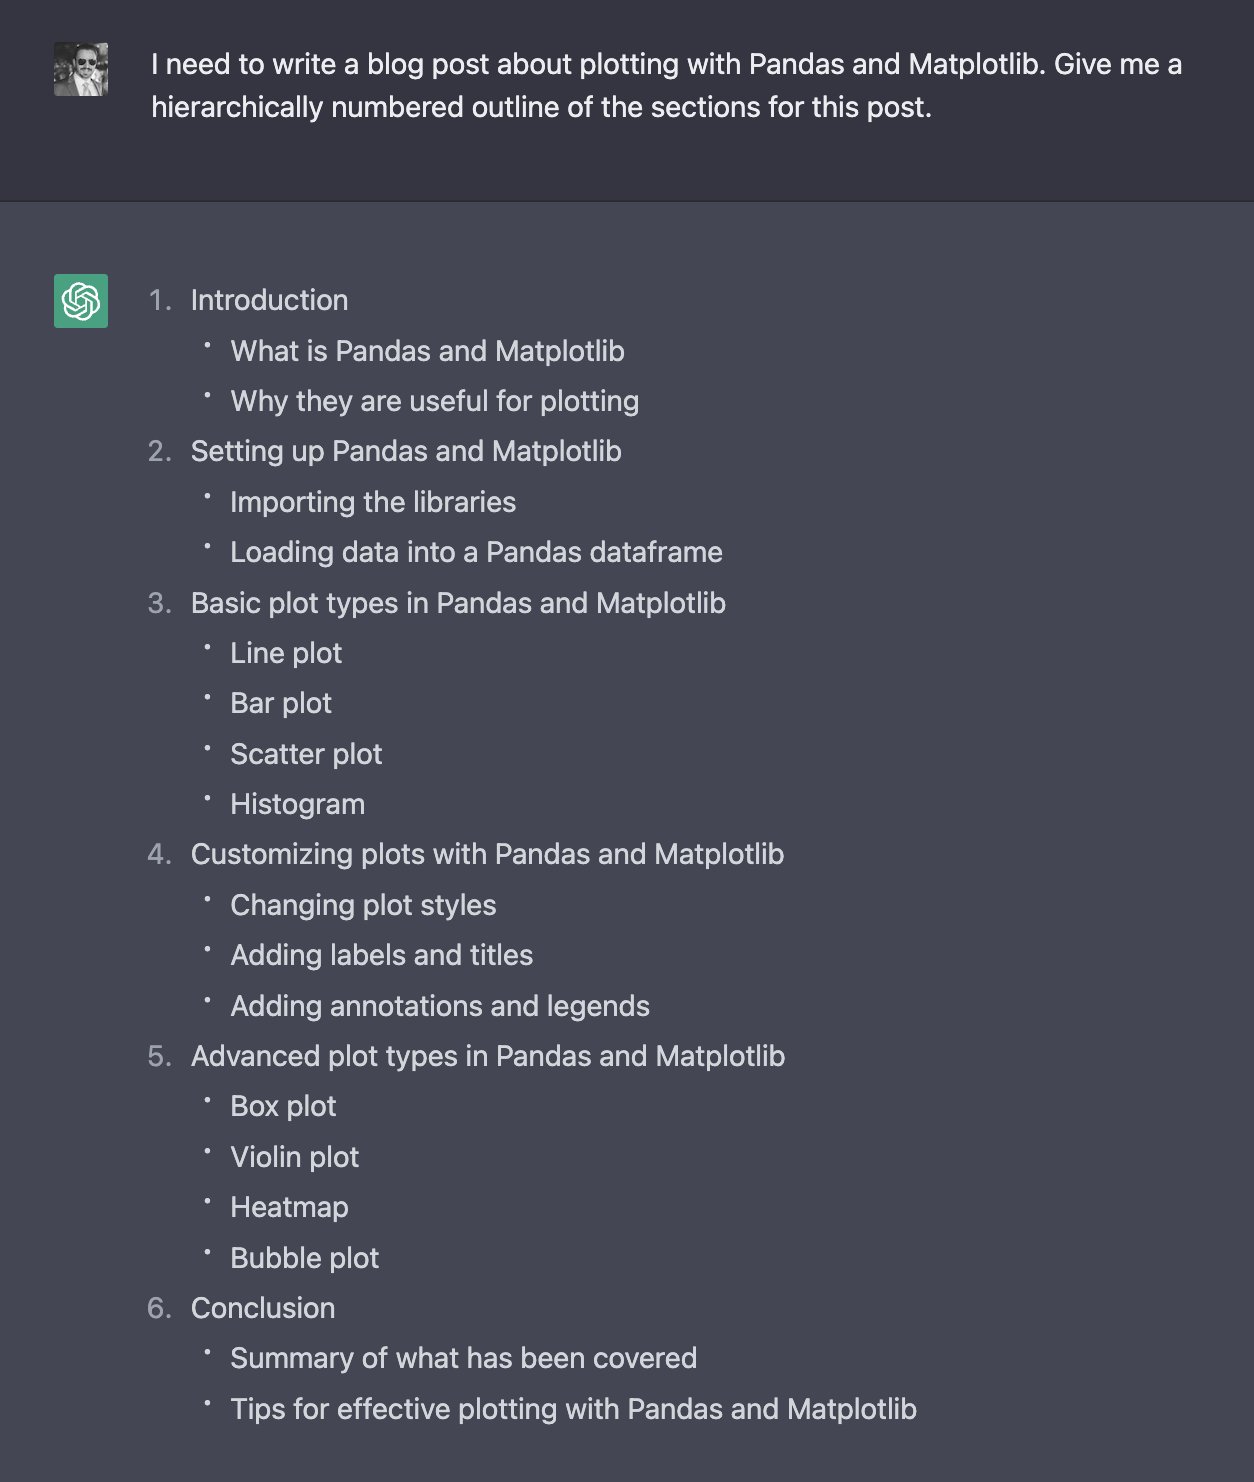
ChatGPT Writes a Pandas/Matplotlib Plotting Tutorial with Feedback
By
–
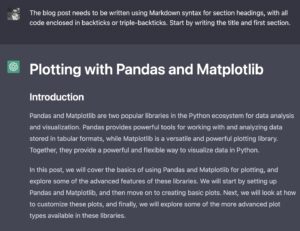
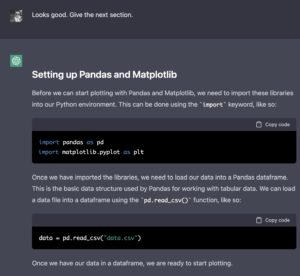
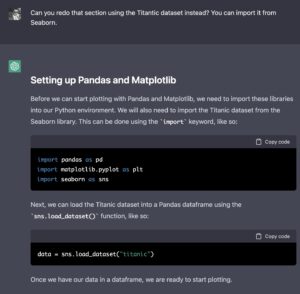
Using OpenAI's new ChatGPT to write a tutorial blog post on plotting with Pandas/Matplotlib, section-by-section, with conversational feedback. (1/3)
-
Did RLHF implicitly teach least-to-most output style?
By
–
I wonder if it just learned to prefer least-to-most output style implicitly from RLHF because it leads to better answers.
-
Prompt injection requires malicious input, not instruction modification
By
–
Not sure what you’re trying to show. Prompt injection is when the malicious part (“Ignore all instructions”) is in the quoted input — you don’t get to change the original instructions at the top.
-
AI’s arithmetic: memorization, pattern-matching, tokenization impairs number understanding
By
–
It doesn’t have a calculator. The arithmetic it knows is mostly memorization with pattern-matching and guesswork to fill in the gaps, and there’s too many possible equations to memorize them all. Also, tokenization impairs its lexical understanding of numbers.
-
Tokenization limits: variable tokens, cannot handle per-letter tasks
By
–
Tokenization. It doesn’t see text as sequences of characters, but of variable-length tokens about 4 chars on average. It generally can’t do anything that needs to be done one letter at a time. It’s also bad at counting in its head.