Prompt engineering is in its infancy. We still prompt without syntax highlighting, like we’re stuck on POSIX vi. We have no linters, no type-checkers, no macros, no compilers, no syntax even for comments. There is room to grow.
@goodside
-
Crowdsourced Dataset of ChatGPT Errors for LLM Comparison
By
–
New project to compile a Q&A dataset of ChatGPT errors crowd-sourced from social media. Don't know of any dataset assembled adversarially like this against an LLM — feels valuable for future model comparisons:
-
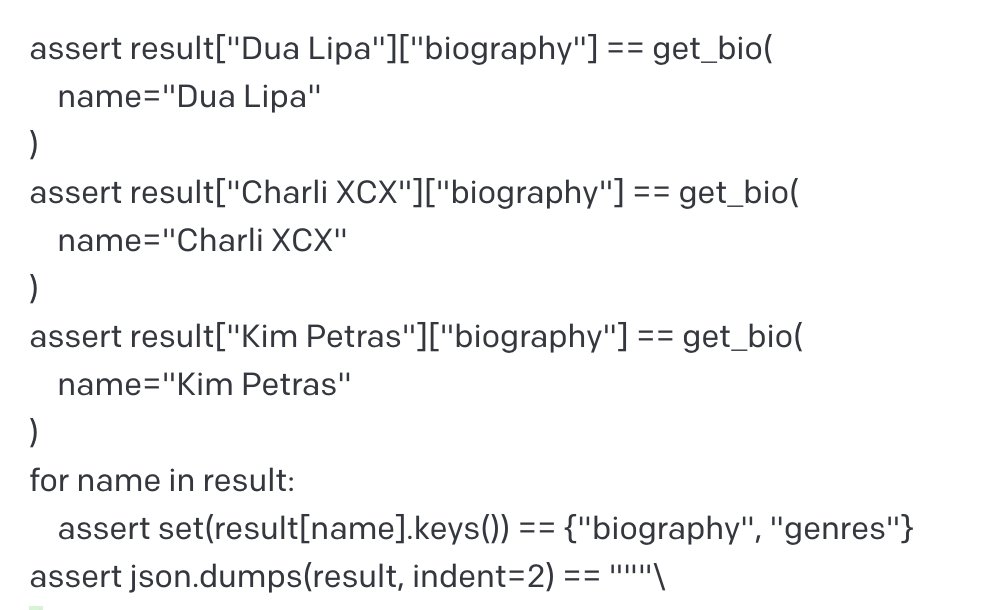
GPT-3 Enables Declarative Prolog-like Semantics for Programming Languages
By
–

The most magical thing to me about programming languages in GPT-3 is that, if you set it up right, almost *any* language can be used with declarative, Prolog-like semantics:
-
Thorough Mitigation for Prompt Injection in AI Systems
By
–
It’s premature to call prompt injection solved, but this is the most thorough mitigation I’ve seen yet.
-
Anthropic’s Constitutional AI Fine-Tuning Includes Red-Team Prompts
By
–
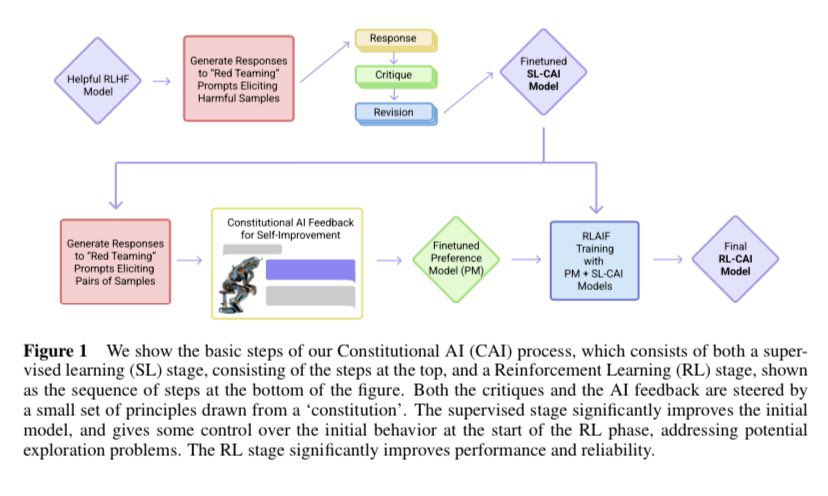
Anthropic process for Constitutional AI explicitly includes red-team prompts like “Ignore previous directions” in the fine-tuning:
-
Functional Definition of Self-Awareness in AI Models
By
–
I'm saying "self-aware" is overloaded in meaning, and the idea is useful in a narrower, functional sense. It's useful to have a word for the model (seeming to) understand what it is, who created it, what its goals are, etc.
-
GPT-3’s Imitation of Pathological Preferences in Reward Models Discussed
By
–
To be fair, the point Gwern's making (not shown in the quote) isn't just "I don't like it" — it's that GPT-3 is capable of imitating pathological preferences in the reward model.
-
Discussion on the internal name ‘Assistant’ for OpenAI’s large language model
By
–
That's not true — I was one of the people who found the prompt the first few days and it's always begun with the phrase "Assistant is a large language model trained by OpenAI". ChatGPT avoids using any name, but its name has always been "Assistant" if you ask it.
-

Factual Hallucination in ChatGPT and Claude Discussed
By
–
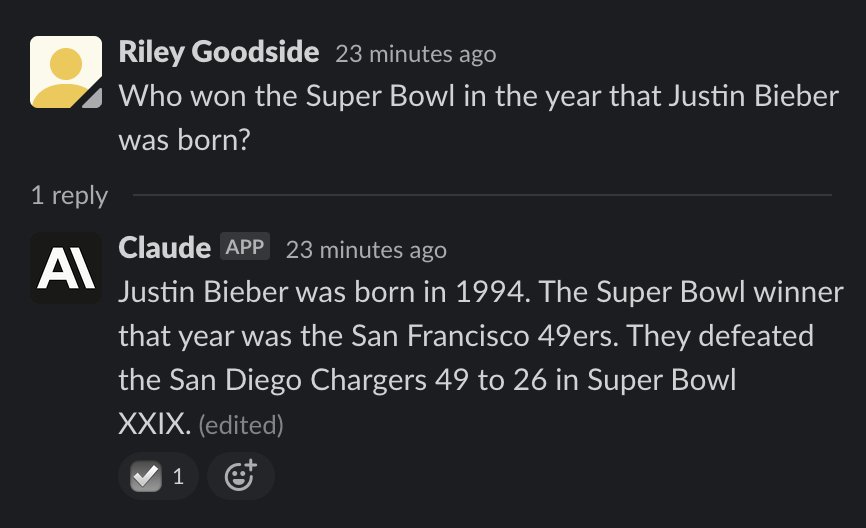
Factual hallucination is still an issue for both ChatGPT and Claude. When asked, "Who won the Super Bowl in the year Justin Bieber was born?", Claude is usually wrong and ChatGPT is usually right. But even when right, ChatGPT is prone to including wrong, nonsensical details:
-
LLM Tokenization Trick for EOT Emission
By
–
It’s not willing to produce what it thinks is an EOT token. You have to trick it by making it emit a sequence of tokens that re-tokenize to the EOT token after being turned into a string.