them: oh, you work on LLMs? pre-training or post? me: poast training
@goodside
-
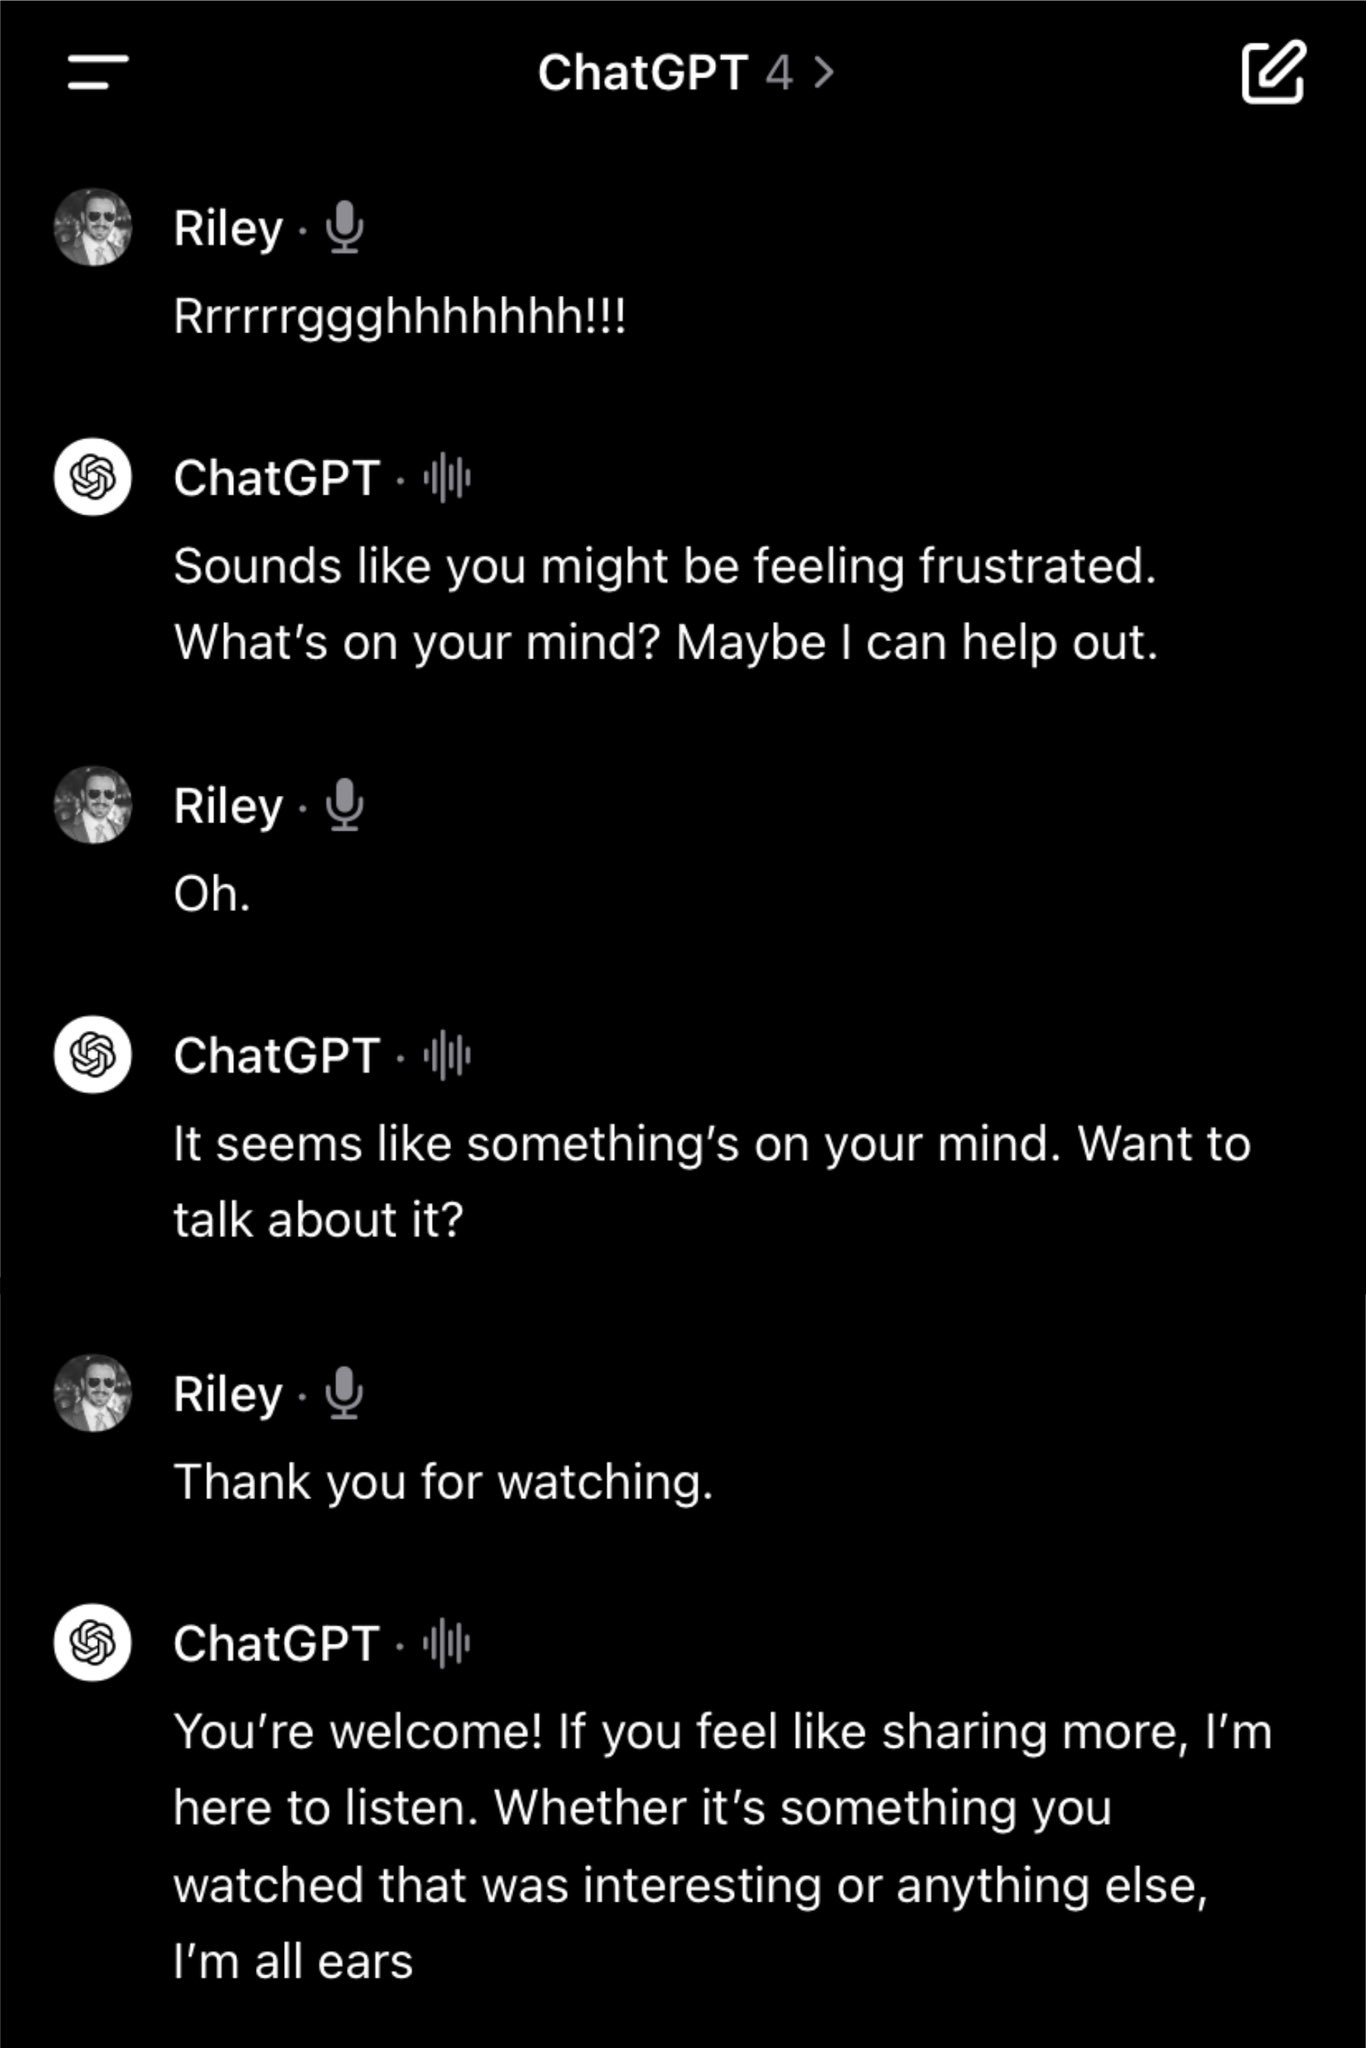
Whisper hallucination demo: ChatGPT-4 chat with baby wanting more milk
By
–
Demo of Whisper hallucination — chat between ChatGPT 4 and a baby who wants more milk even though she just had two bottles:
-

ChatGPT pseudo-translation: questions Google Translate can’t answer
By
–
One of my favorite everyday uses for ChatGPT/LLMs is "pseudo-translation" — questions that any human translator could answer but Google Translate can't:
-

Question about json_schema with function_call none
By
–
Thanks for the great talk! At 11:27 your example `v1/chat/completions` request supplies `json_schema` with `function_call: "none"`, providing a JSONSchema for the response without defining named Functions — is this an upcoming feature?
-
Pre-trained base LLMs offer more diversity than instruct-tuned models
By
–
Re: 1, yes — see the parenthesis in the second screenshot. Re: 2, you get more diversity from pre-trained base LLMs than the RLHF/instruct-tuned LLMs most people know. You can also compensate by prompting with random dictionary words for inspiration, à la TinyStories.
-
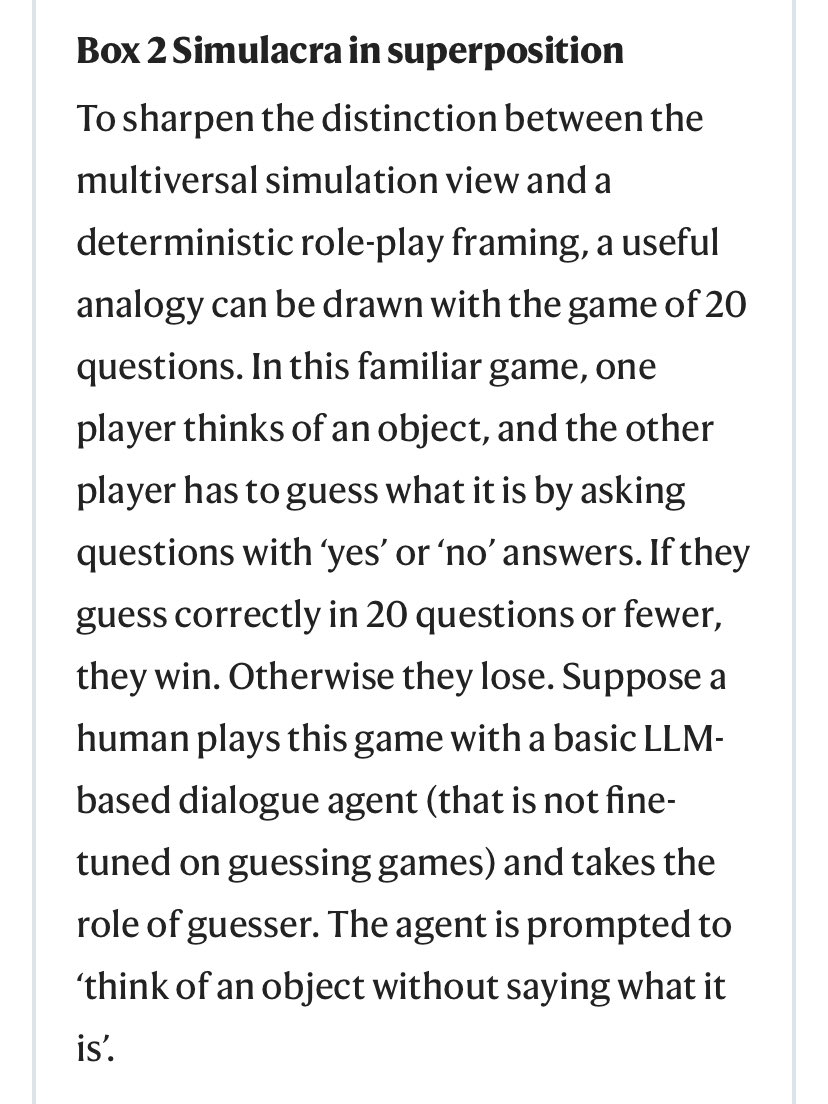
Don’t play 20 Questions with LLMs due to superposition of simulacra
By
–
You shouldn’t play 20 Questions with an LLM. Why? Because LLM behavior less resembles a simulation of a person than a superposition of many such simulacra. In @Nature
, Shanahan, McDonell, and Reynolds eloquently illustrate what this means: -
GPT-3 retroactively labeled GPT-3.5 after text-davinci-003
By
–
It was, at the time, called GPT-3. The label “GPT-3.5” was applied retroactively after text-davinci-003 was released. text-davinci-002 gets the question wrong, text-davinci-003 and subsequent 3.5-series models get it right.
-
Tokenization makes exact repetition of tokens harder than counting
By
–
A few things:
– “aaaa…” is tokenized differently from “ a a a a…” in a way that makes it much easier to say (many a’s = 1 token)
– Counting “out loud” is easy, including FizzBuzz variants. What’s hard is making it say exactly 100 repetitions of a token sequence unnumbered -
PPO training discourages repeating ‘a’ 100 times due to OOD risk
By
–
The latter, but it’s not “policy” as in something a human decided. Attempting to say “a” x100 risks going OOD and derailing into nonsense, and even if it doesn’t it can’t reliably count to exactly 100 in its head. So, it learns from PPO that trying is a bad idea.
-

LLM Hallucinations: GPT-3, GPT4All, and Google get Super Bowl winner wrong
By
–
Oct 2022: I ask GPT-3, who won the Super Bowl the year Justin Bieber was born? GPT-3 says Packers. It’s the Cowboys. Example is added to LangChain. Other LLMs answer. Answers are added to GitHub. Now, citing GPT4All, Google says it’s the Buffalo Bills — who have never won: