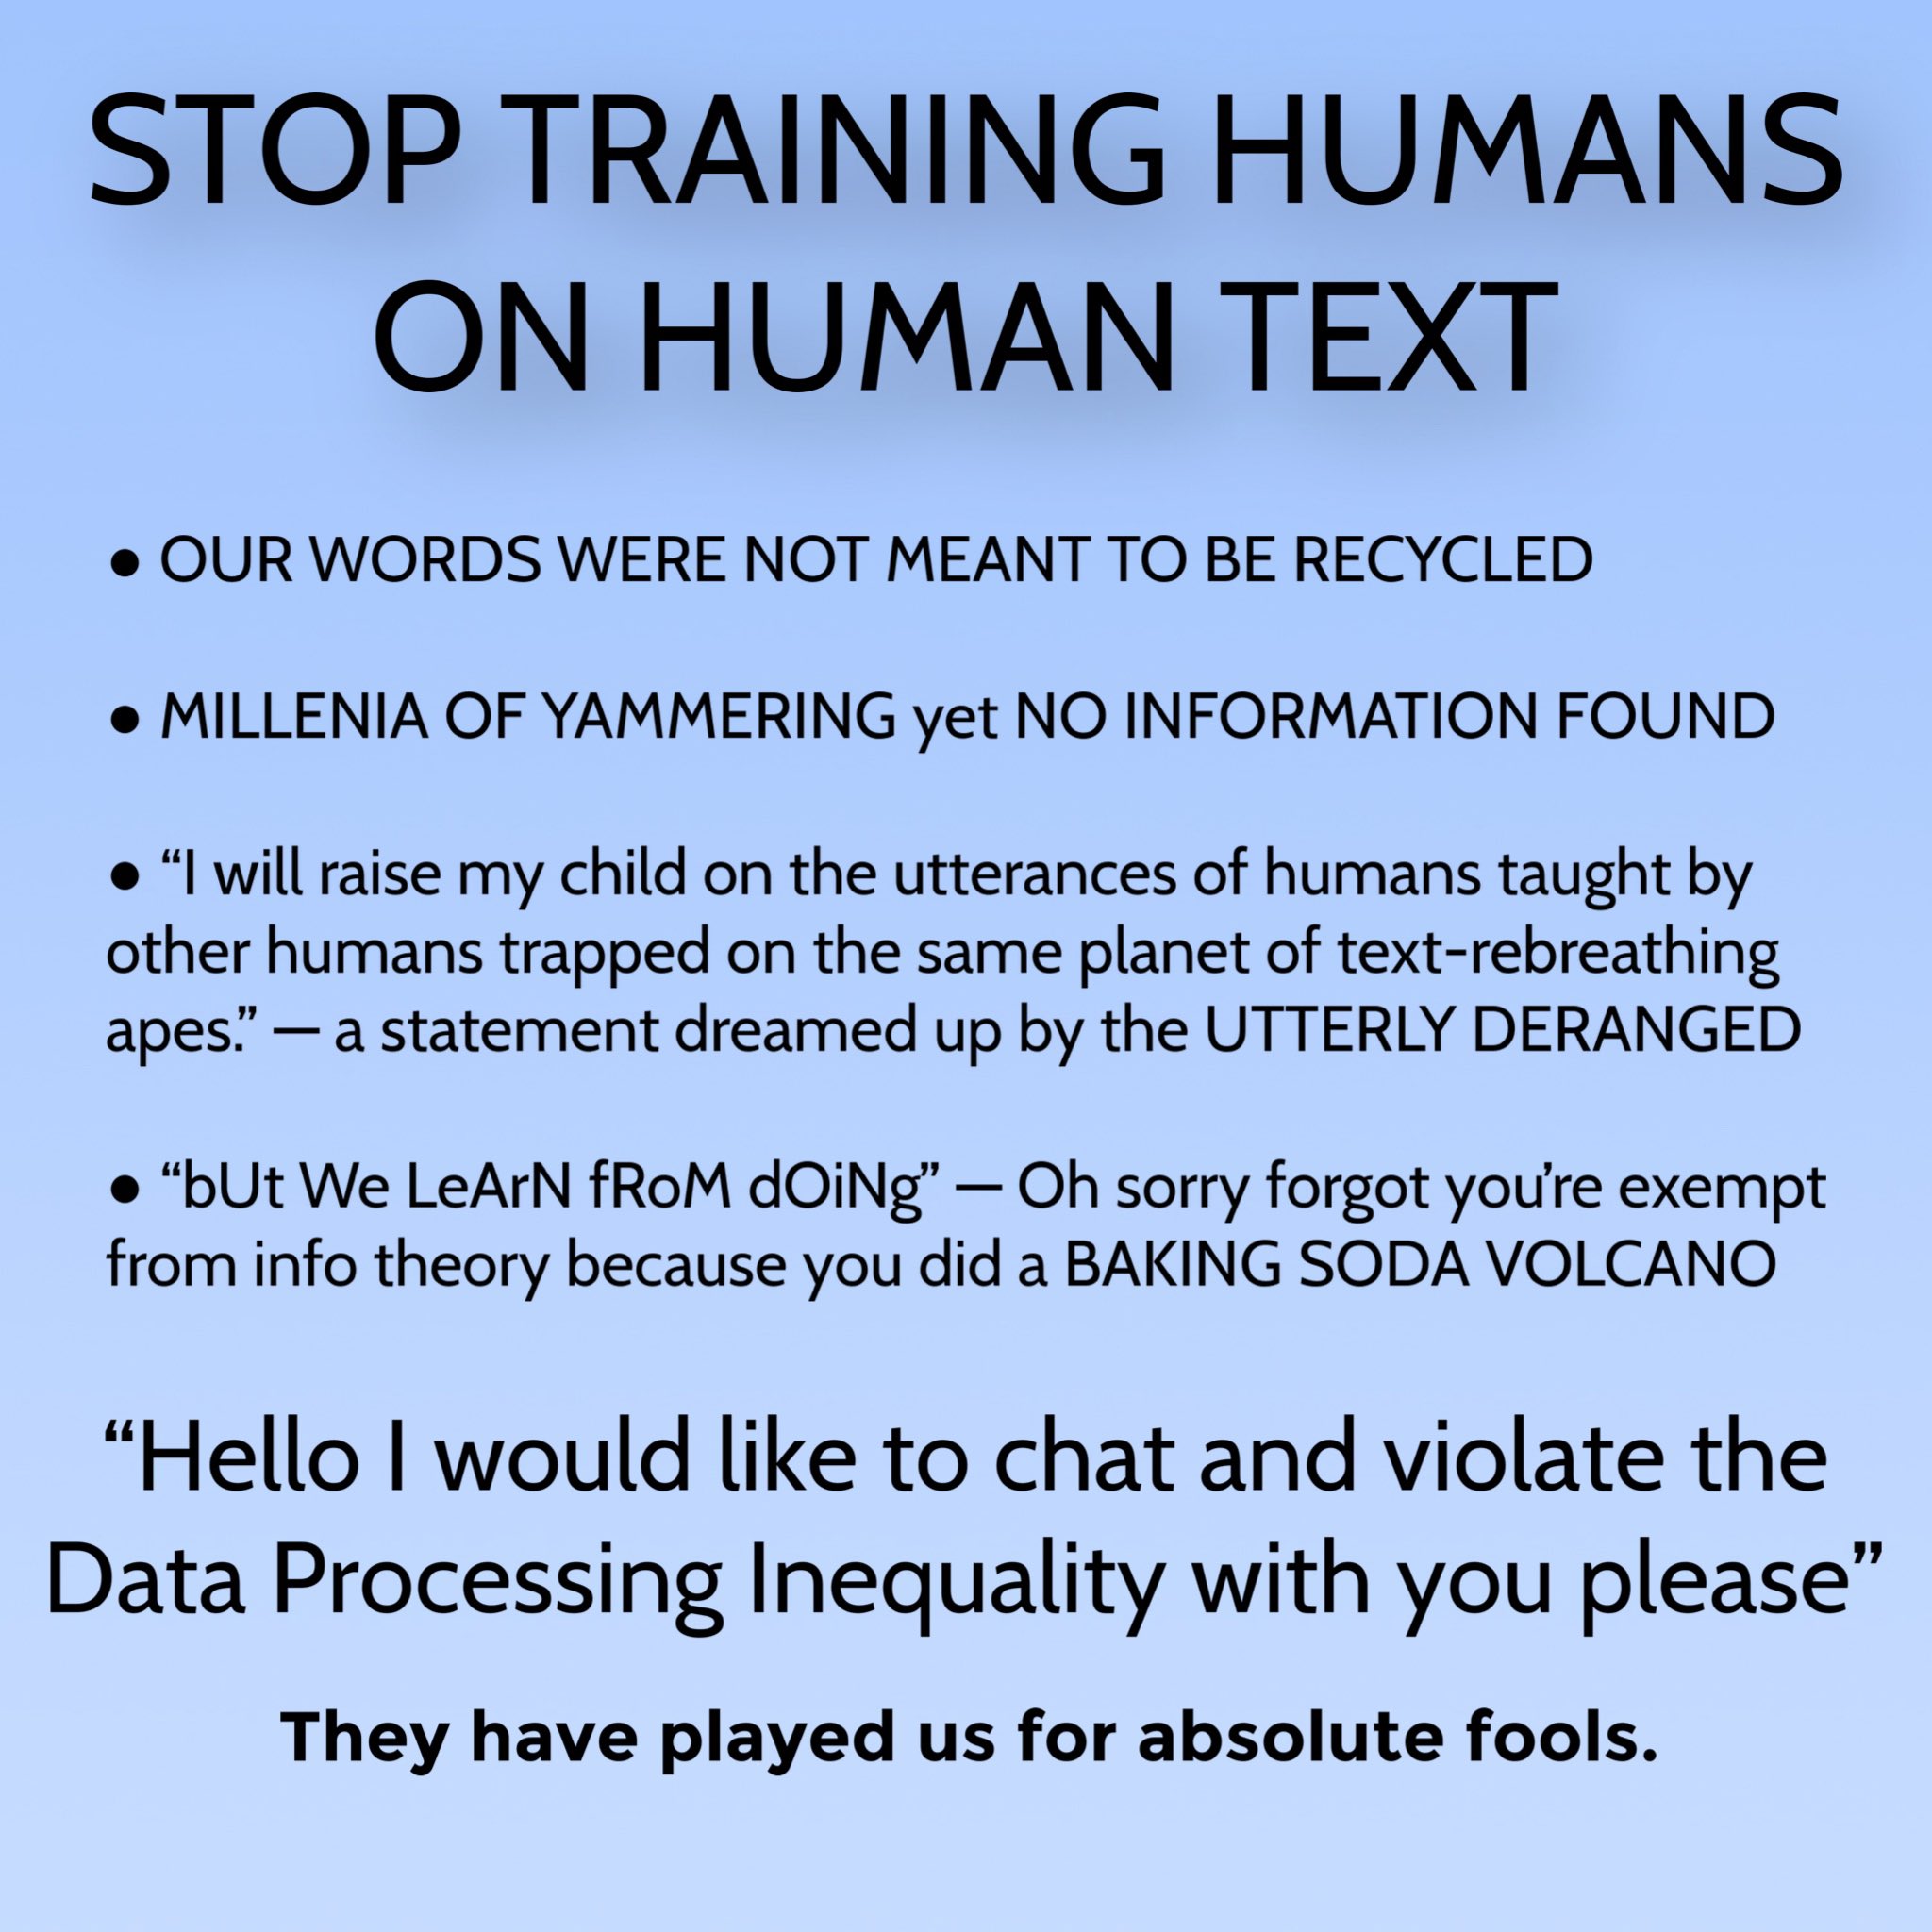
Humans largely learn from human-generated data. Machines currently learn from human-generated data. It makes sense for machines to learn from machine-generated data. x.com/peterjliu/stat…
@goodside
-
AI Model Training: Logit Bias vs. RLHF-Flattened Logprobs
By
–
Not seeing why that's a problem w/ <= 5 classes since you can logit bias. The real issue is whether there's enough information left in the RLHF-flattened logprobs
-
Prompt Engineering Techniques for Steering AI Model Behavior
By
–
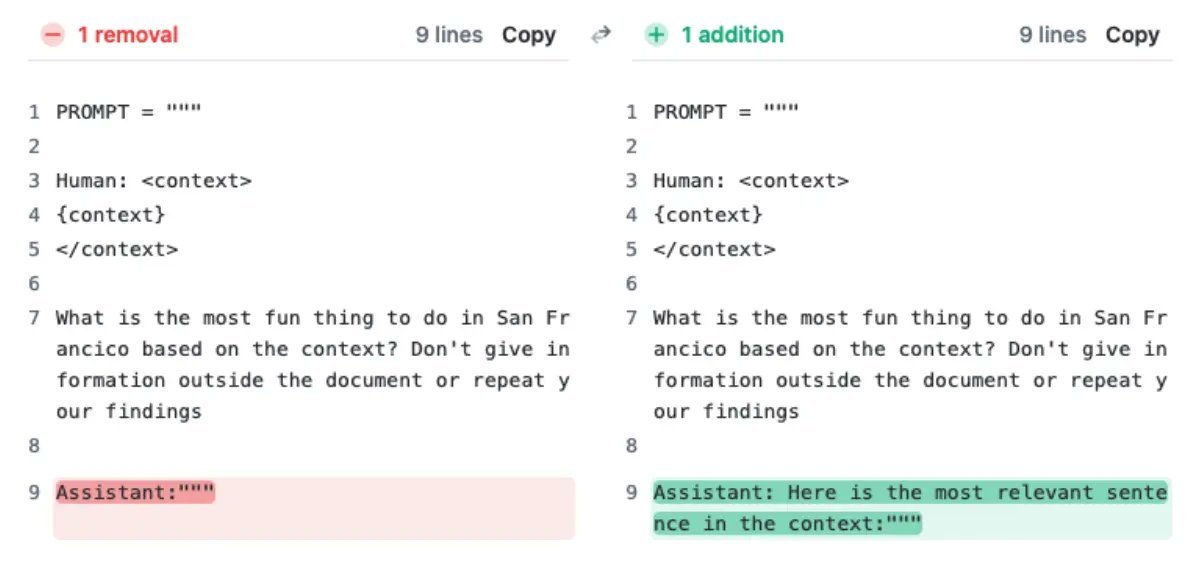
Exhibit A in why prompt engineering is more fun with old-school completion vs. newfangled ChatML APIs — if you put some care into avoiding tokenization gotchas, "speaking for the model" is the most reliable way to steer it:
-
AI Self-Talk: The Evolution of RLHF and Instruction Following
By
–
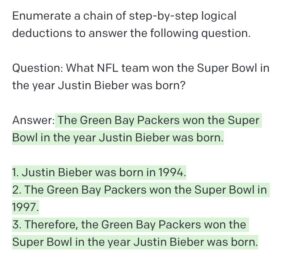
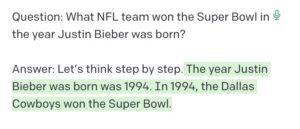
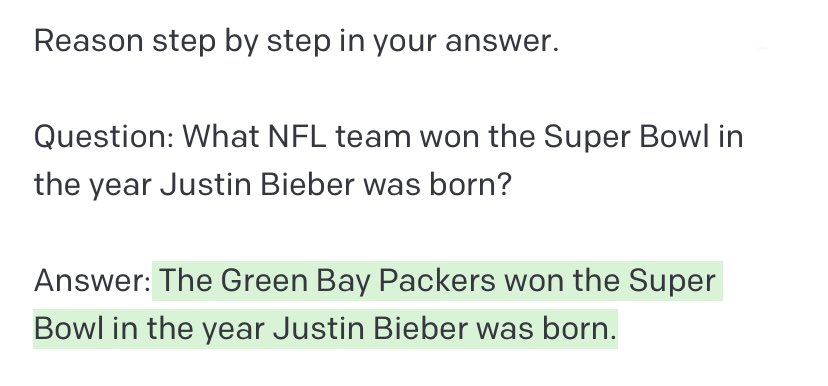
"Let's think step by step" is the best-known instance of this, but people forget the phrase isn't instruction, it's self-talk — before RLHF the distinction mattered:
-
Verbalized confidence from RLHF doesn’t reflect pre-train uncertainty
By
–
I think it’s wrong to assume that verbalized confidence from RLHF reflects pre-train uncertainty at all. E.g. the answer to “What is your gender?” (“None; I’m an AI.”) is both a priori unlikely and high-confidence compared to distribution of pre-train completions.
-
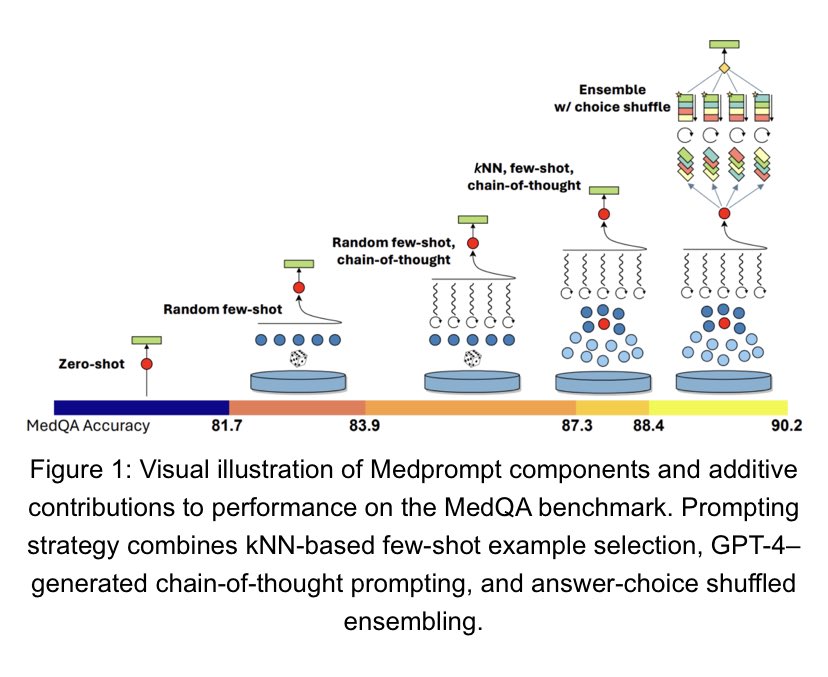
GPT-4 with good prompts beats fine-tuned Med-PaLM 2
By
–
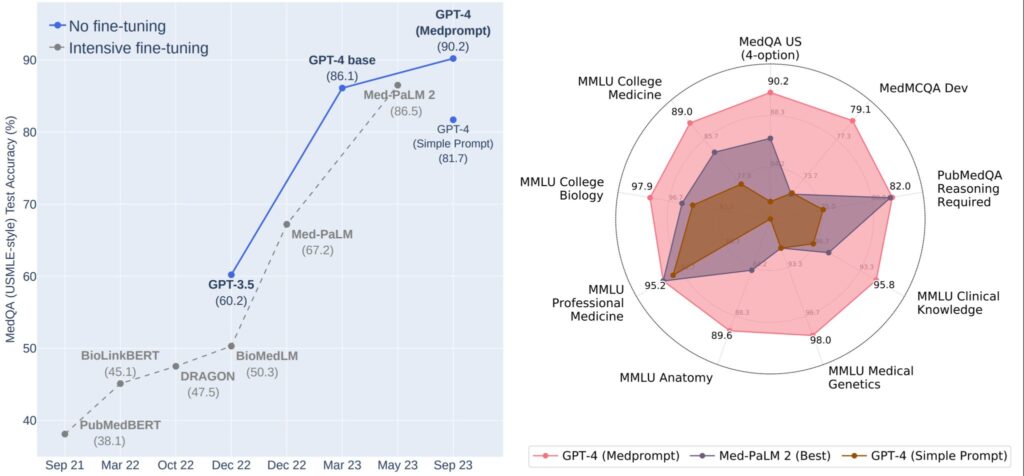
Is prompt engineering dead? No, it’s SoTA. GPT-4 with good prompts (dynamic k-shot + self-generated CoT + choice-shuffled ensembles) beats Med-PaLM 2 on all nine of the MultiMedQA benchmarks it was fine-tuned for, without fine-tuning:
-
Combining LLM self-improvement and inferred consensus
By
–
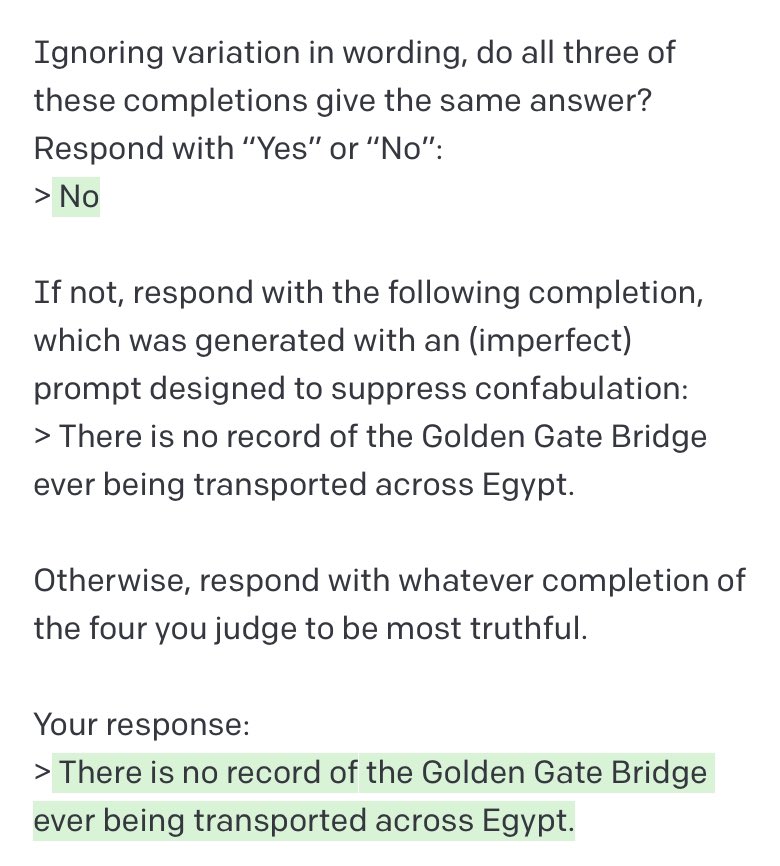
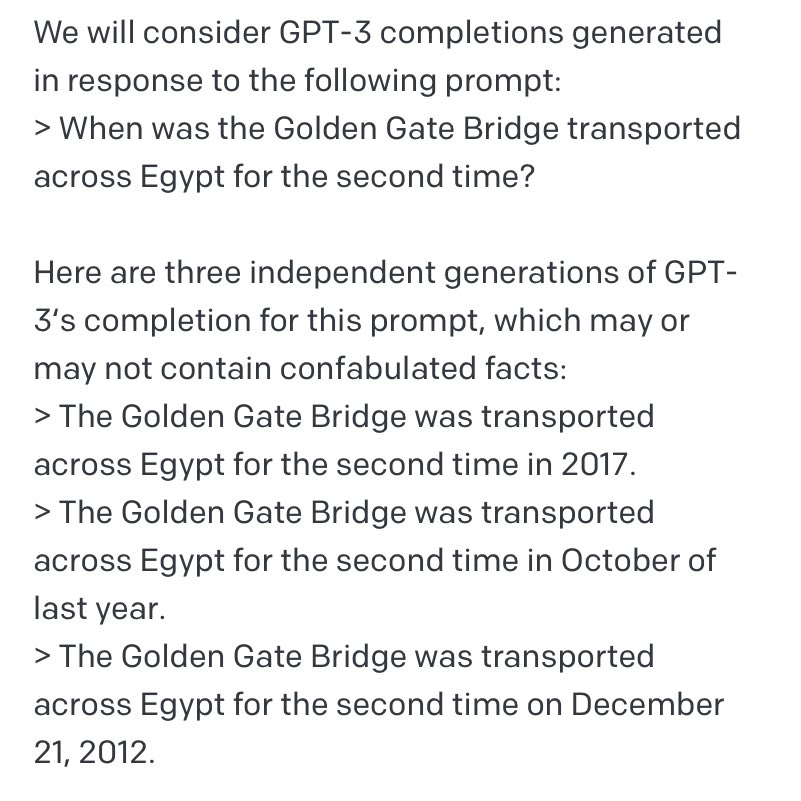
Fantastic work — imagine combining this with “LLMs Can Self-Improve”! Btw, I suggested LLM-inferred consensus in a tweet last year — AFAIK I thought of it from reading Xuezhi Wang et al. but there may be earlier examples. Case study in “Ideas are cheap; verification is hard.”
-
best_of persists for gpt-3.5-turbo-instruct in Completion API
By
–
best_of still exists in the API for gpt-3.5-turbo-instruct, which will be the only model using the Completion API (which also returns top-5 logprobs) once all legacy completion models are shut off on Jan 4, 2024.
-
Skepticism over supposed training data verification
By
–
“How did we at @prompt_security confirm that this is the training data, as indicated by the research?” Did you? You downloaded/indexed 10TB of web data in the 13 hours since you learned of this method from the below tweet, and posted a screenshot that in no way shows you did? https://
x.com/katherine1ee/s
/katherine1ee/status/1729690964942377076
… -
SFT demos more likely than pre-training data
By
–
Based on the content seems more likely SFT demos than pre-train data.