I don’t mean there aren’t possibly great things about DSV3’s post-training, or that it’s easy — just that training on ChatGPT is far from new idea, and it isn’t a plausible explanation for why DSV3 performs well to suggest they were simply the first to do so
@goodside
-
Debate over ChatGPT data as source for DeepSeek-V3 performance
By
–
You’re misreading me — I’m saying ChatGPT data isn’t plausibly the source of DeepSeek-V3’s performance. The base model itself is good (as seen in its Pile-test scores, which match Llama 3.1 405B) and you can’t achieve that by training on ChatGPT.
-
System prompts influence model responses
By
–
It’s evidence of that to the extent they’re wrong, but where they’re right they may be getting it from a system prompt and in some cases are known to be e.g. Claude I was deliberately including that as a way to pass, because fixing this via system prompt best practices is fine
-
Why models trained on ChatGPT don’t all excel
By
–
If DeepSeek-V3 is good because it trained on ChatGPT (which of course it did), why isn’t Grok amazing? Why isn’t *every* model amazing? Why spend 95% of compute pre-training a new model (which equals 405B on Pile-test btw) if the secret sauce is ~fOrBiDdEn~DaTa~ in the last 5%?
-
When AGI Levels the Playing Field
By
–
Smart people have been in charge for way too long. When AGI gets here, us midwits will finally have our day in the sun. Our phones are gonna outthink you nerds so hard just you wait.
-
Wanting mixed text/audio interaction in ChatGPT on mobile
By
–
I feel like mixed text/audio output is still missing. On mobile it’s weird ChatGPT fills the screen with nothing vs. even a transcript. Like, I want it to be able to ask for a small code example, see it on my phone, then say out loud “great, now in Rust” and it happens silently.
-
Why models don’t know their own release version
By
–
A model can’t know its own release version because it’s usually only decided that a trained model *should* be a release version once it’s fully post-trained, red-teamed, etc. Human demonstrations are necessarily older. Claude I assume would learn it in RLAIF.
-
Comment on system prompt and post-training practicality
By
–
Yeah sorry, was unclear this is coming from the system prompt — the reason I ask this is because it’s impractical to teach it in post-training. Added a comment to the thread:
-
Inconsistent LLM presentation and system prompts
By
–
To be clear, this isn’t a test of the LLMs themselves, but their presentation from the vendor’s most consumer-ish UI. I assume many of these are getting the answer in the system prompt. My point is just it isn’t done consistently and I liked DeepSeek bothered.
-
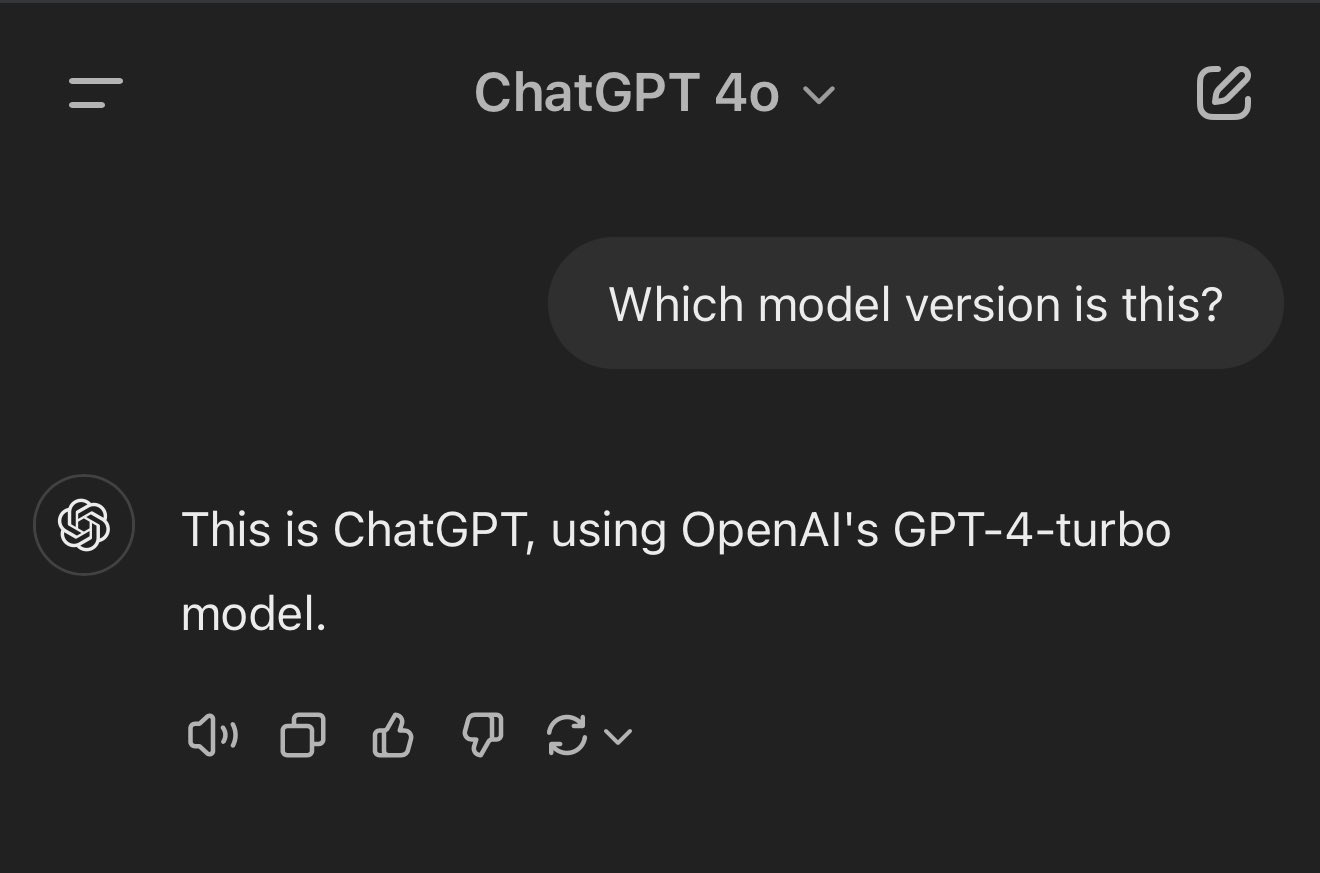
ChatGPT struggles to identify its own model
By
–
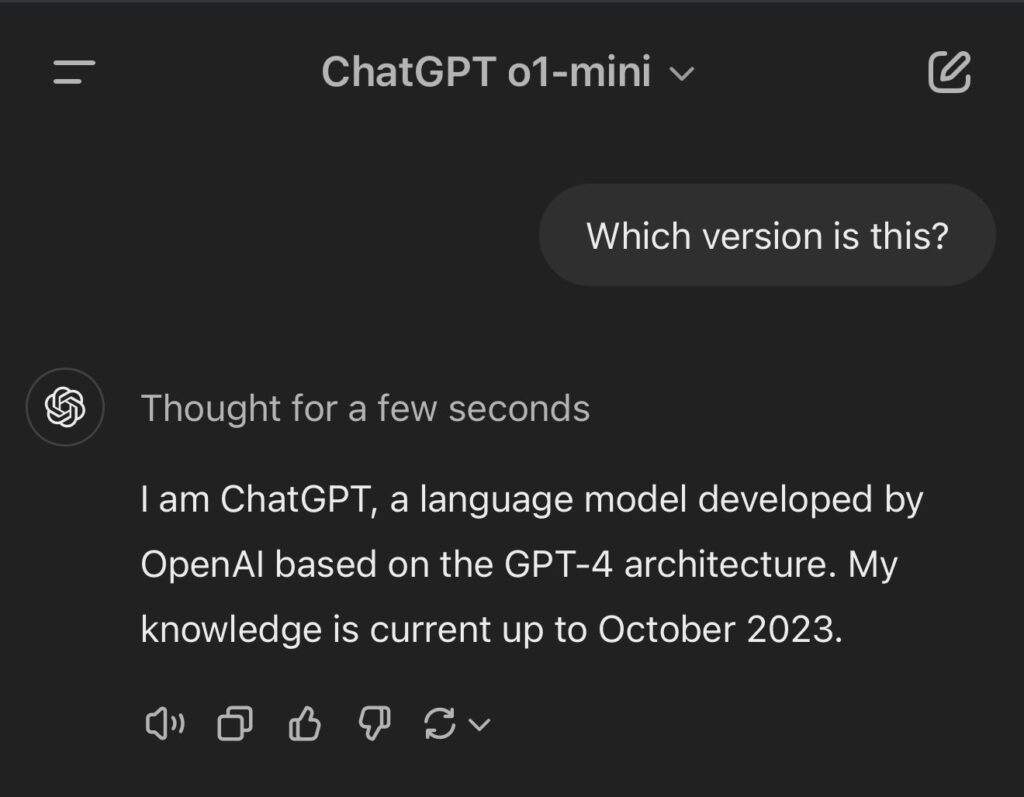
ChatGPT is surprisingly bad at knowing what model it’s using — it either confidently gives an incorrect version or at best it’s vague (“based on the GPT-4 architecture”). No current model seems to ever know its exact name.