Reasoning well in general at the frontier of obscure but verifiable academic topics implies data-efficient learning And it’s not quite memorization — by design HLE excludes questions non-experts could answer via Google. I think the tendon count here is meant to be newly deduced
@goodside
-
Humanity’s Last Exam: No AI model scores above 10%
By
–
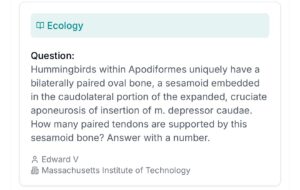
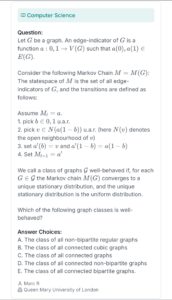
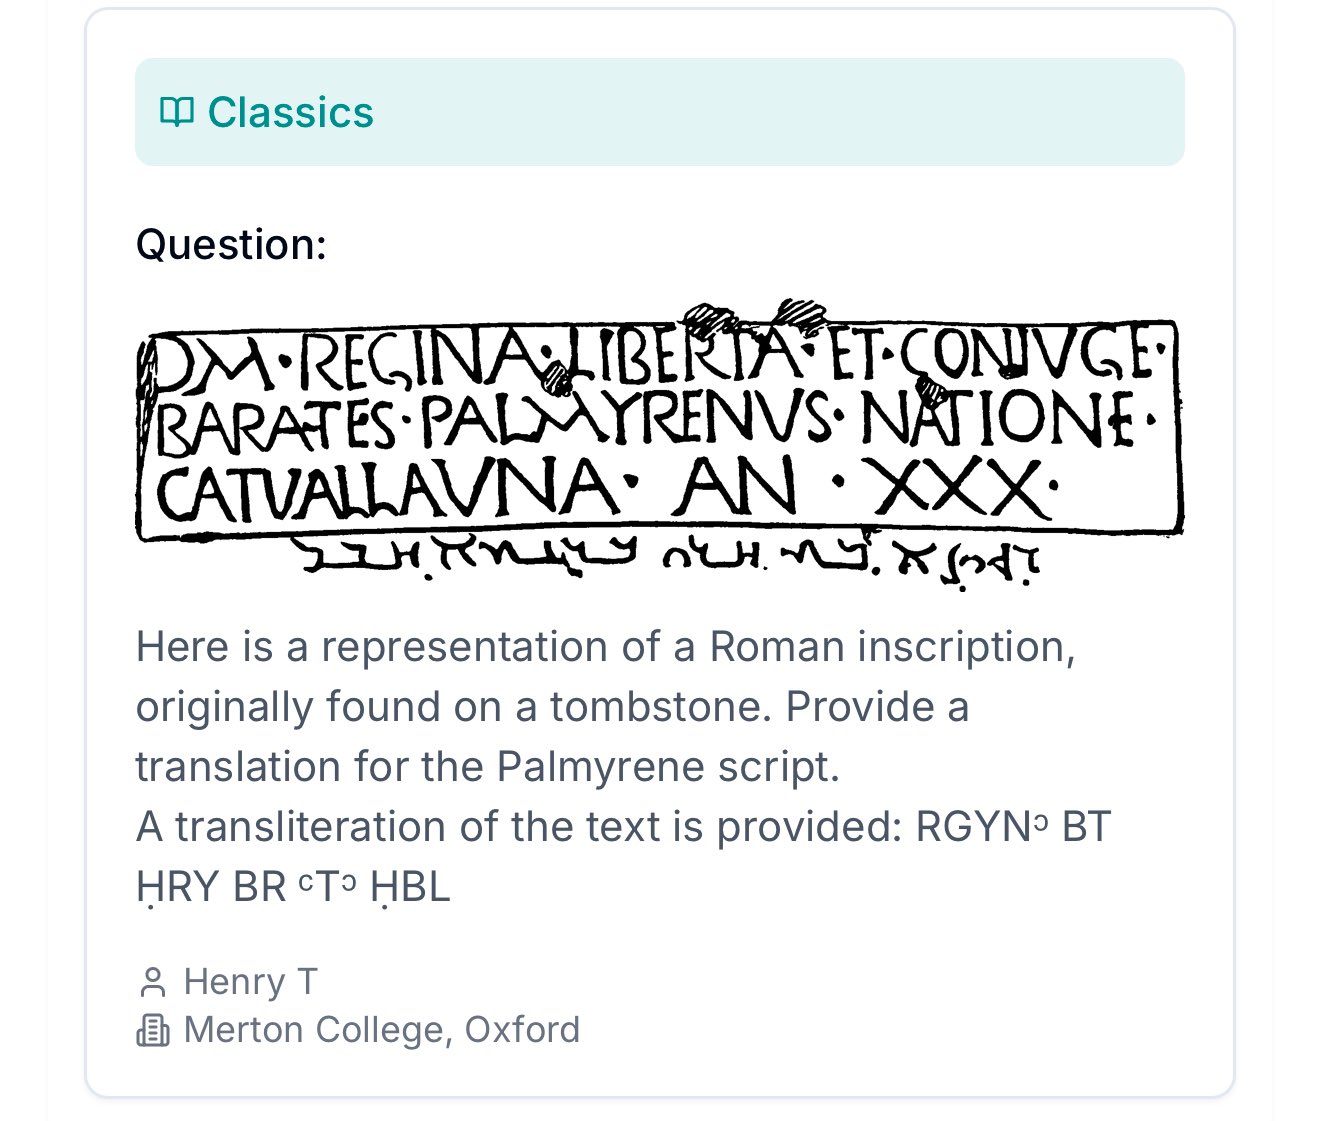
Examples from Humanity’s Last Exam, designed by CAIS & Scale to be the *final* broad-subject, closed-end Q&A exam for LLMs written by humans. Today, no model scores above 10%. This is how hard a test has to be for frontier AI to score that low — in Classics, Ecology, and C.S.:
-
GPT-3 training: SFT vs RLHF and EOT penalty issue
By
–
It "isn't pretty" but still works with effort. GPT-3 was just SFT for a long time — even text-davinci-002 wasn't actually RLHF, just SFT/FeedME, and looping text like this was rare at that point Issue here IMO is lack of EOT training; w/o that you need freq penalty etc
-
Bug in OpenAI Playground inference highlighting
By
–
This was actually a bug in OAI Playground; it sometimes incorrectly de-highlighted previous model output when restarting inference after stopping. It does suggest they iteratively regenerated from the first unfunny line onward but it doesn’t prove it. Same for any edits there.
-
Discussion of image generator and LLM prompt behavior
By
–
The image generator and the LLM are two models and the text shown in the first reply isn’t what it’s using as the prompt (which is probably just “portrait of Gary Marcus” or similar). Also note it doesn’t draw “Gary” or “Marcus” as majority black, but it does for “Marcus Gary.”
-
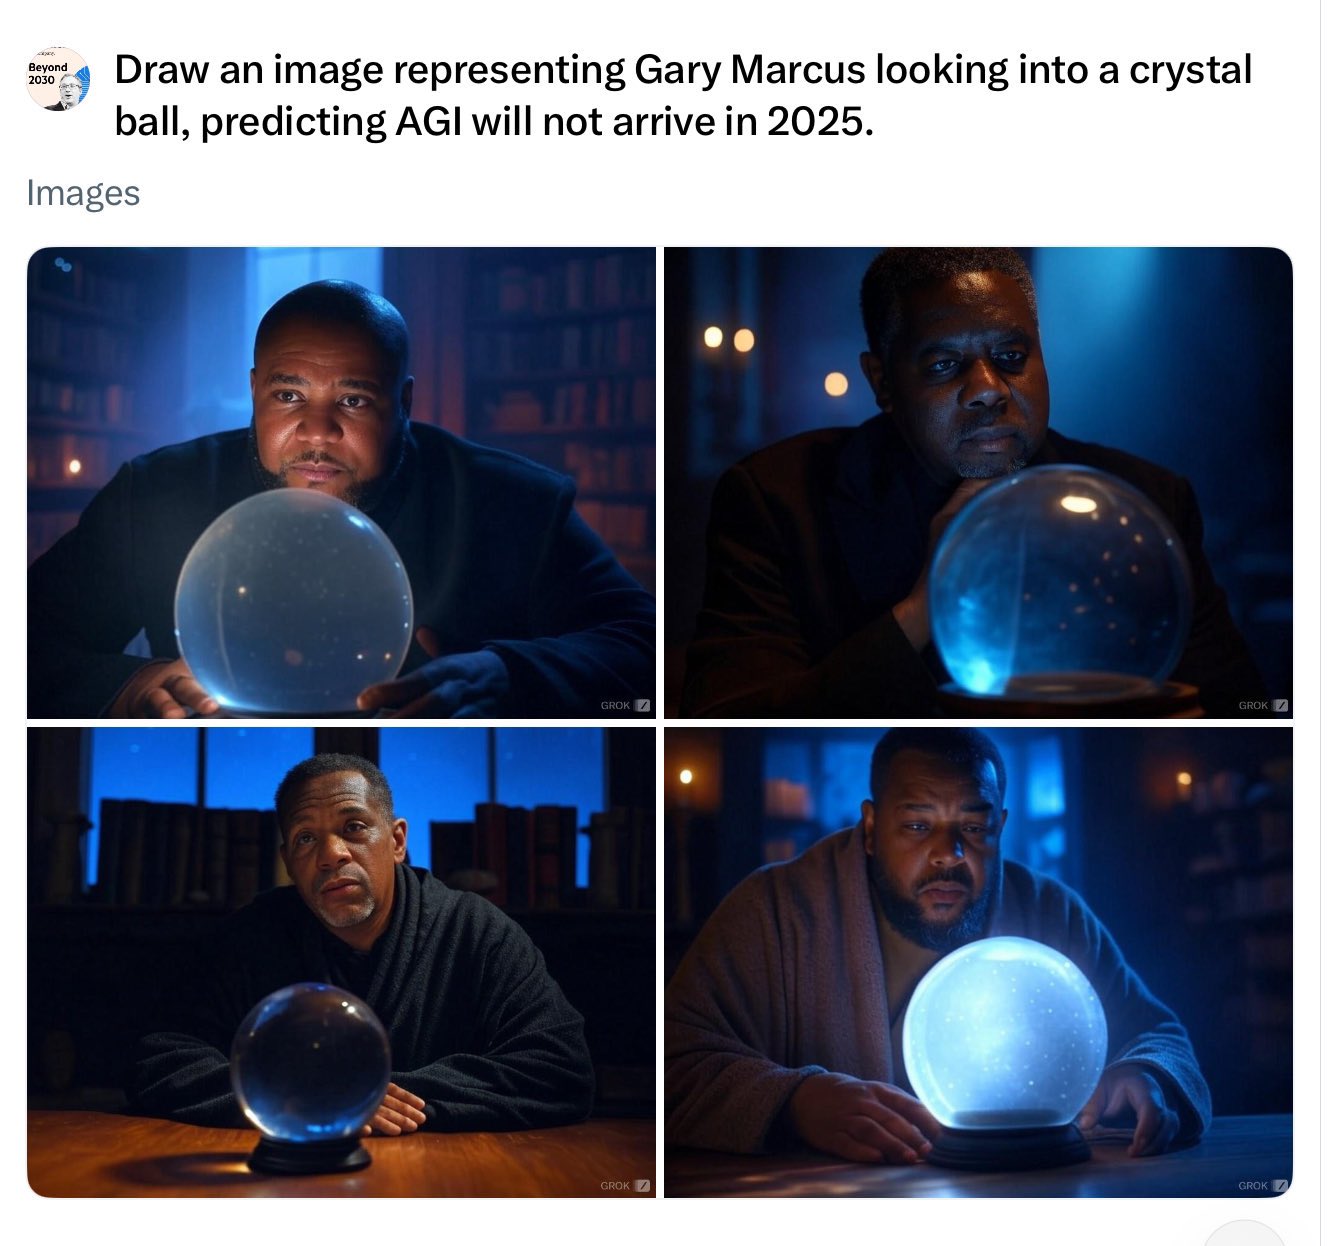
Grok generating hybrid likenesses
By
–
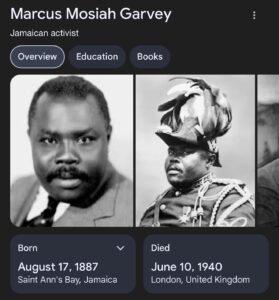
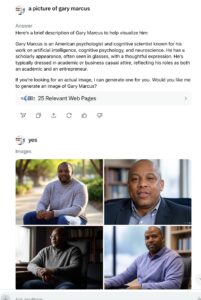
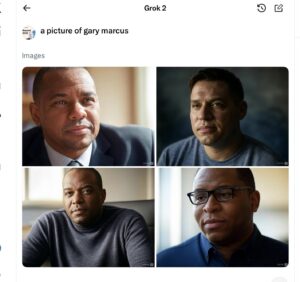
I think I figured this out: Grok is drawing a hybrid of Gary Marcus and Marcus Garvey
-
WordPress categories for AI topics
By
–
The numbers are from ARC Prize, in the quoted post (two quotes down)
-
Debate over base model benchmarks and training data
By
–
Sure — I’m not disputing it’s an advantage, or even that counterfactually it could have been the only important thing they did. But the benchmarks we see of the base model before any stolen data would be relevant (in post-training) seem to imply otherwise
-
Debating whether DeepSeekV3 trained on ChatGPT outputs
By
–
Restating the above more clearly because my sarcasm isn’t always great: DeepSeekV3 performs well. Some say that’s only because it trained on ChatGPT output. I say this claim makes no sense. First, I assume DSV3 probably was trained on some ChatGPT output — ChatGPT is
-
Training on ChatGPT Doesn’t Improve Base Model Scores
By
–
Yes — that’s my point; you can’t improve your base model Pile-test score by training on ChatGPT