Old way: • write prompt
• wait
• get clip
• hate it
• start over New way: • think it
• see it build LIVE at 1080P
• change anything mid-generation
• it never stops The render bar is dead.
@godofprompt
-
From waiting and hating to live interactive generation
By
–
-
PixVerse R1: Real-time world model replaces AI video generation
By
–
AI video just died. What comes next is so much better it's not even the same category. PixVerse R1 isn't a video generator. It's a real-time world model that responds to your thoughts instantly. This changes everything.
-
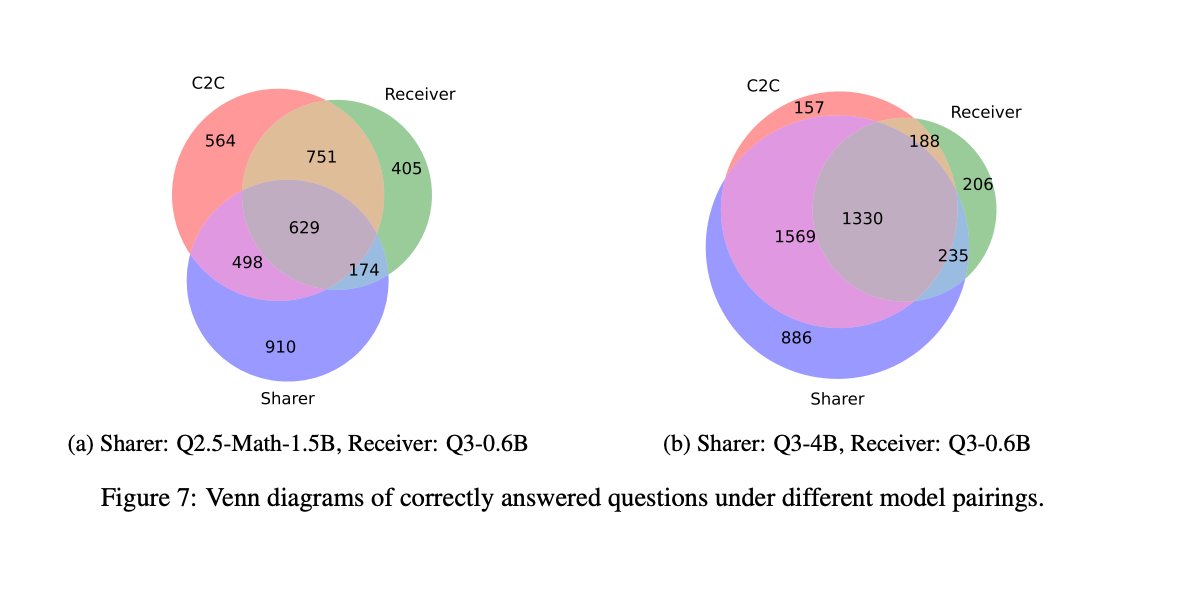
C2C outperforms traditional Text-to-Text on four benchmarks
By
–
8. C2C was rigorously tested on four major challenges: MMLU-Redux, OpenBookQA, ARC-Challenge, and C-Eval. It significantly outperformed the traditional "Text-to-Text" approach.
-

Efficient Cache Improves Model Performance Without Retraining
By
–
7. The paper demonstrated that improving a model's performance is possible by utilizing a more efficient cache. This enhancement does not require adding extra words or retraining, maintaining the same input length while enhancing understanding.
-

C2C introduces neural Fuser to connect model KV-Caches
By
–
5. Each model possesses a memory storage referred to as KV-Cache. C2C introduces a small neural "Fuser" that connects the memory of one model to another, facilitating information sharing and collaboration.
-
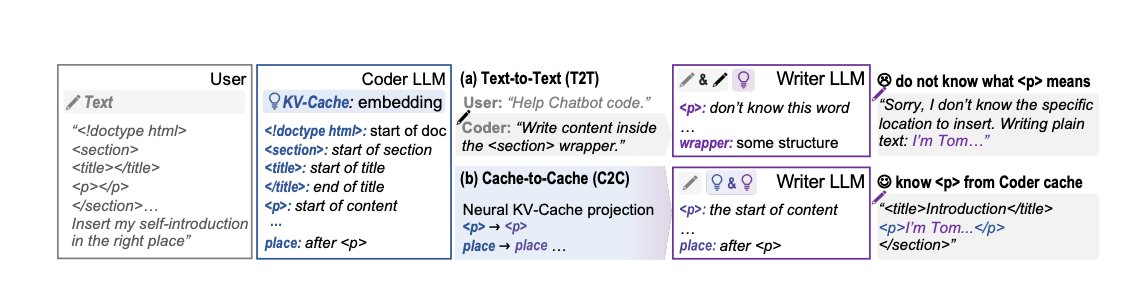
Architectural breakthrough: model pairs boost accuracy and speed
By
–
The results are insane: – 8.5-10.5% higher accuracy than individual models
– 3.0-5.0% better than text-based communication
– 2× speedup in latency
– Works across ANY model pair (different sizes, architectures, tokenizers) This isn't incremental. It's architectural. -

C2C is telepathy for AI, replacing slow telegram-like communication
By
–
Every LLM today communicates like humans sending telegrams. Model 1 generates text → Model 2 reads text → repeats. It's slow, expensive, and loses meaning in translation. C2C is telepathy for AI models.
-

Cache-to-Cache: LLMs talk via KV-Caches, 10% accuracy boost, 2x speed
By
–
Researchers just made LLMs talk to each other WITHOUT generating a single word. Cache-to-Cache (C2C) lets AI models talk directly through their KV-Caches, bypassing text entirely. 8.5-10.5% accuracy boost. 2× faster. Zero token waste. Here's the breakthrough (and why this
-

AI Skills from 2025 Useless, New Playbook for 2026 Event
By
–
90% of the AI skills you learned in 2025 are already useless. 2026 requires a completely different playbook. I'm breaking down what's dead vs. what's next at AI Skills'2026 on Jan 22. 4,000+ attendees. 4+ hours. Free. Join free https://
conf.cosprints.ai/?3