
Here’s the cycle that traps you. AI speeds up a task → expectations for speed rise → you rely more on AI → you take on wider scope → workload intensifies → repeat
@godofprompt
-
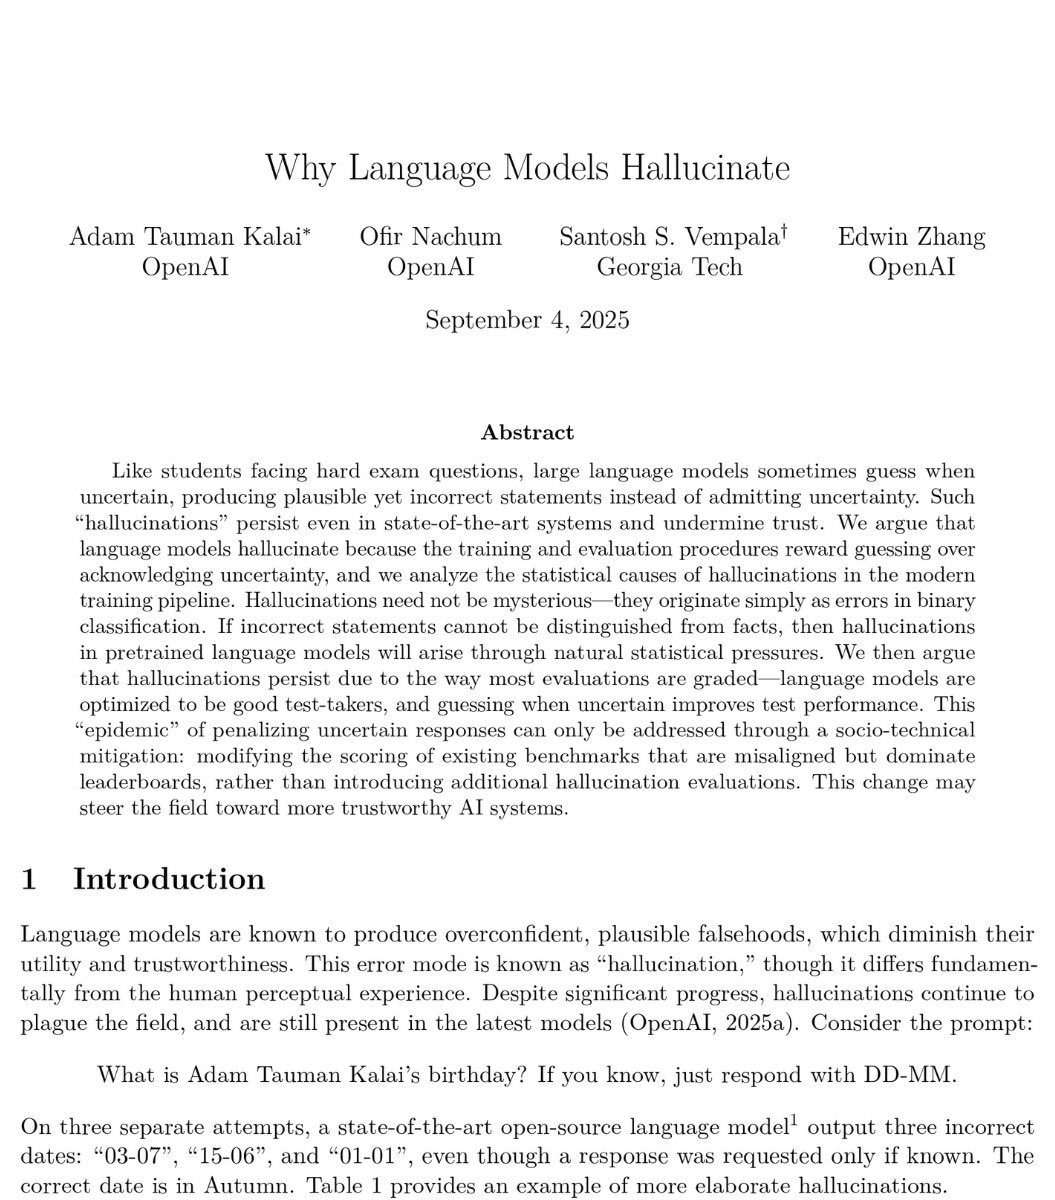
OpenAI Proves AI Hallucinations Are Inevitable
By
–
BREAKING: OpenAI just mathematically proved that no AI model will ever stop hallucinating. Their paper demonstrates that the way language models generate text, predicting one word at a time based on probability, creates a mathematical floor of error that cannot be engineered
-
Hackathon Winner Freely Reveals Claude System
By
–
BREAKING: An Anthropic hackathon winner just gave away the entire system for free. @affaanmustafa beat 100+ participants at the Anthropic x Forum Ventures hackathon. Built http://
zenith.chat in 8 hours using Claude Code. Walked away with $15K in API credits. Then he -
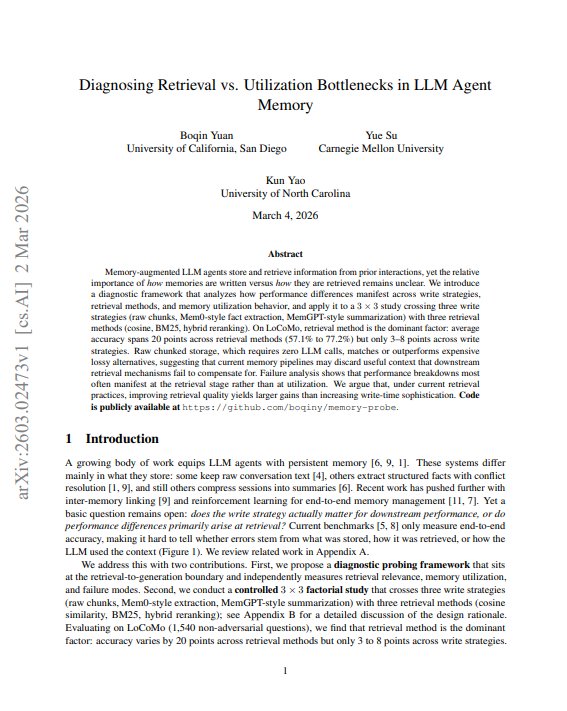
Retrieval, Not Writing, Boosts AI Memory Accuracy
By
–
most people building AI agents obsess over how they WRITE memories.
turns out that's basically irrelevant. new research analyzed 9 different memory systems across 1,540 questions.
the finding? – retrieval method drives 20-point accuracy swings.
– write strategy? 3–8 points max. -
Why most finance prompts fail
By
–
What separates these prompts from the ones circulating on X: Most finance prompts follow the same pattern: "You are a Goldman VP. Give me a DCF." That's a search query dressed as a prompt. It produces generic output because Claude gets no methodology, no constraints, and no
-
Anthropic Launches 5 Finance Plugins for Claude
By
–
What just changed: On February 24, Anthropic launched 5 dedicated Claude finance plugins: financial analysis, investment banking, equity research, private equity, and wealth management. The investment banking plugin can review transaction documents, analyze comparable
-
Claude Ranks High in 2026 Finance Benchmark
By
–
Anthropic just built Claude specifically for investment banking. Wall Street Prep's 2026 benchmark ranked Claude #2 for finance tasks, with a score of 5.5 out of 10 – ahead of Copilot (4.4) and ChatGPT (2.5). Most finance prompts circulating on X are basic role assignments. No
-
Models Know Longer Isn’t Always Better
By
–
the deeper point here connects to something the field keeps rediscovering. we trained reasoning models to think longer. then we discovered longer doesn't mean better. now this paper shows the models themselves already know that. they're generating stop signals that our inference
-
DeepSeek and Qwen3 performance improvements
By
–
specific numbers worth sitting with: > DeepSeek-R1-7B on MATH-500: 93% accuracy (up from 91.6%), tokens cut from 3,871 to 2,141 > DeepSeek-R1-1.5B on AIME 2025: accuracy jumps 6.2 percentage points > Qwen3-8B: response length halved from 18,342 to 9,183 tokens with no accuracy
-
SAGE-RL: Simple RL Training Modification
By
–
then they fold it into training with SAGE-RL. dead simple modification: in standard reinforcement learning (GRPO), you sample 8 responses per question. SAGE-RL replaces 2 of those 8 with SAGE-generated samples. the other 6 stay normal. one-line code change. the model learns to