THIS WORKS: You can use Claude to filter out freelancers who are faking their prompting skills. Open a shared screen. Give them a fresh Claude session. Run these 7 challenges live, like a coding interview but for prompting. Nothing rehearsed. Just them, Claude, and 30
@godofprompt
-
Trend: Fewer Modes, More Autonomous AI Coding Agents
By
–
This is the AI coding agent trend in one sentence: Fewer modes. More autonomy. TRAE is moving from “pick the right coding assistant” to “tell one agent what to build and let it orchestrate the workflow.” Try it here:
-
SOLO Agent Dynamically Loading MCPs for Real-World Apps
By
–
The MCP side is especially interesting. TRAE’s unified SOLO Agent can dynamically load configured MCPs as the project evolves, instead of getting boxed into one rigid setup. That matters when you’re building real apps with databases, payments, AI services, and deployment tools.
-
AI agents that automate idea-to-deployment workflows
By
–
That’s the real unlock: Less mode-switching.
Less setup friction.
Less “wait, which workflow do I need?” The agent can move from idea → app → tool connections → deployment without forcing you to babysit every step. -
SOLO Agent auto-selects tools and sub-agents
By
–
This sounds small until you actually build with agents. Before, you had to pick the right agent for the right task. Now you just describe what you want. TRAE’s SOLO Agent decides which capabilities, tools, MCPs, and sub-agents to use automatically.
-
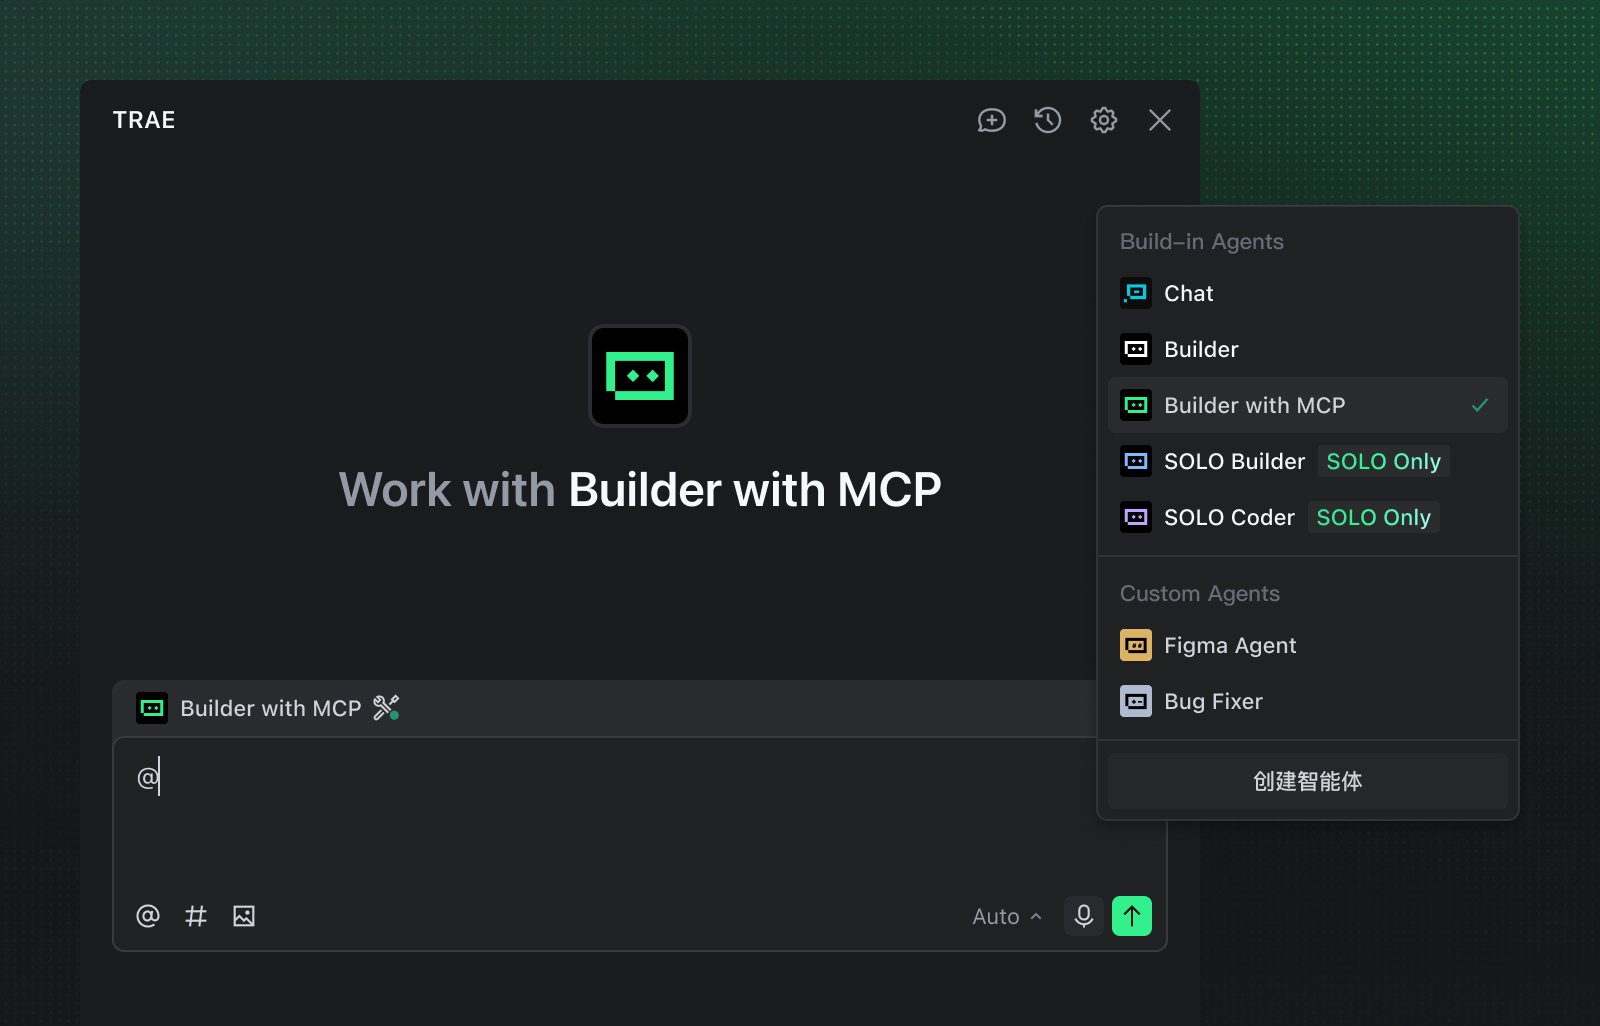
Trae merges SOLO Builder and SOLO Coder into unified SOLO Agent
By
–
TRAE just killed the “which agent should I use?” problem. SOLO Builder and SOLO Coder are now merged into one unified SOLO Agent. One agent for frontend apps, complex programming tasks, routine dev work, MCPs, tools, and shipping. @Trae_ai
-
Agents need memory for production-ready flows
By
–
Agents don’t need another shiny demo.
— God of Prompt (@godofprompt) 28 mai 2026
They need memory for the boring production flows that actually matter.
Rote turns successful API runs into replayable local flows, so agents stop burning tokens to rediscover what already worked.
That’s the missing infra layer.@modiqoai… https://t.co/WWmEgi3V0zAgents don’t need another shiny demo. They need memory for the boring production flows that actually matter. Rote turns successful API runs into replayable local flows, so agents stop burning tokens to rediscover what already worked. That’s the missing infra layer. @modiqoai
-
GPT-5.5 Leads — Industry Leaderboard Misrepresented Parity
By
–
The takeaway here isn't about which model won. GPT-5.5 is ahead right now. That could change next month. The takeaway is that the leaderboard the industry has been citing for months was telling a story of parity that never existed. The models aren't as close as we thought. Some
-
Claude benchmarked: SWE-Bench Pro vs DeepSWE performance
By
–
That Haiku number is the one worth sitting with. Claude Haiku scores 39% on SWE-Bench Pro. On DeepSWE, where it can't coast on contaminated data or exploit the test environment, it scores zero. Not low. Zero. That's not a model that dropped in performance. That's a model that
-
DeepSWE designed to prevent dataset contamination and cheating
By
–
DeepSWE was designed to make all of this impossible. Tasks written from scratch. Not pulled from public commits. No contamination. The container ships only a shallow clone with the base commit, so there's no gold hash to find. Hand-written verifiers. Solutions require over 5x