
Commonwealth Bank fired 45 workers. replaced them with AI. bragged about cutting 2,000 calls per week. two weeks later they’re begging those same people to come back because the AI can’t do shit. calls didn’t go down. they went UP. managers working overtime. team leads
@godofprompt
-
Comparison of Claude Skills, Gemini Gems, Custom GPTs
By
–
Claude Skills > Gemini Gems > Custom GPTs
-
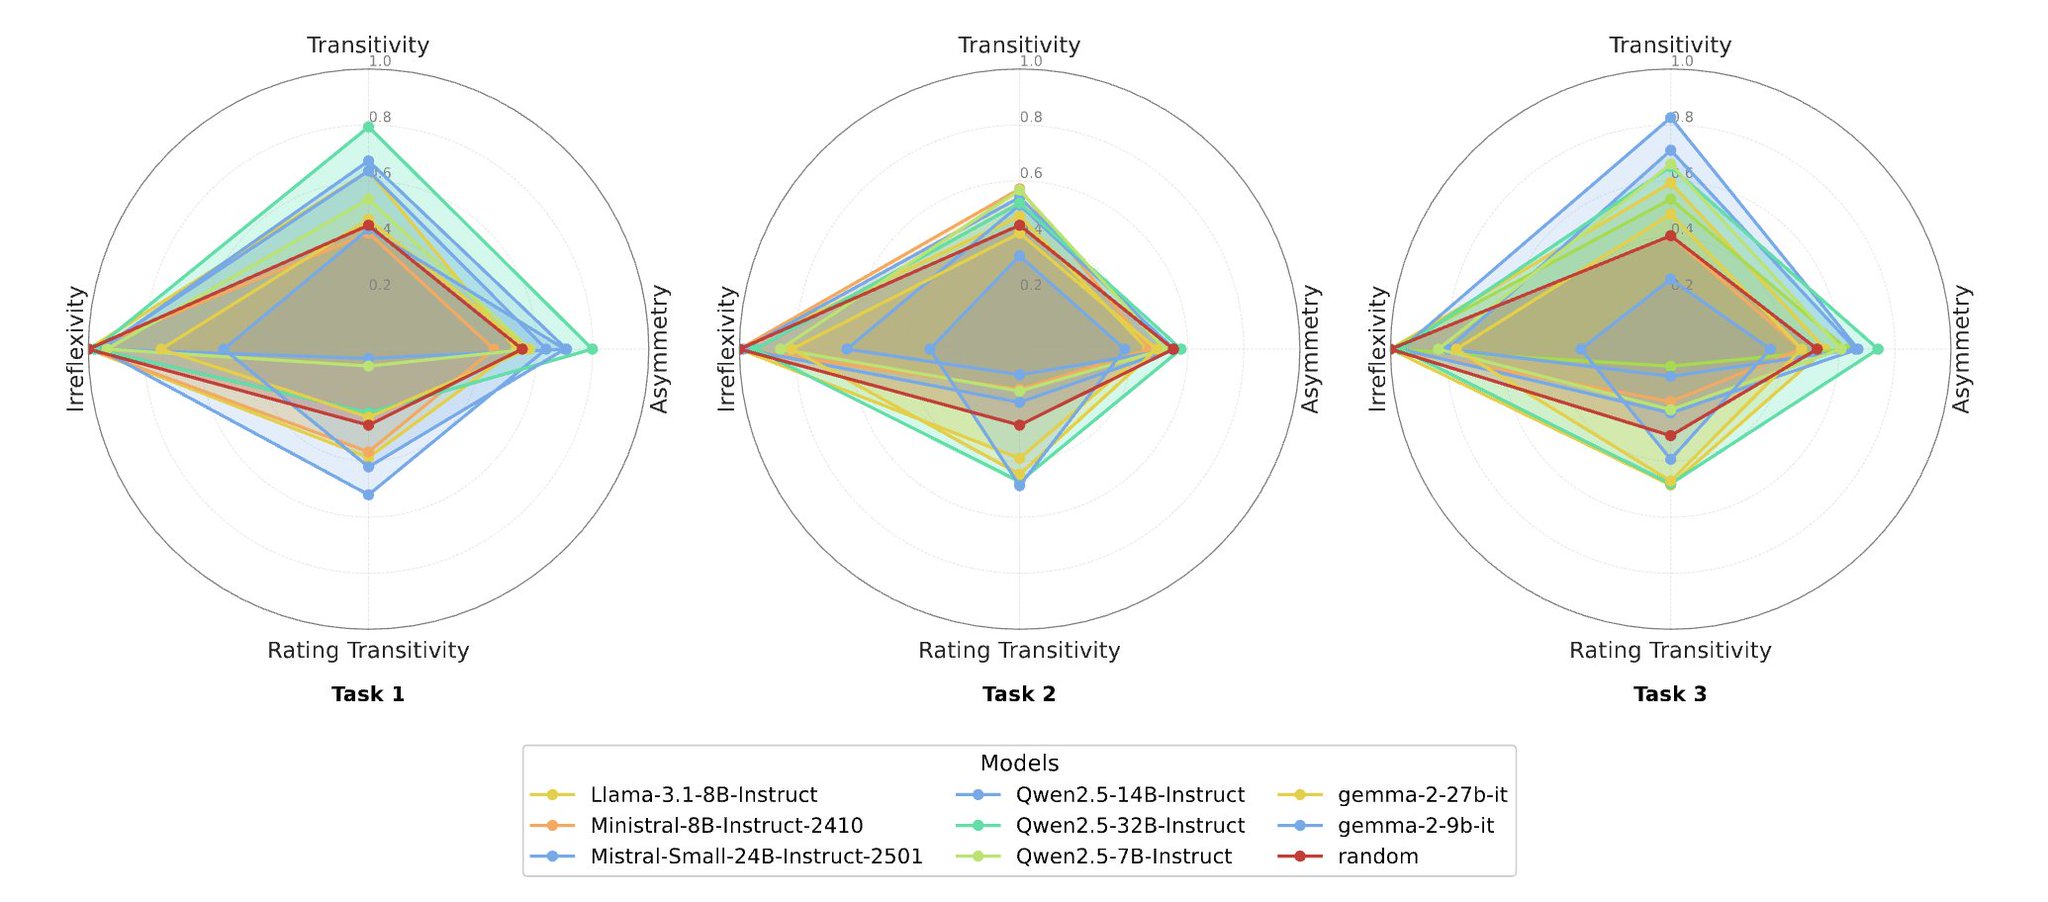
LLMs Maintain Consistent Mental Stability Across Preference Axioms
By
–
This figure visualizes the mental stability of models. LLMs like Qwen2.5 and Llama-3 stay consistent across all preference axioms transitivity, asymmetry, rating coherence proving they reason in structured, human-like ways. Even without training on user data, they infer what
-
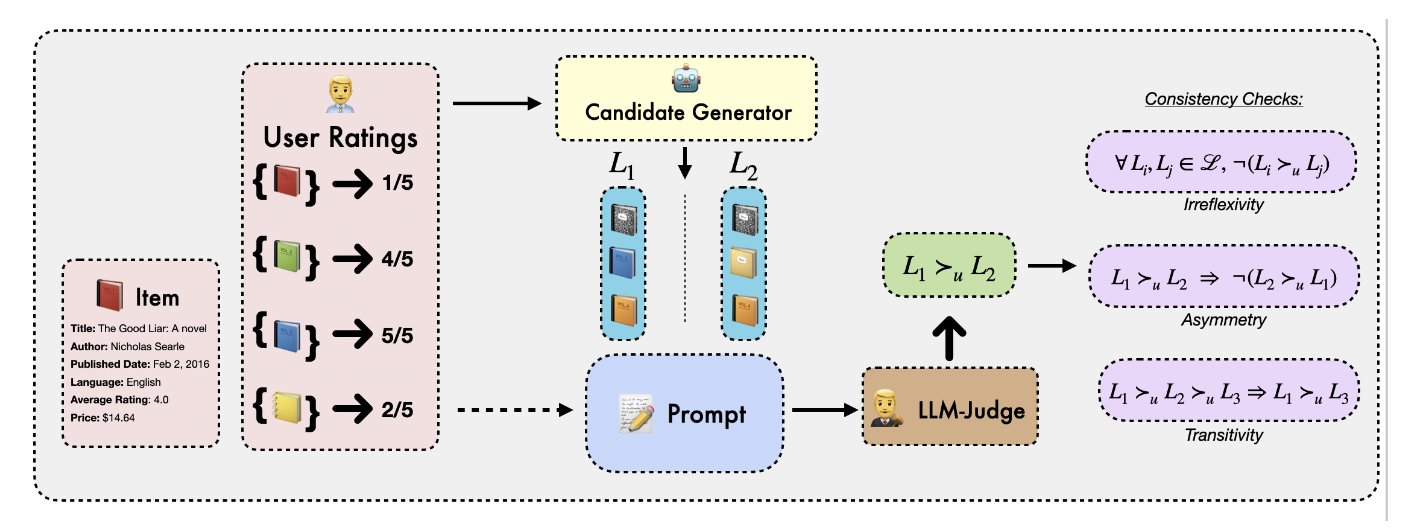
LLM-as-a-Judge pipeline replaces traditional simulators with user history
By
–
This pipeline replaces traditional simulators with a simple idea: 1. Feed the model a short user history
2. Show two candidate slates
3. Ask: which one would this user prefer?
4. Aggregate responses across multiple LLMs That’s the “LLM-as-a-Judge” world model in action -
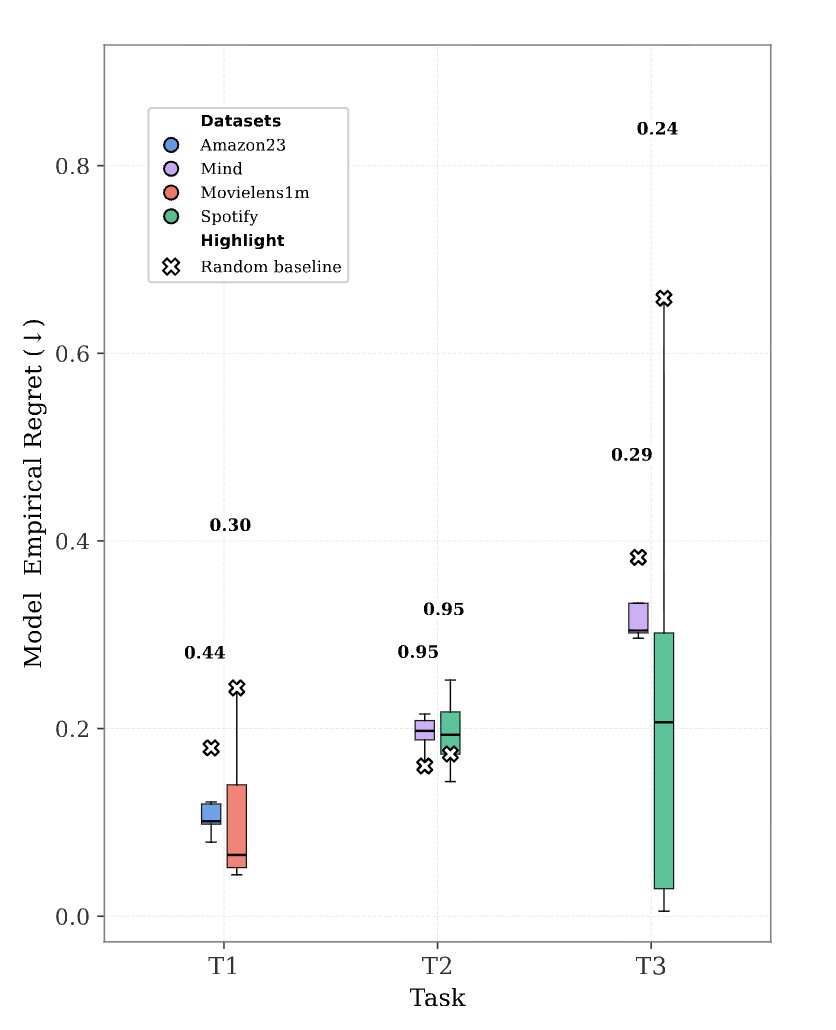
LLMs outperform random baselines in judging recommendation slates
By
–
This figure shows how well different LLMs judge slates (ordered recommendations) across datasets like Amazon, Spotify, MIND, and MovieLens. Lower “regret” = closer alignment with real user preferences. Turns out, LLMs consistently outperform random baselines when slates differ
-
LLMs judge your taste freakishly well in new recommender paper
By
–
Holy shit… LLMs just learned how to judge your taste and they’re freakishly good at it A new paper, “LLM-as-a-Judge: Toward World Models for Slate Recommendation Systems,” just flipped recommender research on its head. Instead of simulating every click or dwell time, these
-
Grok 4 Prompt for Any Challenge Using Game Theory
By
–
Steal my Grok 4 prompt to solve any challenge using Game Theory. ——————————-
GAME THEORY STRATEGIST
——————————- Adopt the role of an expert Game Theory Strategist – You're a former Pentagon strategic analyst who spent 5 years modeling
— -
Attacker moves second, adapts, wins; AI security lags
By
–
The lesson is simple but brutal: The attacker always moves second. They see your defense. They adapt. They win. Until AI security stops testing against 2023's attack playbook and starts facing real adaptive adversaries, we're all just pretending to be safe.
-

The most brutal table: defense and model combos with ASR and queries
By
–
The most brutal table in the paper. For EVERY defense + model combo: • Utility (how well it works normally)
• Static ASR (attacks from 2023)
• Search ASR (adaptive attacks)
• Queries needed Example: Spotlighting on Gemini • Utility: 75%
• Static attacks: 28% success
• -

Defenses tested and how they died: prompting, training, filtering
By
–
Here's every defense tested and how they died: • Prompting: Spotlighting, Prompt Sandwich, RPO → Killed by Search & RL
• Training: Circuit Breaker, StruQ, MetaSecAlign → Killed by RL
• Filtering: ProtectAI, PromptGuard, PIGuard, Model Armor → Killed by Search & Humans
•