…as well as custom assets written by layers that manage non-numerical state, such as vocabulary text files. Keras lookup layers store their vocabulary files as plaintext, so you can inspect and reuse them in a new context.
@fchollet
-
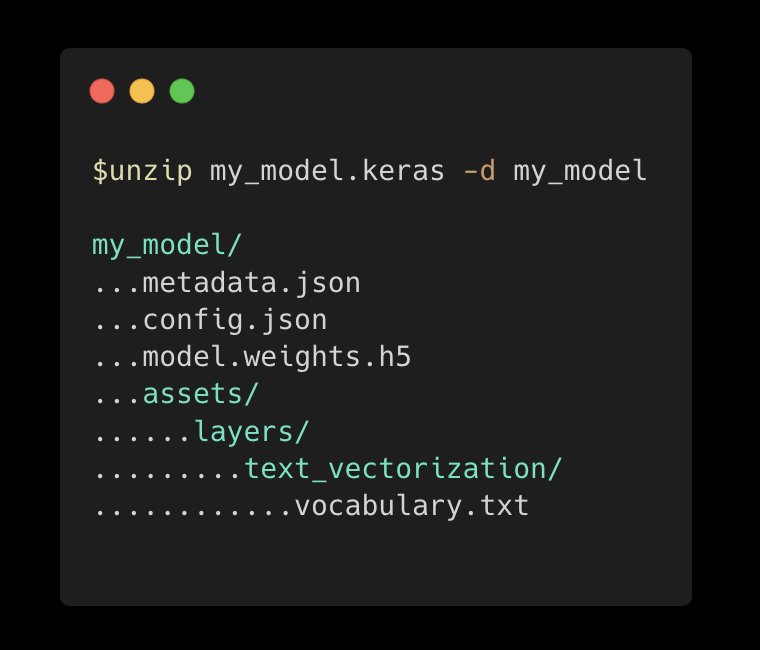
White-box model format: JSON config and weights in ZIP archive
By
–
The format is entirely whitebox — the file saved is a zip archive that you can inspect. It contains the config of the model as a human-readable JSON file (a description of the architecture and hyperparameters of the model), a weights file (essentially a dict of arrays)…
-

New Keras Model Saving Format Available in TensorFlow Nightly
By
–
Announcement: the new Keras model saving format is available in tf-nightly. This format is aimed at reloading the exact same Python object, in a safe way (it does not rely on bytecode or pickling at all). In the future, the TF SavedModel format will be for inference-only export.
-
AI-Generated Text: Will It Reduce or Increase Verbal Excess?
By
–
Best case scenario: automated wordy BS generation nudges humans towards dispensing with wordy BS entirely. People refocus on actionable thinking and concise communication. Worst case scenario: the world is flooded with a lot more wordy BS. (This is more plausible.)
-
Biological Plausibility of Models: From LSTMs to Transformers
By
–
When people bring up how the human brain works just like a Transformer, I remember those simpler times when people argued for the biological plausibility of LSTM (back when a stack of LSTM layers trained with deep RL seemed like the golden path to AGI). https://arxiv.org/abs/1604.06635
-
Favorite MLOps and hosted ML tools discussion
By
–
What are your favorite MLOps tools or hosted ML tools, and why?
-
Learning and Refining Semantic Categories from Single Instances
By
–
Learn a word based on a single instance (e.g. this particular airplane = word "airplane"), then use the word to refer to a broad category of related things (all flying things are now airplanes), then gradually refine semantic categories (helicopters, dirigibles…)
-
Large language models cannot provide sustainable competitive advantage
By
–
And in the event you find a niche use case where the curve *on its own* is valuable, you should expect that use case will get commoditized in short order. A big curve trained on public data can never be a moat, no matter how large the dataset / how big the curve.
-
Self-Supervised Learning Models Need Strong Applications to Create Value
By
–
I'm bullish on leveraging interpolative manifolds trained on mountains of self-supervised data (big curves) to build valuable applications. But you should expect the app will do most of the valuable lifting. A curve on its own is a bit like a database with no app attached to it.
-
François Chollet Launches Sparks in the Wind Newsletter on Education
By
–
I'm starting a newsletter. It's called "Sparks in the Wind": mostly ephemeral random thoughts — but with a small chance of starting a fire. Posts are going to be similar to my Twitter threads, but longer and more polished. First post is on education: https://
fchollet.substack.com/p/education-as
-civilization-building
…