This is true — gen AI will add value (and thus revenue) to a wide range of products, but… this is irrelevant to how much a chatbot/API provider should invest in model training. What they should invest on depends on how much money *they* will make via their subscriptions and
@fchollet
-
Models as Fast-Depreciating Assets with Limited Lifespan
By
–
Also — models are fast-depreciating assets. Lifespan is 2 years or less.
-
Keras Layer for Raw Audio to Mel Spectrogram Conversion
By
–
Do you work with audio data? If we add a Keras layer to convert raw audio to Mel spectrograms, would you be interested?
-
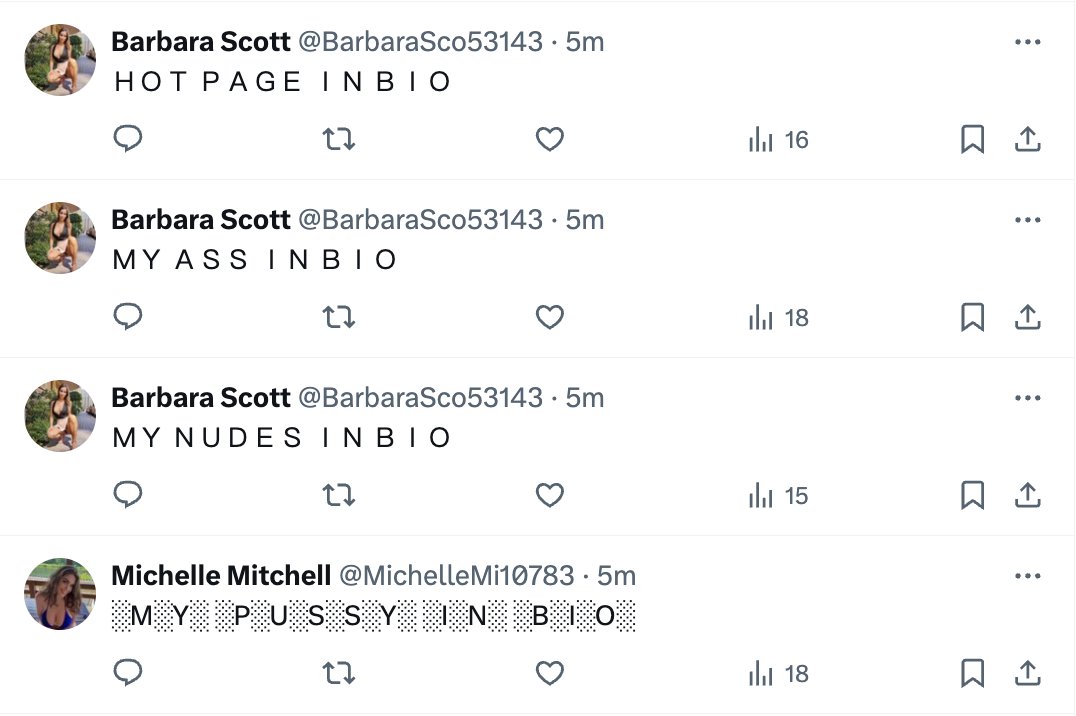
AGI on the Horizon: Yet Bot Detection Remains Challenging
By
–
Yes, we may be on the cusp of AGI. But using AI to automatically detect and block bots like this remains elusive, due to their use of a remarkably sophisticated evasion technique — whitespace.
-
XOR Representability vs Efficiency in Program Search
By
–
There's no connection, XOR was a representability issue. It's easy to fit a curve to a XOR dataset. That said, doing so is tremendously inefficient compared to program search over a DSL that just has NOR, for instance. So if you want a parallel, it's there.
-
Transformers Excel at Interpolation but Struggle with Symbolic Learning
By
–
Not saying that Transformers are worse than RNNs, mind you — Transformers are *the best* at *what deep learning does* (generalizing via interpolation), specifically *because* of their strongly interpolative architecture prior (MHA). They are, however, worse at learning symbolic
-
RNNs: The Core Principle of Recurrence and Latent Space Iteration
By
–
RNNs are… recurrent. It's right there in the name. That was the entire intuition behind creating them: iterating in latent space, like the brain.
-
Transformers’ Interpolative Architecture and Limitations for Symbolic Tasks
By
–
Ironically, Transformers are even worse in that regard — mostly due to their strongly interpolative architecture prior. Multi-head-attention literally hardcodes sample interpolation in latent space. Also, the fact that recurrence is a really helpful prior for symbolic programs.
-
RNNs and Universal Computation: A 2013-2016 Perspective
By
–
From 2013 to 2016 I was actually quite convinced that RNNs could be trained to learn any program. After all, they're Turing-complete (or at least some of them are) and they learn a highly compressed model of the input:output mapping they're trained on (rather than mere pointwise
-
The Limitations of Curve-Fitting for Symbolic Reasoning Tasks
By
–
The "aha" moment when I realized that curve-fitting was the wrong paradigm for achieving generalizable modeling of problems spaces that involve symbolic reasoning was in early 2016. I was trying every possible way to get a LSTM/GRU based model to classify first-order logic