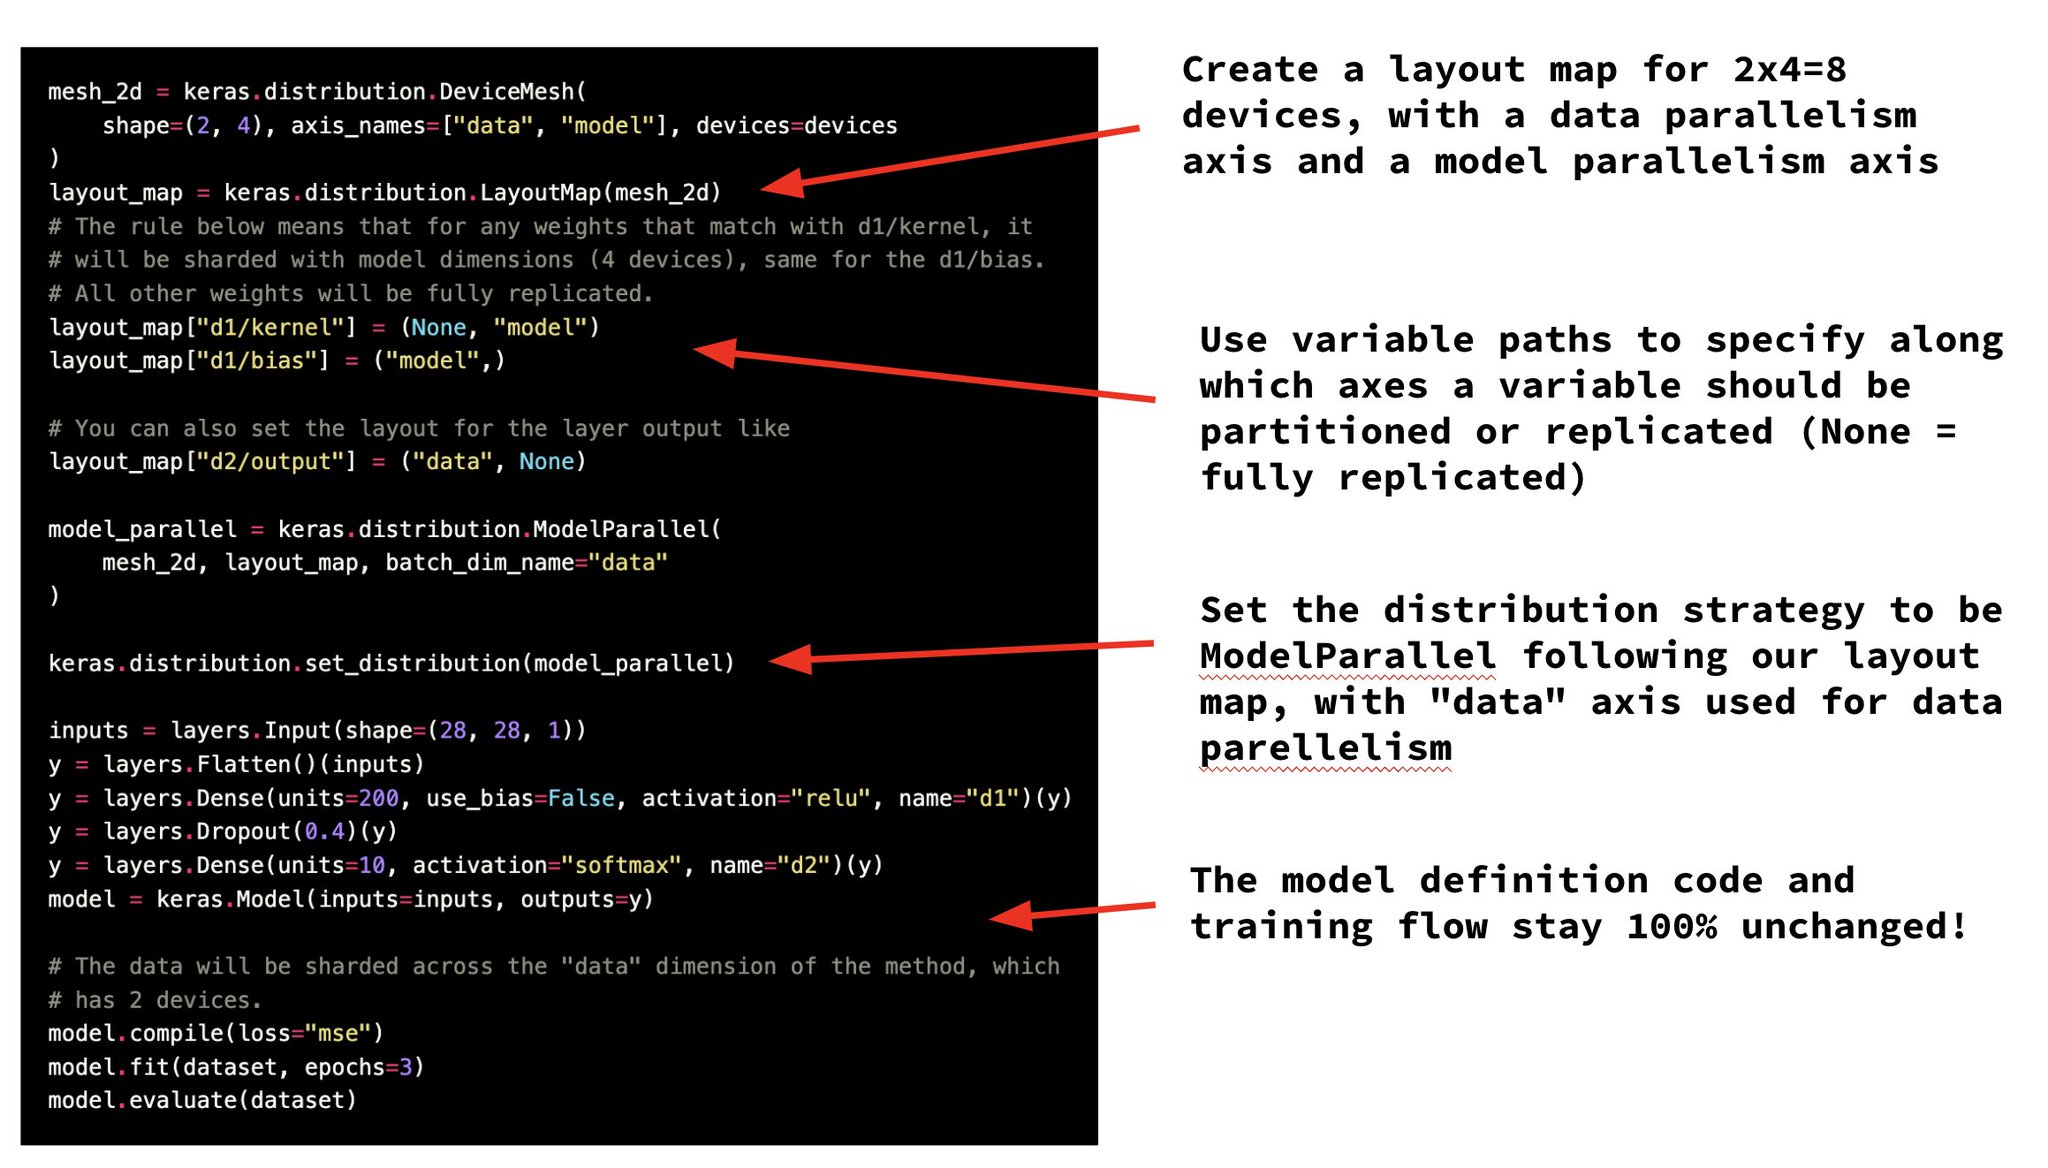
Every other model parallelism API I've seen has partitioning annotations in-lined in the model code and uses custom training logic — making it challenging to modify and maintain the partitioning config. Keras 3 dramatically simplifies this.
@fchollet
-
Keras 3 JAX Enables Efficient Distributed Model Training
By
–
Keras 3 + JAX makes it possible to efficiently distribute large models via both data parallelism and model parallelism (variable partitioning) across arbitrarily many devices. It doesn't require modifying your model code or your training code at all — all you need is to
-
Contributing sampling functions to Keras random module
By
–
Do you want to open a PR? You can definitely add more sampling functions to `keras.random`
-
Keras Compiles to JAX, TensorFlow, PyTorch with JAX Recommended
By
–
Keras code compiles to JAX, TensorFlow, or PyTorch code, so anything you can do with one of these frameworks you can do with Keras. I recommend using JAX as your backend, as it is suitable for very-large scale computation and can be easily parallelized across many devices.
-
GPU acceleration and XLA compilation limitations in framework integration
By
–
But then you would not be able to run it on GPU, nor compile to XLA for a ~5x speedup, nor use it inside a TensorFlow codebase or a PyTorch codebase.
-
Keras ops API: NumPy syntax across JAX PyTorch TensorFlow
By
–
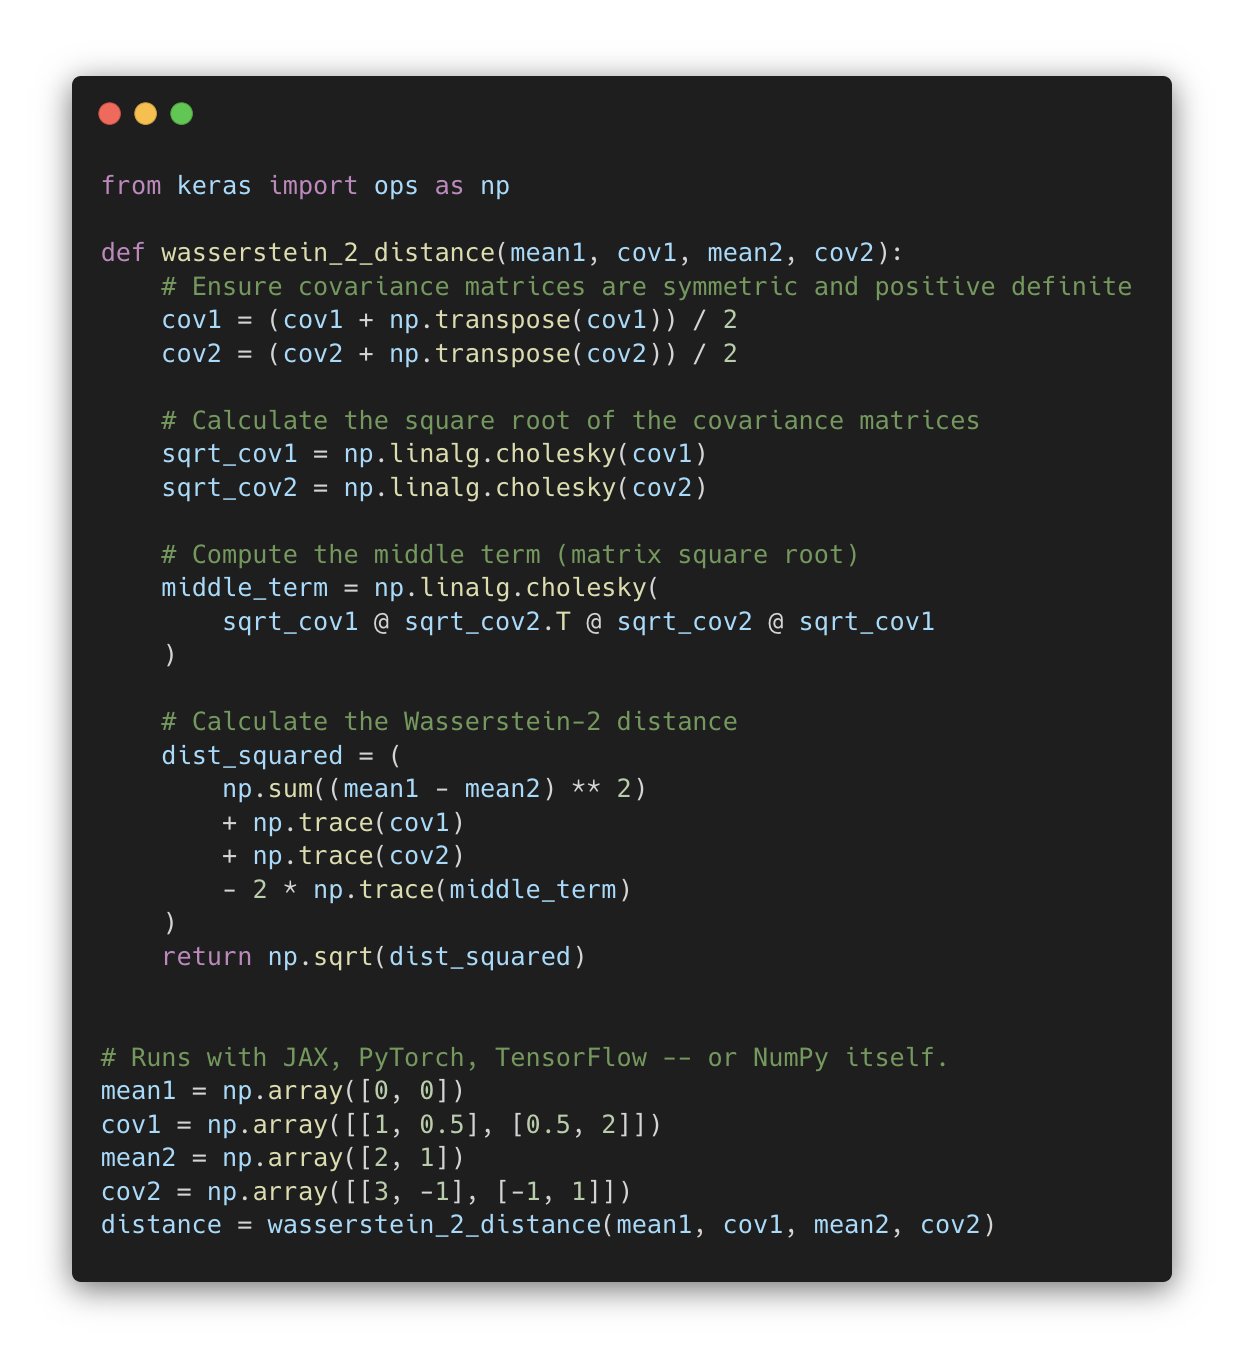
A neat feature of Keras is that its `keras.ops` API follows the NumPy API syntax exactly. And since it runs on JAX, PyTorch, TensorFlow, and NumPy itself, you can use Keras to write GPU-accelerated NumPy code that runs with any framework.
-
Critique of flawed paper on model interpolation definition
By
–
I've seen a paper that argued that, but it was utterly idiotic since it used "L2 interpolation in encoding space" as its definition for "interpolation". Effectively, it was saying, "models that aren't linear aren't linear".
-
Regularization as a Prior: Simplicity Without Extrapolation
By
–
Regularization is a prior towards simplicity. It is not a domain-specific prior and does not enable extrapolation on its own.
-
Broken Control Mechanisms and Misaligned Incentives
By
–
It will happen regardless, because the incentives are stacked this way, and because control mechanisms (peer review and social validation) are broken or non existent.
-
LLM-Generated Papers Risk Slowing Scientific Progress
By
–
What's holding back research isn't a lack of verbose, low-signal, high-noise papers. Using LLMs to automatically generate 100x more of those will not accelerate science, it will slow it down.