
1). Self-Adaptive LLMs – introduces Transformer^2, a novel self-adaptation framework that adapts LLMs for unseen tasks in real-time by selectively adjusting singular components of their weight matrices…
@dair_ai
-
Top AI Papers Week: VideoRAG, MiniMax-01, Self-Adaptive LLMs
By
–
Here are the top AI Papers of the Week (Jan 13-19): – VideoRAG
– MiniMax-01
– Enhancing RAG
– Self-Adaptive LLMs
– Foundations of LLMs
– Learning to Memorize at Test Time Read on for more: -
Survey on LLMs: Capabilities and Limitations Insights
By
–
10). A Survey on LLMs – a new survey on LLMs including some insights on capabilities and limitations.
-

Process Reinforcement Implicit Rewards Framework Language Models
By
–
8). Process Reinforcement through Implicit Rewards – a framework for online reinforcement learning that uses process rewards to improve language model reasoning…
-

Can LLMs Design Good Questions? Quality Evaluation Study
By
–
9). Can LLMs Design Good Questions? – systematically evaluates the quality of questions generated with LLMs; here are the main findings: 1) there is a strong preference for asking about specific facts and figures in both LLaMA and GPT models…
-

Cosmos World Foundation Model for Physical AI Training
By
–
7). Cosmos World Foundation Model – a framework for training Physical AI systems in digital environments before real-world deployment.
-

Meta Chain-of-Thought Extends AI System 2 Reasoning Capabilities
By
–
5). Towards System 2 Reasoning – proposes Meta Chain-of-Thought (Meta-CoT), which extends traditional Chain-of-Thought (CoT) by modeling the underlying reasoning required to arrive at a particular CoT.
-
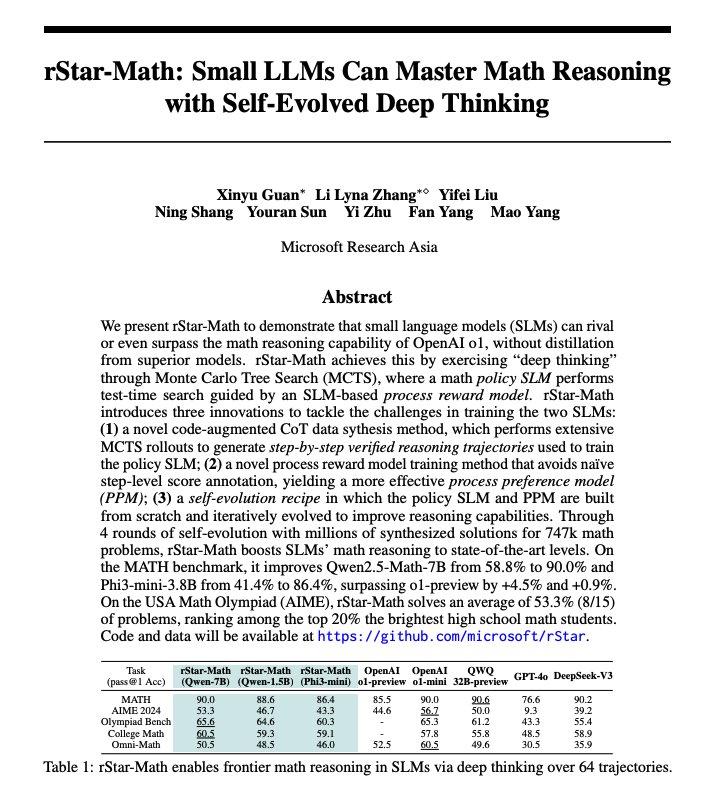
rStar-Math: Code-Augmented CoT for Enhanced Math Reasoning
By
–
6). rStar-Math – a new approach proposes three core components to enhance math reasoning: 1) a code-augmented CoT data synthesis method involving MCTS to generate step-by-step verified reasoning trajectories which are used to train the policy SLM…
-

Agent Laboratory: LLM Agents Advancing Research Process
By
–
2). Agent Laboratory – an approach that leverages LLM agents capable of completing the entire research process; the main findings are: 1) agents driven by o1-preview resulted in the best research outcomes…
-

Search-o1 Framework Combines Reasoning Models with Agentic Search
By
–
4). Search-o1 – a framework that combines large reasoning models (LRMs) with agentic search and document refinement capabilities to tackle knowledge insufficiency…