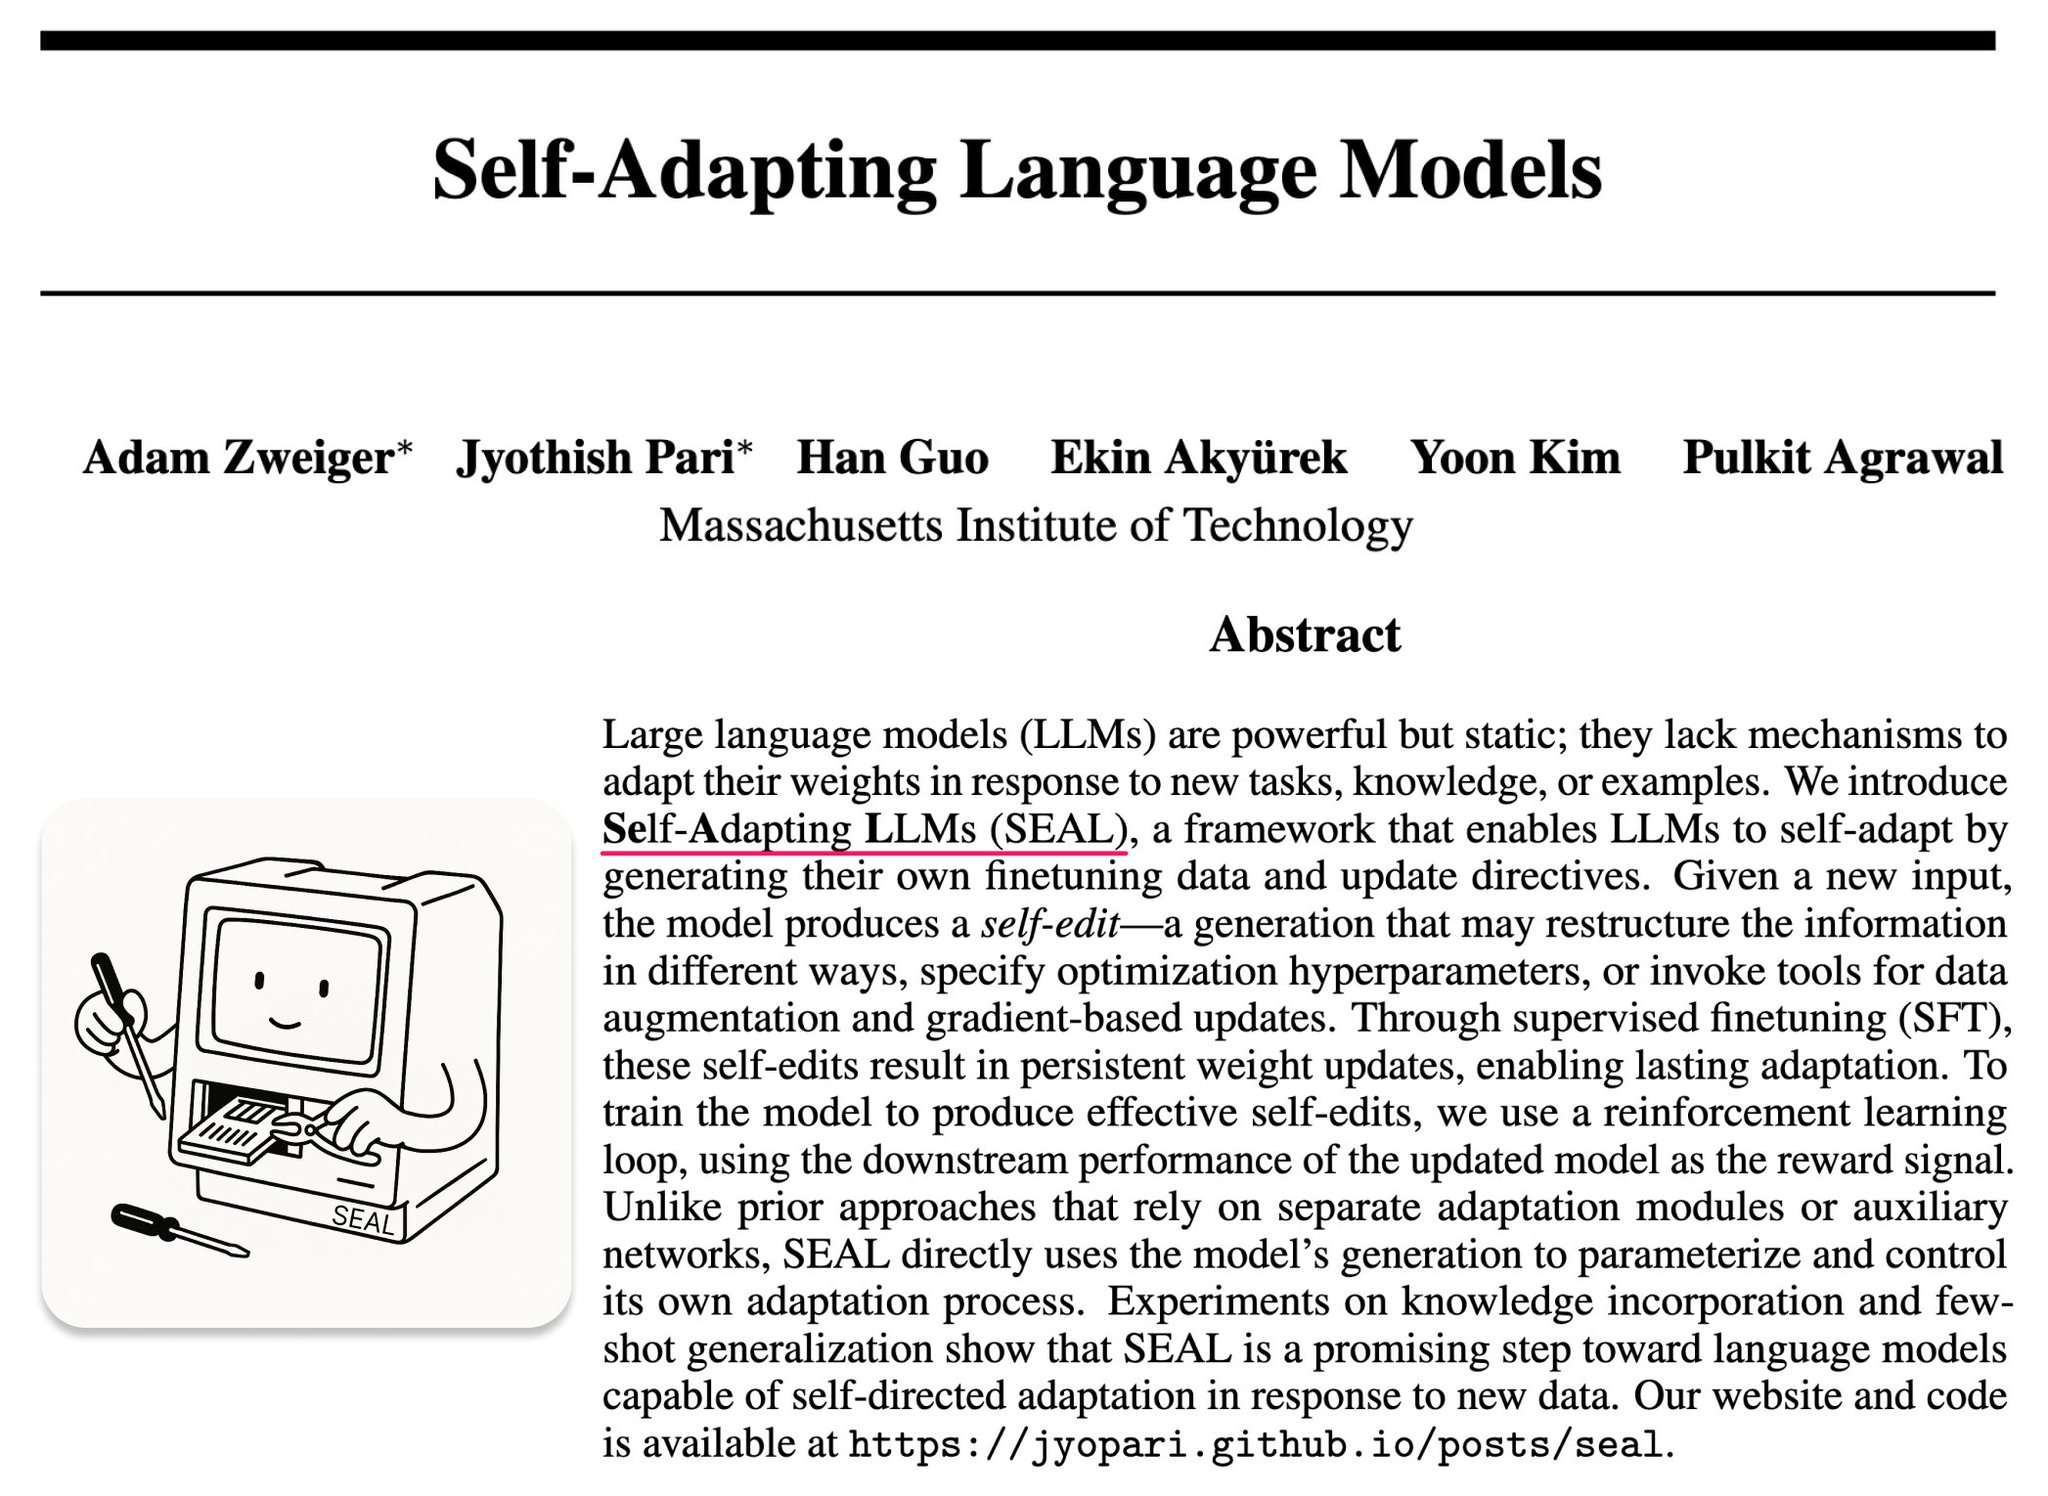
5. Self-Adapting Language Models It proposes a novel framework that enables LLMs to adapt themselves through reinforcement learning by generating their own fine-tuning data and update directives, referred to as “self-edits.”
@dair_ai
-

ComfyUI-R1: 7B Reasoning Model for Automated Workflow Generation
By
–
6. ComfyUI-R1 Introduces ComfyUI-R1, a 7B-parameter large reasoning model fine-tuned for automatic workflow generation in the ComfyUI ecosystem.
-

Reinforcement Pre-Training: Bridging LLM Pretraining and Reasoning
By
–
3. Reinforcement Pre-Training This paper introduces Reinforcement Pre-Training (RPT), a new paradigm that bridges LLM pretraining and RL by reinterpreting next-token prediction as a reasoning task rewarded via verifiable correctness.
-
Meta AI Introduces V-JEPA 2 for Video Understanding
By
–
2. V-JEPA 2 Meta AI introduces V-JEPA 2, a scalable joint-embedding predictive architecture for self-supervised video learning, targeting the goal of building a generalist world model capable of understanding, predicting, and planning in the physical world.
-

Text-to-LoRA: Generate Adapters from Natural Language
By
–
1. Text-to-LoRA Introduces a hypernetwork-based approach for instantly generating LoRA adapters from natural language task descriptions, removing the need for conventional task-specific fine-tuning.
-
Top AI Papers of The Week: V-JEPA, TableRAG, and More
By
–
Here are the top AI Papers of The Week (June 9-15): – V-JEPA 2
– Magistral
– TableRAG
– Text-to-LoRA – Reinforcement Pre-Training
– Self-Adapting Language Models Read on for more: -
RewardBench 2: New Multi-Skill Reward Model Evaluation Benchmark
By
–
9. RewardBench 2 RewardBench 2 is a new multi-skill benchmark for evaluating reward models with more challenging human prompts and stronger correlation to downstream performance.
-
LLM Memorization Capacity: Quantifying 3.6 Bits per Parameter
By
–
10. Memorization in LLMs This study introduces a method to quantify how much a model memorizes versus generalizes, estimating GPT models have a capacity of ~3.6 bits per parameter.
-
AlphaOne: Universal Framework for Controlling LRM Reasoning
By
–
7. AlphaOne Introduces a universal framework, α1, for modulating the reasoning progress of large reasoning models (LRMs) during inference. Rather than relying on rigid or automatic schedules, α1 explicitly controls when and how models engage in “slow thinking” using a tunable
-
Common Pile v0.1: 8TB Open Licensed Text Dataset for LLM Training
By
–
8. Common Pile v0.1 The Common Pile v0.1 is an 8TB dataset of openly licensed text designed for LLM pretraining, addressing legal and ethical concerns of unlicensed data use.