Top ML Papers of the Week (April 24 – 30): – AudioGPT
– Track Anything
– Agents Learn Soccer Skills
– Harnessing the Power of LLMs
– Scaling Transformer to 1M tokens
– A Cookbook of Self-Supervised Learning
…
@dair_ai
-
Top ML Papers Week: AudioGPT, Agents, Transformers, Self-Supervised Learning
By
–
-
Deep Reinforcement Learning Enables Soccer Skills for Humanoid Robot
By
–
1/ Agents Learn Soccer Skills – applies deep reinforcement learning to synthesize agile soccer skills for a miniature humanoid robot; the resulting policy allows dynamic movement skills such as fast recovery, walking, and kicking.https://t.co/A6Yaif0vOs
— DAIR.AI (@dair_ai) 30 avril 20231/ Agents Learn Soccer Skills – applies deep reinforcement learning to synthesize agile soccer skills for a miniature humanoid robot; the resulting policy allows dynamic movement skills such as fast recovery, walking, and kicking.
-
Latent Diffusion Models for High-Resolution Video Generation
By
–
10/ Video Latent Diffusion Models – applies latent diffusion models to high-resolution video generation; validates the model on creative content creation and real driving videos of 512 x 1024 and achieves state-of-the-art performance.https://t.co/8KIUSpH1Rs
— DAIR.AI (@dair_ai) 23 avril 202310/ Latent Diffusion Models – applies latent diffusion models to high-resolution video generation; validates the model on creative content creation and real driving videos of 512 x 1024 and achieves state-of-the-art performance.
-
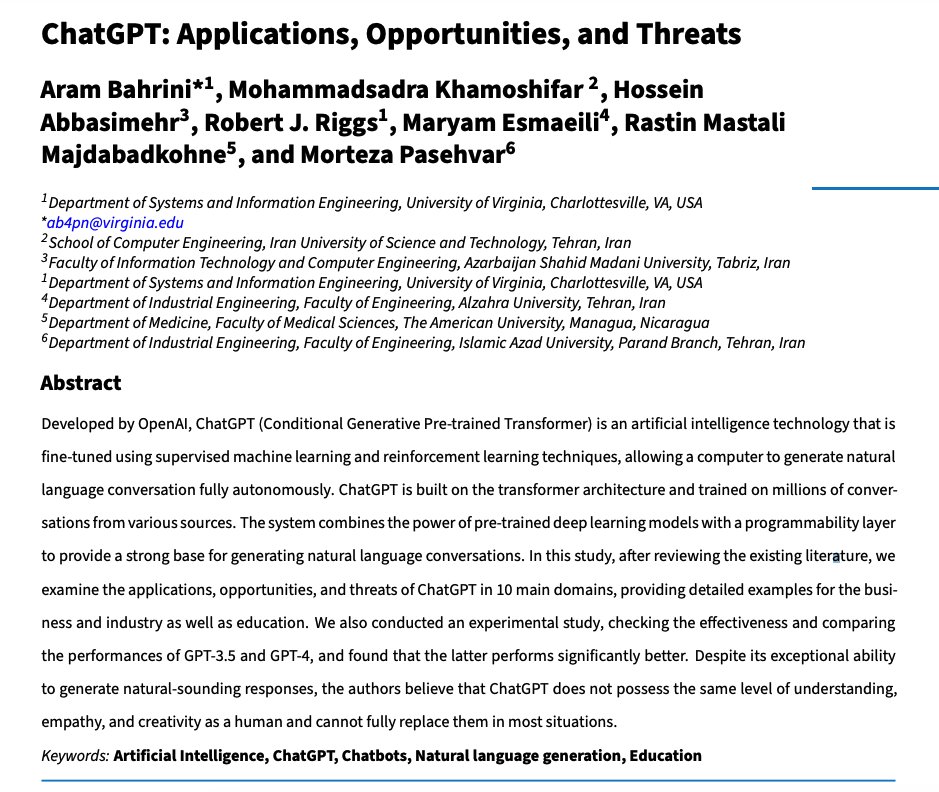
ChatGPT Applications Opportunities and Threats Overview
By
–
8/ Overview of ChatGPT applications, opportunities, and threats
-

Chameleon: Compositional Reasoning Framework for LLM Tool Integration
By
–
9/ Chameleon – a plug-and-play compositional reasoning framework that augments LLMs and can infer the appropriate sequence of tools to compose and execute in order to generate final responses; achieves 87% accuracy on ScienceQA and 99% on TabMWP.
-
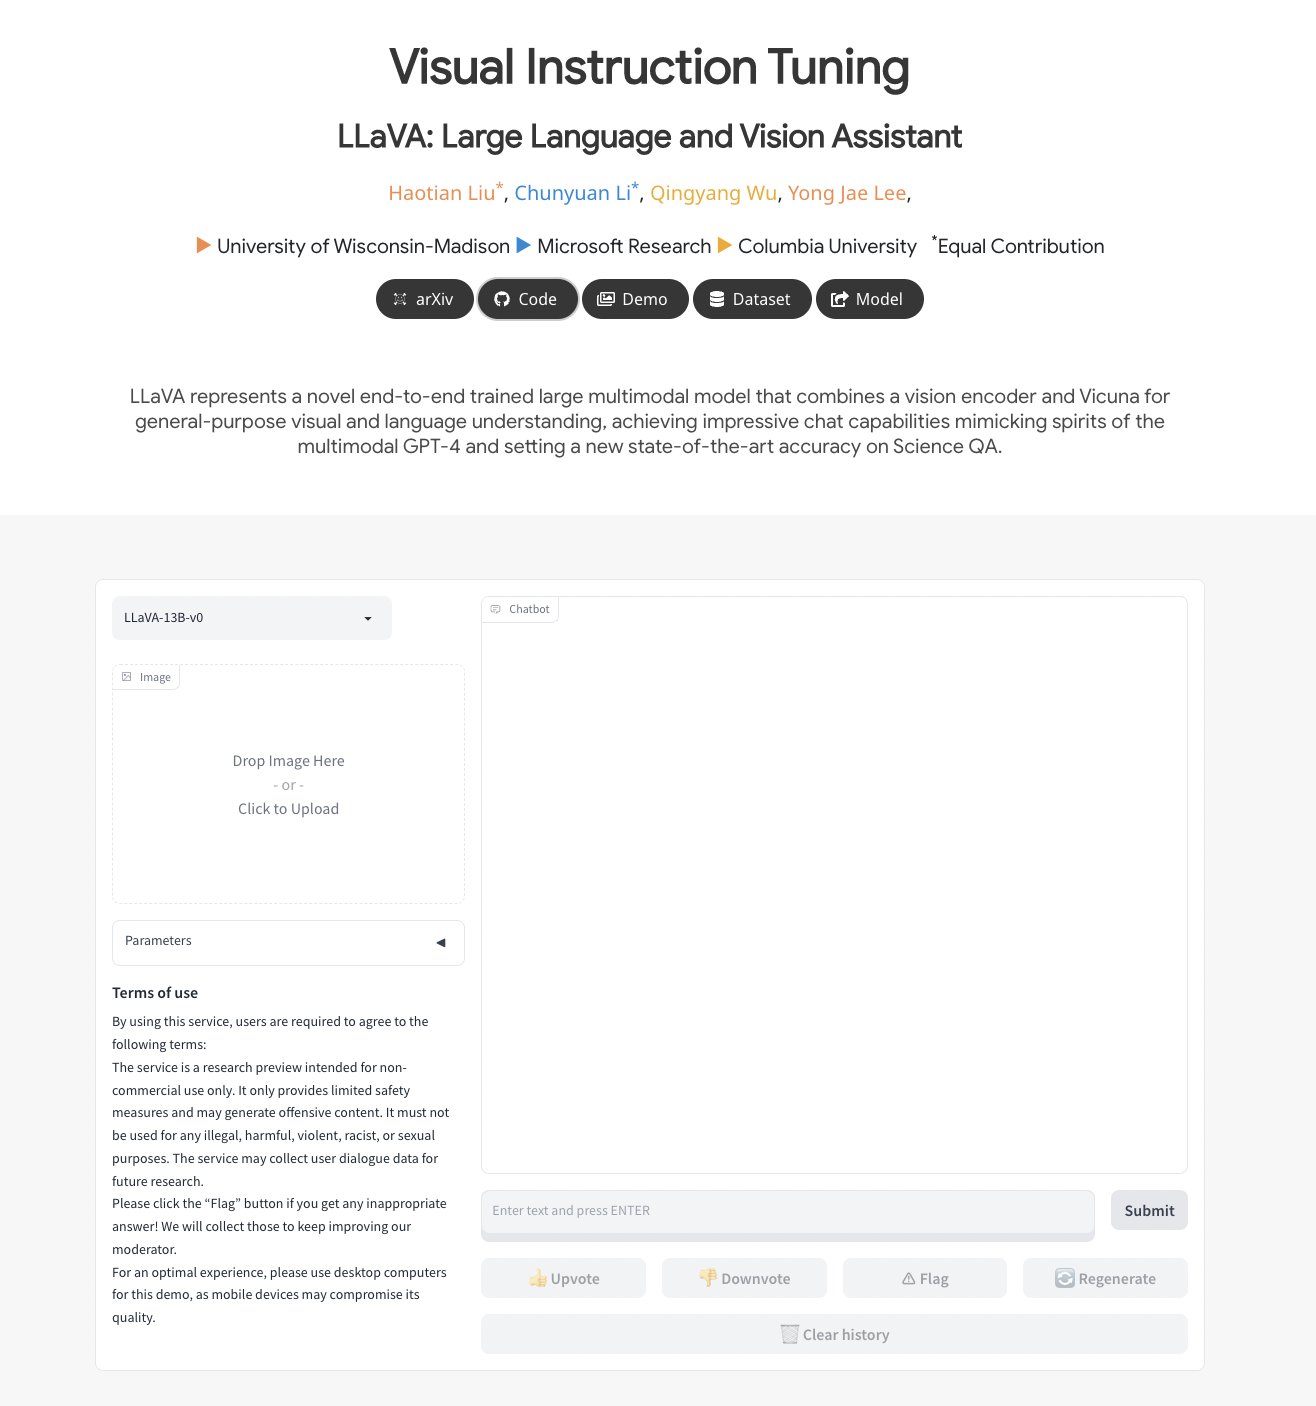
LLaVA: Multimodal Model for Visual Language Understanding
By
–
7/ Visual Instruction Tuning – uses language-only GPT-4 to generate multimodal language-image instruction-following data; applies instruction tuning and introduces LLaVA, a large multimodal model for general-purpose visual and language understanding.
-

Generative Disco: AI Music Visualization System
By
–
5/ Generative Disco – an AI system based on LLMs and text-to-image models that generates music visualizations.
-
Generative Search Engines Citation Accuracy Audit Results
By
–
4/ Verifiability in Generative Search Engines – performs human evaluation to audit popular generative search engines like Bing Chat & NeevaAI; only 52% of statements are supported by citations & 75% of citations support their associated sentence. https://
x.com/nelsonfliu/sta
tus/1649075151303221249?s=20
… -
Deep Learning Framework Enables Large-Scale Biomolecular Dynamics Simulation
By
–
3/ Deep Learning for Large-Scale Biomolecular Dynamics – presents a framework for large-scale biomolecular simulation; this is achieved through the high accuracy of equivariant deep learning and the ability to scale to large and long simulations. https://
x.com/simonbatzner/s
tatus/1649214171236691969?s=20
…