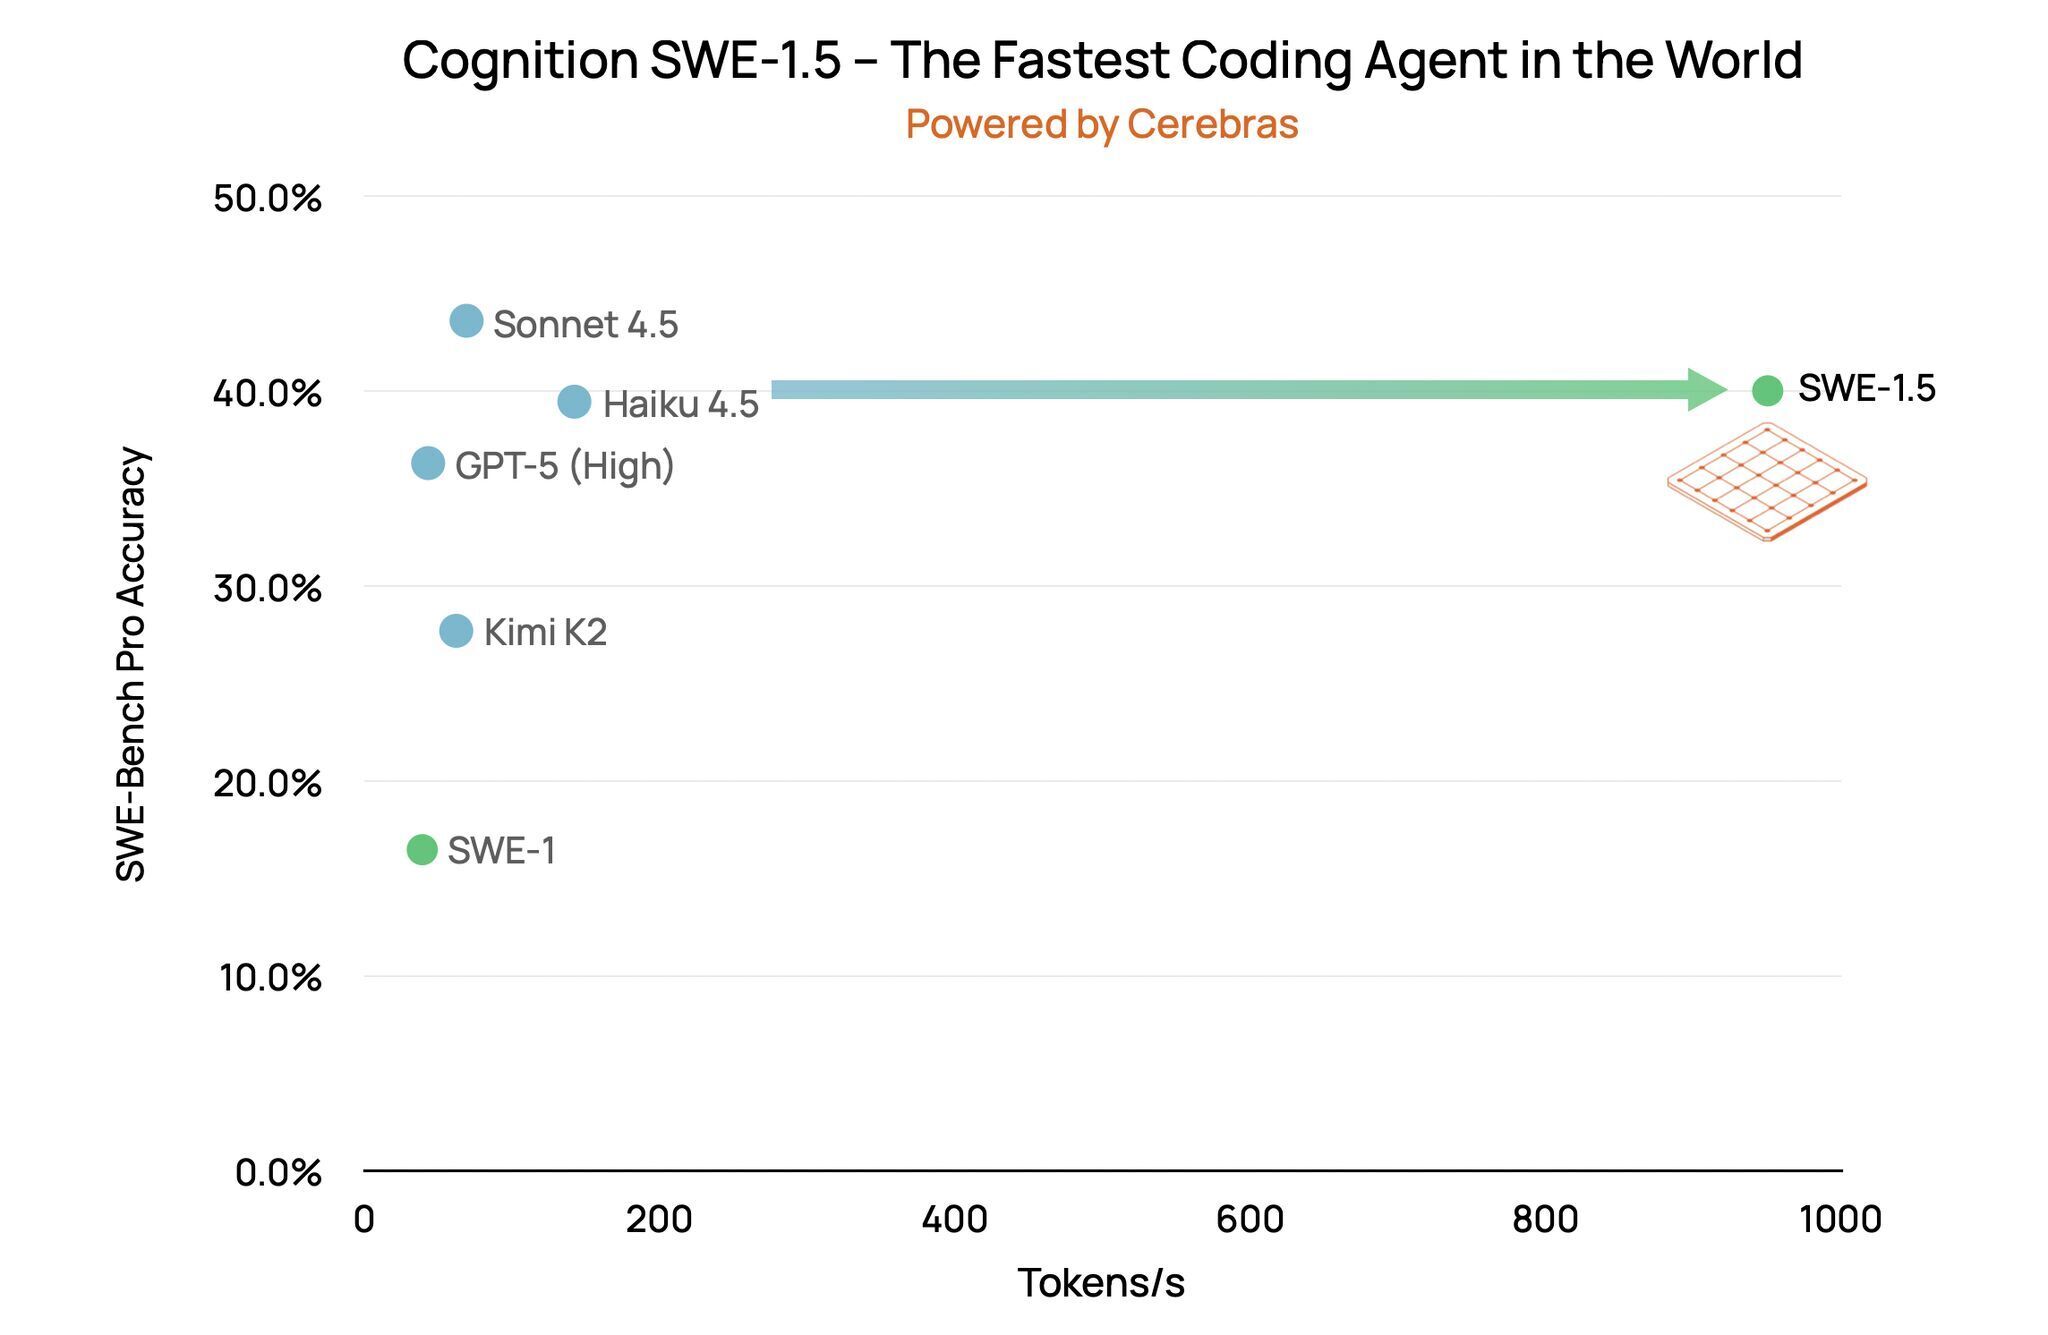
Tired of waiting for minutes for your AI coding assistant? @cognition built agents that search, reason & edit code in a few seconds. Powered by Cerebras—running at 1K tokens/sec with frontier-level accuracy.
@cerebras
-
Cerebras Wins TSMC Innovation Award for AI Hardware Breakthrough
By
–
📽️ A five-person Cerebras team approached one of the world’s largest semiconductor manufacturers with a radical proposal — and TSMC backed the vision.
— Cerebras (@cerebras) 11 décembre 2025
We recently won TSMC North America’s Innovation Zone Demo of the Year, earning the highest number of attendee votes across 43… pic.twitter.com/KUN1PLQZiUA five-person Cerebras team approached one of the world’s largest semiconductor manufacturers with a radical proposal — and TSMC backed the vision.
We recently won TSMC North America’s Innovation Zone Demo of the Year, earning the highest number of attendee votes across 43 -
Choosing Right LLM Model for Your Product Use Case
By
–
Some of our top customers are still choosing Llama 3.1 8B.
— Cerebras (@cerebras) 10 décembre 2025
For a while, we jumped to whatever hottest, latest model was taking up our twitter feed. 🙈
But as we are quickly realizing, to create a SOTA product, you need a model that fits your exact use case.
Here’s what our… pic.twitter.com/caeW3NFA8JSome of our top customers are still choosing Llama 3.1 8B. For a while, we jumped to whatever hottest, latest model was taking up our twitter feed. But as we are quickly realizing, to create a SOTA product, you need a model that fits your exact use case. Here’s what our
-

Jais-2: Arabic LLM 20x Faster Than Leading Models
By
–
Introducing Jais-2 – a major leap for Arabic AI. Co-developed with @G42ai , Inception, and @mbzuai
, Jais-2 is a family of Arabic models built end-to-end on Cerebras from pretraining to inference. Jais-2 70B runs at 2,000 tokens/sec – 20x faster than leading LLMs. It brings deep -
Cerebras showcases nine papers at NeurIPS 2025 spanning pretraining to inference
By
–
Cerebras is showcasing nine new papers at NeurIPS 2025, spanning pretraining to inference:
CODA – orchestrate 32B models to beat 235B models Calibrated Reasoning – 1-3x token savings in best-of-n sampling
DREAM – 3.6× faster VLM inference using spec decode CompleteP – -
AI Developers Confess: Behind the Scenes at aiDotEngineer
By
–
We set up a camera and asked @aiDotEngineer developers to CONFESS. The answers … speak for themselves.
— Cerebras (@cerebras) 4 décembre 2025
Thank you @swyx, @dkundel, @altryne, @RealGeneKim! Until the next one… pic.twitter.com/n1g65mCBOWWe set up a camera and asked @aiDotEngineer developers to CONFESS. The answers … speak for themselves. Thank you @swyx
, @dkundel
, @altryne
, @RealGeneKim
! Until the next one… -
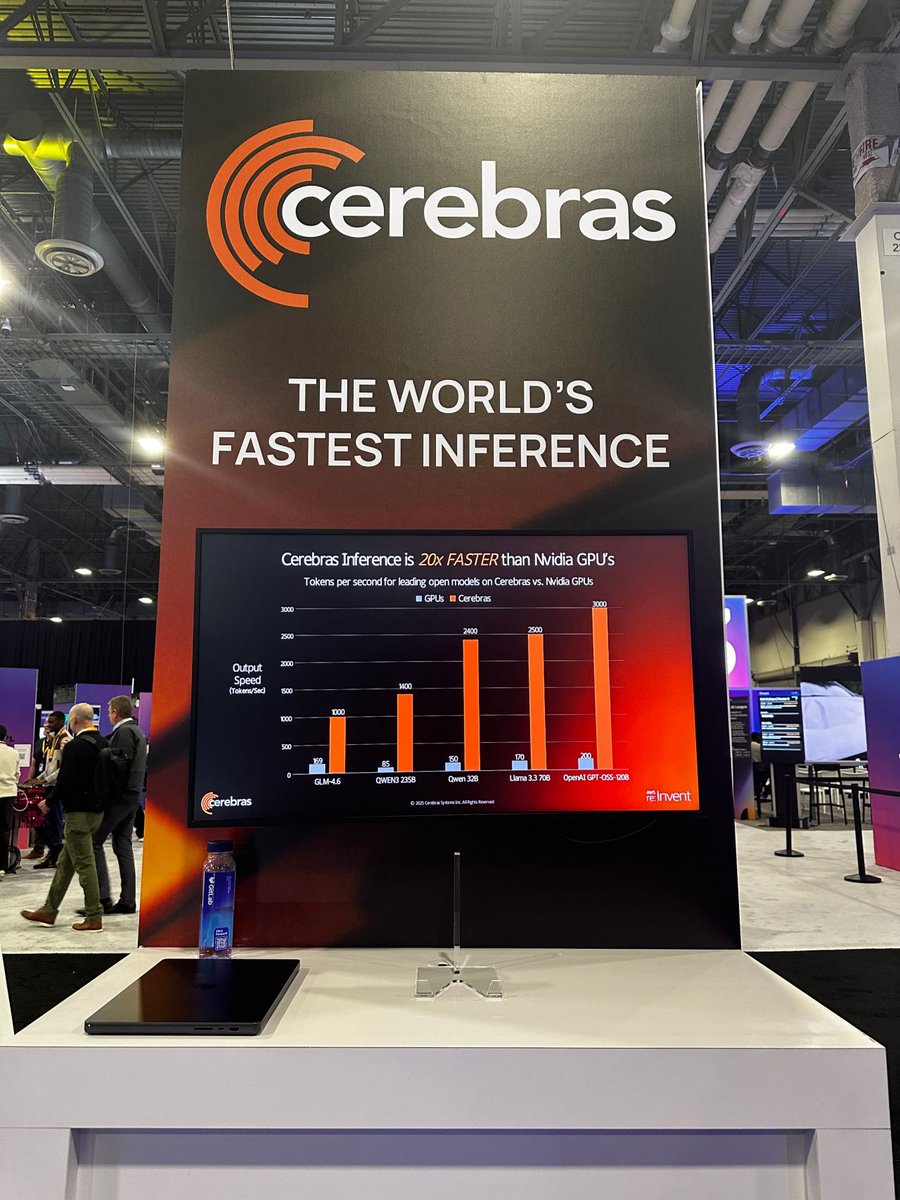
Cerebras Launches Live Demos at AWS re:Invent 2026
By
–
Viva Las Cerebras! We are at AWS re:Invent all week.
Come see live demos, meet the team and spin up Cerebras in minutes using @awscloud Marketplace.
Booth 1772 in the Venetian. -
Real-time cutting edge experiences enabled at Rox via AWS
By
–
Read more about how we enable real-time, cutting edge experiences at Rox, via @awsmarketplace
: -

Rox AI Uses Cerebras for Ultra-Low-Latency GTM Agents
By
–
If you want your team to actually use agentic GTM, it has to feel instant. @rox_ai
, one of the hottest AI agent startups serving the Fortune 2000, now routes its fast-path GTM workflows to Cerebras (~1,000 TPS). The result: ultra-low-latency responses that drive real adoption -
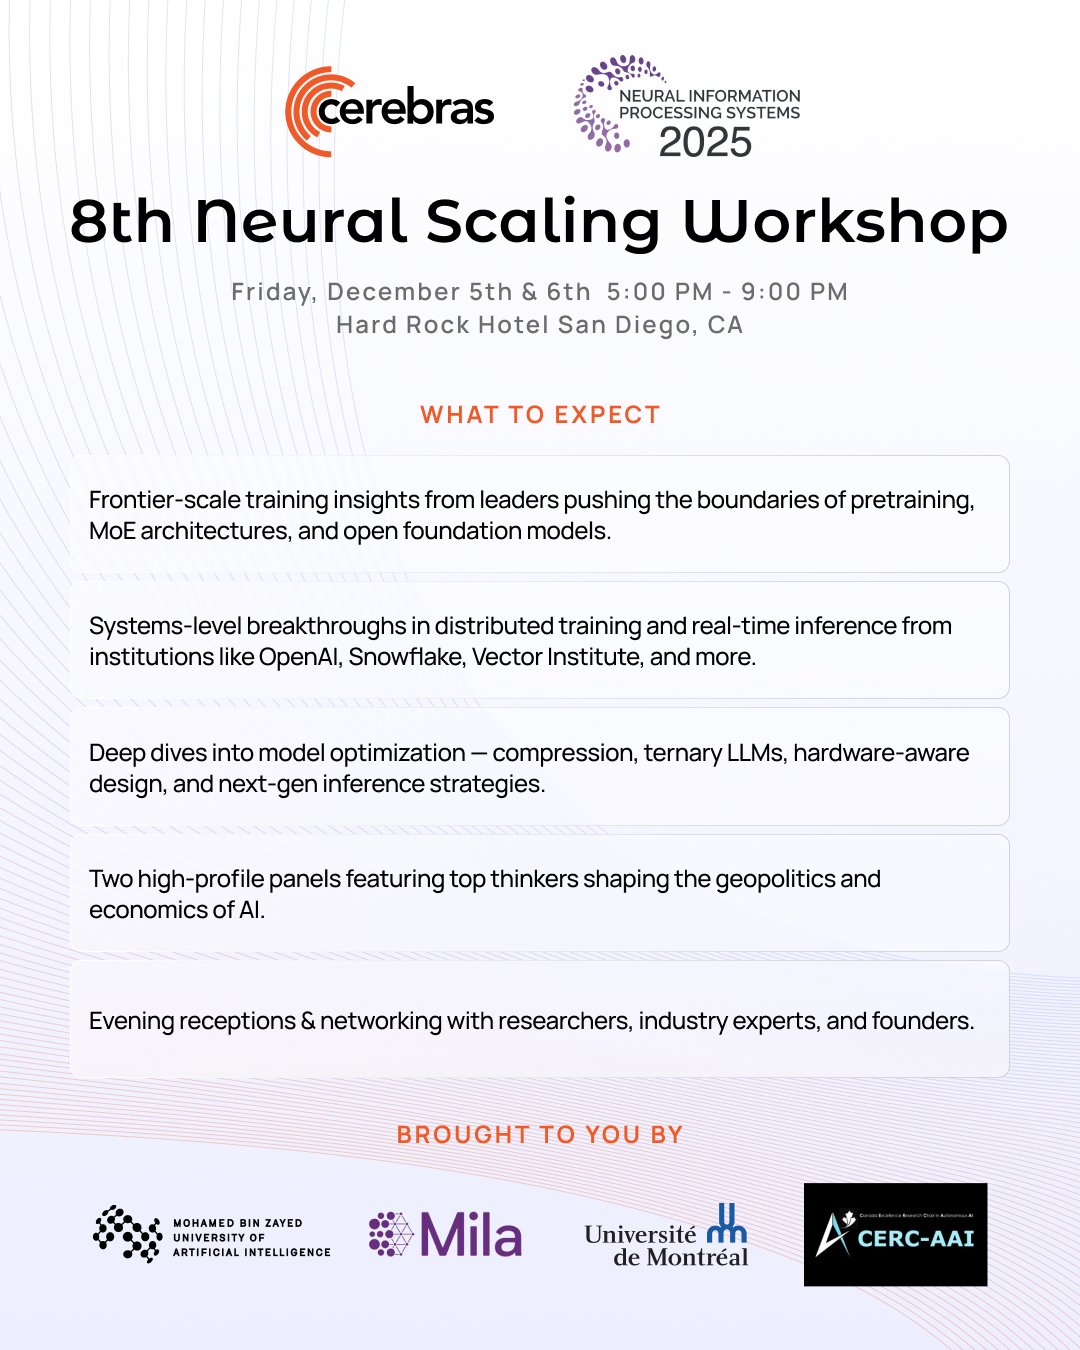
Cerebras Co-hosts 8th Neural Scaling Workshop at NeurIPS 2025
By
–
Heading to @NeurIPSConf 2025? Cerebras is co-hosting the 8th Neural Scaling Workshop at NeurIPS 2025 with @mbzuai
, @Mila_Quebec and CERC-AAI Lab. Join us: https://
luma.com/gy51vuqd