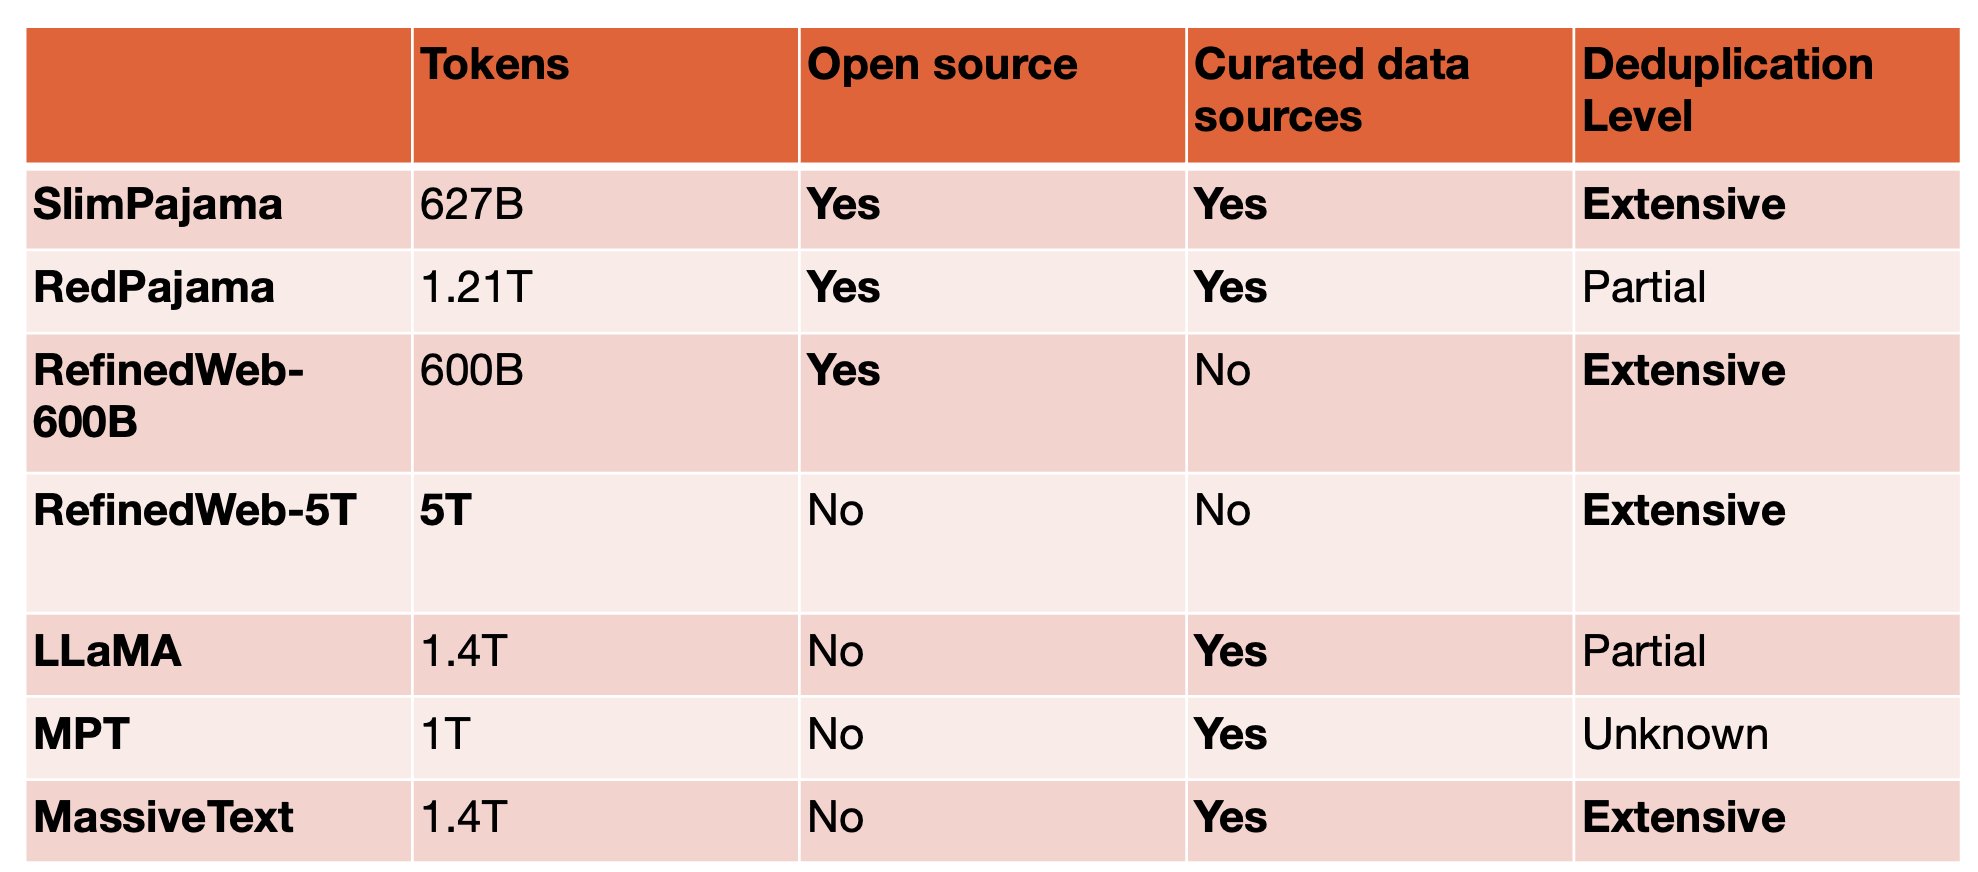
It was no mean feat to deduplicate data on this scale – existing tools does not scale to a trillion tokens. We built a custom parallel data pre-processing pipeline and are sharing the code open source with the community.
@cerebras
-
SlimPajama: 50% Smaller, Twice Faster LLM Training Dataset
By
–
SlimPajama cleans and deduplicates RedPajama-1T, reducing the total token count and file size by 50%. It's half the size and trains twice as fast! It’s the highest quality dataset when training to 600B tokens and when upsampled performs equal or better than RedPajama.
-
SlimPajama: High-Quality Dataset Reduces Duplicates Training
By
–
RedPajama-1T is the largest open dataset today but contains a large percentage of duplicates, making a full training run costly and inefficient. Like the Falcon team, we found data quality is just as important as quantity – which led to SlimPajama.
-
SlimPajama-627B: Largest Deduplicated Open-Source LLM Dataset
By
–
New dataset drop!
Introducing SlimPajama-627B: the largest extensively deduplicated, multi-corpora, open-source dataset for training large language models. https://
cerebras.net/blog/slimpajam
a-a-627b-token-cleaned-and-deduplicated-version-of-redpajama
… -
Industry Leadership in Advanced AI Development and Future Direction
By
–
"Advanced AI may have suddenly jumped into public consciousness, but people in the industry have been working on it for years. Count @andrewdfeldman among them" @svbizjournal profiles our history of leadership in #AI and what comes next:
-
Cerebras Tech Talk: ML and Generative AI for DoD
By
–
Join Cerebras at the AFCEA San Diego June Virtual Tech Talk! Product Manager Richard Kuzma will address how Machine Learning and Generative AI is transforming the way DoD, industry, and academia think about and harness the power of their data Register: https://
hubs.li/Q01SL_HG0 -
Tech Talk: Building Large AI Chips and Training 100B Models
By
–
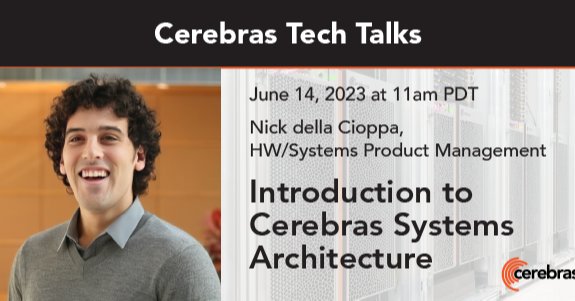
One week until our our Tech Talk! Join us on Wednesday, June 14th, at 11 am PST, for a 30-minute tech talk where we will cover why we built a big chip, how we manage to train 100B+ parameter models on a single system, and much more! Register: https://
hubs.li/Q01SHS6W0 -
Cerebras Leads AI Hardware Startups with Research Citations
By
–
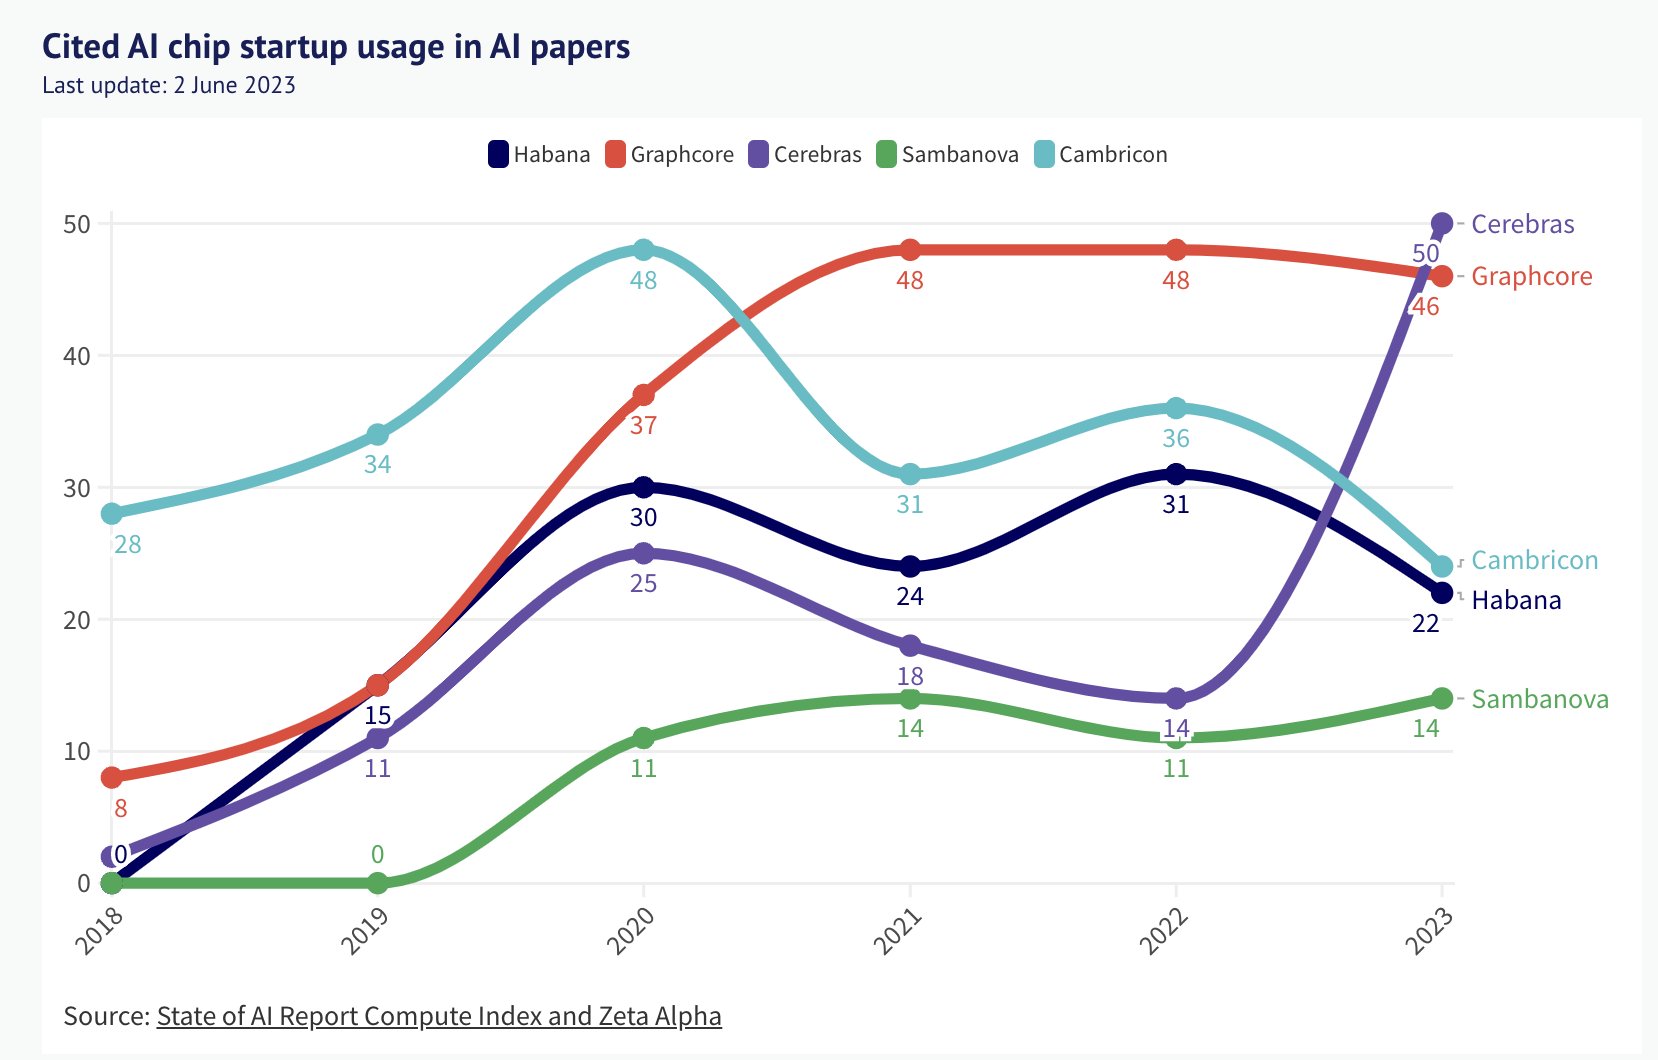
Cerebras is now the leading AI hardware startup as measured by research paper citations! Cerebras-GPT is just the start – we have so much cool research that we can't wait to share with you all. Stay tuned!
h/t: @nathanbenaich -
Cerebras Tech Talk: Training 100B+ Models on Single System
By
–
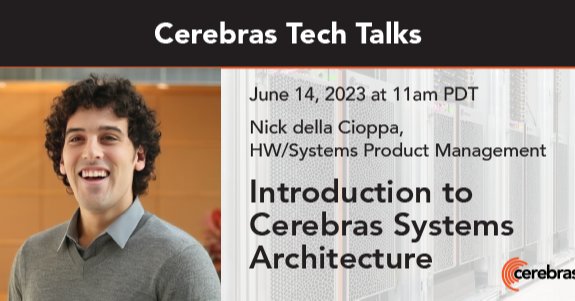
Attend our Tech Talk! On Wednesday, June 14th, at 11am PST, we will host a 30-minute tech talk where Cerebras Hardware PM, Nick Della Cioppa, will cover why we built a big chip, how we train 100B+ parameter models on a single system, and more! Register: https://
hubs.li/Q01R_ldM0 -
Sparsity’s Impact on Neural Network Training Research
By
–
Our latest podcast is live! In this episode, @vithursant19 and @draecomino explore cutting-edge research on sparsity and its impact on training neural networks.
— Cerebras (@cerebras) 31 mai 2023
Click here to listen: https://t.co/SxmKlz2DtW pic.twitter.com/O7yYyJkbvMOur latest podcast is live! In this episode, @vithursant19 and @draecomino explore cutting-edge research on sparsity and its impact on training neural networks. Click here to listen: https://
hubs.li/Q01RPx_C0