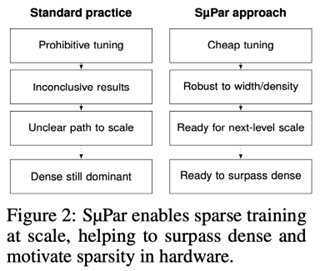
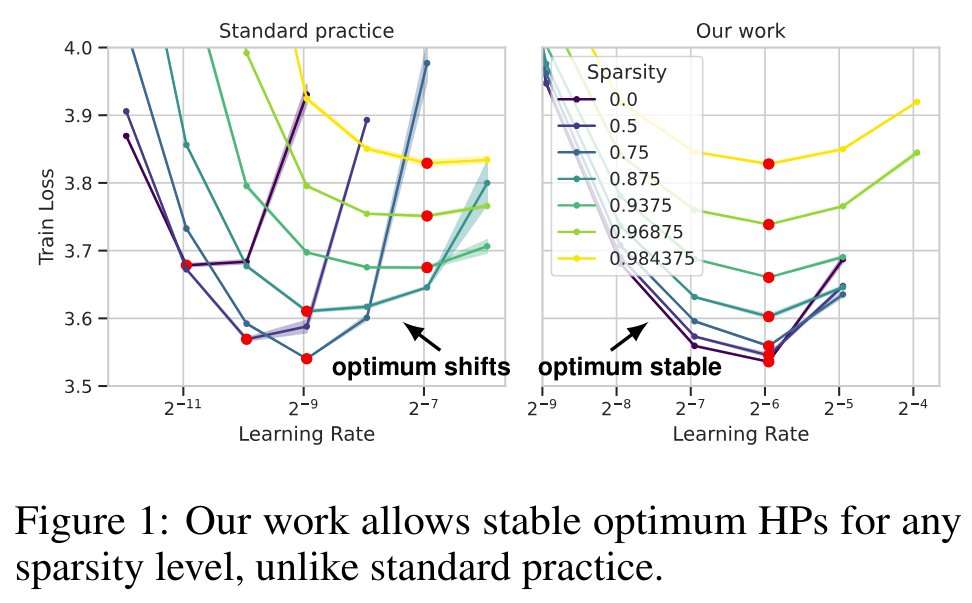
(8/n) Using dense optimal HPs, the SP and μP models experience detuning HPs as sparsity increases. This detuning is a confounding variable present in many existing sparse studies. SμPar eliminates this confounding variable and enables more robust sparsity studies.
@cerebras
-
SμPar improves LLM pretraining loss over SP and μP
By
–
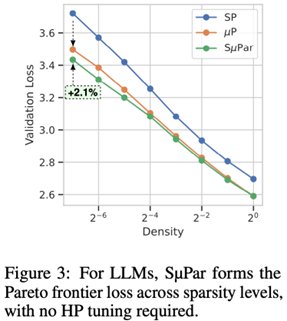
(6/n) Applying SμPar to pretraining a 610M parameter LLM significantly improves loss over SP and μP models due to improved HP tuning.
-
Sparse Iso-Parameter Scaling Achieves 87.5% Sparsity
By
–
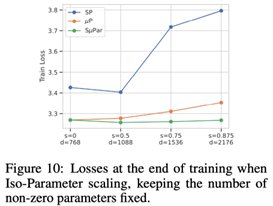
(7/n) We test Sparse Iso-Parameter Scaling, where width and sparsity are increased, holding n_params constant. Using the standard practice (SP + dense optimal HPs), one would conclude only up to 50% sparsity help. Instead using SμPar allows an 87.5% sparse model to match dense
-
SμPar Maintains Stable Hyperparameters Across Sparsity Width
By
–
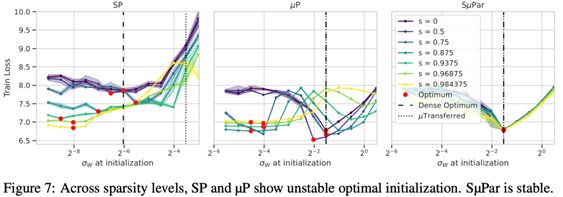
(5/n) SμPar enables optimum hyperparameters to remain stable for any combination of sparsity and width, unlike SP and μP.
-

SμPar Extends μP for Sparse Neural Network Training
By
–
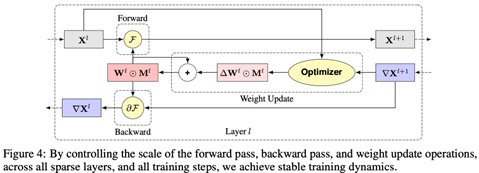
(4/n) We introduce the sparse maximal update parameterization (SμPar), which extends μP to also fix the vanishing activation problem with increasing sparsity.
-
Preventing Activation Vanishing in Sparse Neural Network Training
By
–
(3/n) This motivated us to develop a parameterization that prevents activation vanishing due to sparsity. We need to ensure all 3 operations in a training step (forward, backward, and weight update) are controlled with respect to sparsity.
-
Sparse Maximal Update Parameterization Reduces Hyperparameter Tuning
By
–
(1/n) Paper drop: https://
arxiv.org/abs/2405.15743 TLDR: We introduce the sparse maximal update parameterization (SμPar), which ensures optimal HPs remain the same for any width or sparsity level. This dramatically reduces HP tuning costs, allowing SμPar to achieve superior losses. -

Weight Sparsity Impact on Activation Scales Training
By
–
(2/n) Increasing weight sparsity causes vanishing activation scales with both SP and μP, leading to poor training dynamics.
-

Company Named to TIME 100 Most Influential Companies List
By
–
We are proud and honored today to have been named to the TIME 100 Most Influential Companies list! As we reflect on this incredible moment, we are grateful for the fundamentals that got us here: Winning team – We have the very best engineers and talent worldwide,
-
AI Reshaping Healthcare: Cerebras at GenAI Summit SF 2024
By
–
Learn about AI in Healthcare! VP and Field CTO Natalia Vassilieva will be speaking at the #GenAISummitSF2024 on "How AI is Reshaping the Service in Medical and Healthcare" Register here: http://
genaisummit.ai Learn how Cerebras is reshaping Healthcare: