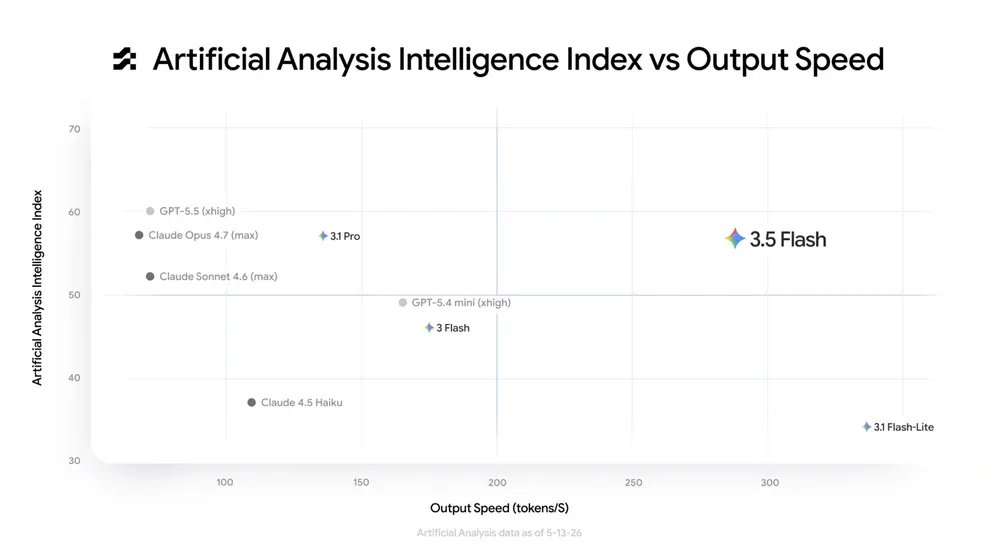
We are in the recursive era of AI.
Faster inference => faster AI development.
Our take on this from a hardware perspective:
https://cerebras.ai/blog/why-the-ai-race-shifted-to-speed
…
@cerebras
-
The Recursive Era of AI: Fast Inference and Accelerated Development per Cerebras
By
–
-
Colocating memory avoids costly transfers during inference
By
–
"If you can co-locate your memory, you're getting a lot more bang for your buck because you're avoiding this costly memory transfer."@sarahookr (author of The Hardware Lottery, founder of @adaptionlabs ) on why inference is forcing a new chip paradigm – one that wafer-scale was… pic.twitter.com/tTfu19zUWU
— Cerebras (@cerebras) 4 juin 2026“If you can colocate your memory, you get much more value for your money because you avoid that costly memory transfer.” @sarahookr (author of The Hardware Lottery, founder of @adaptionlabs) on why inference forces a new paradigm
-
Wafer-Scale AI Compute: Dedicated Silicon Architecture
By
–
“This technology, this work would be big enough to require dedicated silicon… you needed to start with a clean sheet of paper and you needed to do something fundamentally different.”@andrewdfeldman joined @PeterDiamandis on MOONSHOTS to discuss wafer-scale AI compute, fast… pic.twitter.com/RNv3i2VTZL
— Cerebras (@cerebras) 28 mai 2026“This technology, this work would be big enough to require dedicated silicon… you needed to start with a clean sheet of paper and you needed to do something fundamentally different.” @andrewdfeldman joined @PeterDiamandis on MOONSHOTS to discuss wafer-scale AI compute, fast
-
Cerebras Inference Speed Performance Across Model Types
By
–
"As people began integrating AI into their day-to-day work, speed became fundamentally important. And we were just crushed with demand. Is Cerebras inference faster for specific use cases? No, it's faster across the board. Big models, small models, U.S. models, Chinese models,
-
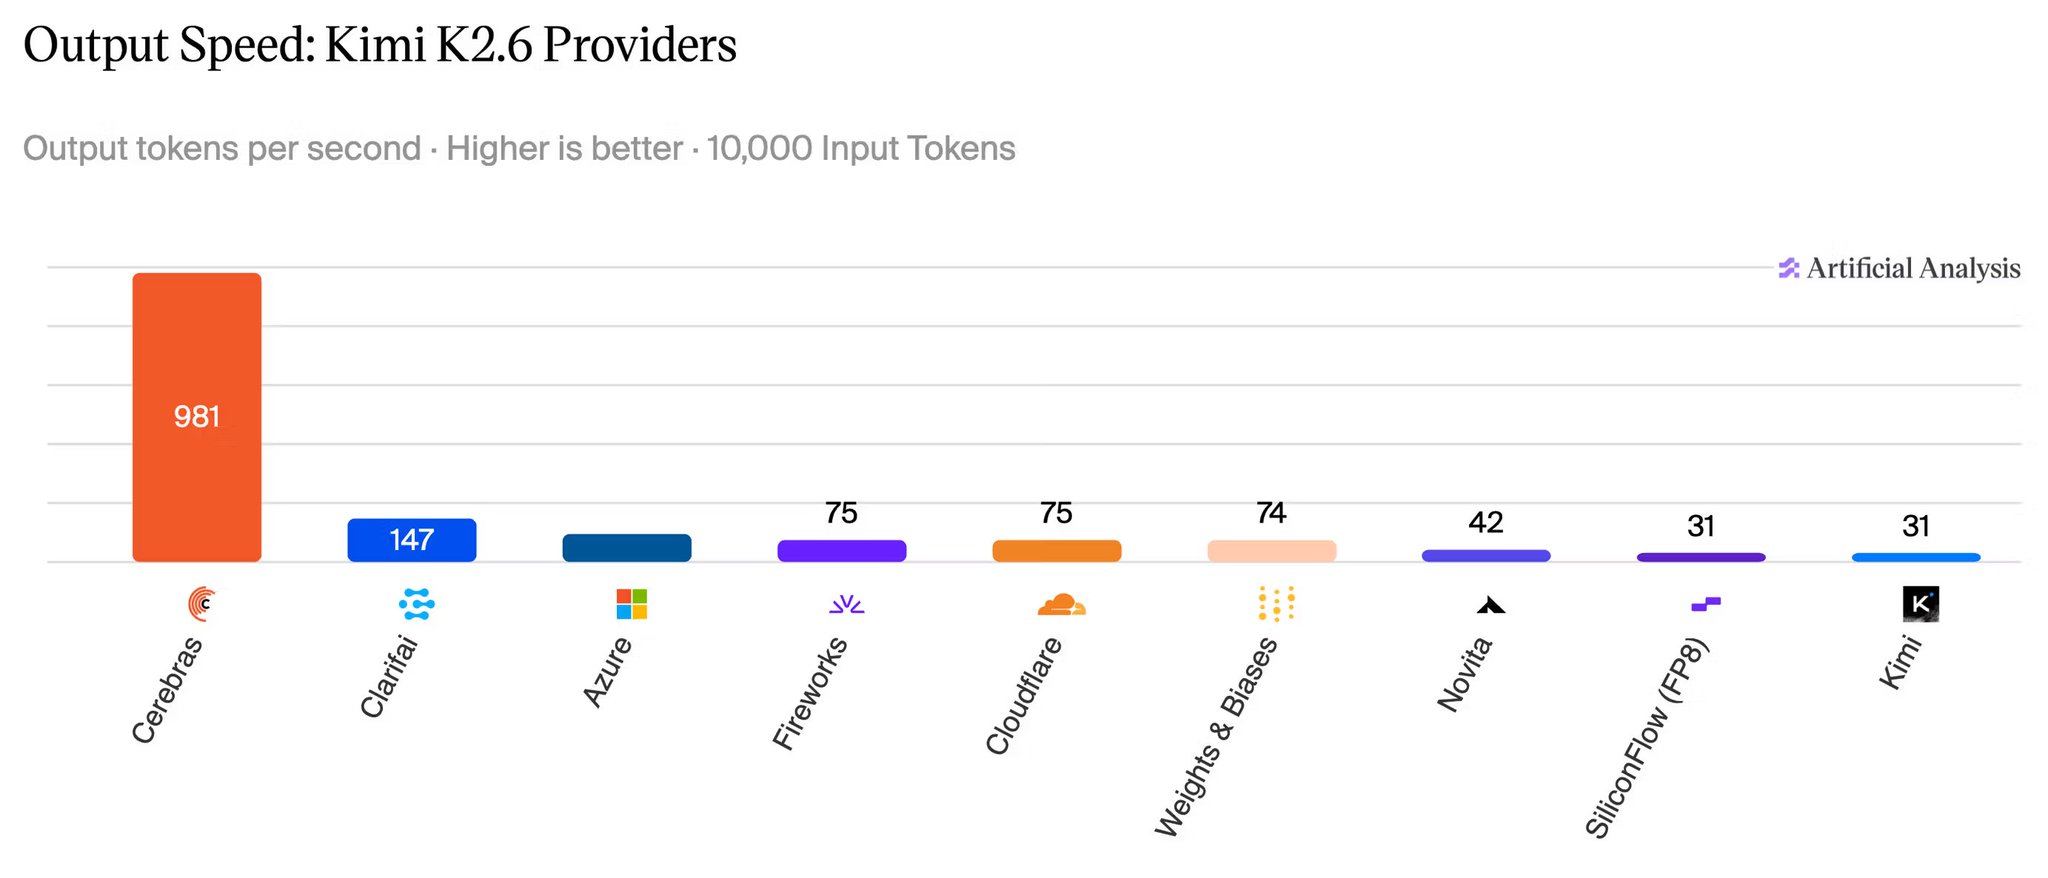
Cerebras Runs Kimi K2.6 Frontier Model in Enterprise Trials
By
–
Cerebras is now running Kimi K2.6 – a trillion parameter model – in enterprise trials. At ~1,000 tokens/s, this is the fastest frontier model performance ever measured by Artificial Analysis @ArtificialAnlys
. -
Cerebras gives away 5 Windsurf plans with SWE-1.6 model
By
–
🎁 We're giving away 5 Windsurf plans ($250 credit each)!
— Cerebras (@cerebras) 7 mai 2026
Try SWE-1.6 — @Cognition’s latest fast and intelligent agentic coding model, powered by Cerebras. In a side-by-side with Claude, the speed difference is clear. More iterations, faster fixes, better code.
💬Comment why… pic.twitter.com/f4zhV9OhYQWe're giving away 5 Windsurf plans ($250 credit each)! Try SWE-1.6 — @Cognition
’s latest fast and intelligent agentic coding model, powered by Cerebras. In a side-by-side with Claude, the speed difference is clear. More iterations, faster fixes, better code. Comment why -
Fully Homomorphic Encryption: Breakthroughs in Speed and Adoption
By
–
Fully homomorphic encryption was invented in the 1980s.
— Cerebras (@cerebras) 6 mai 2026
Why wasn't it adopted sooner? A 100,000x slowdown, driven by memory boundedness. Ajay Joshi from @CipherSonicAI explains how his team got it down to less than 2x.
(if this pattern sounds familar… LLM inference is… pic.twitter.com/gBVRMCBhBRFully homomorphic encryption was invented in the 1980s. Why wasn't it adopted sooner? A 100,000x slowdown, driven by memory boundedness. Ajay Joshi from @CipherSonicAI explains how his team got it down to less than 2x. (if this pattern sounds familar… LLM inference is
-
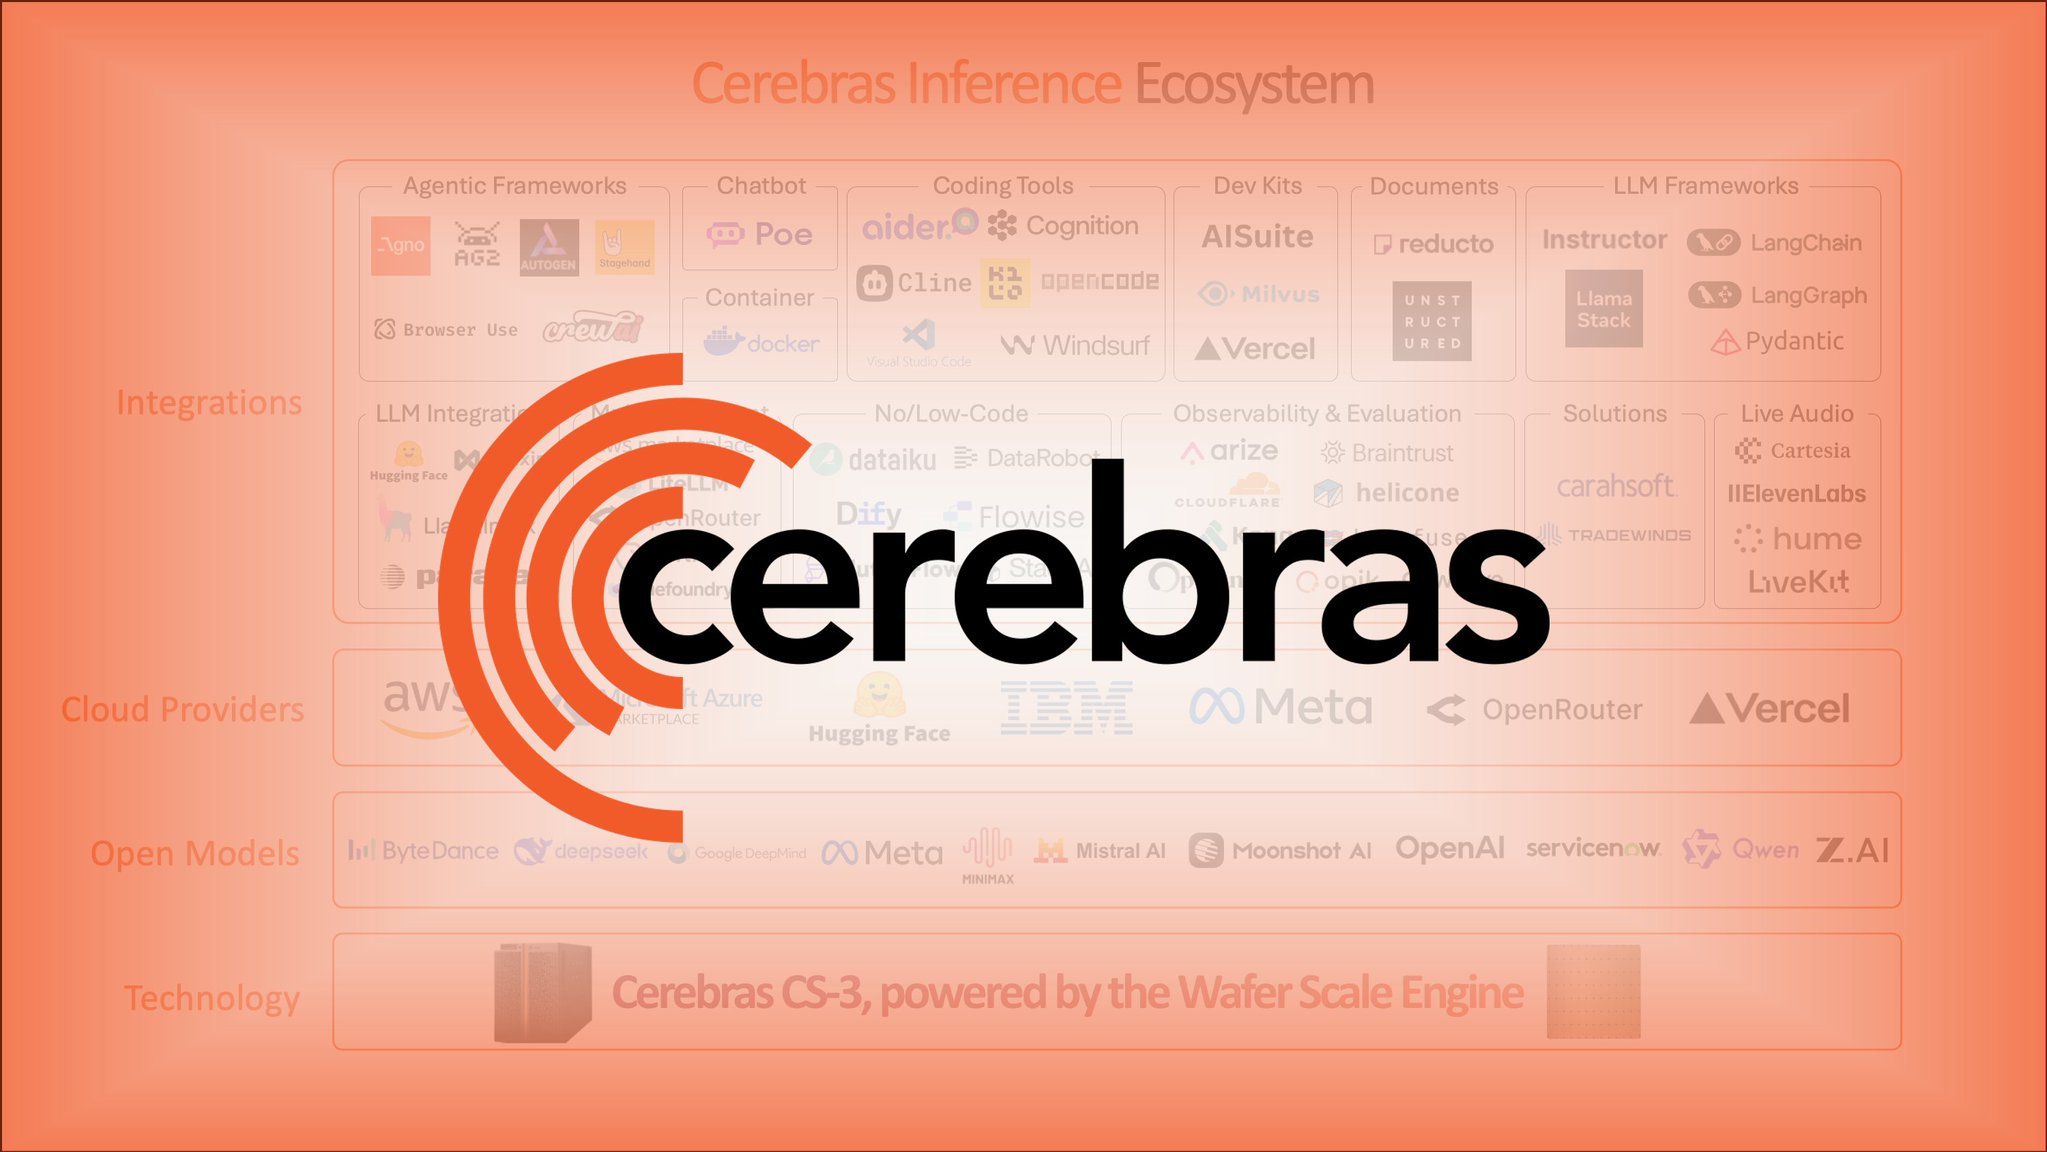
Cerebras Inference Ecosystem Update: Open Models, Cloud, and Integrations
By
–
Cerebras inference ecosystem, updated: open-weight model families, cloud providers, integrations. https://
cerebras.ai/blog/ecosystem -
Inference Speed: The Real Bottleneck for Browser Agents
By
–
"Everyone wants faster agents. And you know what sucks… people think it's my fault. But it's actually the inference."@pk_iv, CEO of @Browserbase, sits down with @MilksandMatcha on why inference speed is the real bottleneck for browser agents, and why Browserbase + Cerebras… pic.twitter.com/5Aa83cjc0D
— Cerebras (@cerebras) 29 avril 2026"Everyone wants faster agents. And you know what sucks… people think it's my fault. But it's actually the inference." @pk_iv
, CEO of @Browserbase
, sits down with @MilksandMatcha on why inference speed is the real bottleneck for browser agents, and why Browserbase + Cerebras