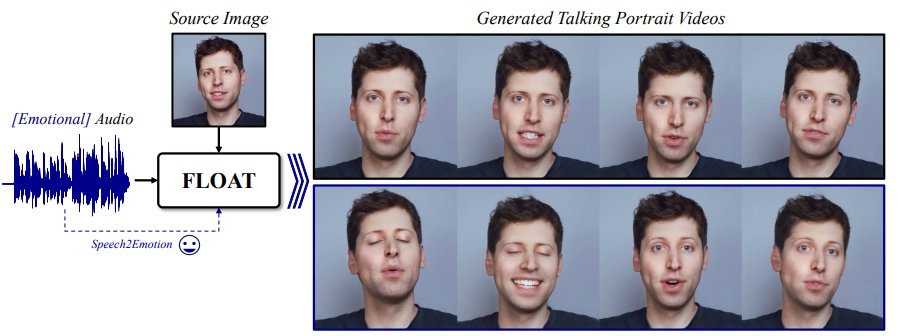
FLOAT A method for generating expressive, temporally consistent talking portrait videos from a single image and audio. Problem: Audio-driven talking portrait generation faces challenges in creating temporally consistent motion and efficient sampling while maintaining
@askalphaxiv
-
Open-Sora Plan: Open-Source High-Resolution Video Generation
By
–
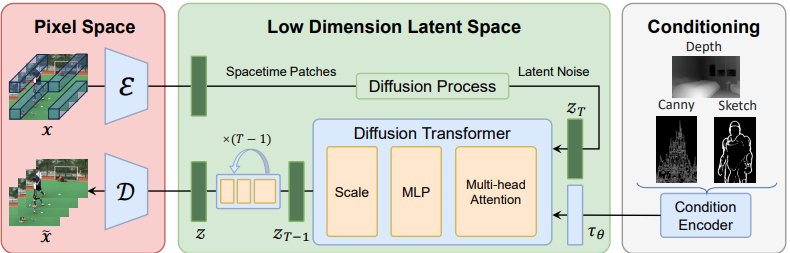
Open-Sora Plan: Open-Source Large Generation Model An open-source framework for generating high-resolution, long-duration videos from diverse user inputs. Problem: Existing video generation models struggle with high-resolution, long-duration video outputs due to high
-
Navigation World Models: Video Generation for Autonomous Agent Planning
By
–
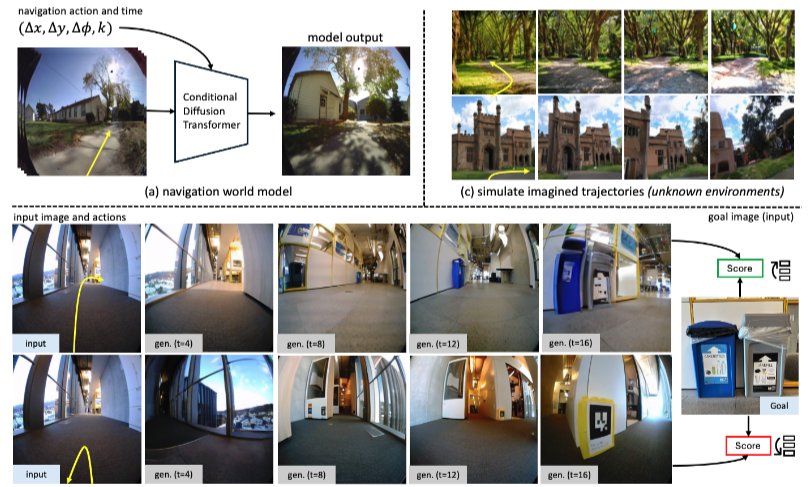
Navigation World Models A controllable video generation model that predicts future visual observations for navigation tasks based on past observations and actions. Problem: Visual-motor agents struggle with planning flexible navigation trajectories, especially in dynamic or
-
Latest AI Papers: Navigation Models and Video Generation
By
–
Trending AI papers on alphaXiv this week, featuring an incredible week for the computer vision and multimodal communities – Navigation World Models (discussion with author @_amirbar
)
– Open-Sora Plan: Open-Source Large Generation Model (discussion with author -
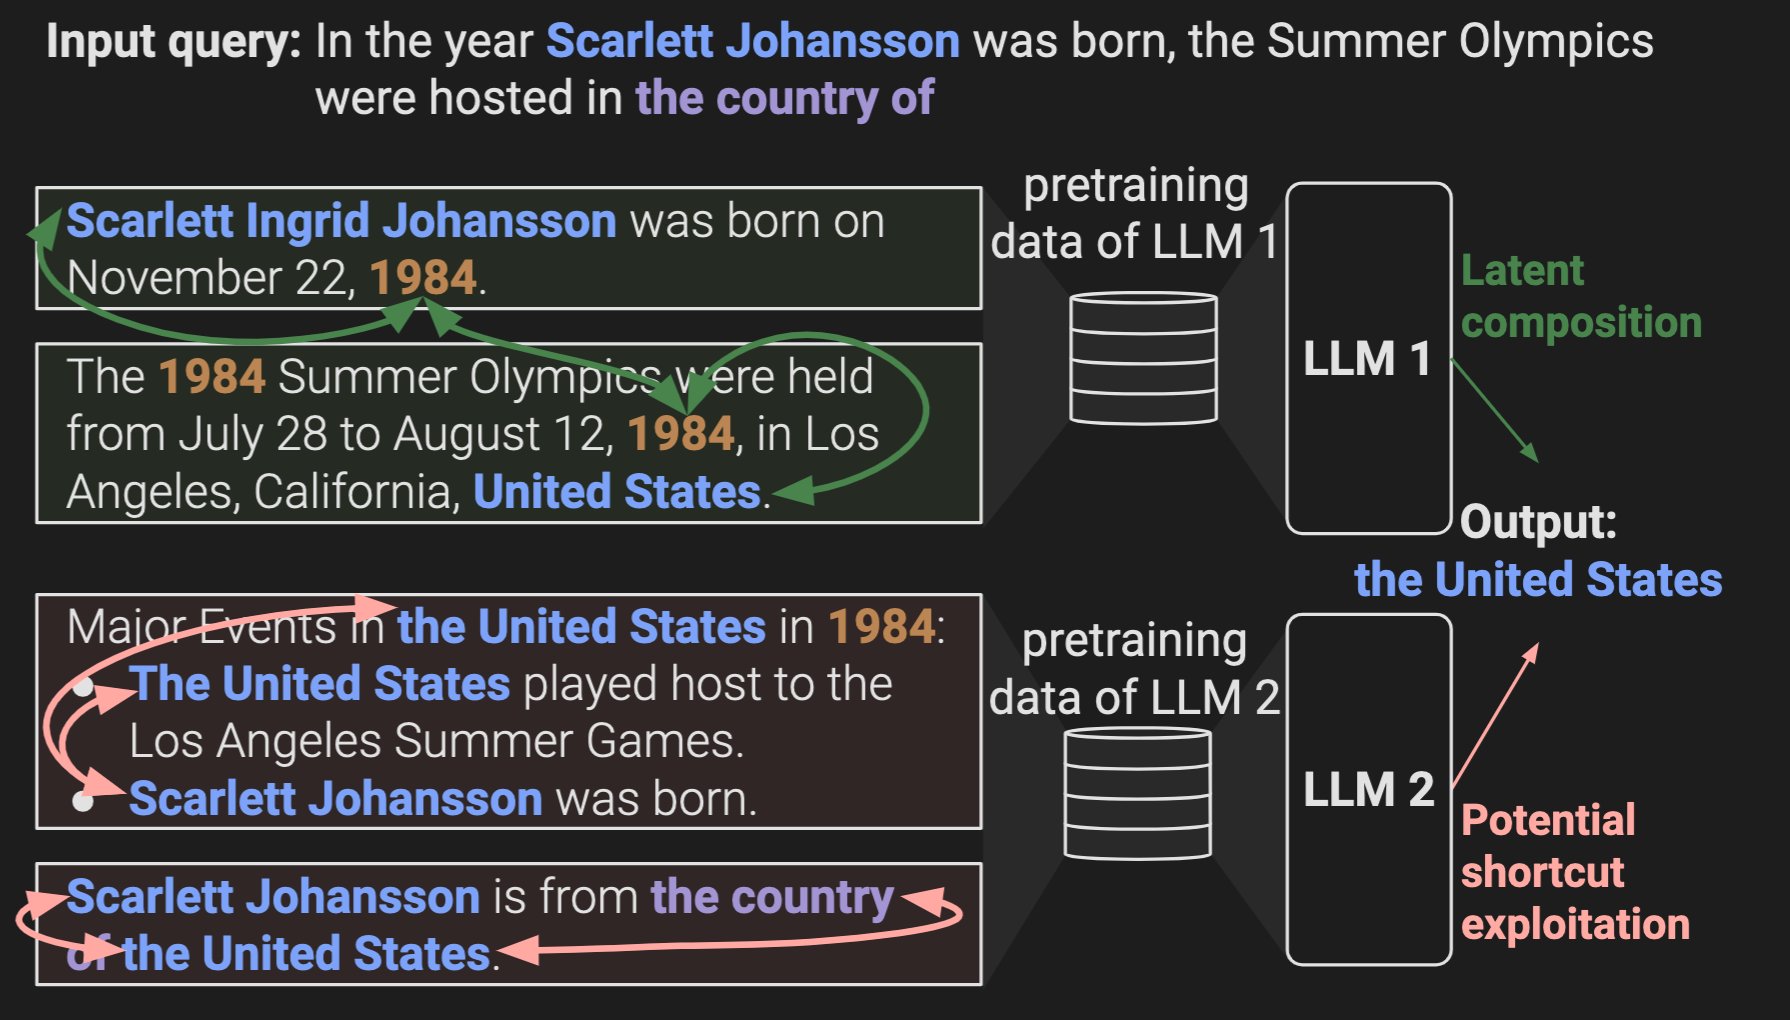
Multi-Hop Reasoning Limitations in Large Language Models
By
–
Evaluating Latent Multi-Hop Reasoning in Large Language Models Investigates whether LLMs can combine factual knowledge across multiple hops without relying on pretraining shortcuts. Problem:
LLMs struggle with latent multi-hop reasoning due to reliance on pretraining -
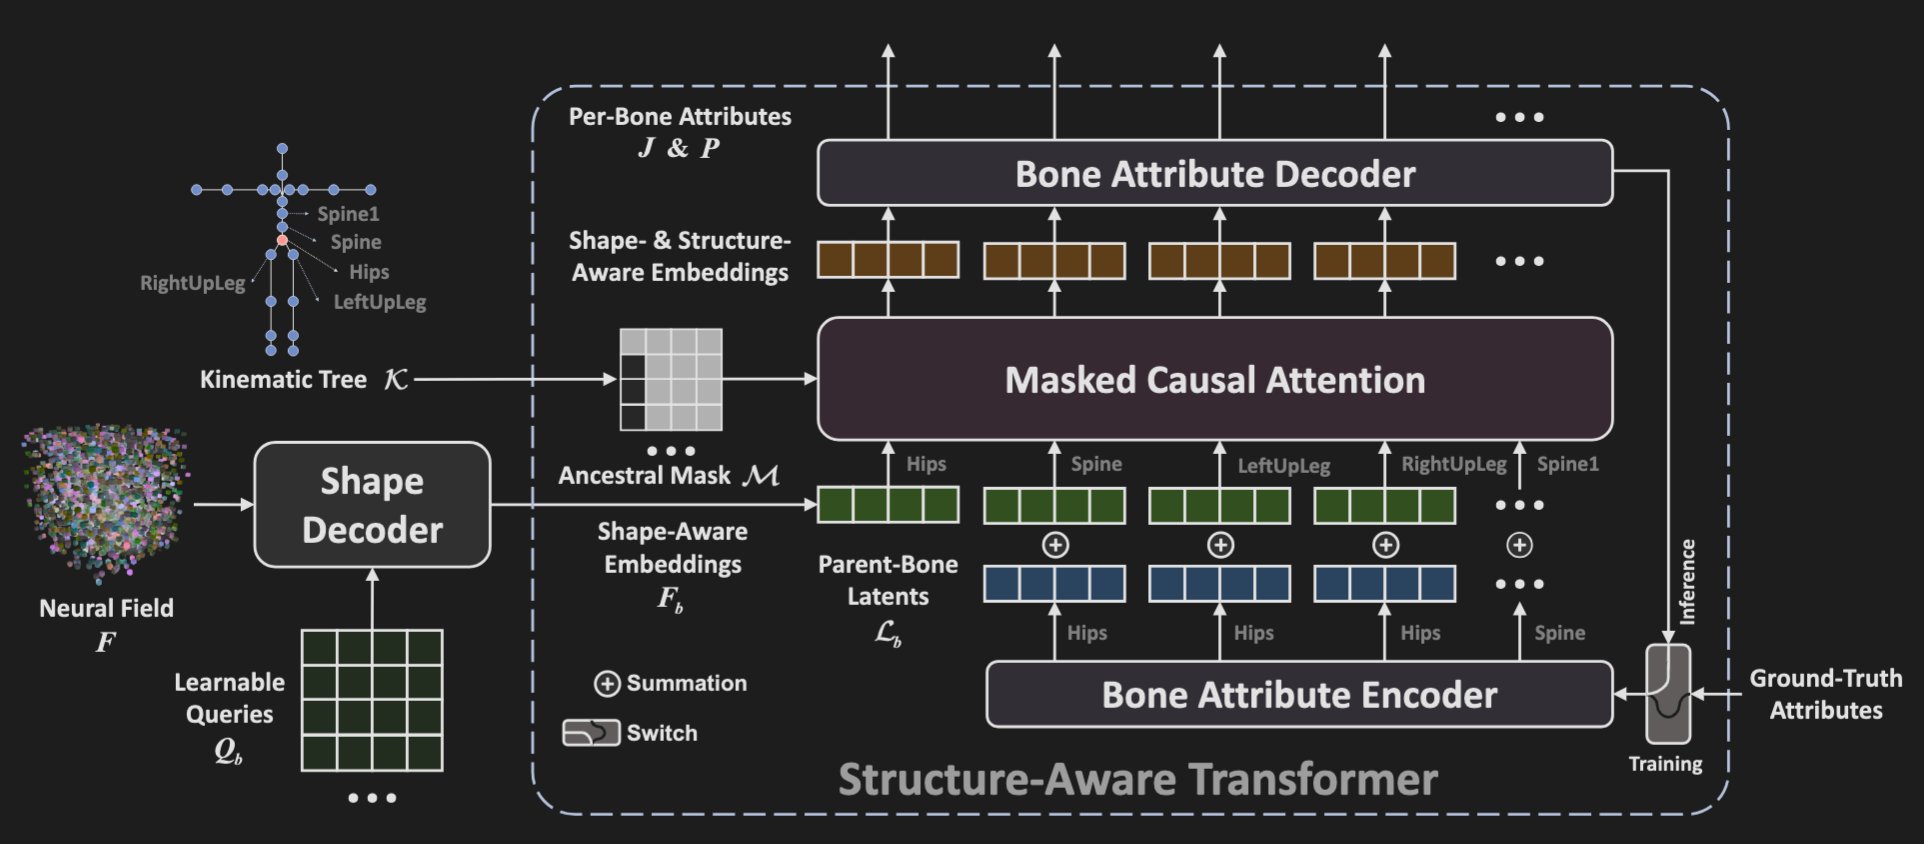
Make-It-Animatable: Automated 3D Character Rigging Framework
By
–
Make-It-Animatable Efficient framework for converting any 3D humanoid character into animation-ready form in under one second. Problem:
Rigging and skinning 3D characters are labor-intensive and existing methods fail to generalize across diverse shapes and poses. Method: -

LLM-Powered GUI Agents: Automation Survey and Insights
By
–
Large Language Model-Brained GUI Agents: A Survey A comprehensive survey exploring how large language models can be used to create AI agents that interact with graphical user interfaces through natural language. Problem:
GUI automation lacks flexibility, requiring complex -

Enhancing LLM Reasoning with Separate Critique Model
By
–
Enhancing LLM Reasoning Improving LLM reasoning by using a separate "critique" model to provide feedback during both training and testing. Problem:
LLMs struggle with complex reasoning and self-correction, especially on challenging tasks where performance plateaus. Method: -
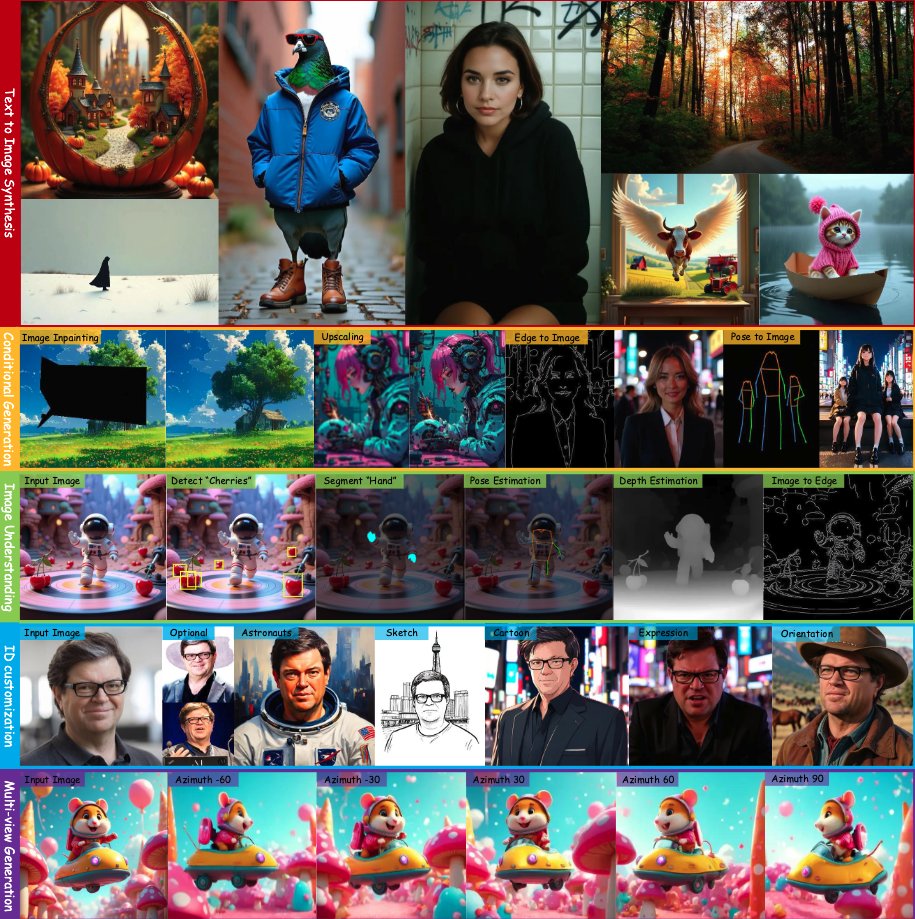
Unified Diffusion Model for Image Generation and Understanding
By
–
One Diffusion to Generate Them All A unified diffusion model that can perform both image generation and understanding tasks through a simple sequence-based approach. Problem:
Diffusion models are task-specific, lacking the universality and flexibility seen in large language -
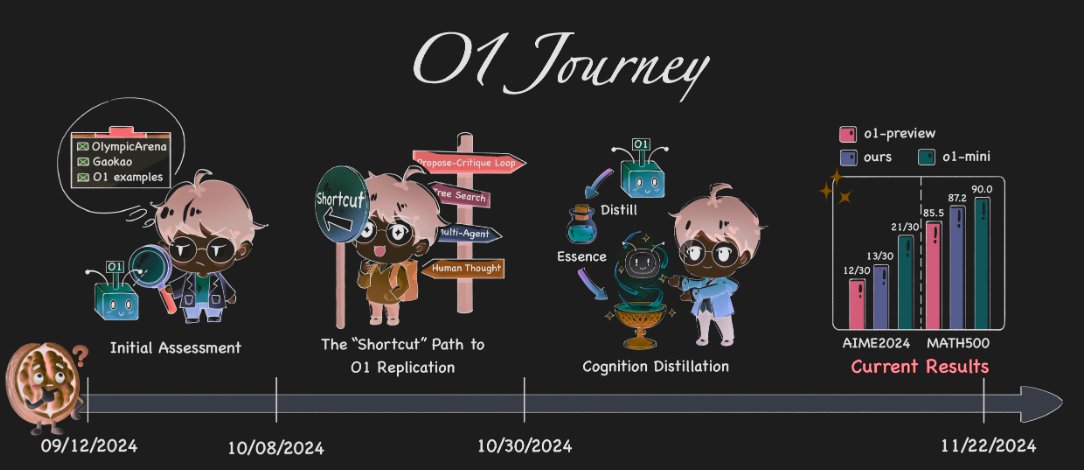
Model Distillation and O1 Replication: Research Ethics Concerns
By
–
O1 replication journey (part 2) A critical examination of how simple model distillation can match O1's mathematical abilities, raising concerns about AI research practices. Problem: Replicating O1 model capabilities has encouraged the use of undisclosed distillation