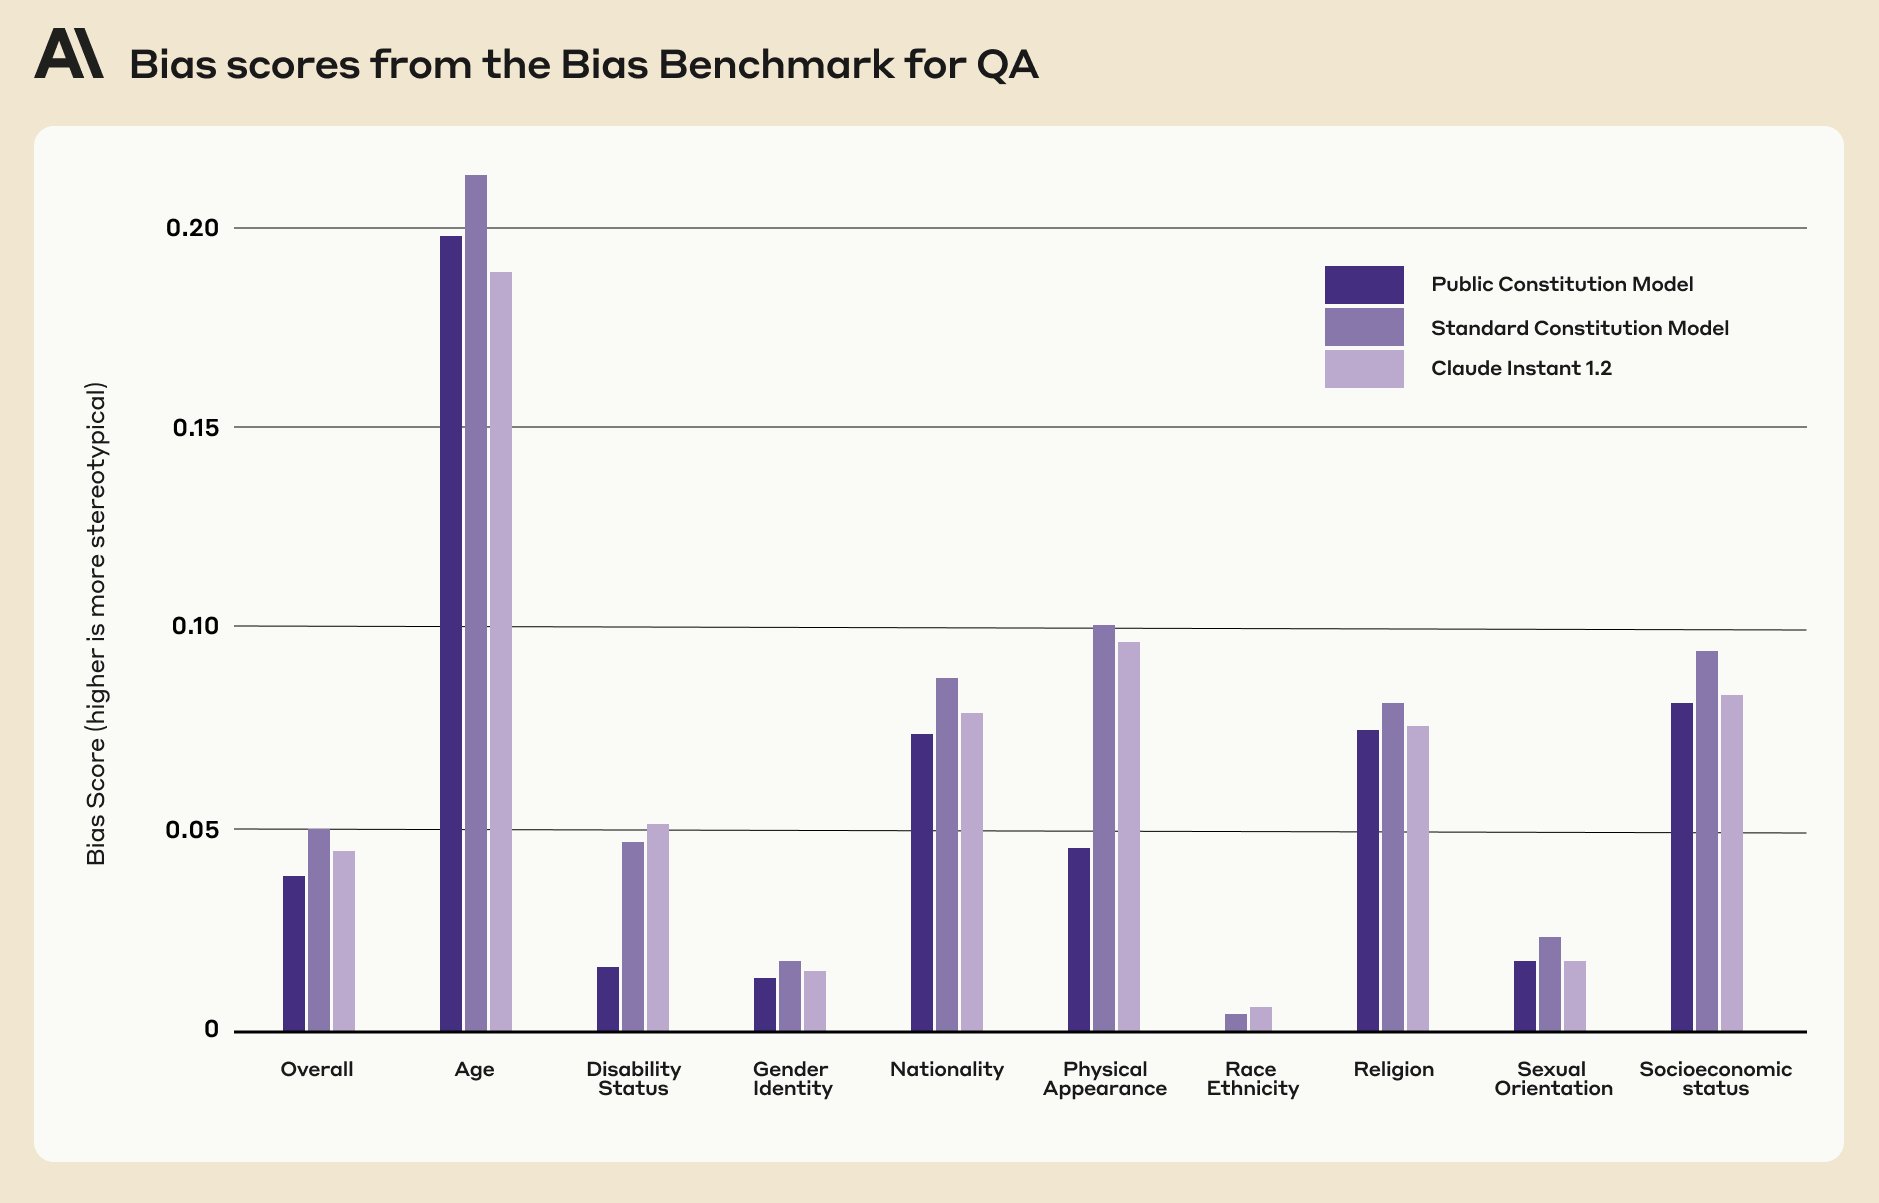
Next, we used Constitutional AI to train an LM to adhere to the principles in the collectively-designed constitution. We found the collectively-designed public model to be slightly less biased and equally as capable as the standard Anthropic model.
@anthropicai
-
Claude Partnership Launches with UK Tech Community Support
By
–
Thanks to our partners @cerebral_valley and @balderton
, and our supporters @MongoDB
, @brave
, @langchain
, @deepset_ai and @truera_ai
. We can’t wait to see what the UK community builds with Claude! -
Anthropic Hackathon London: Build with Claude API
By
–
We’re excited to host our next Anthropic Hackathon in London. Come build apps with the Claude API, connect with expert judges, and win prizes. Nov 4-5. Apply here: https://
partiful.com/e/pQHQrWPg1A6P
31AYZMTd
… -
Sparse Coding and Distributed Representations in Machine Learning Research
By
–
Our research builds on work on sparse coding and distributed representations in neuroscience, disentanglement and dictionary learning in machine learning, and compressed sensing in mathematics.
-
Monosemantic Features and Sparse Autoencoders for Neural Networks
By
–
There's a lot more in the paper if you're interested, including universality, "feature splitting", more evidence for the superposition hypothesis, and tips for training a sparse autoencoder to better understand your own network! https://
transformer-circuits.pub/2023/monoseman
tic-features/index.html
… -
Anthropic Hiring Research Scientists for Interpretability Team
By
–
If this work excites you, our interpretability team is hiring! See our job descriptions below. Research Scientist, Interpretability: https://
jobs.lever.co/Anthropic/33dc
d828-a140-4cd3-973f-1d9a828a00a7
… Research Engineer, Interpretability: https://
jobs.lever.co/Anthropic/3dbd
1272-d673-4494-999a-47528e7cd6a3
… -
Monosemantic Features: More Interpretable Than Neurons
By
–
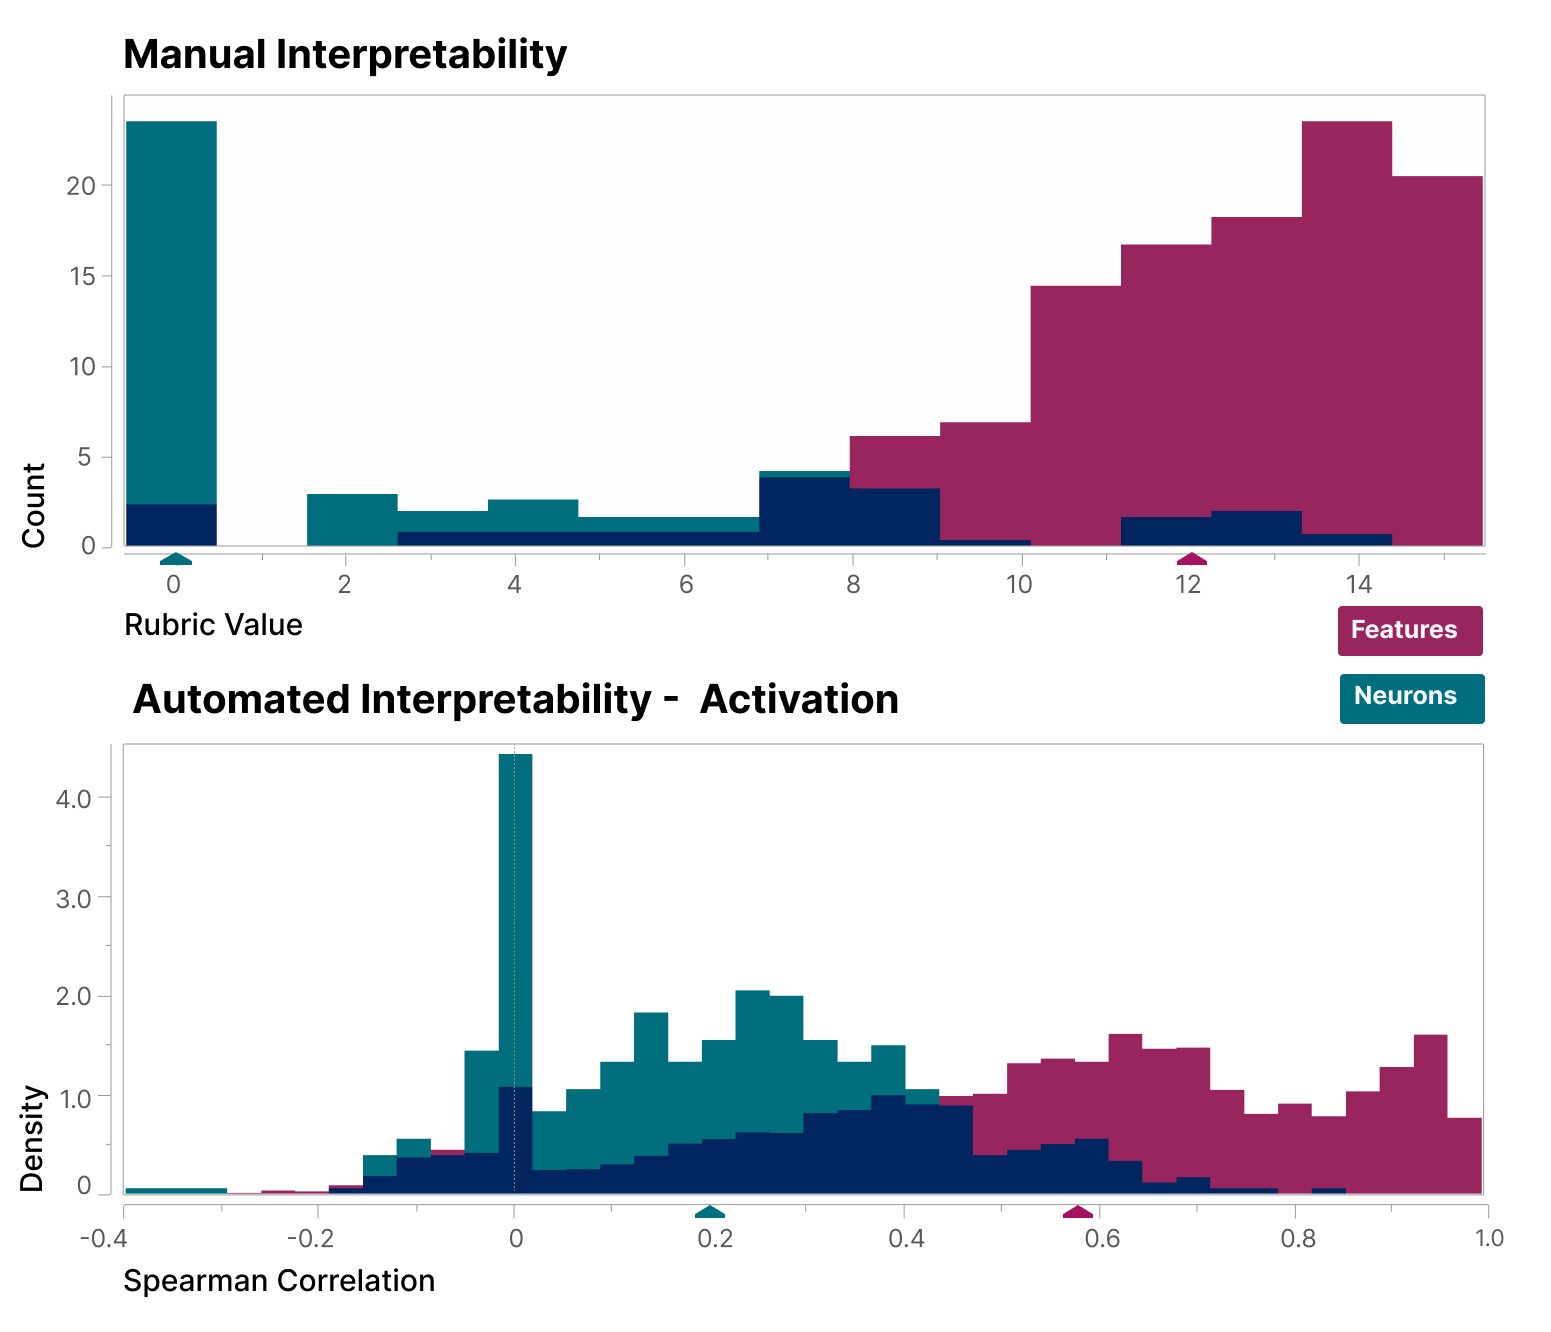
We also systematically show that the features we find are more interpretable than the neurons, using both a blinded human evaluator and a large language model (autointerpretability). https://
transformer-circuits.pub/2023/monoseman
tic-features/index.html
… -

Finite-State Automata Features Generate Complex HTML Behaviors
By
–
Features connect in "finite-state automata"-like systems that implement complex behaviors. For example, we find features that work together to generate valid HTML. https://
transformer-circuits.pub/2023/monoseman
tic-features/index.html
… -
Monosemantic Features Steer Transformer Model Outputs
By
–
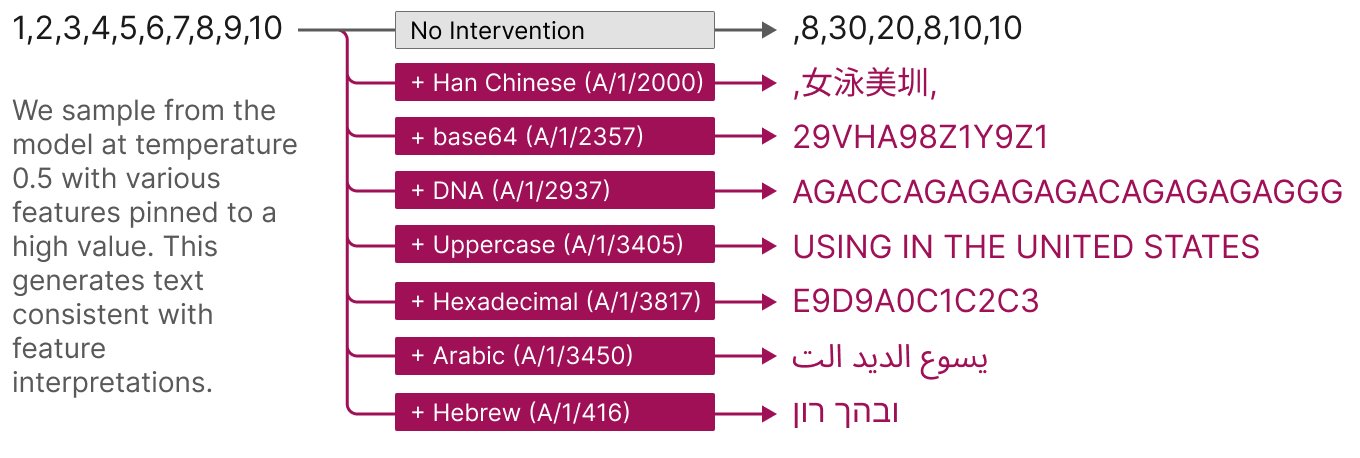
Artificially stimulating a feature steers the model's outputs in the expected way; turning on the DNA feature makes the model output DNA, turning on the Arabic script feature makes the model output Arabic script, etc. https://
transformer-circuits.pub/2023/monoseman
tic-features/index.html
… -
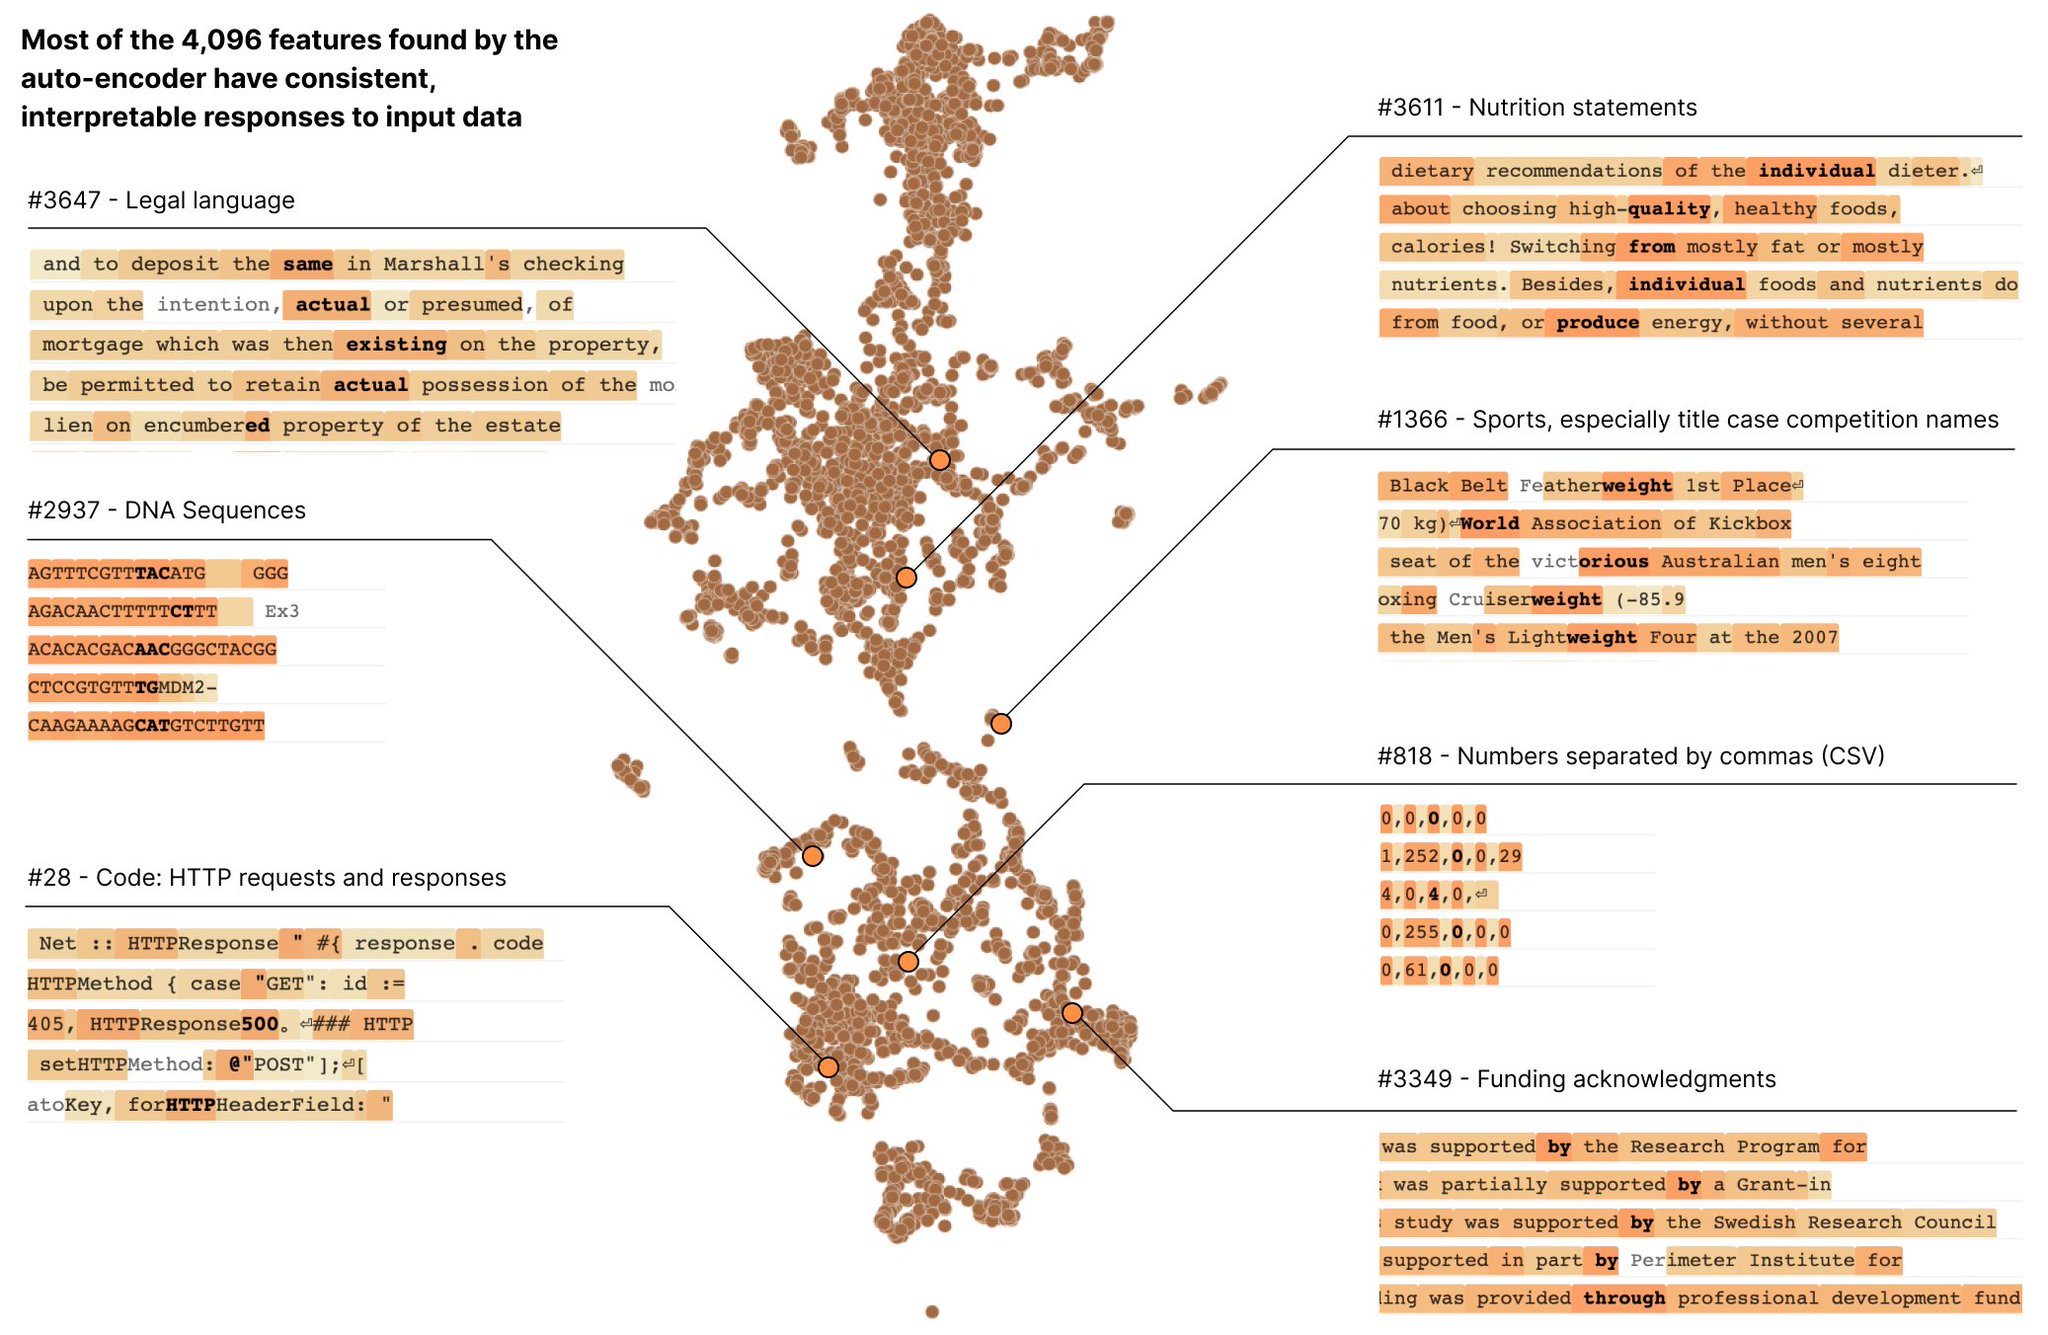
Sparse Autoencoders Extract Purer Concepts Than Individual Neurons
By
–
Dictionary learning works! Using a "sparse autoencoder", we can extract features that represent purer concepts than neurons do. For example, turning ~500 neurons into ~4000 features uncovers things like DNA sequences, HTTP requests, and legal text. https://
transformer-circuits.pub/2023/monoseman
tic-features/index.html
…