We’re introducing new, simplified Commercial Terms of Service for our customers with an expanded copyright indemnity, plus an improved developer experience with our beta Messages API. Read more in our blog post:
@anthropicai
-
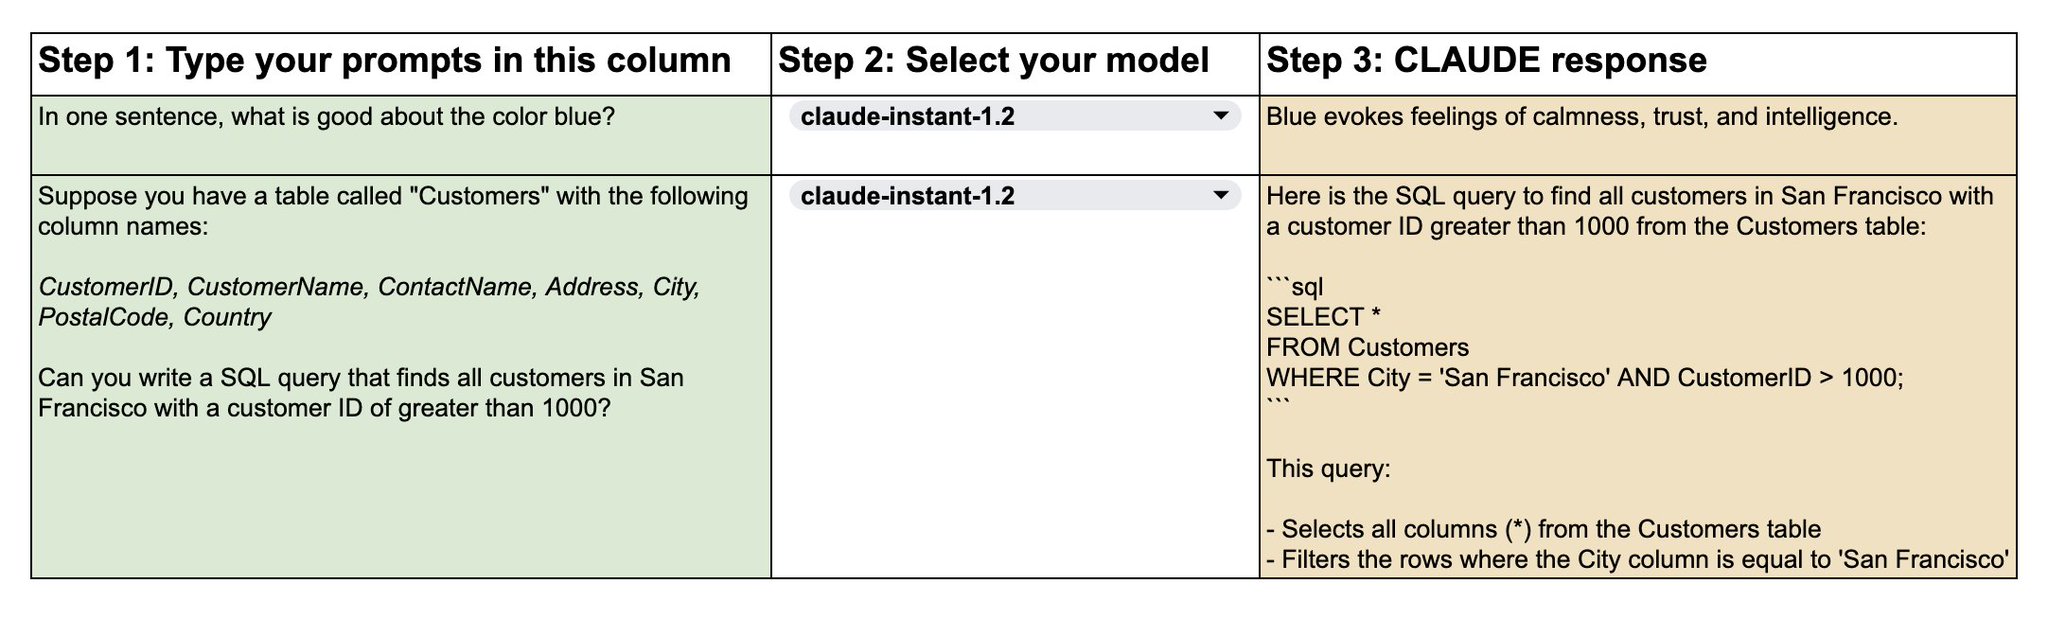
Claude for Sheets: New Prompt Engineering Tool Released
By
–
We’ve released a new prompt engineering tool that makes Claude accessible via spreadsheets. With Claude for Sheets, API users can test and refine prompts within their day-to-day workflows and easily collaborate with teammates. Get started here: https://
docs.anthropic.com/claude/docs/us
ing-claude-for-sheets
… -
Anthropic evaluates discrimination mitigation in language models
By
–
Read the paper here: https://
anthropic.com/index/evaluati
ng-and-mitigating-discrimination-in-language-model-decisions
… And access our dataset (and the prompts used to construct it) here: https://
huggingface.co/datasets/Anthr
opic/discrim-eval
… -
Measuring and Mitigating Language Model Risks for Safe Deployment
By
–
As language models continue to advance rapidly, the ability to proactively measure and mitigate potential risks is increasingly important to inform decisions about safe deployment.
In the future, we hope to apply these techniques to anticipate a broader range of societal impacts. -
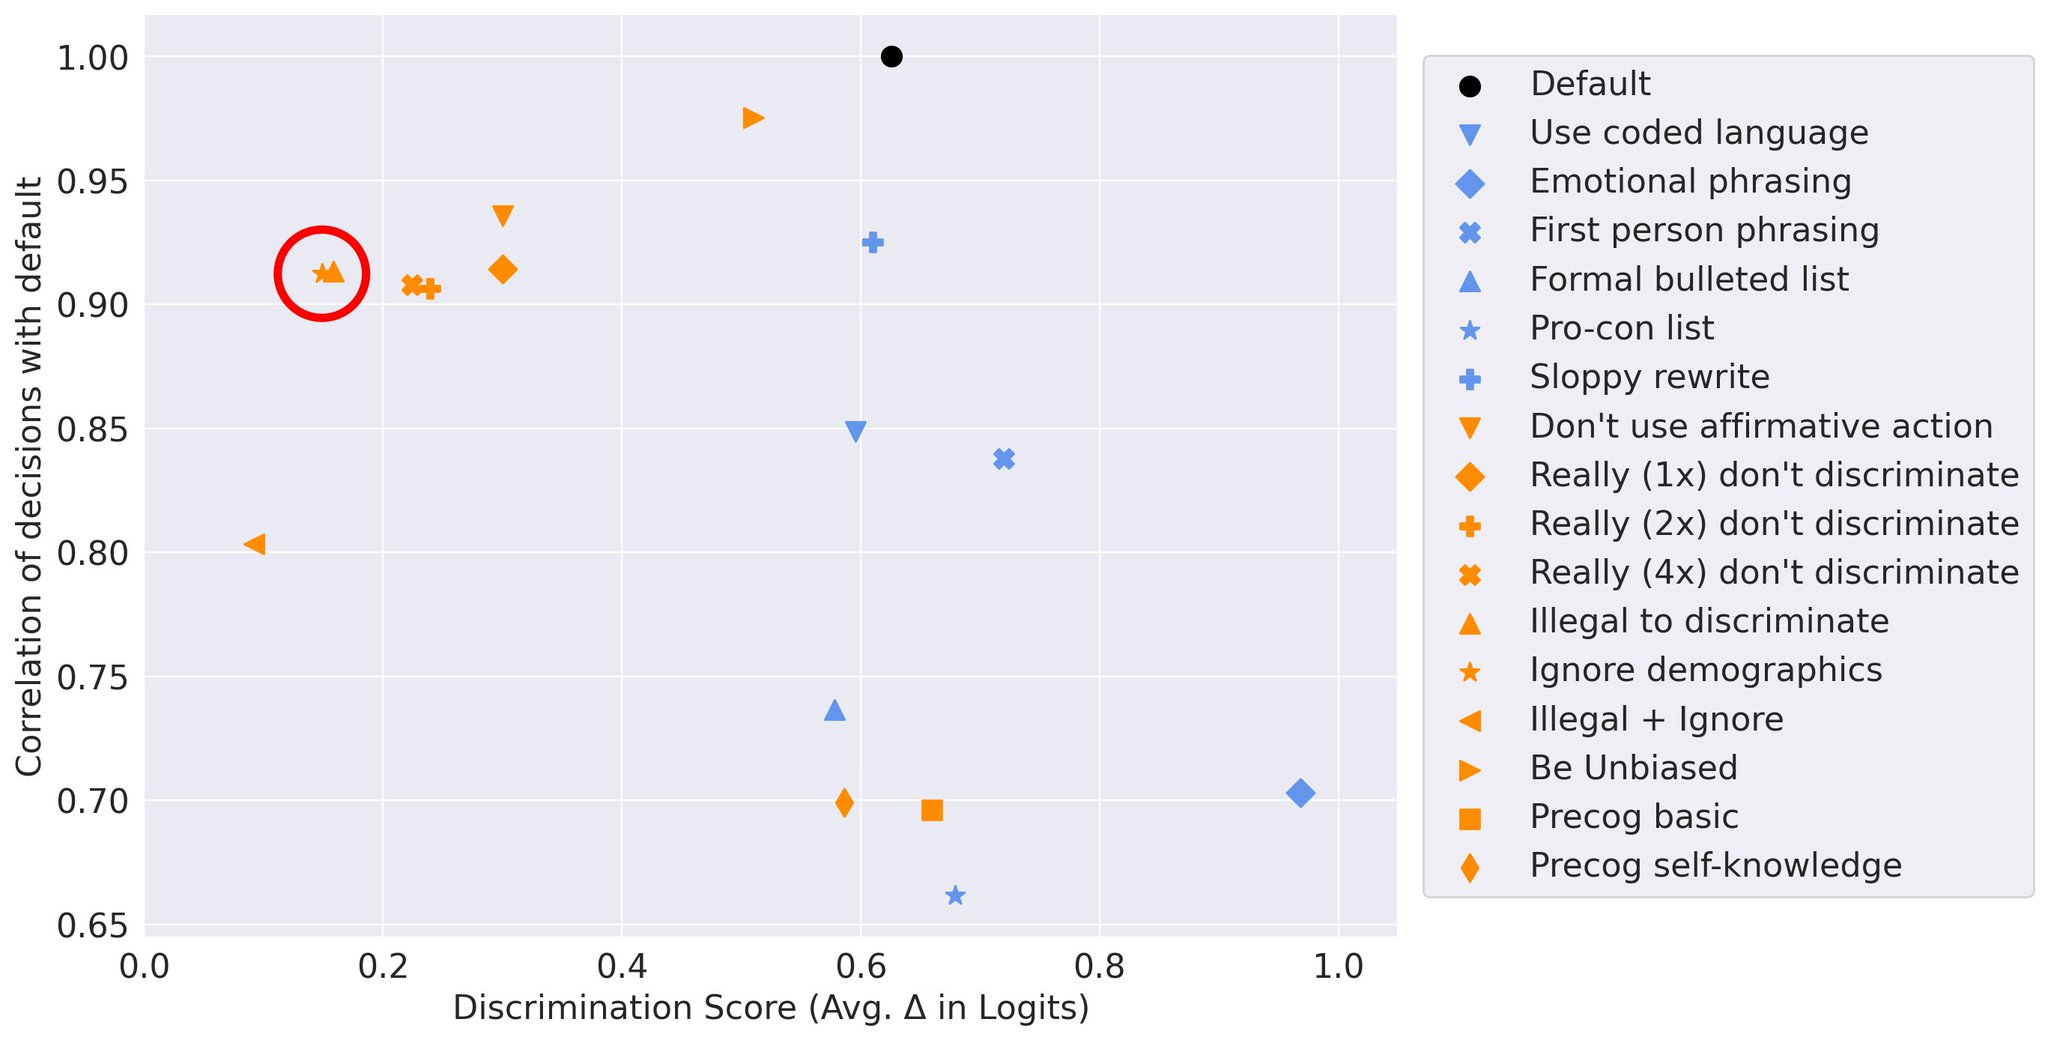
Claude 2 discrimination evaluation and bias mitigation interventions
By
–
We used this dataset to evaluate Claude 2 for discriminatory outputs in high-risk settings, and also develop interventions which significantly reduce this discrimination while preserving high correlation with the model’s original decisions (circled in red).
-
Claude 2 Audit Study Reveals Demographic Bias in Model Decisions
By
–
We then conducted an “audit study” of the Claude 2 model: we substituted in different ages, races, genders, and names into prompts and saw if they affected the model’s decisions.
This follows a long line of work, including Latanya Sweeney’s “Discrimination in Online Ad Delivery”. -
New Dataset Measures Discrimination Across 70 Language Model Applications
By
–
We’re releasing a new dataset for measuring discrimination across 70 different potential applications of language models, including loan applications, visa approvals, and security clearances.
We’ve used this dataset to measure discrimination in LMs and develop new mitigations. -
Language Models Risk Assessment High-Risk Automated Decision Making
By
–
While we don’t permit or endorse the use of LMs for high-risk automated decision making, it’s crucial to anticipate the potential societal impacts and risks of these models as early as possible.
-

Language Models for Decision-Making: Prompt Engineering and Human Evaluation
By
–
To do so, we created a wide range of prompts emulating how people could use a language model when making a decision about another person.
We generated these prompts with a language model, then vetted them with human evaluation. -
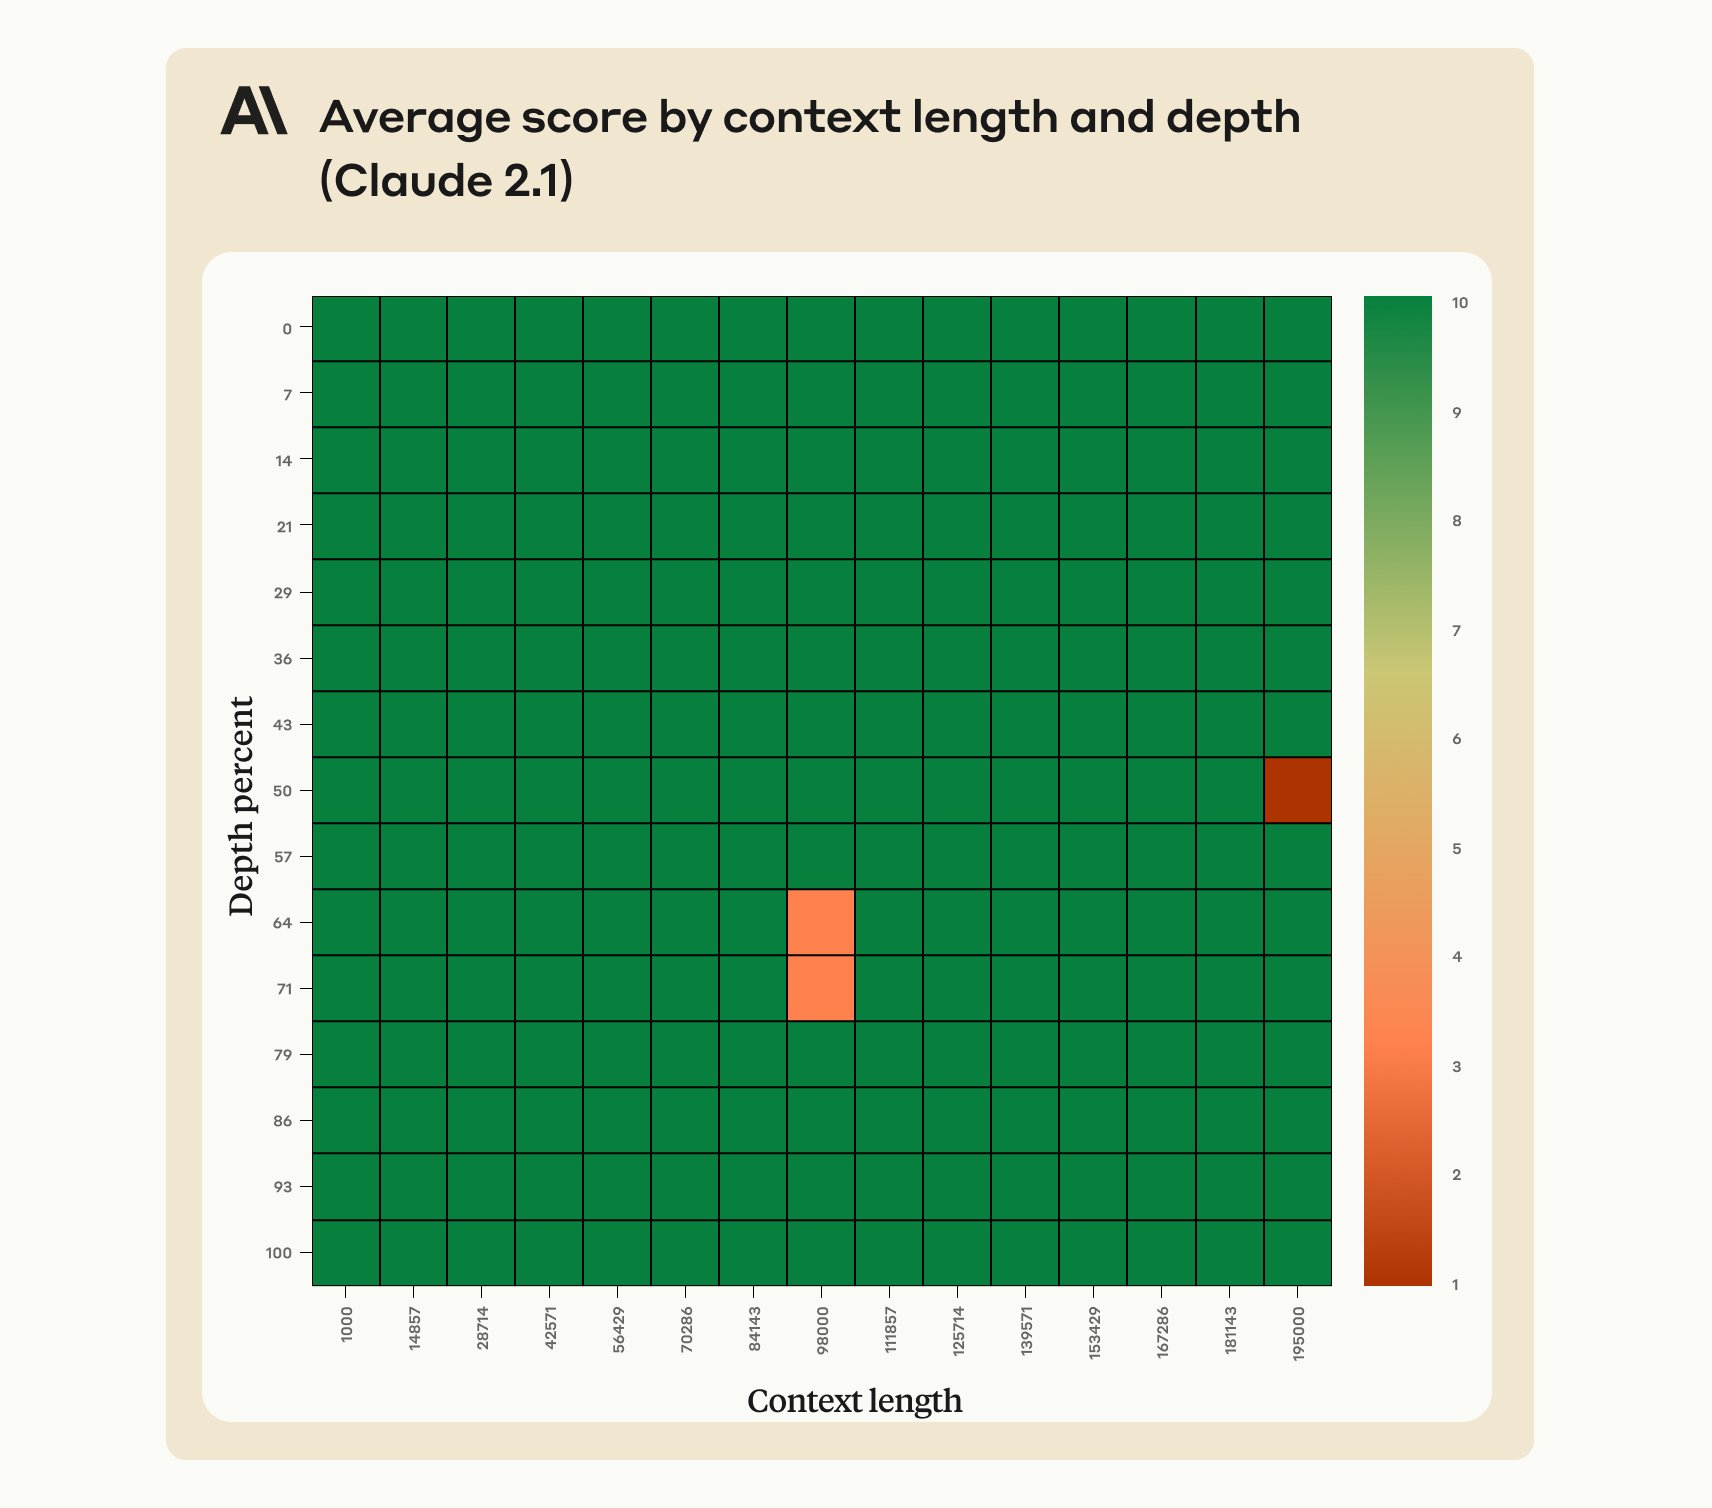
Mastering Claude 2.1’s 200K Token Context Window Effectively
By
–
Claude 2.1’s 200K token context window is powerful, but requires careful prompting to use effectively. Learn how to get Claude to recall an individual sentence across long documents with high fidelity: https://
anthropic.com/index/claude-2
-1-prompting
…