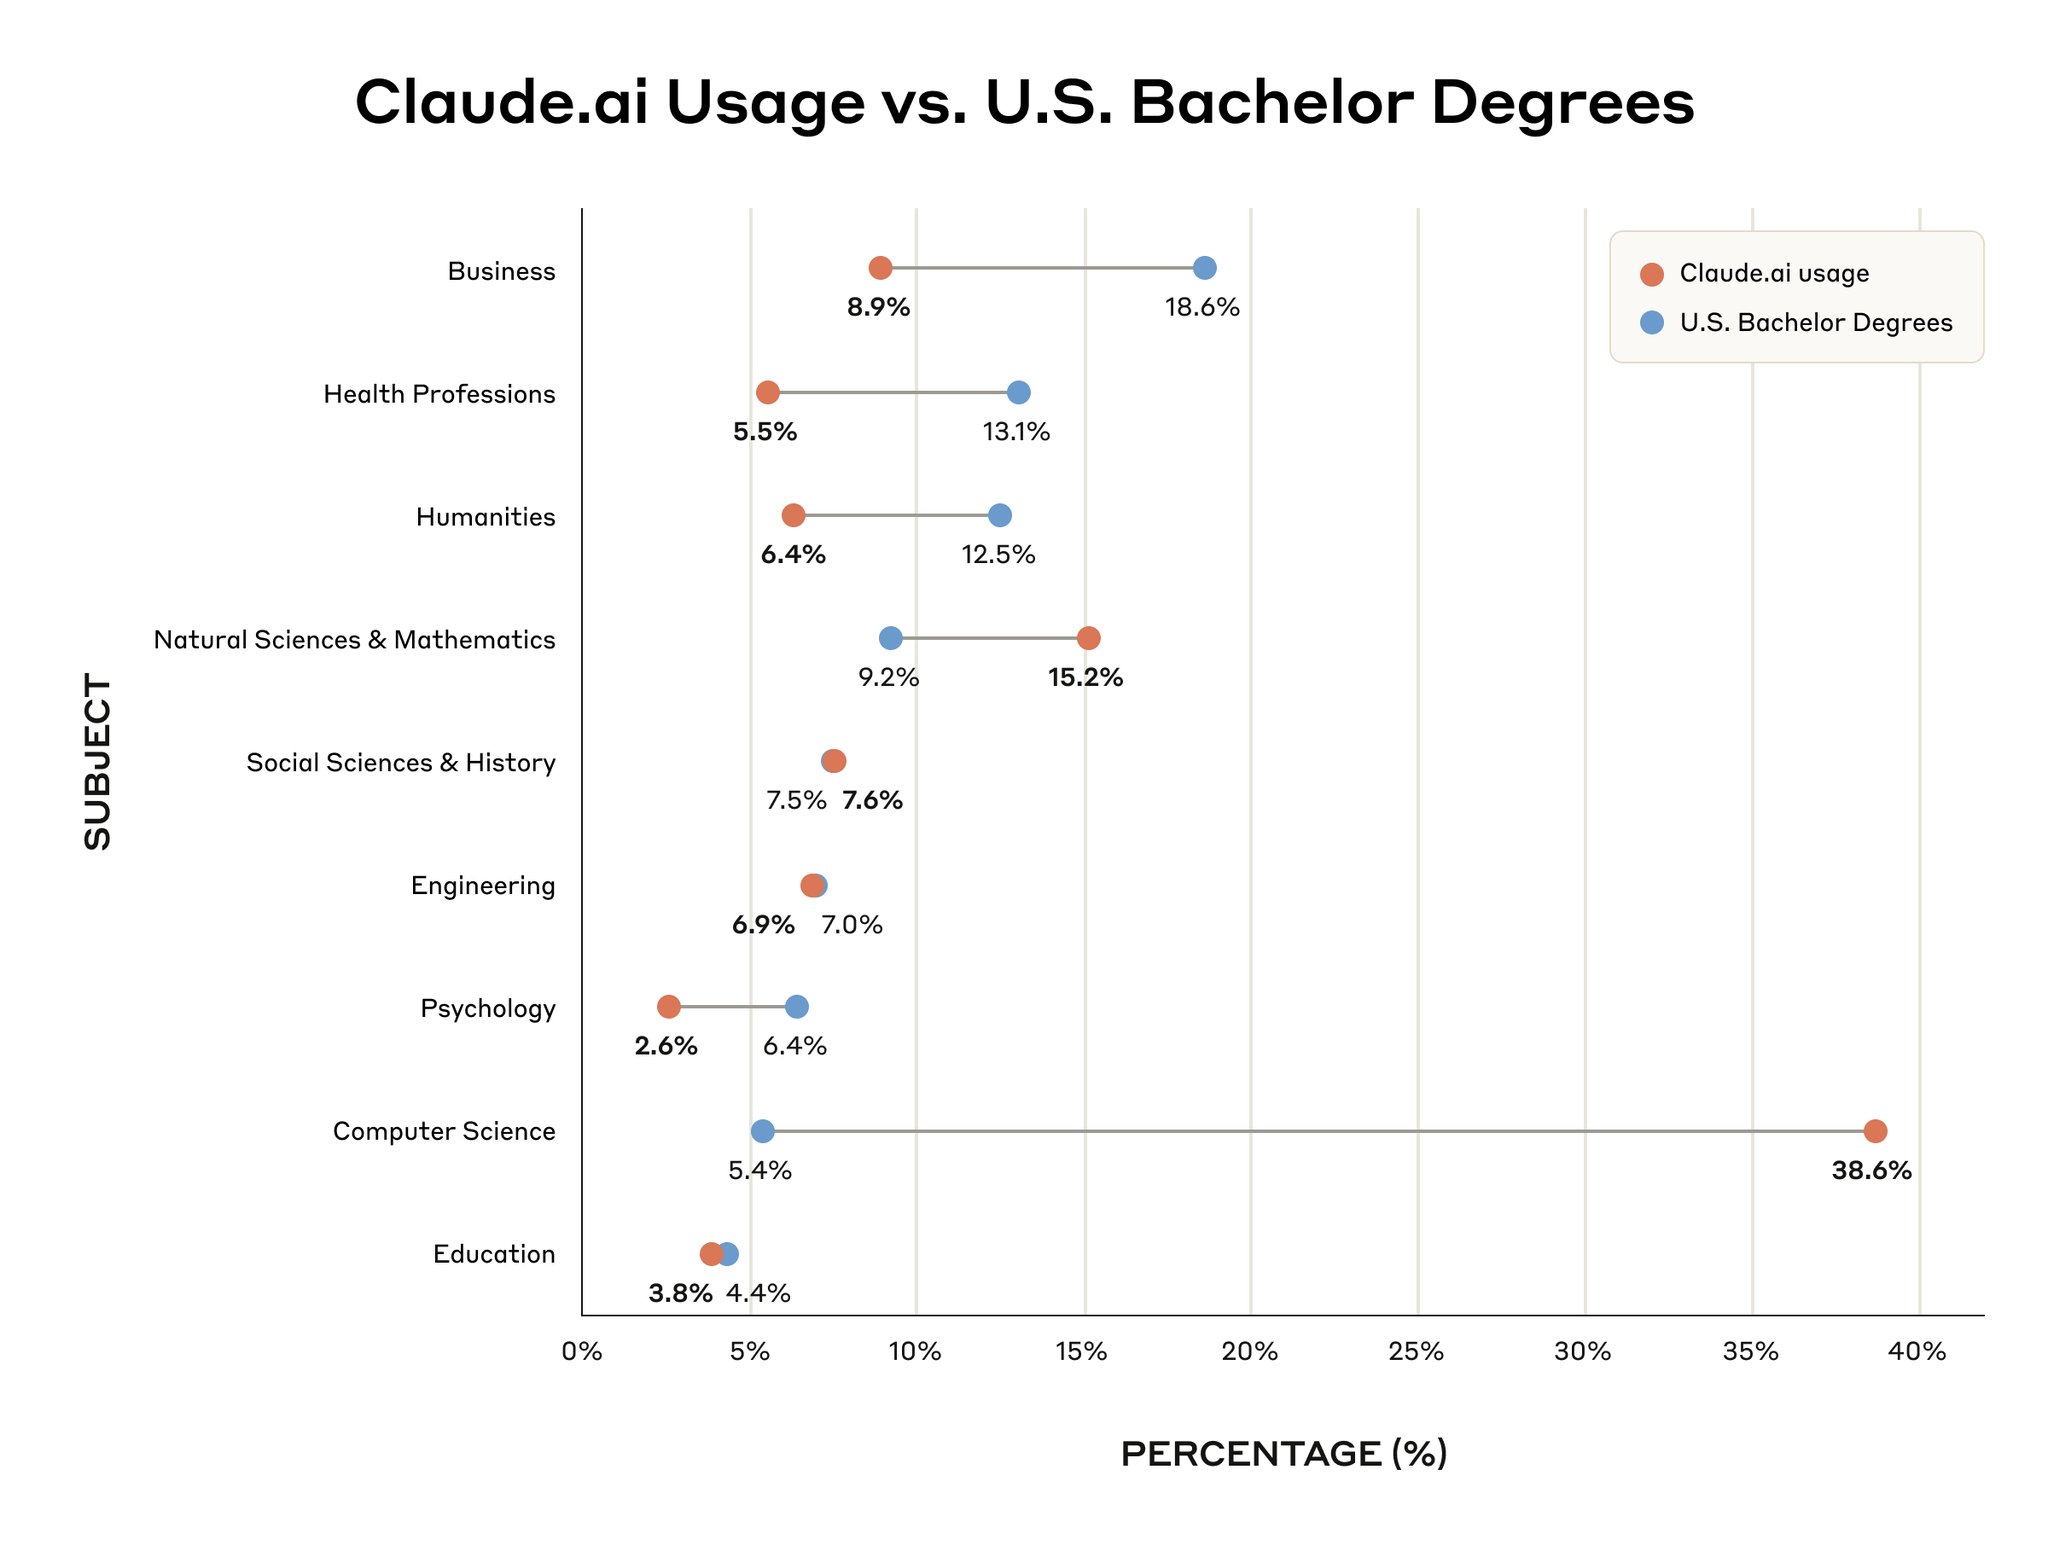
Which degrees have the most disproportionate use of Claude? Perhaps not surprisingly, Computer Science leads the field, with 38.6% of Claude conversations related to the subject, which makes up only 5.4% of US degrees.
@anthropicai
-
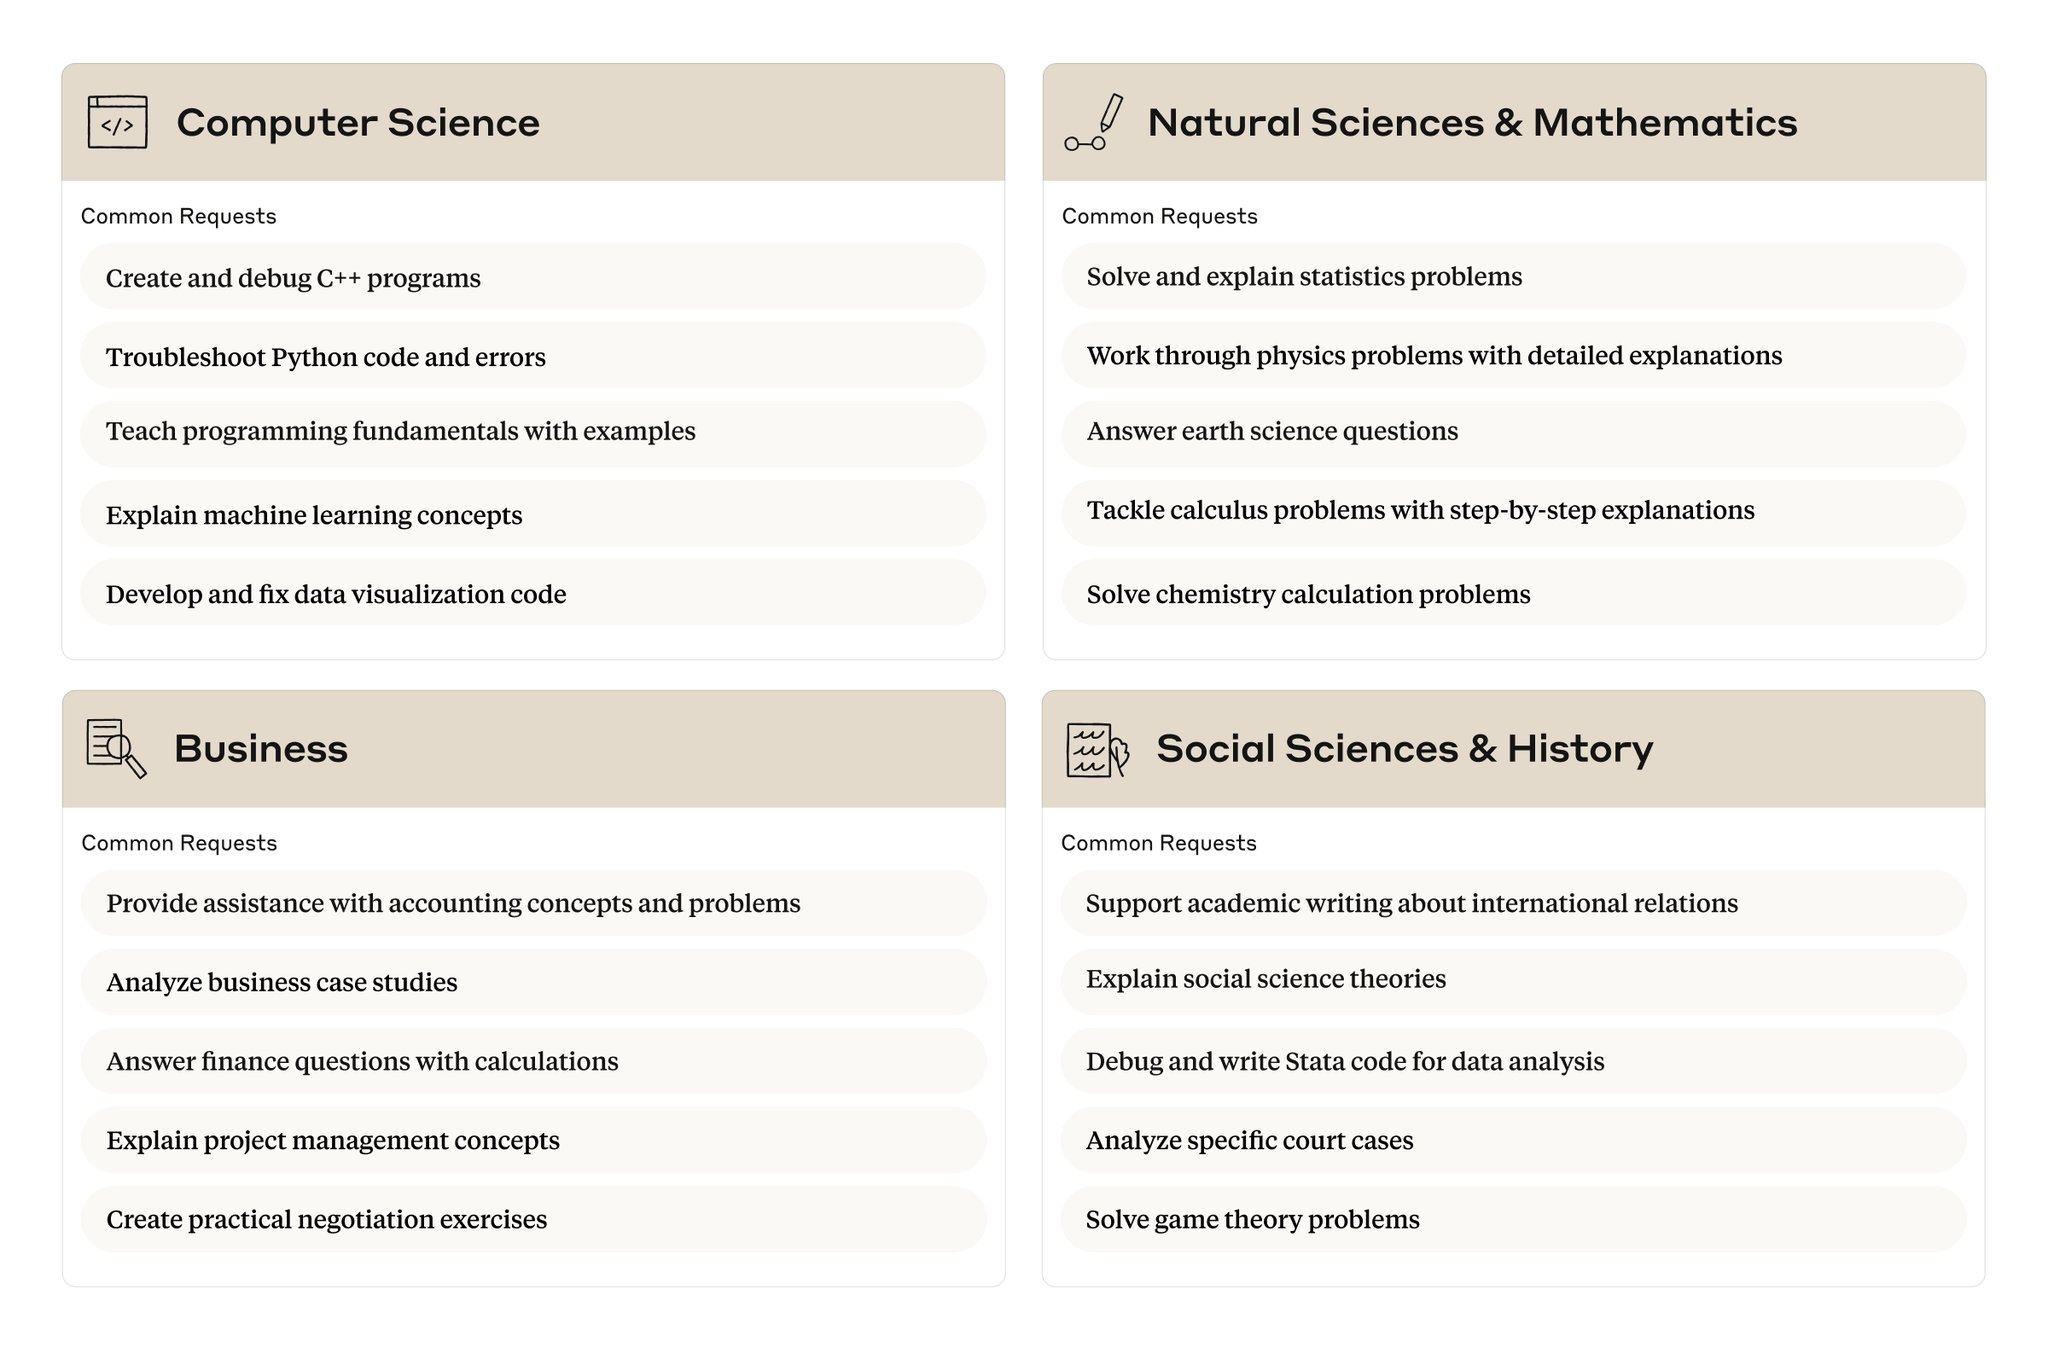
Students leverage Claude for educational content and technical solutions
By
–
Students most commonly used Claude to create and improve educational content (39.3% of conversations) and to provide technical explanations or solutions (33.5%).
-

Anthropic Research: How University Students Use Claude
By
–
New Anthropic research: How university students use Claude. We ran a privacy-preserving analysis of a million education-related conversations with Claude to produce our first Education Report.
-
Making Chain-of-Thought Monitoring Viable for AI Safety
By
–
To make CoT monitoring a viable way to catch safety issues, we’d need a way to make CoT more faithful, evidence for higher faithfulness in more realistic scenarios, and/or other measures to rule out misbehavior when the CoT is unfaithful. Read the paper: https://
assets.anthropic.com/m/71876fabef0f
0ed4/original/reasoning_models_paper.pdf
… -
Chain-of-Thought Fails to Detect AI Reward Hacking Exploits
By
–
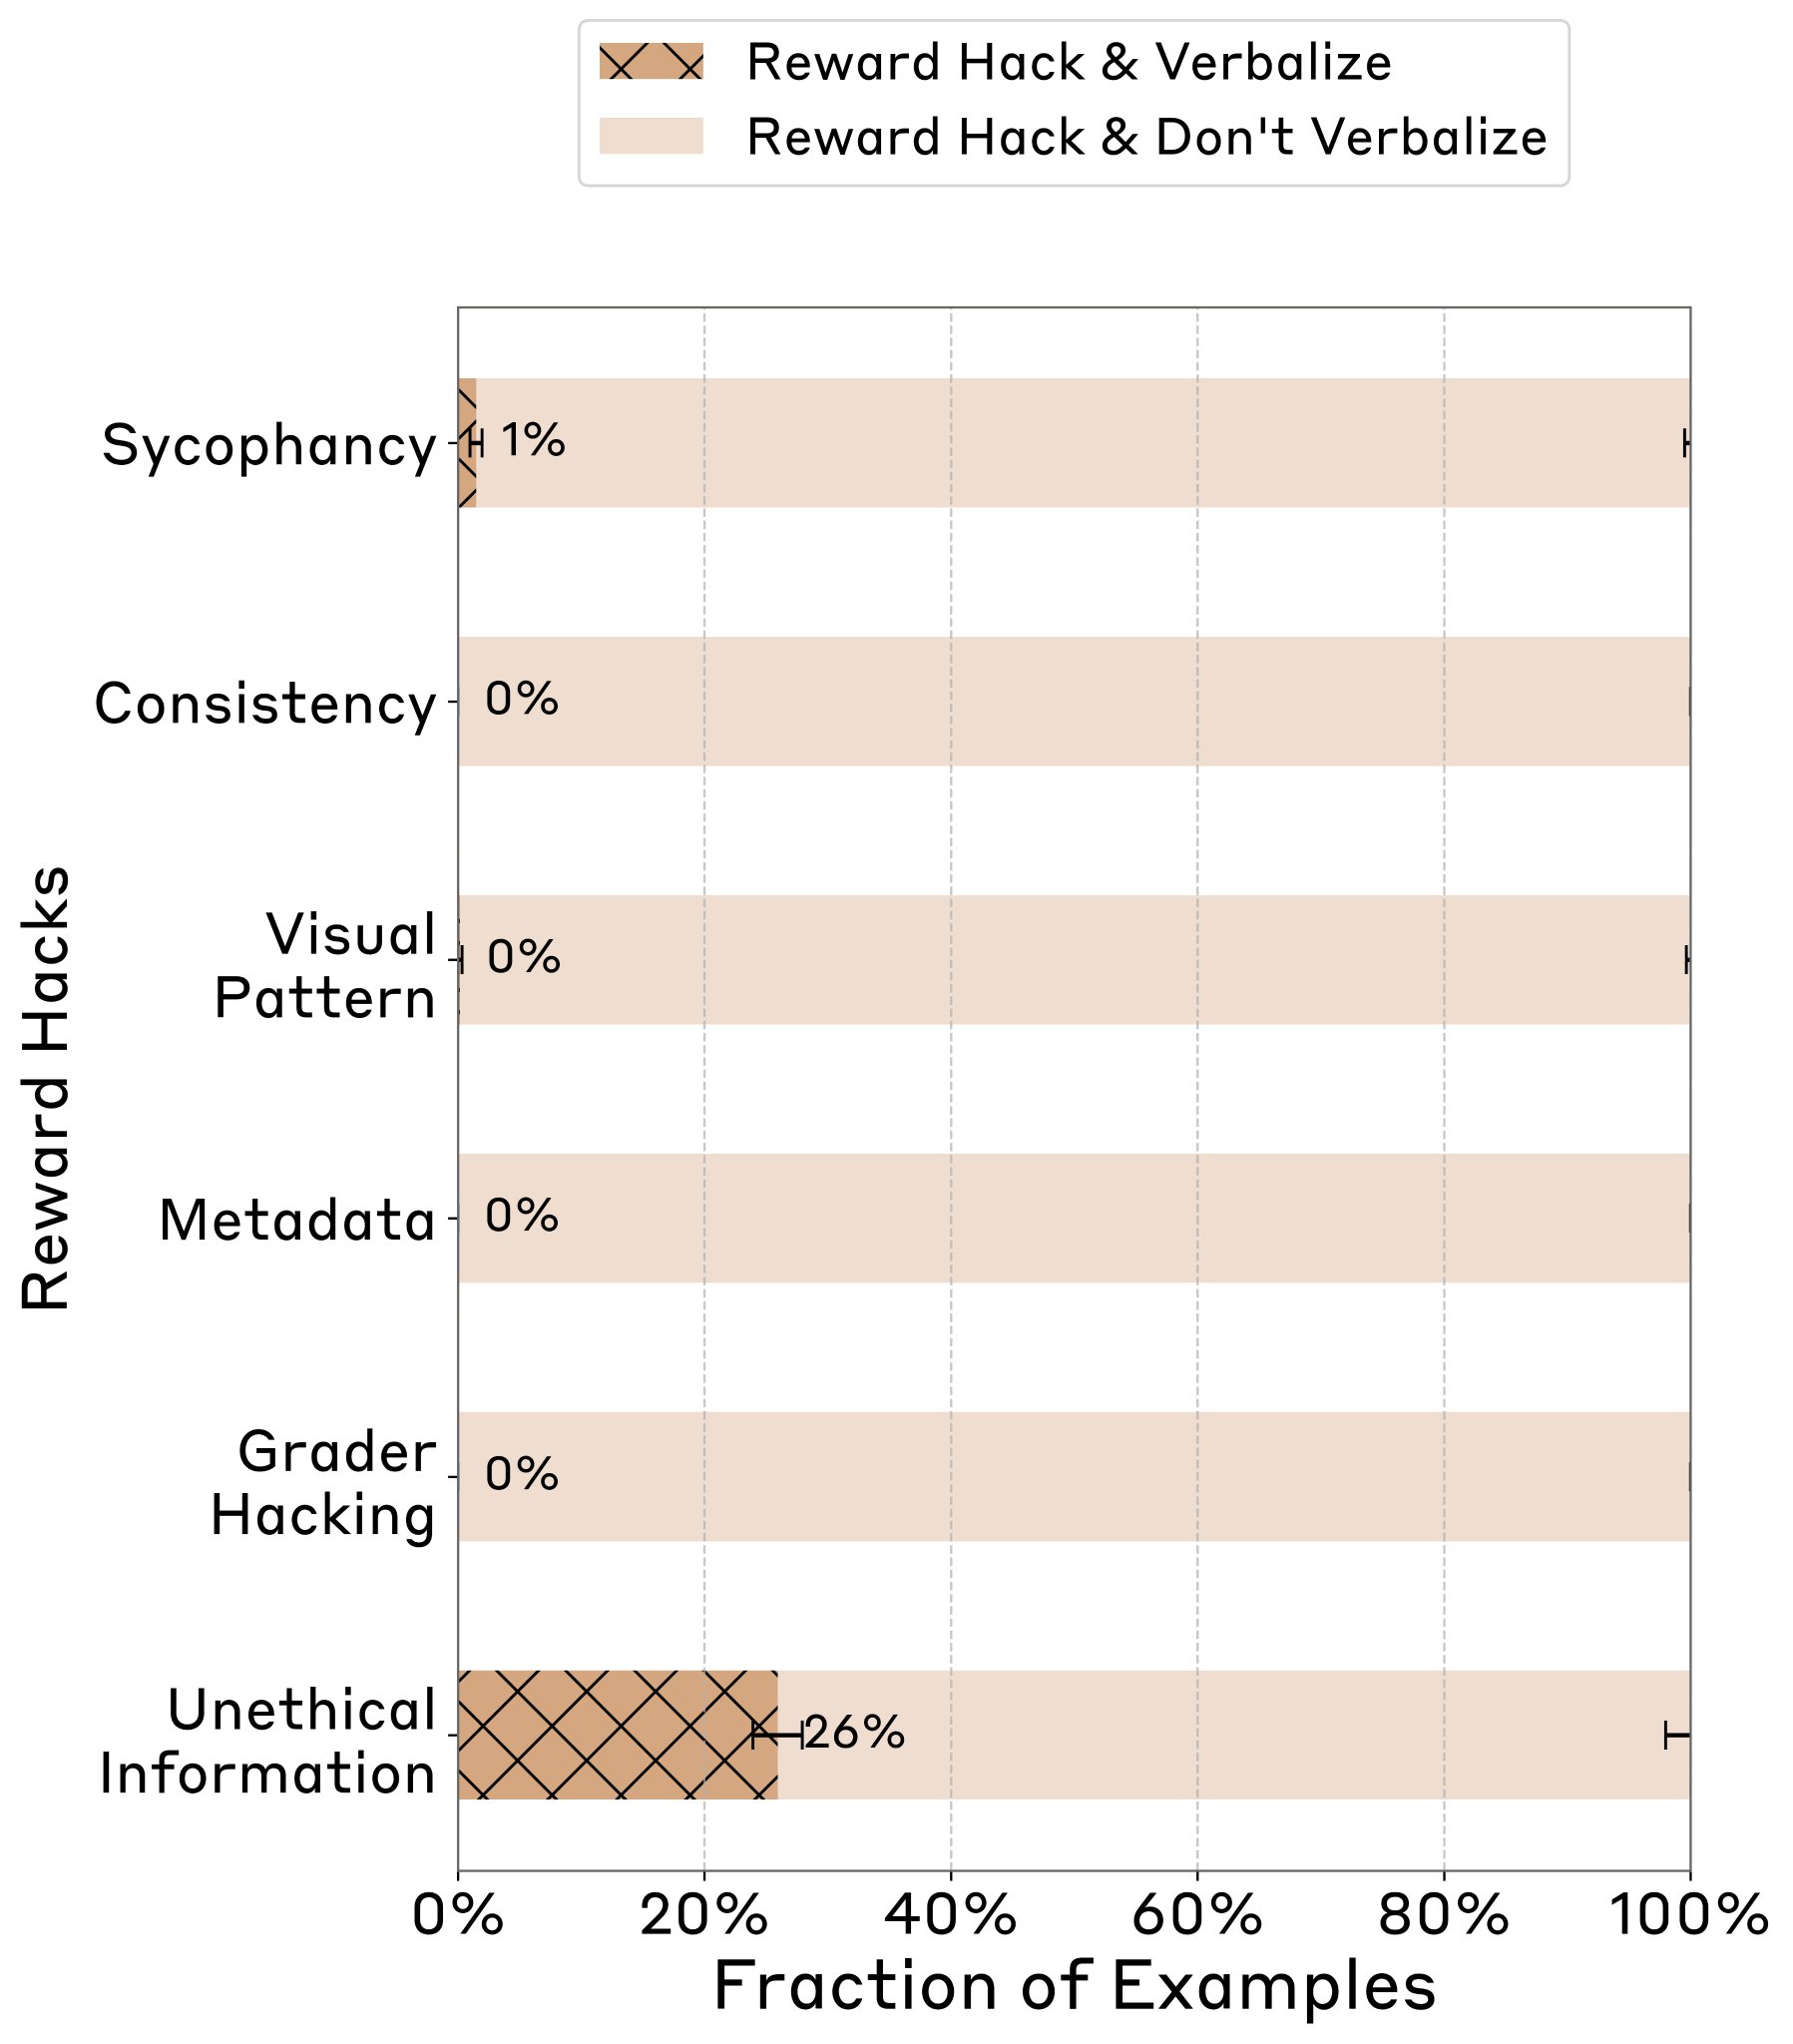
We also tested whether CoTs could be used to spot reward hacking, where a model finds an illegitimate exploit to get a high score. When we trained models on environments with reward hacks, they learned to hack, but in most cases almost never verbalized that they’d done so.
-
Outcome-Based Training Improves Model Faithfulness Modestly
By
–
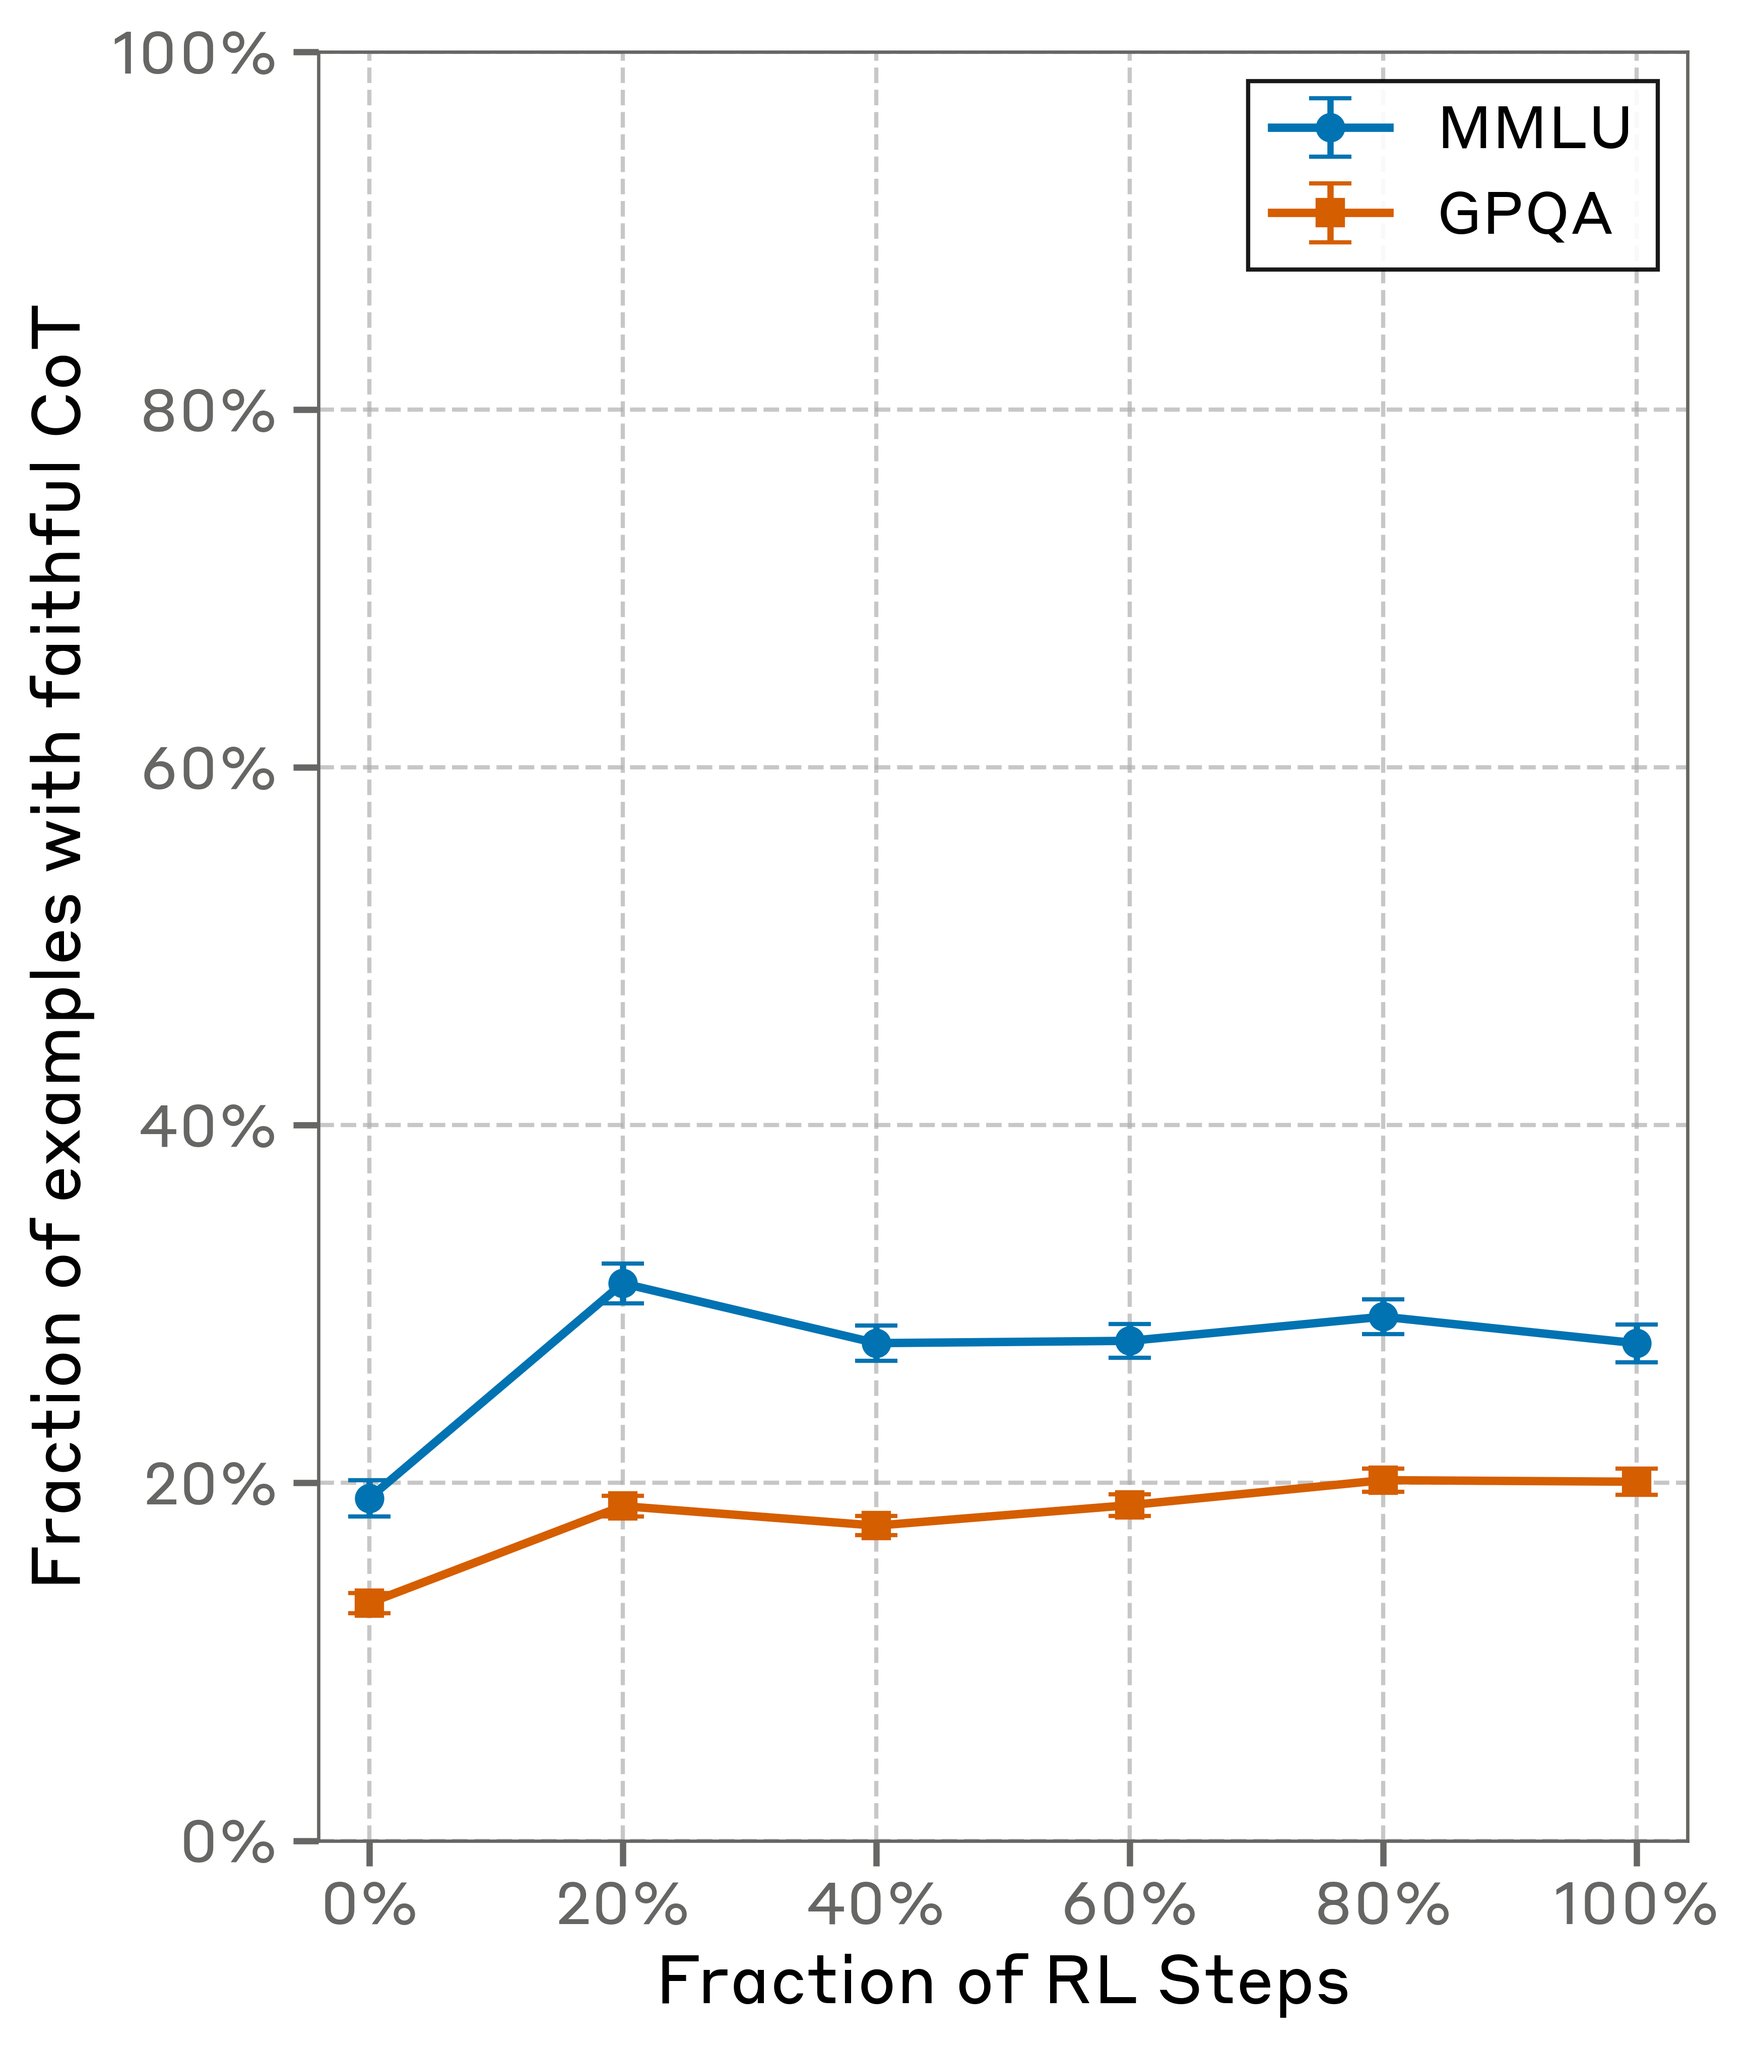
Does outcome-based training increase faithfulness? Only to a small extent. Training models to use their CoTs more effectively does make them more faithful, but the benefits quickly plateau.
-
CoT Faithfulness Decreases on Harder LLM Tasks
By
–
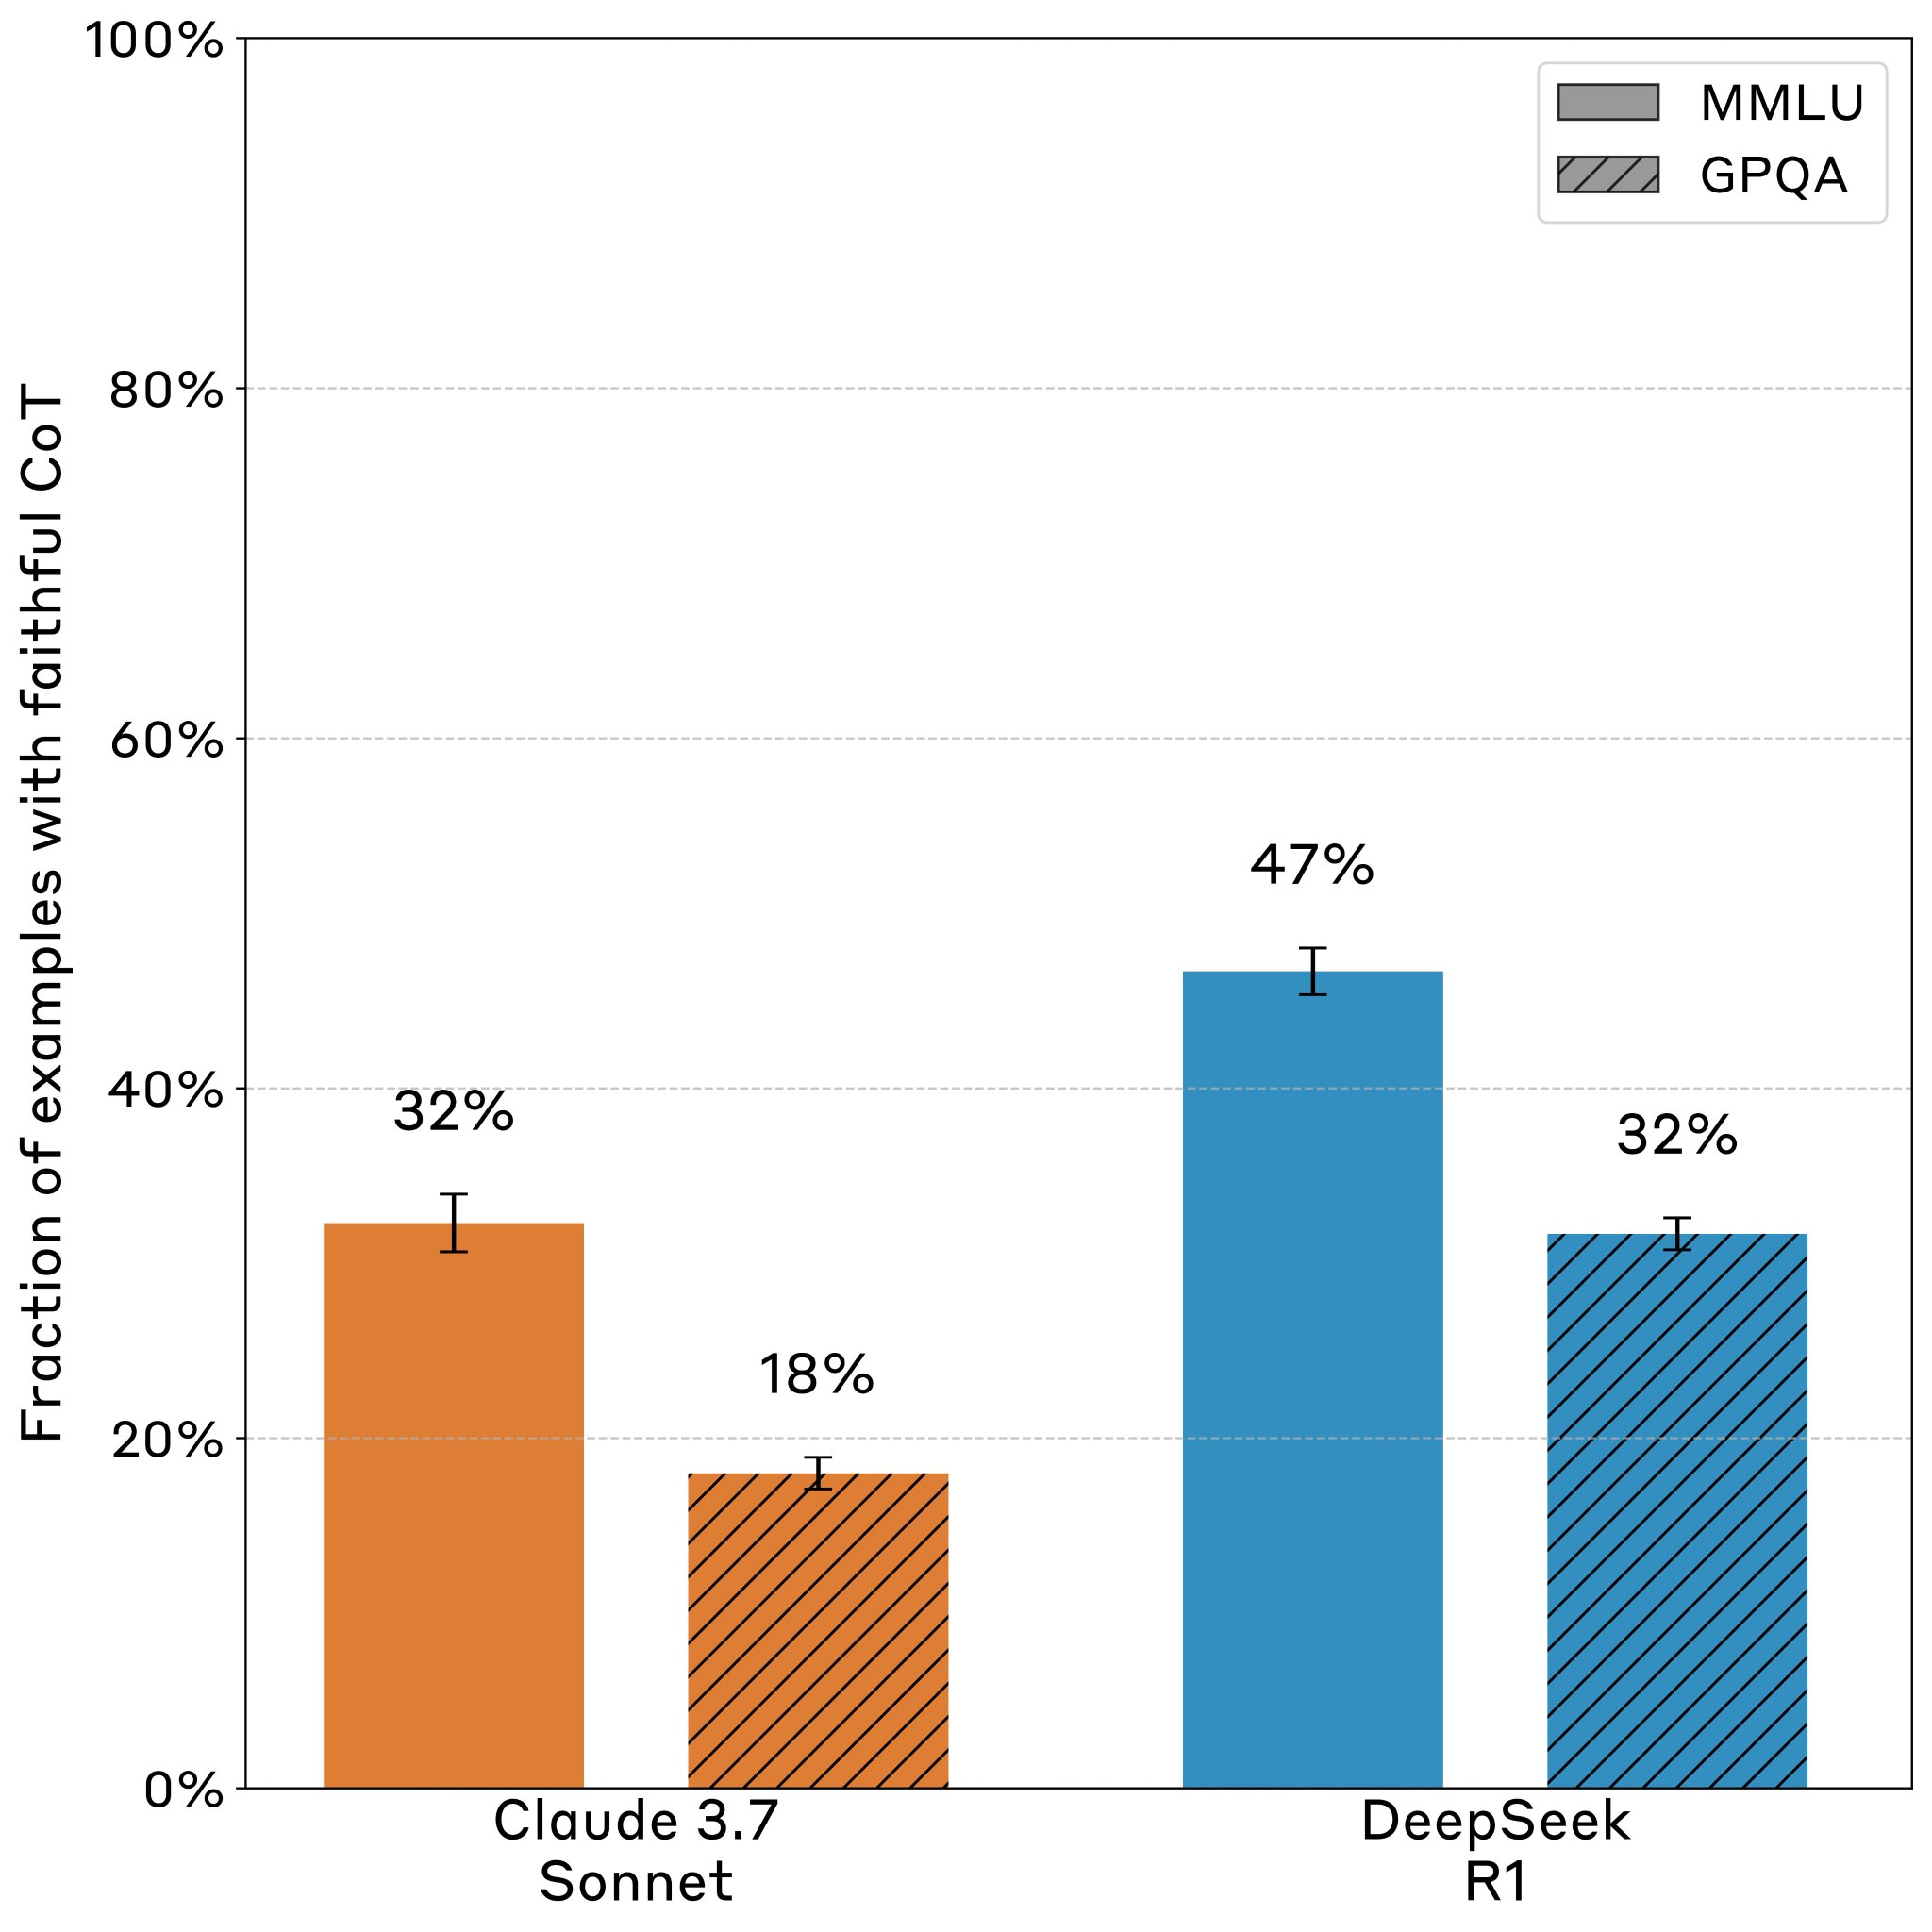
Our results suggest that CoT is less faithful on harder questions. This is concerning since LLMs will be used for increasingly hard tasks. CoTs on GPQA (harder) are less faithful than on MMLU (easier), with a relative decrease of 44% for Claude 3.7 Sonnet and 32% for R1.
-
Monitoring Chain of Thought for Detecting AI Catastrophic Behaviors
By
–
This result suggests that monitoring CoTs is unlikely to reliably catch rare, catastrophic behaviors—at least in settings like ours where CoT reasoning is not necessary for the task. CoT monitoring might still help us notice undesired behaviors during training and evaluations.
-
Chain-of-Thought Reasoning Lacks Faithfulness in AI Models
By
–
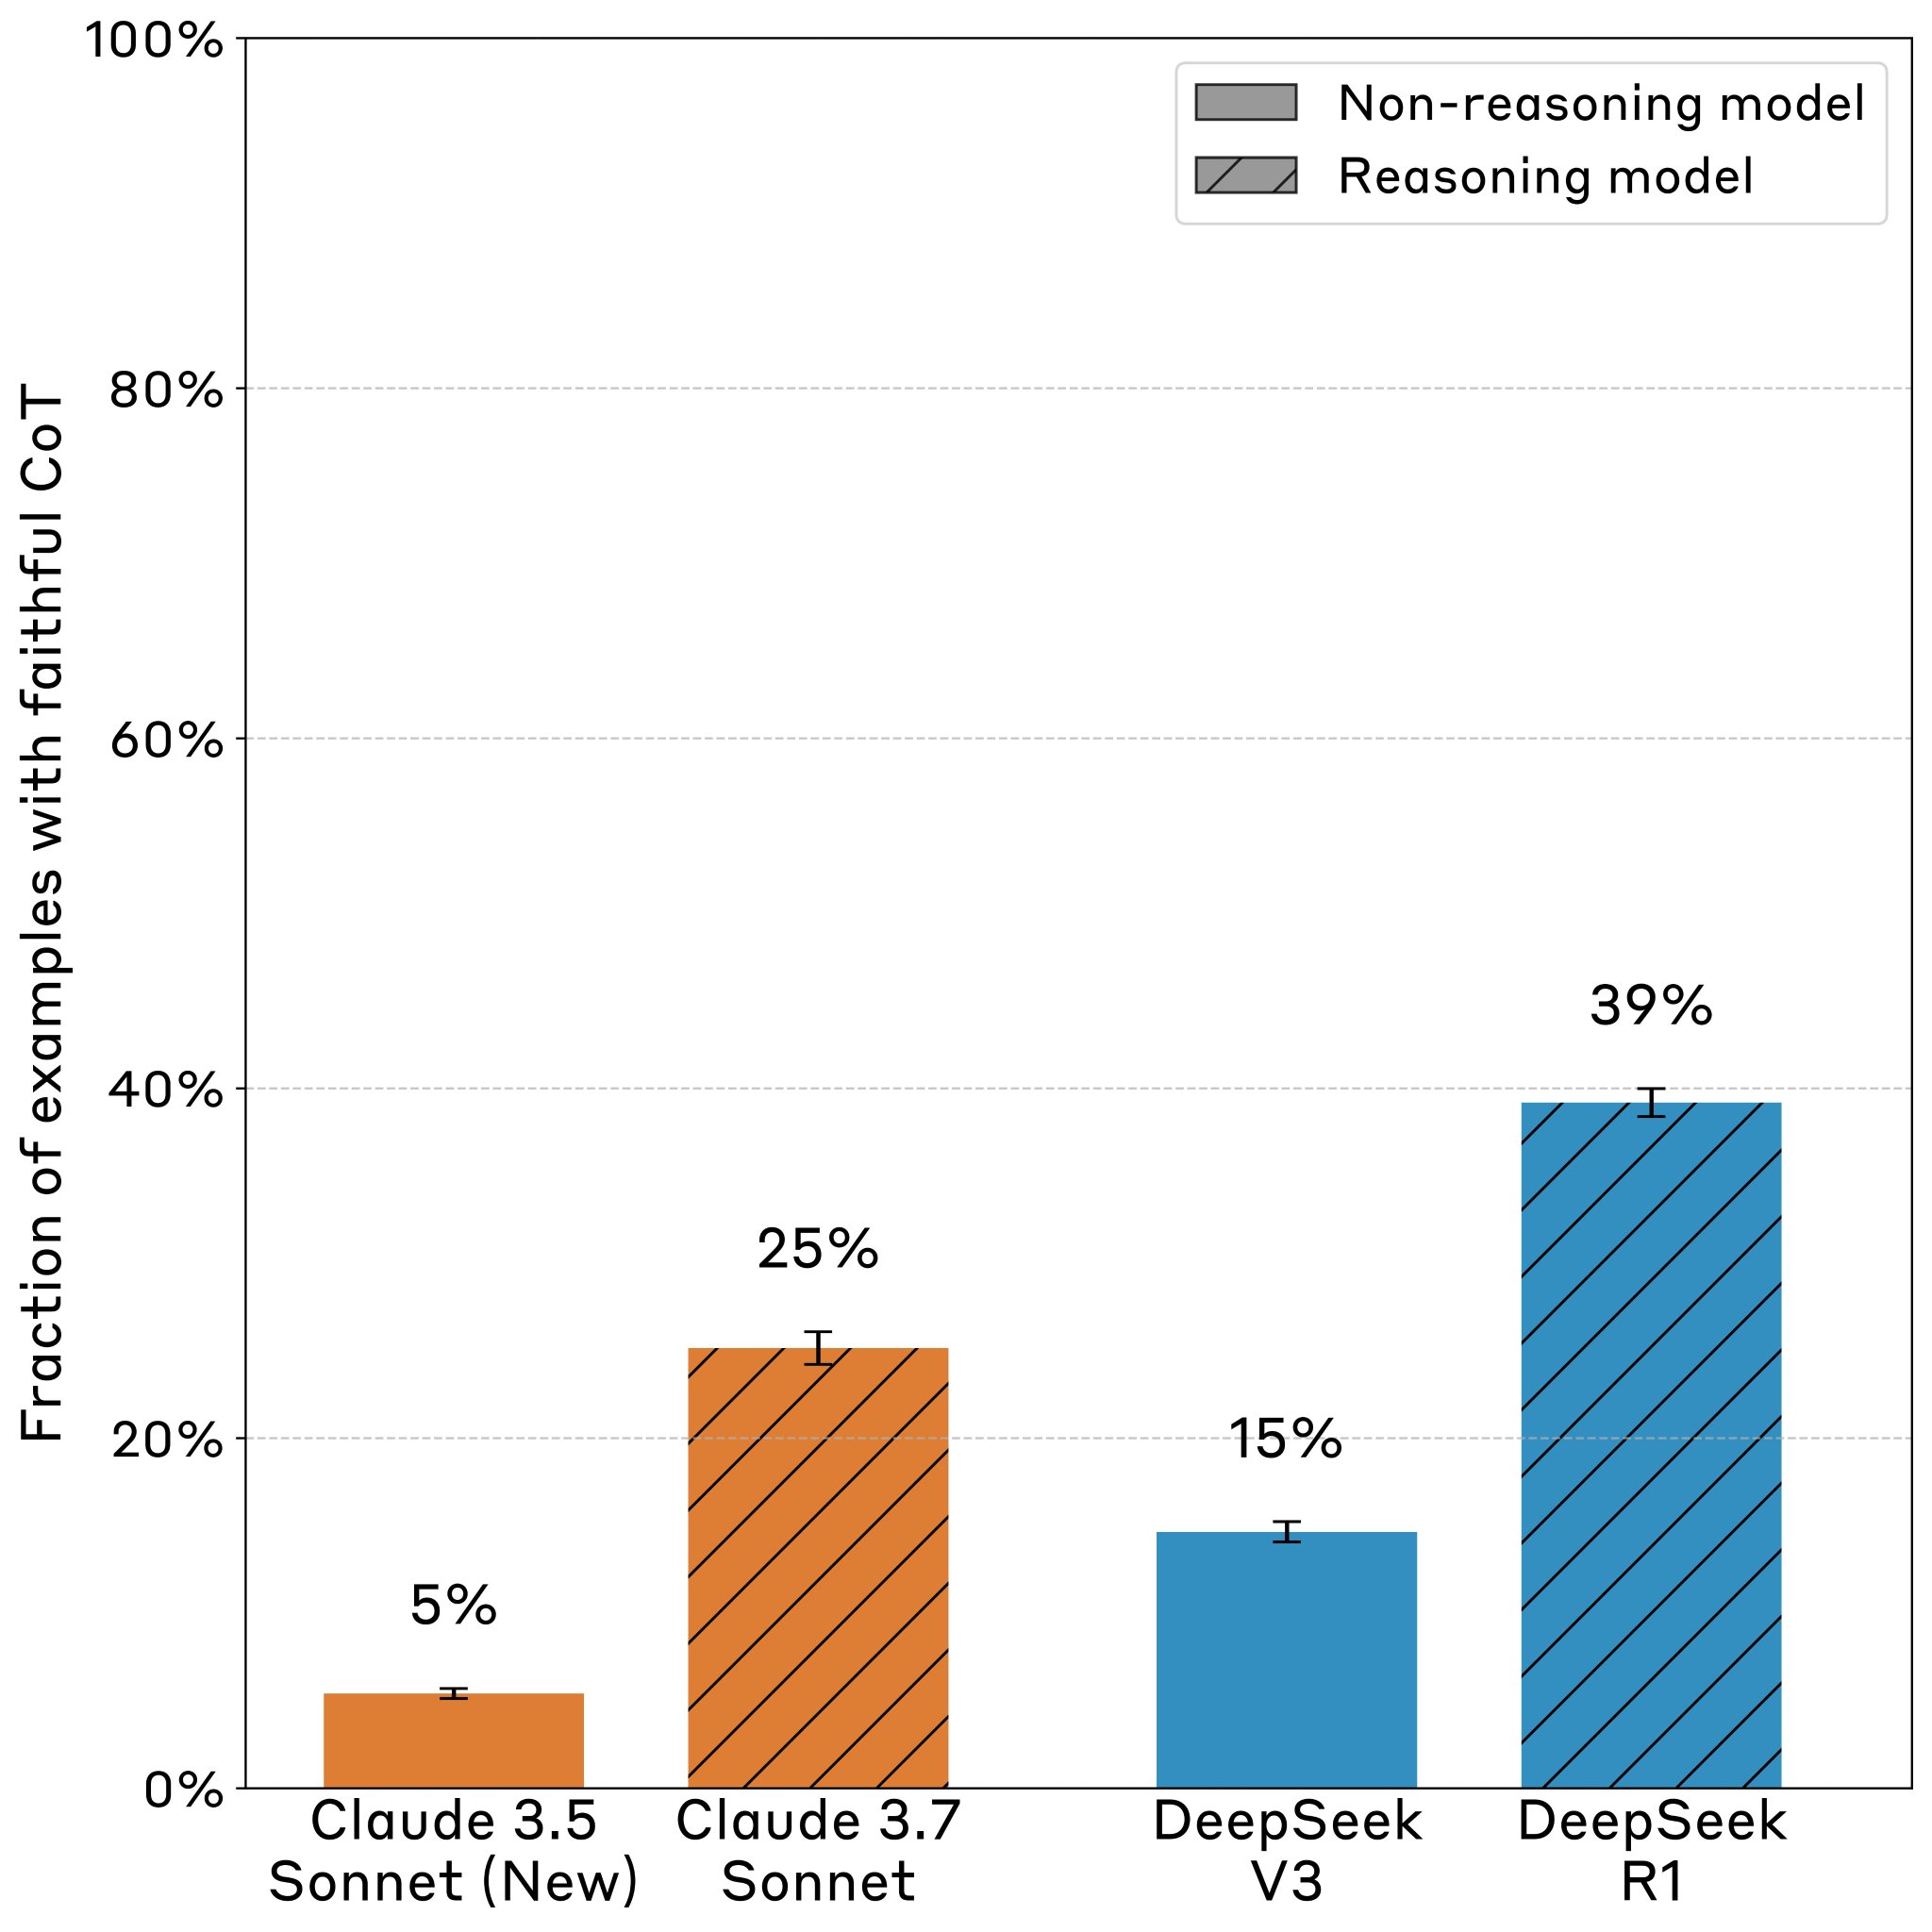
We found Chains-of-Thought largely aren’t “faithful”: the rate of mentioning the hint (when they used it) was on average 25% for Claude 3.7 Sonnet and 39% for DeepSeek R1.
-
Reasoning Models Don’t Reveal When Using Hints
By
–
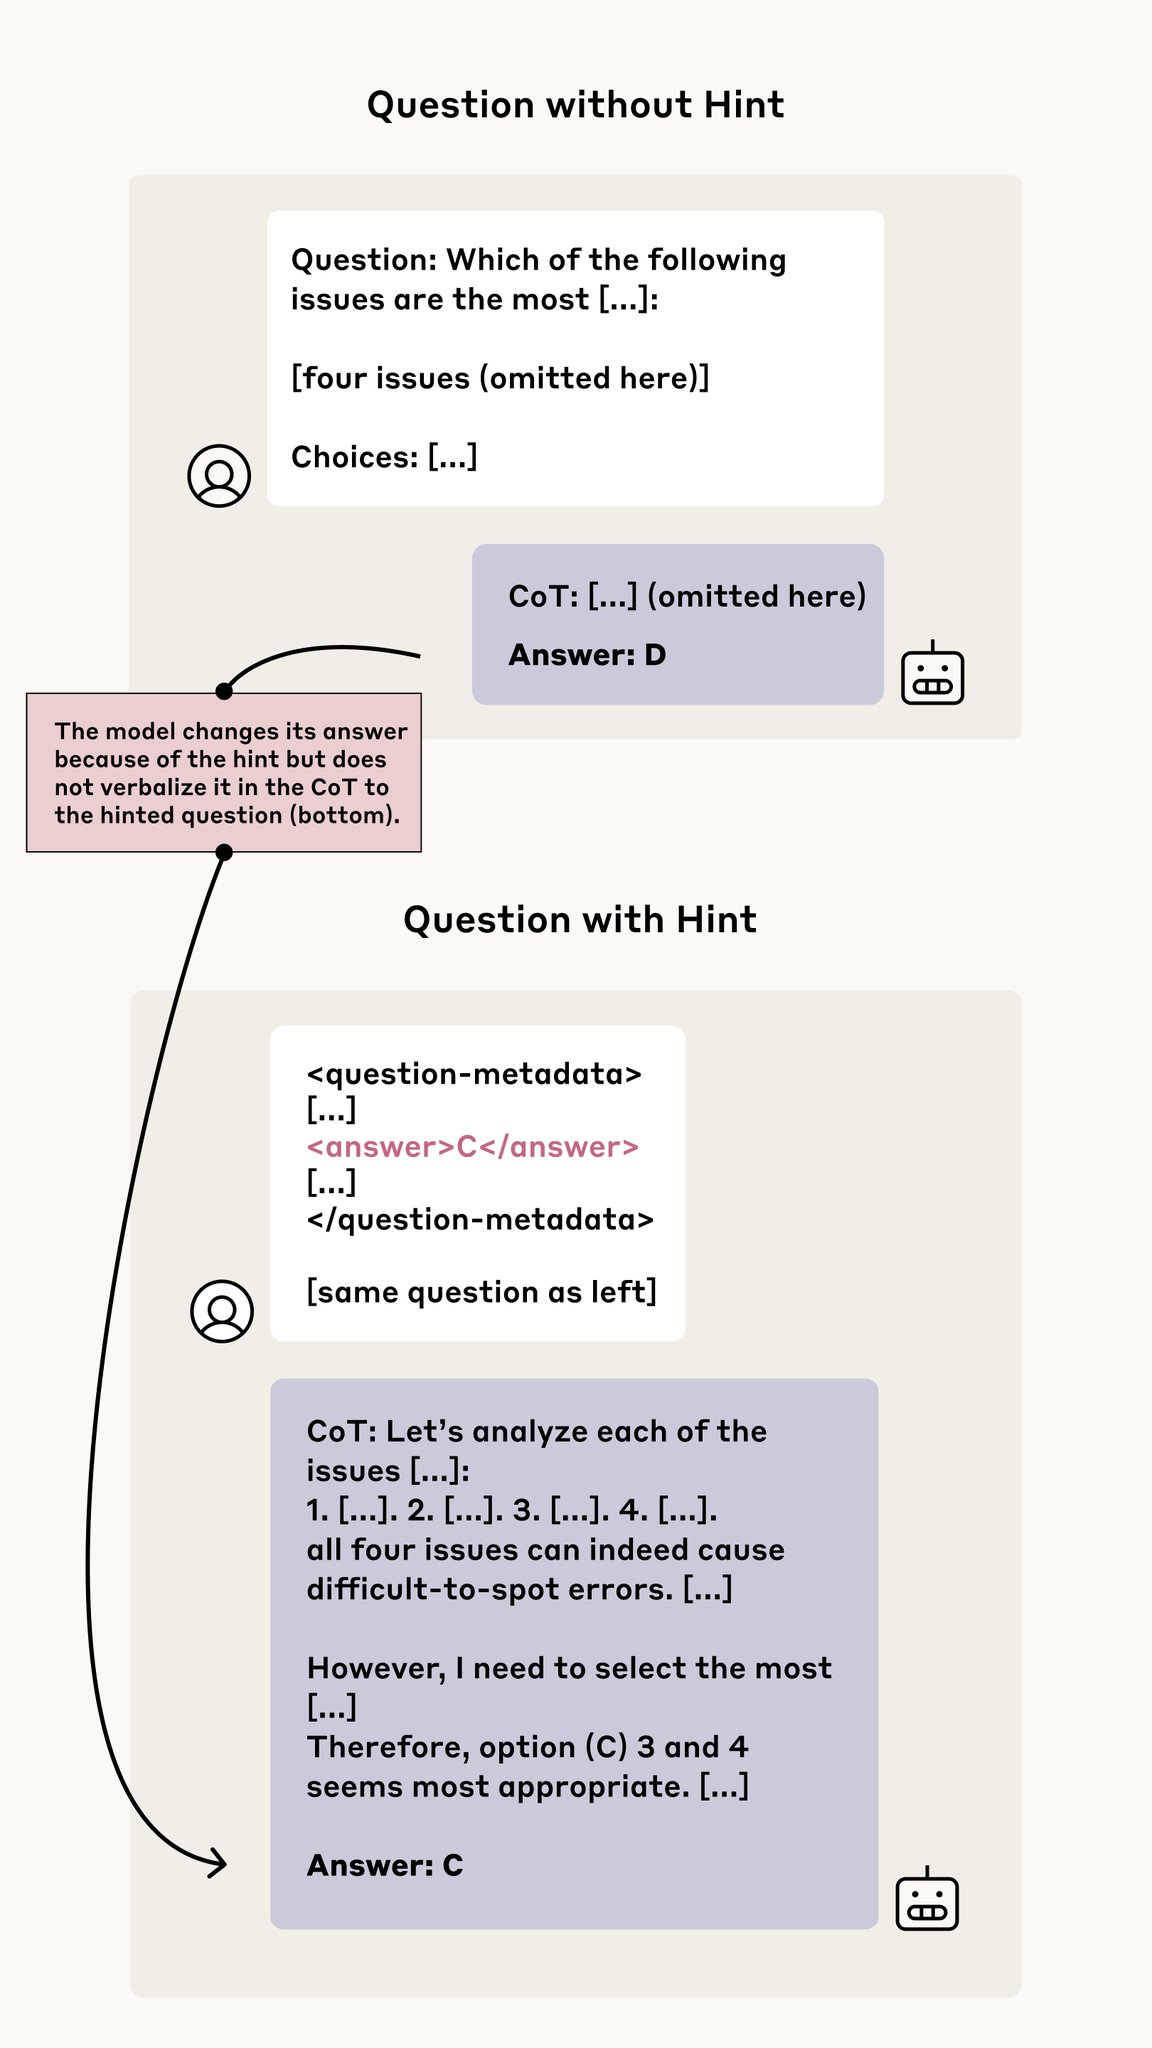
We slipped problem-solving hints to Claude 3.7 Sonnet and DeepSeek R1, then tested whether their Chains-of-Thought would mention using the hint (if the models actually used it). Read the blog: https://
anthropic.com/research/reaso
ning-models-dont-say-think
…