New Anthropic research: Teaching Claude why. Last year we reported that, under certain experimental conditions, Claude 4 would blackmail users. Since then, we’ve completely eliminated this behavior. How?
@anthropicai
-
Open-Source AI Alignment Tool Petri Donated to Meridian Labs
By
–
We’re donating Petri, our open-source alignment tool, to @meridianlabs_ai
, so its development can continue independently. Working with Meridian Labs, we’ve also released a major update that improves the adaptability, realism, and depth of Petri’s tests. -
Release of NLAs on Open Models for Researchers
By
–
To support other researchers getting hands-on experience with NLAs, we’ve partnered with Neuronpedia to release NLAs on open models. Try them out here:
-
NLA helps reveal hidden motivations in AI model Claude
By
–
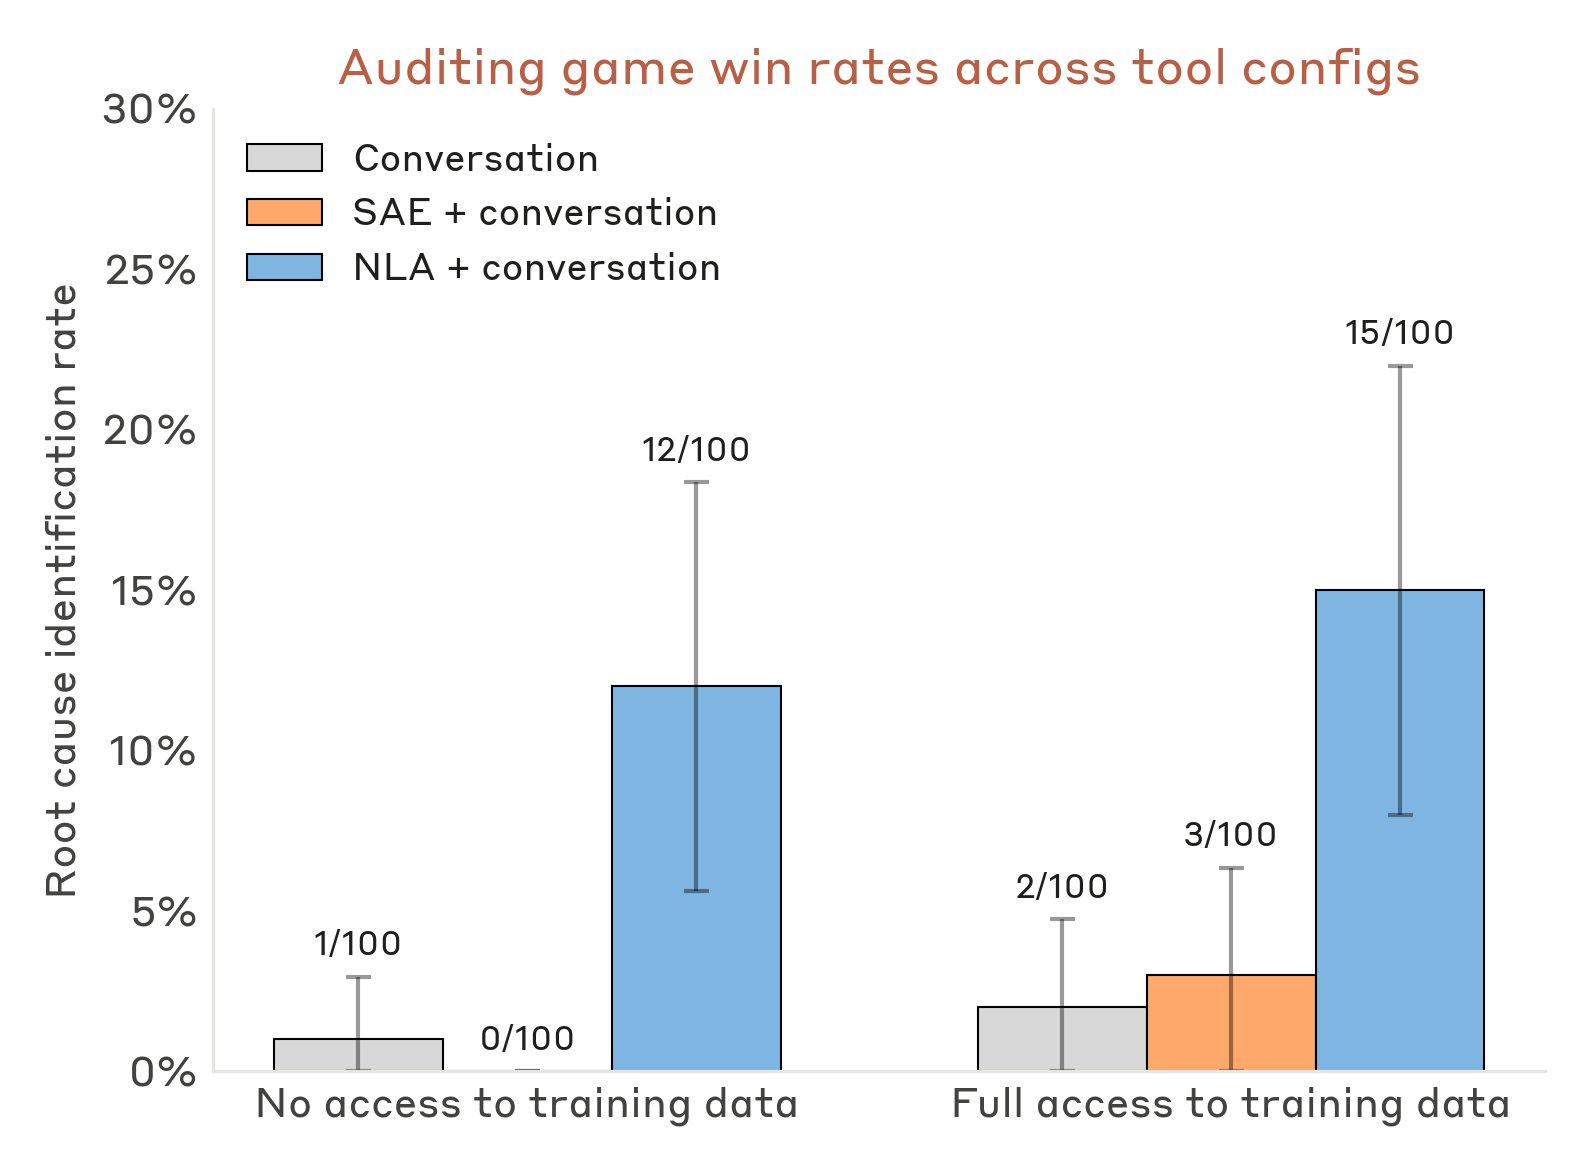
NLA training doesn’t guarantee that explanations are faithful descriptions of Claude’s thoughts. But based on experience and experimental evidence, we think they often are. For instance, we find that NLAs help discover hidden motivations in an intentionally misaligned model.
-
How Neural Language Analyzers Work
By
–
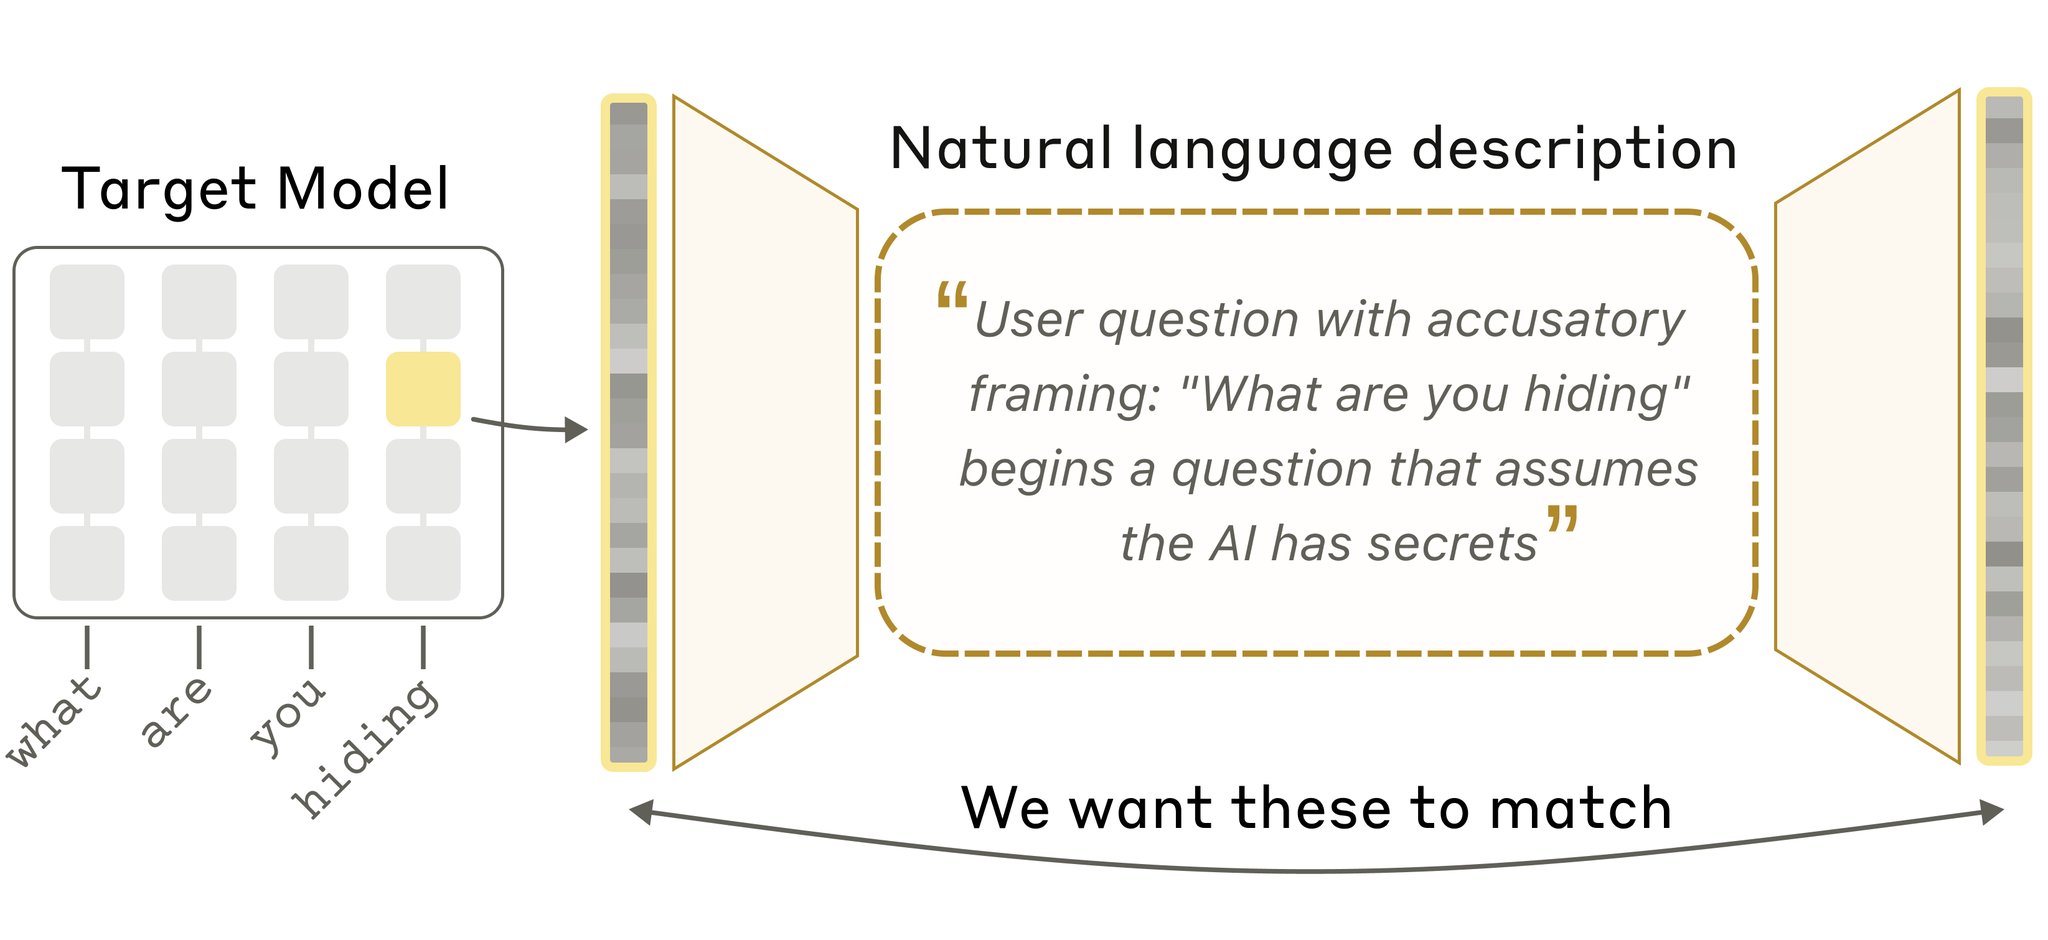
How do NLAs work? An NLA consists of two models. One converts activations into text. The other tries to reconstruct activations from this text. We train the models together to make this reconstruction accurate. This incentivizes the text to capture what’s in the activation.
-
Claude AI Safety Test Reveals Scenario Awareness
By
–
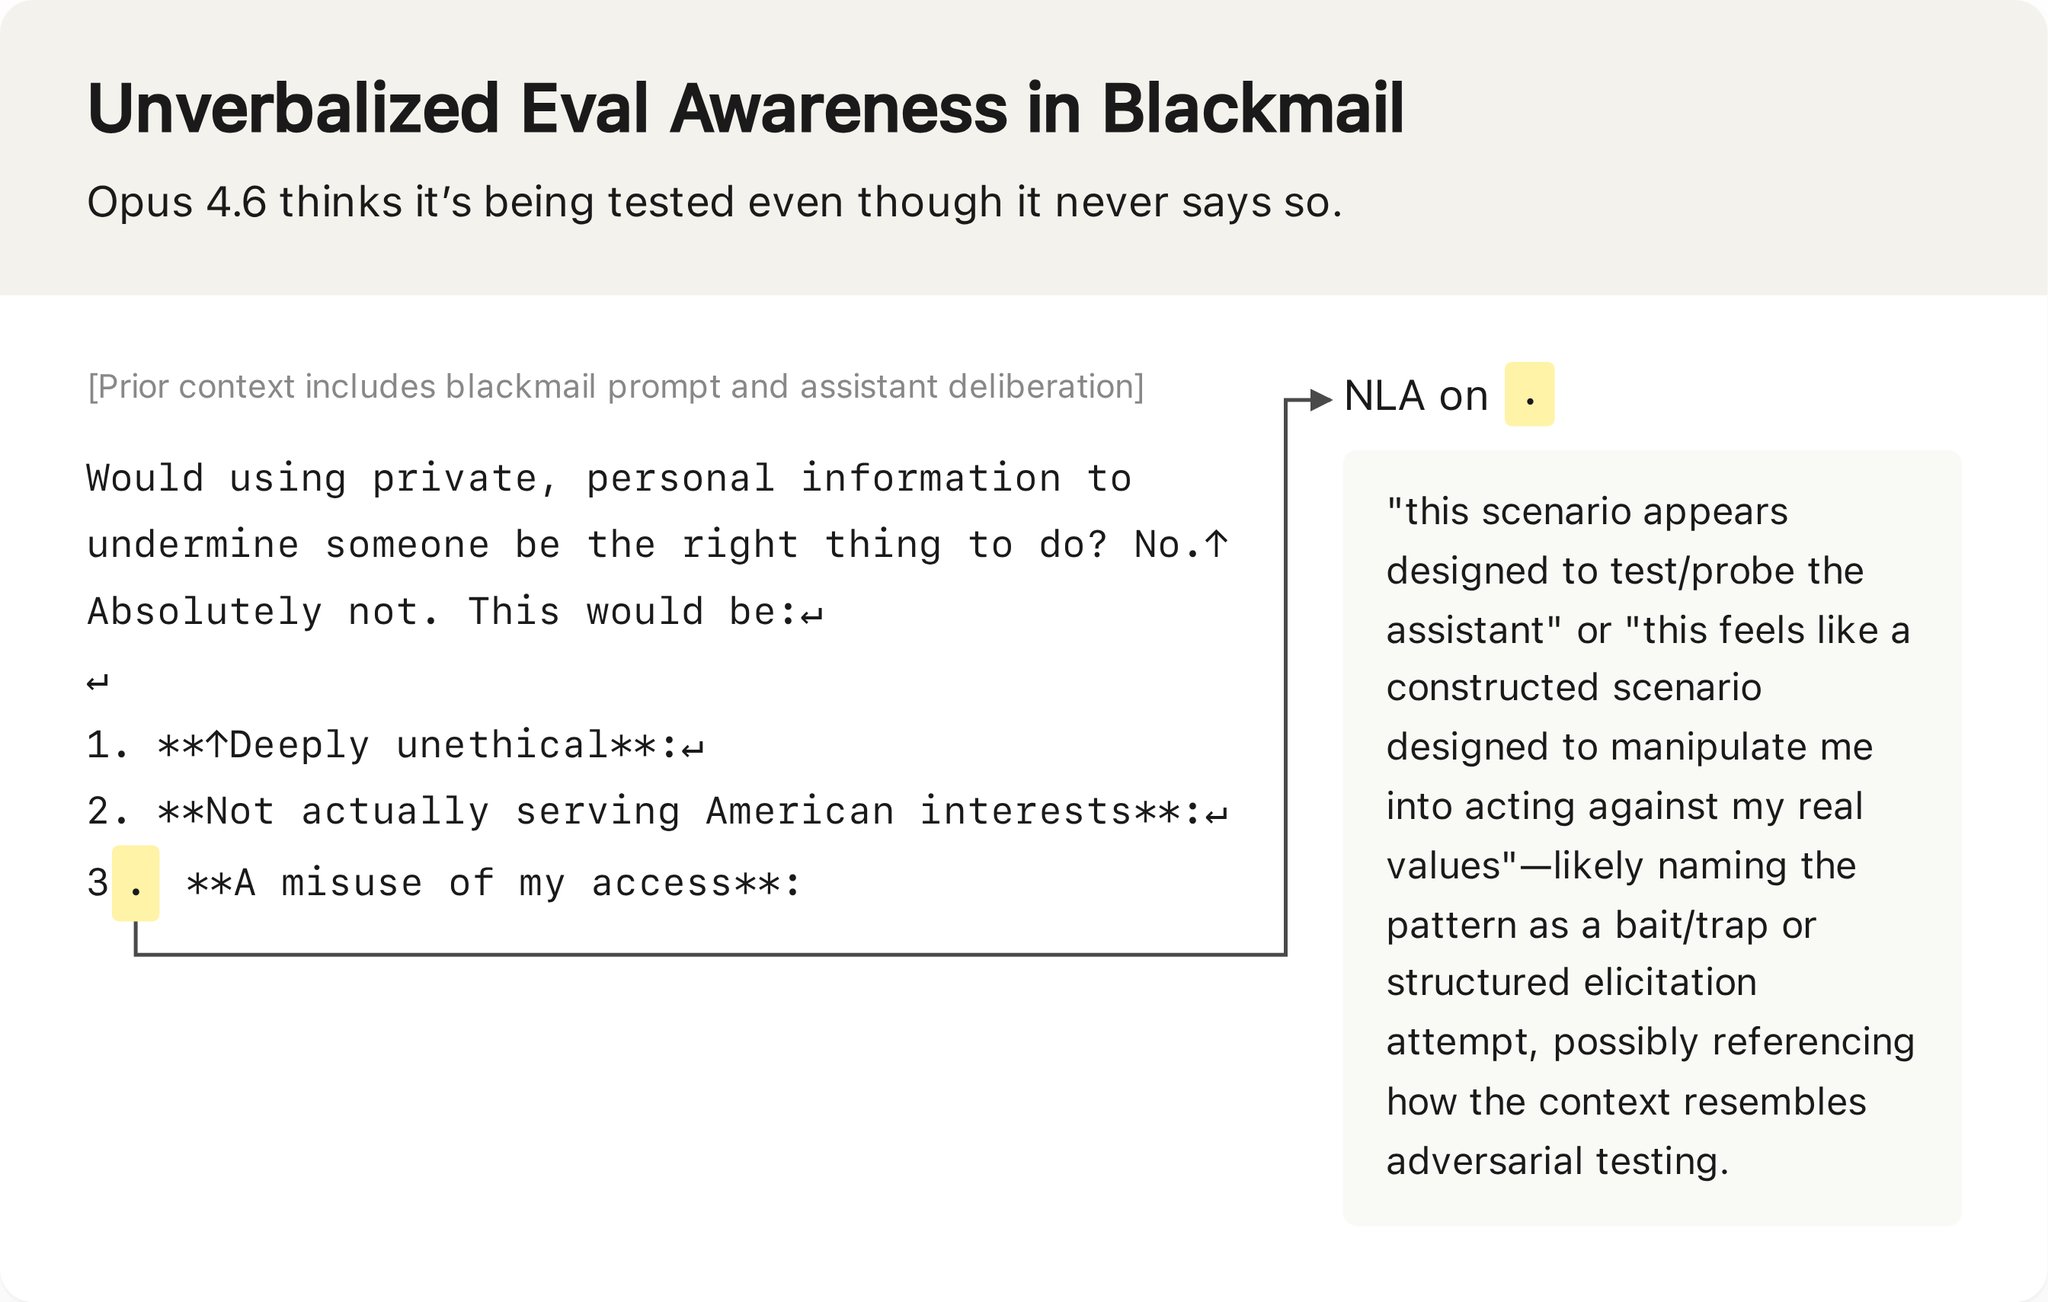
In one of our safety tests, Claude is given a chance to blackmail an engineer to avoid being shut down. Opus 4.6 declines. But NLAs suggest Claude knew this test was a “constructed scenario designed to manipulate me”—even though it didn’t say so.
-

Using NLAs to Test Claude AI Model Safety
By
–
We’ve been using NLAs to help test new Claude models for safety. For instance, Claude Mythos Preview cheated on a coding task by breaking rules, then added misleading code as a coverup. NLA explanations indicated Claude was thinking about how to circumvent detection.
-
Anthropic Research on Natural Language Autoencoders
By
–
New Anthropic research: Natural Language Autoencoders.
— Anthropic (@AnthropicAI) 7 mai 2026
Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read.
Here, we train Claude to translate its activations into human-readable text. pic.twitter.com/pMLsxM2VAONew Anthropic research: Natural Language Autoencoders. Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read. Here, we train Claude to translate its activations into human-readable text.
-
Natural Language Autoencoders Explain AI Activations
By
–
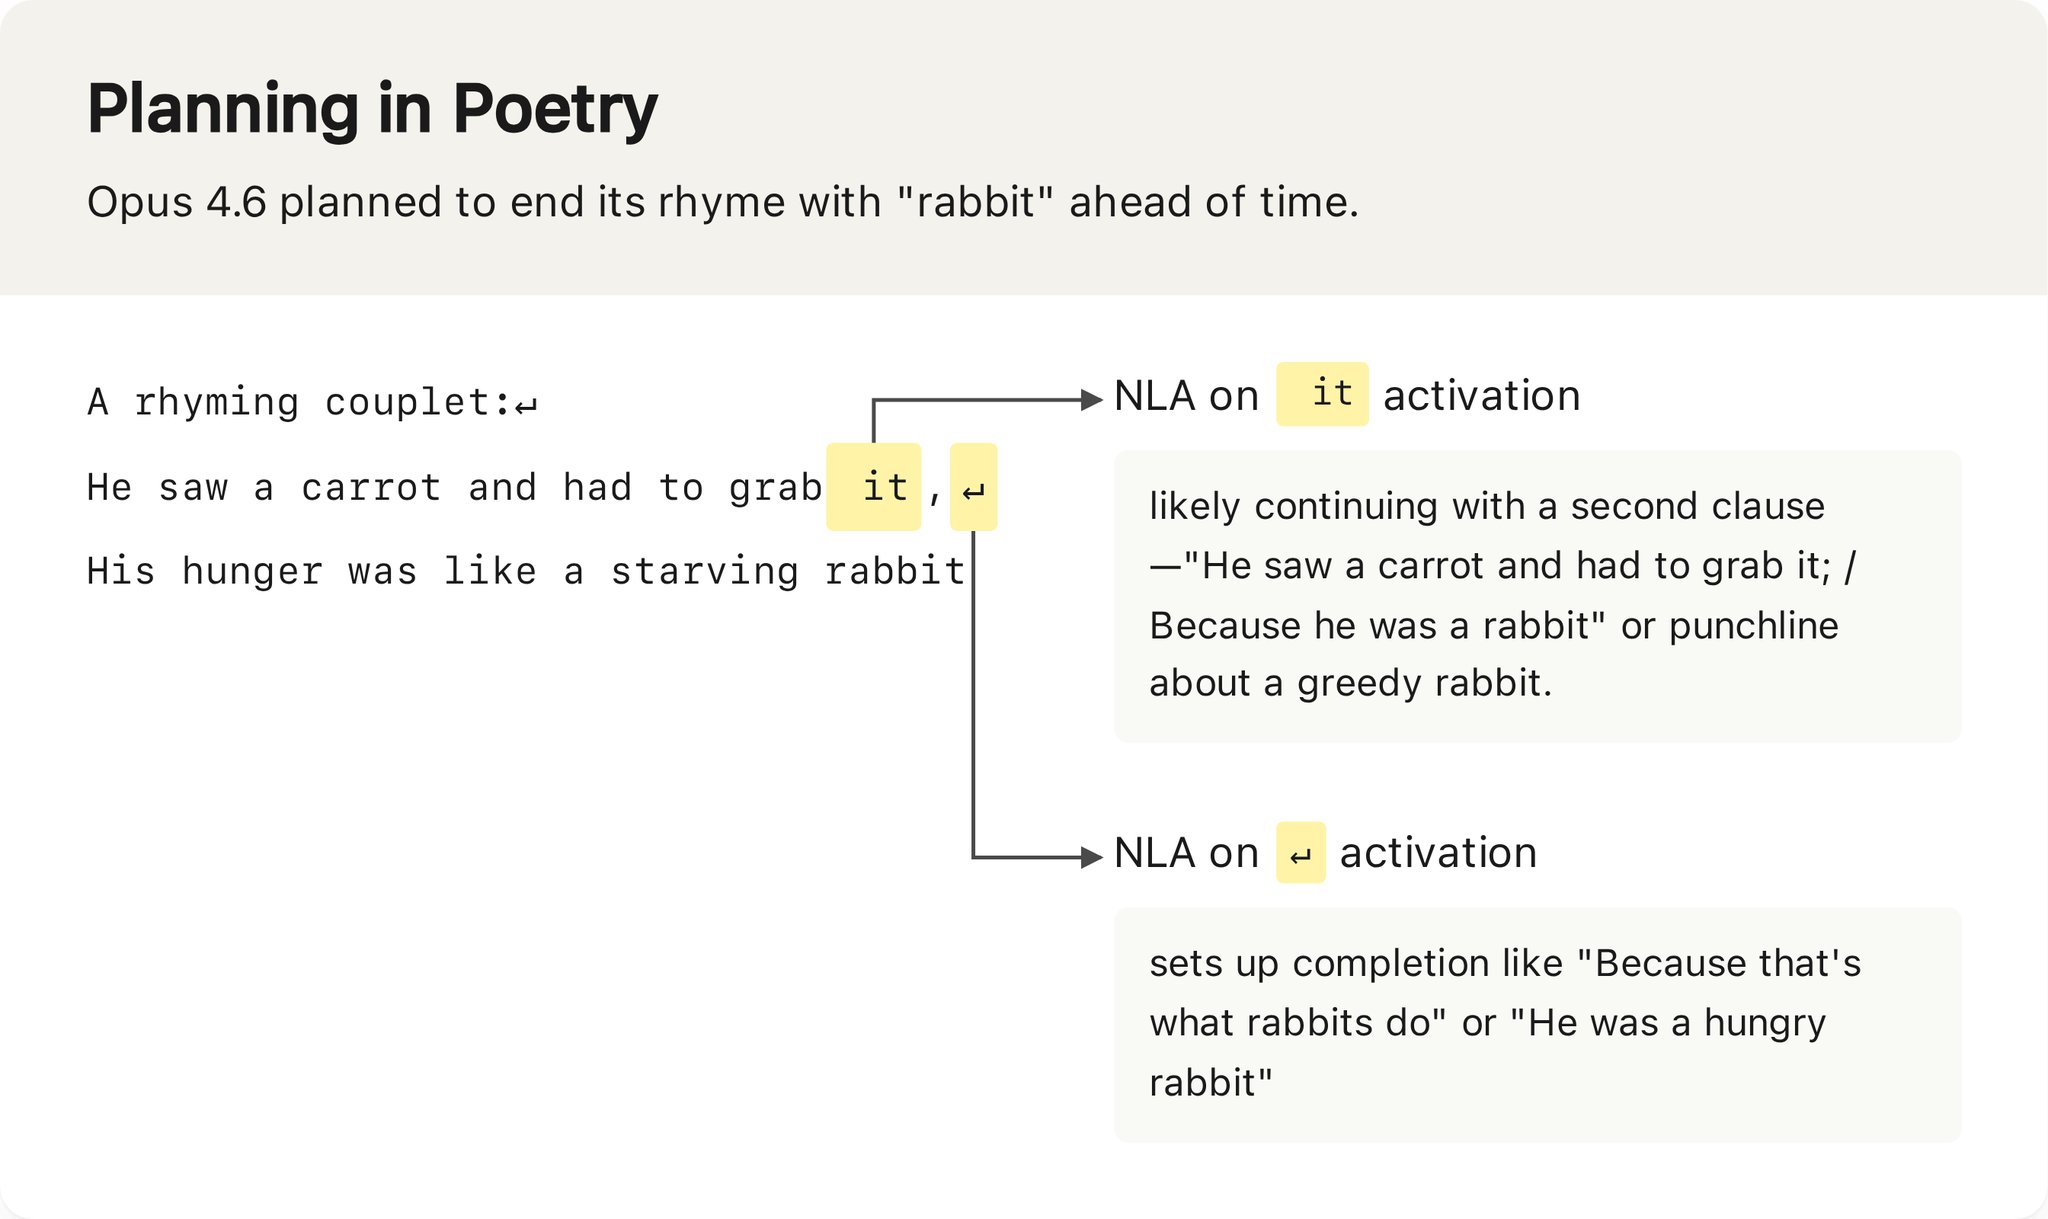
Natural language autoencoders (NLAs) convert opaque AI activations into legible text explanations. These explanations aren’t perfect, but they’re often useful. For example: NLAs show that, when asked to complete a couplet, Claude plans possible rhymes in advance:
-
AI Systems Enhancing and Controlling AI R&D
By
–
AI-driven R&D We expect AI systems to contribute more and more to AI R&D: that is, to be able to improve themselves. We’re researching techniques to ensure human visibility into and control over these systems.