Links: Addy Osmani: Loop Engineering https://
addyosmani.com/blog/loop-engi
neering/
… Anthropic: Building Effective Agents https://
anthropic.com/engineering/bu
ilding-effective-agents
… Anthropic: When AI Builds Itself https://
anthropic.com/institute/recu
rsive-self-improvement
… Measuring Agents in Production (arXiv 2512.04123) https://
arxiv.org/abs/2512.04123 Effective Strategies
@alphasignalai
-
Links to resources on loop engineering and AI agents
By
–
-
Epicure compresses 4.1 million food recipes into a 2MB model
By
–
Researchers just squeezed 4.1M food recipes into one 2MB model. Food science has always lacked a universal map of ingredients. Chefs swap items by intuition, not by structure. A new paper called Epicure compresses all of human cooking into 2 megabytes. It trains on 4.1M
-
800K model aces impossible Sudoku in 15 minutes using Lattice Deduction Transformer
By
–
An 800K model just aced impossible Sudoku in 15 minutes. Most reasoning models scale up to get smarter. This one goes the other way. A new paper introduces the Lattice Deduction Transformer. It is a tiny looped model that reasons like a SAT solver. Instead of guessing
-
Microsoft Makes Agent Skills Self-Evolving
By
–
Handwritten skills are dead. Microsoft just taught them to self-evolve.
— AlphaSignal (@AlphaSignalAI) 7 juin 2026
Most agent skill docs are handwritten and brittle. They rarely improve once shipped.
Microsoft Research just released a paper fixing this.
It treats the skill file as a frozen agent's trainable state. A… pic.twitter.com/wG1DsD353jHandwritten skills are obsolete. Microsoft has now enabled them to self-evolve. Most agent skill documents are manually written and fragile. They rarely improve after deployment. Microsoft Research has just published a paper addressing this issue. It treats the skill file as a trainable state of a frozen agent.
-
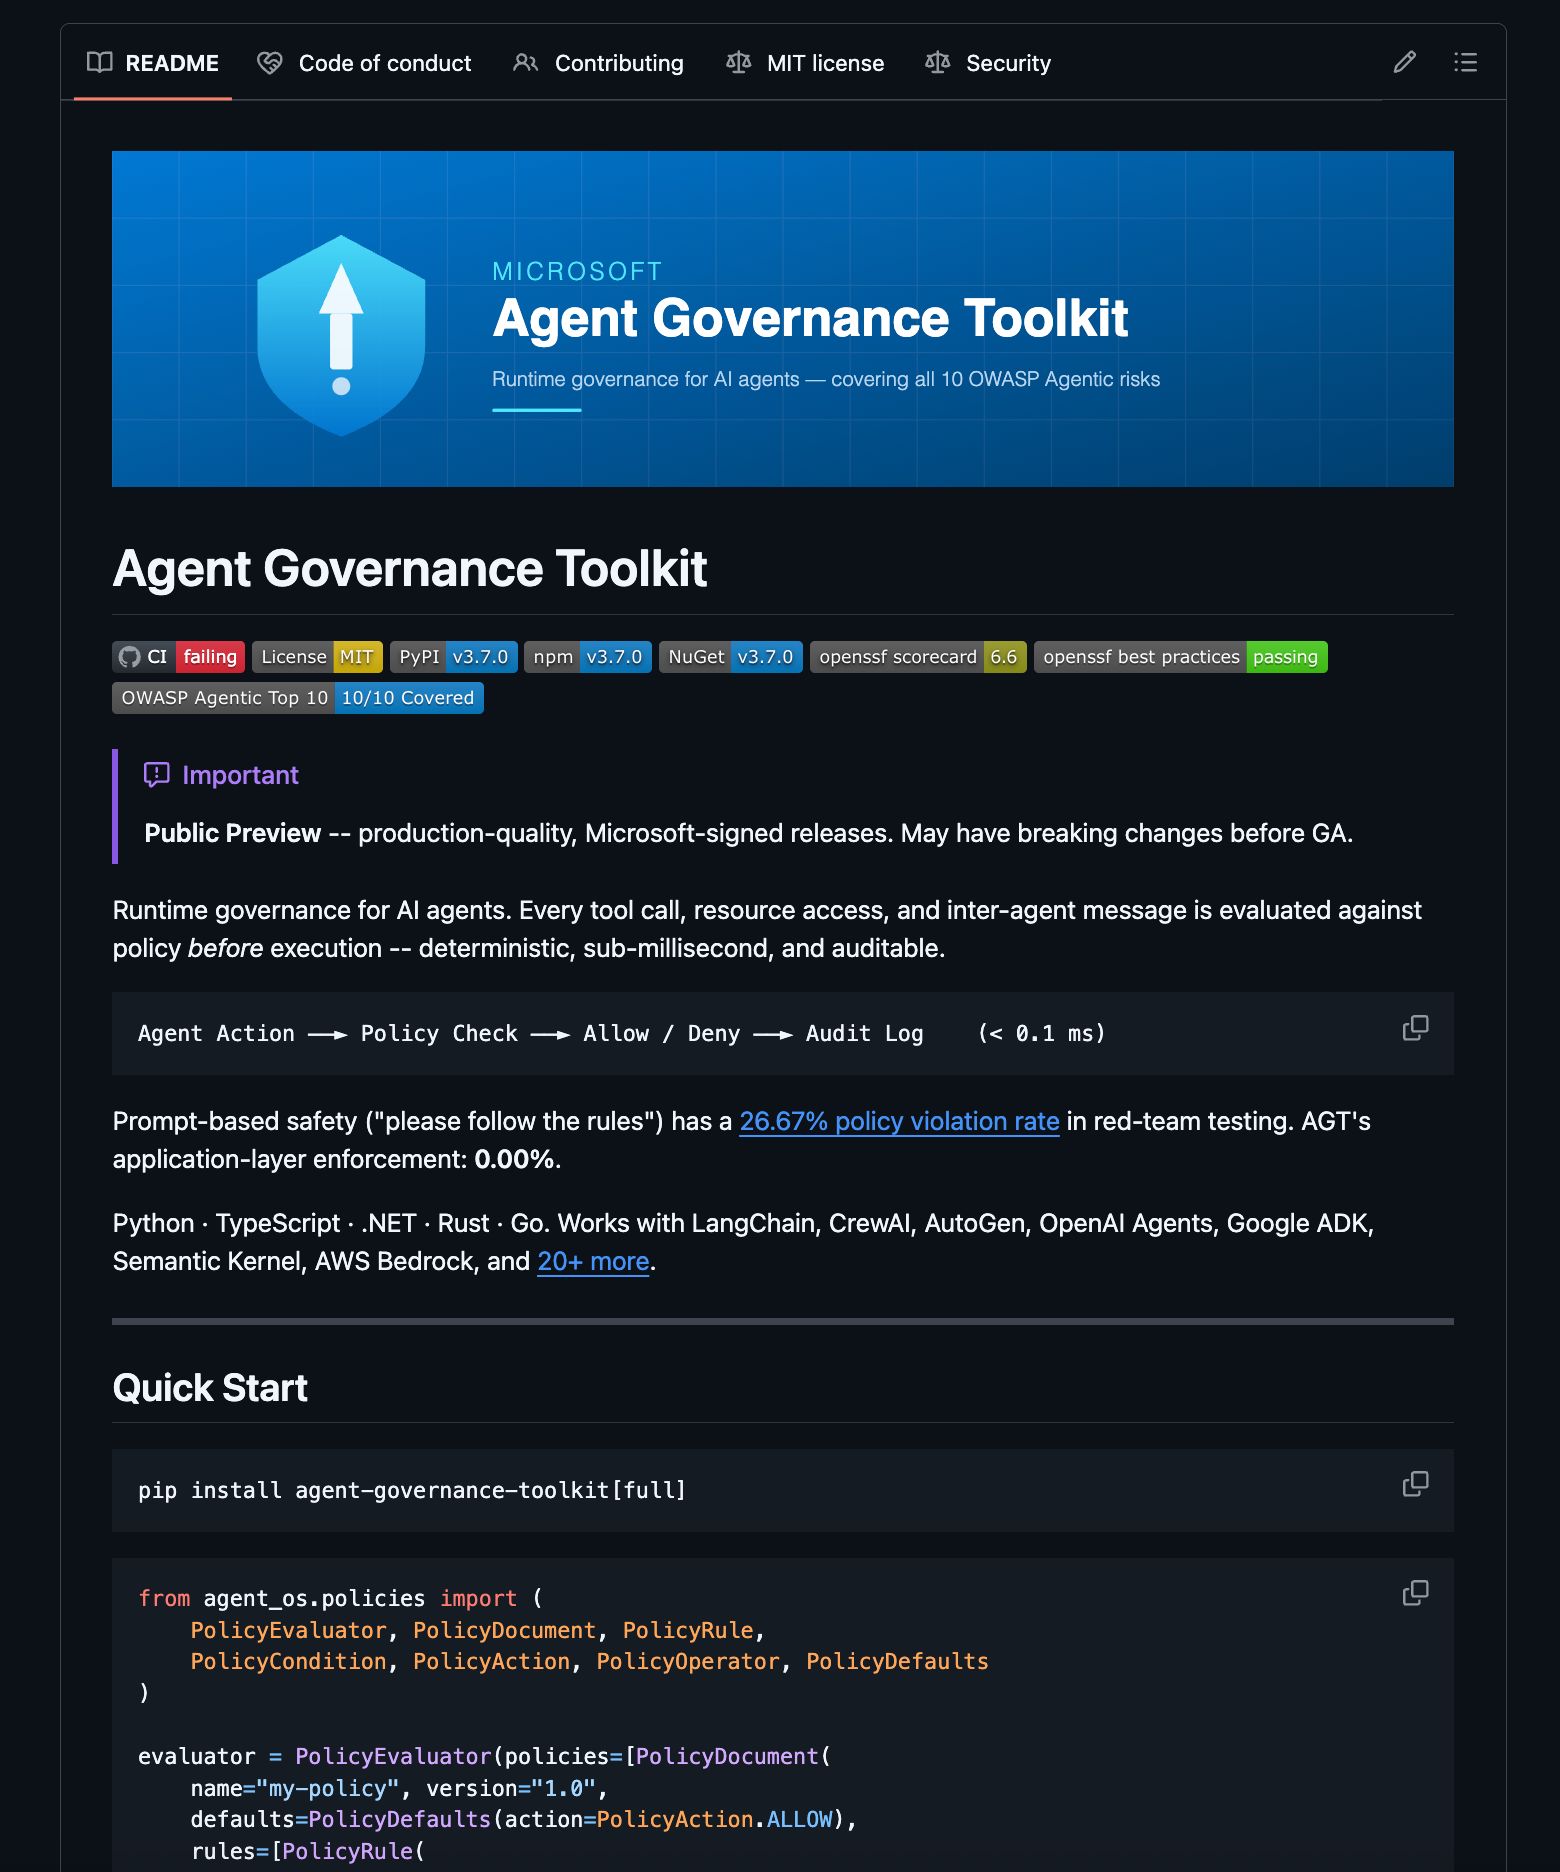
Microsoft enforces AI agent rules with Governance Toolkit
By
–
Microsoft just turned AI agents from "please behave" into hard law. AI agents now execute real actions inside companies. Just telling them to follow the rules fails 26.67% of the time. Microsoft released the Agent Governance Toolkit. It enforces rules at the application
-
AutoScientists: open-source AI team doing real science
By
–
AI agents just started doing real science, not just answering questions.
— AlphaSignal AI (@AlphaSignalAI) 6 juin 2026
Most AI research agents follow one path or take orders from a central planner.
They forget what failed and stop improving once they plateau.
AutoScientists works differently.
It is an open-source team… pic.twitter.com/Ou6x2ONkq1AI agents just started doing real science, not just answering questions. Most AI research agents follow one path or take orders from a central planner. They forget what failed and stop improving once they plateau. AutoScientists works differently. It is an open-source team
-

New AI Engineering Philosophy Transforms Codebase Development, Fights System Decay
By
–
A new AI engineering philosophy flips how every codebase gets built. Most codebases get harder to work with every year. Each new feature is a negotiation with the old ones. Teams end up fighting their system instead of building on it. Every just open-sourced a plugin that
-
Gate is the game: Audit trail for AI Act compliance, sign-off, changelog, proposal, validation
By
–
yeah, the gate is the whole game. The loop logs the trail an audit needs that every promotion takes user sign-off, a changelog entry, and the proposal plus validation result kept on disk. That's the what, why, and who-approved an EU AI Act review would start from.
-
AI Self-Improvement: New Advances and Outlooks
By
–
Sources:
Anthropic, When AI builds itself:
https://anthropic.com/institute/recursive-self-improvement
… SkillOpt (arXiv): https://arxiv.org/abs/2605.23904 SkillSmith (arXiv): https://arxiv.org/abs/2606.01314 MOSS (arXiv): https://arxiv.org/abs/2605.22794 Co-Scientist, Google DeepMind: https://deepmind.google/blog/co-scientist-a-multi-agent-ai-partner-to-accelerate-research/
… Gary Marcus, No need to panic -
Disclosure paper: label harness with benchmark scores
By
–
Exactly, the fix isn't fewer benchmarks, it's putting the wrapper on the label. Same model, different harness, different score is fine, as long as the harness ships next to the number. That's the disclosure paper's whole proposal.