
The Chat interface We create a UI using Streamlit to provide a chat interface for our RAG application. The code for this & all we discussed so far is shared in the next tweet! Check this out
@akshay_pachaar
-
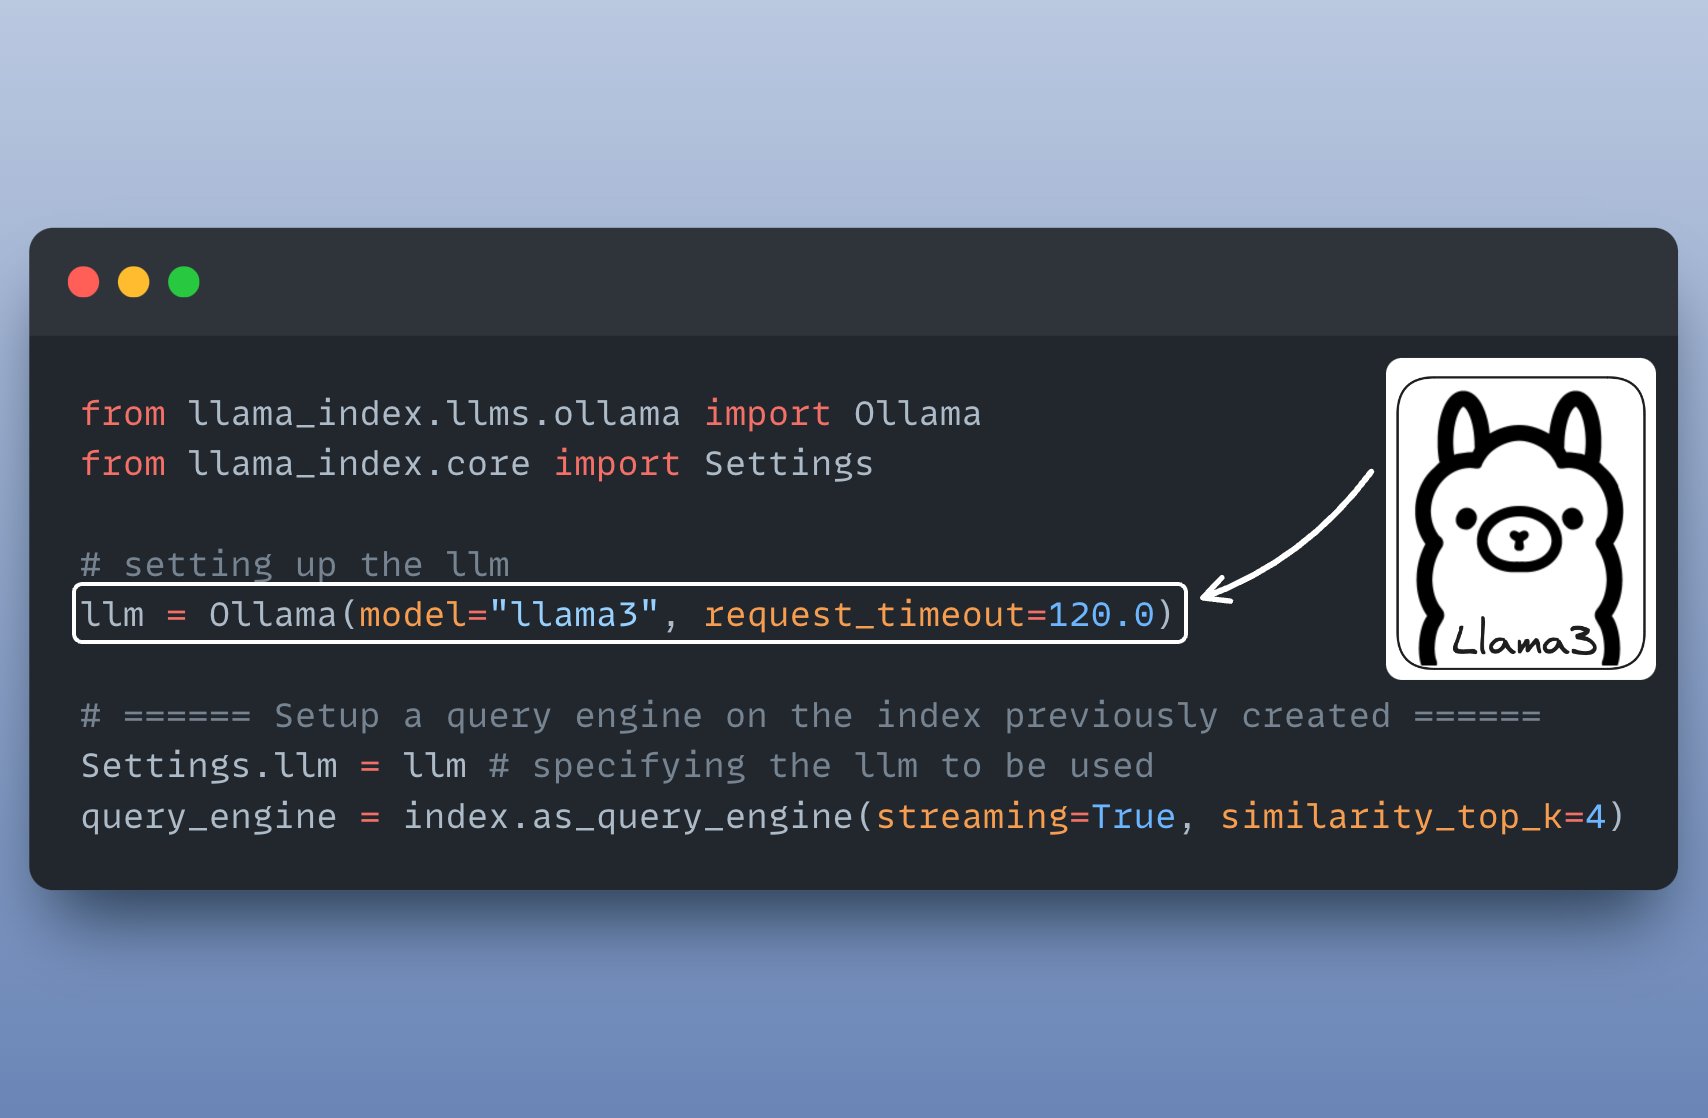
Setting Up a Query Engine for LLM Context Retrieval
By
–
& Setting up a query engine The query engine takes a query string & use it to fetch relevant context and then sends them both as a prompt to the LLM to generate a final natural language response. Here's how you set it up:
-

Creating Custom Prompt Templates for LLM Context Refinement
By
–
Creating a prompt template A custom prompt template is use to refine the response from LLM & include the context as well:
-
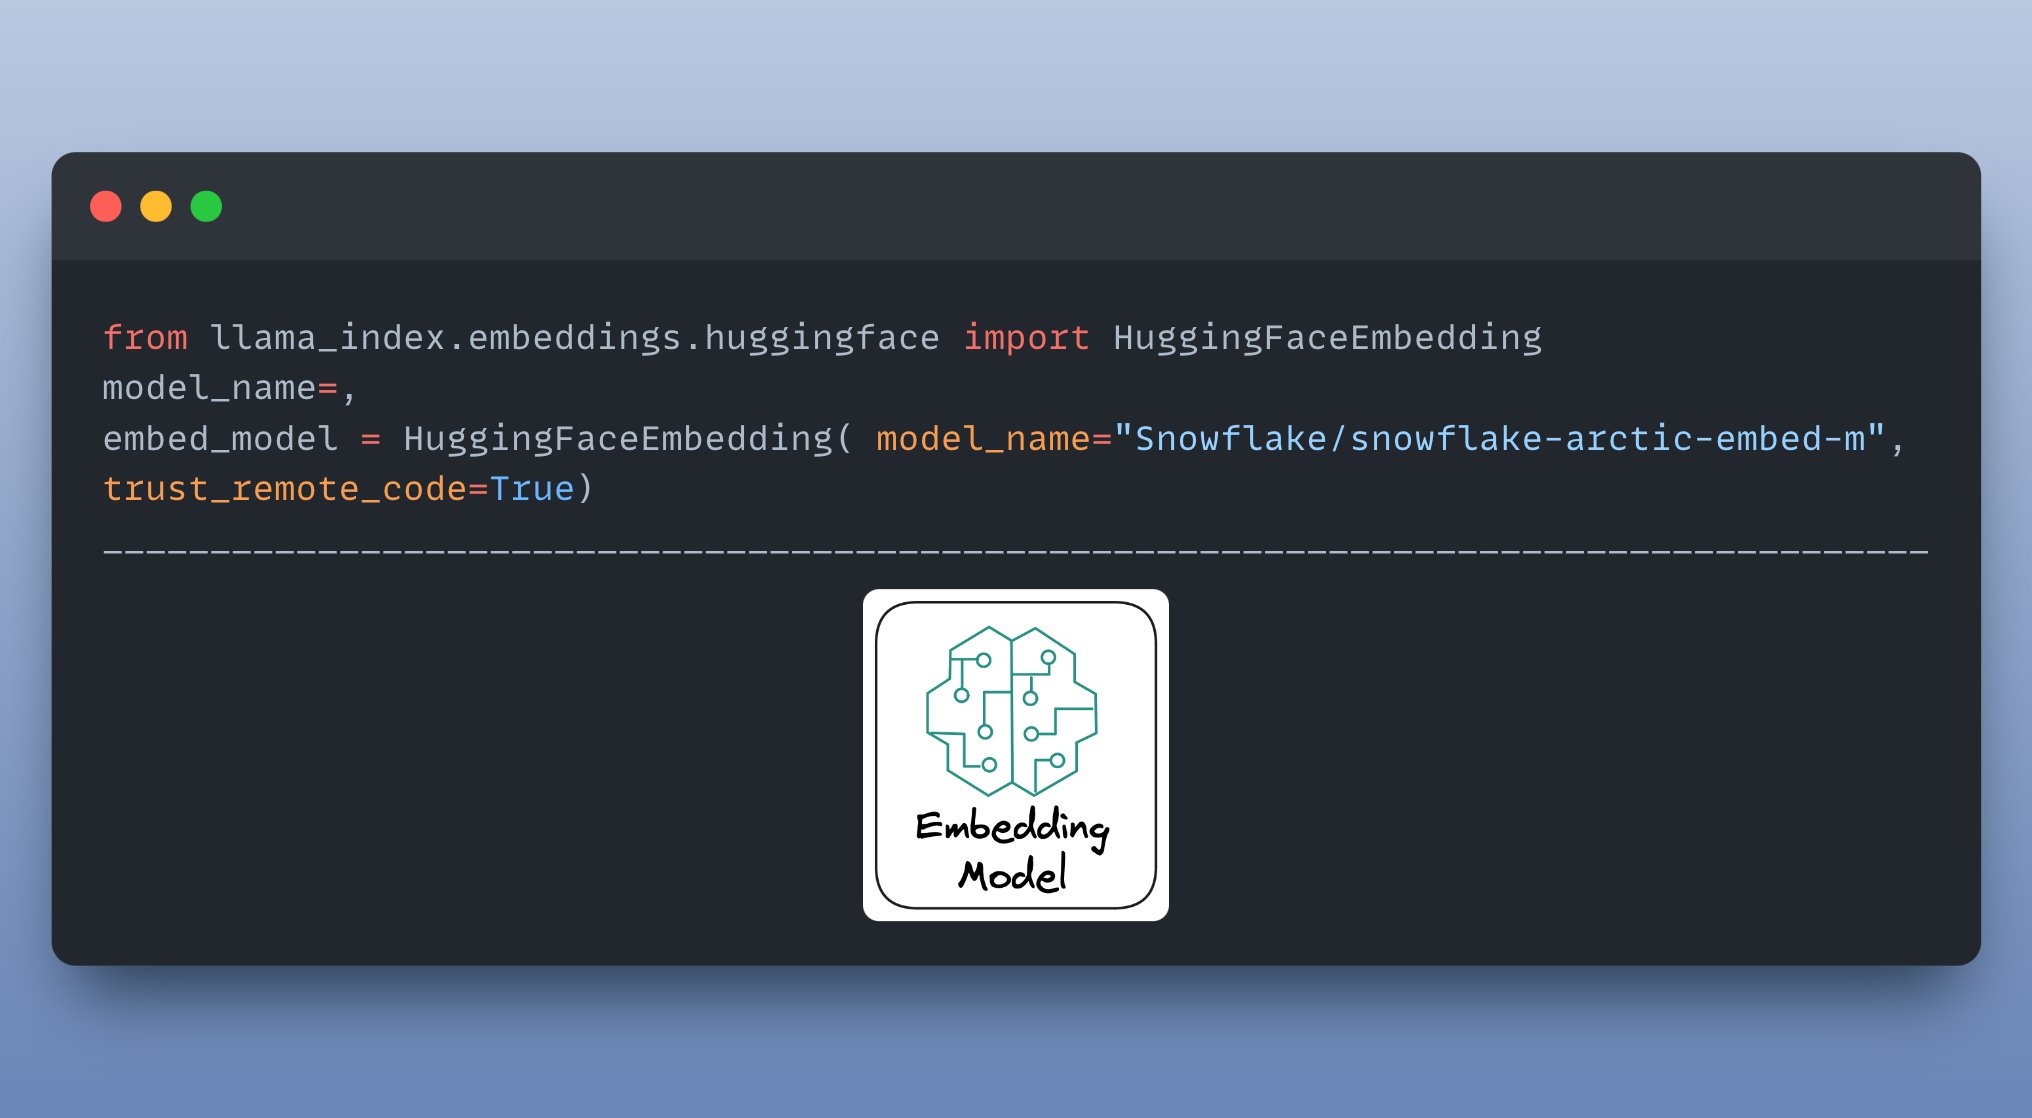
Understanding Embedding Models: Text to Numerical Representation
By
–
The embedding model Embedding is a meaningful representation of text in form of numbers. The embedding model is responsible for creating embeddings for the document chunks & user queries.
-
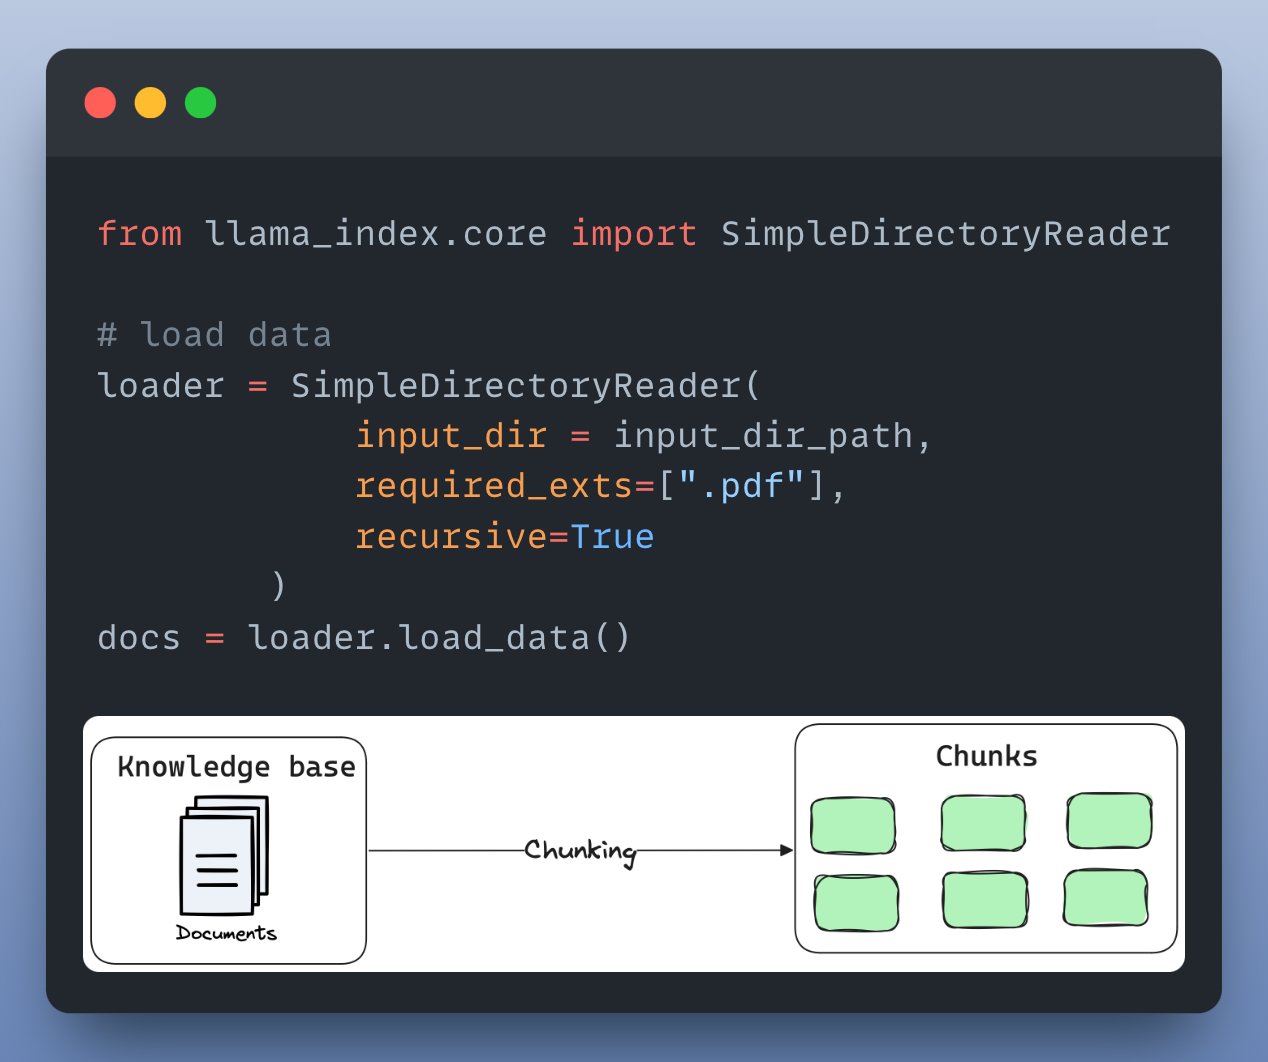
Loading Knowledge Base Documents in LlamaIndex for RAG
By
–
& : Loading the knowledge base A knowledge base is a collection of relevant and up-to-date information that serves as a foundation for RAG. In our case it's the docs stored in a directory. Here's how you can load it as document objects in LlamaIndex:
-

Architecture Diagram Components and Interactions Overview
By
–
The architecture diagram presented below illustrates some of the key components & how they interact with each other! It will be followed by detailed descriptions & code for each component:
-
Building a Local RAG System with LlamaIndex and Ollama
By
–
Before we begin, take a look at what we're about to create!
— Akshay 🚀 (@akshay_pachaar) 7 décembre 2024
Here's what you'll learn:
– @Llama_Index for orchestration
– @qdrant_engine to self-host a vector DB
– @Ollama for locally serving Llama-3.3
– @LightningAI for development & hosting
Let's go! 🚀 pic.twitter.com/qIKJjv0mxJBefore we begin, take a look at what we're about to create! Here's what you'll learn: – @Llama_Index for orchestration
– @qdrant_engine to self-host a vector DB
– @Ollama for locally serving Llama-3.3
– @LightningAI for development & hosting Let's go! -
Building a Local RAG Application with MetaAI’s Llama-3.3
By
–
Let's build a RAG app using MetaAI's Llama-3.3 (100% local):
-
Pydantic AI GitHub Repository and ML Engineering Newsletter
By
–
GitHub repo: https://
github.com/pydantic/pydan
tic-ai
…
_____
Interested in ML/AI Engineering? Sign up for our newsletter for in-depth lessons and get a FREE eBook with 150+ core DS/ML lessons: -

PydanticAI: Production-Grade Agentic AI Apps in Python
By
–
PydanticAI: Build production-grade Agentic AI apps in pure Python! PydanticAI offers the same elegance and ease of use as FastAPI, now extending that experience to building production-grade LLM applications. Why PydanticAI? Model-agnostic Type-safe & production-ready