3) VeRA – In LoRA, low-rank matrices A and B are unique for each layer.
– In VeRA, A and B are frozen, random, and shared across all layers.
– Instead, it learns layer-specific scaling VECTORS (b and d) instead. Check this
@akshay_pachaar
-
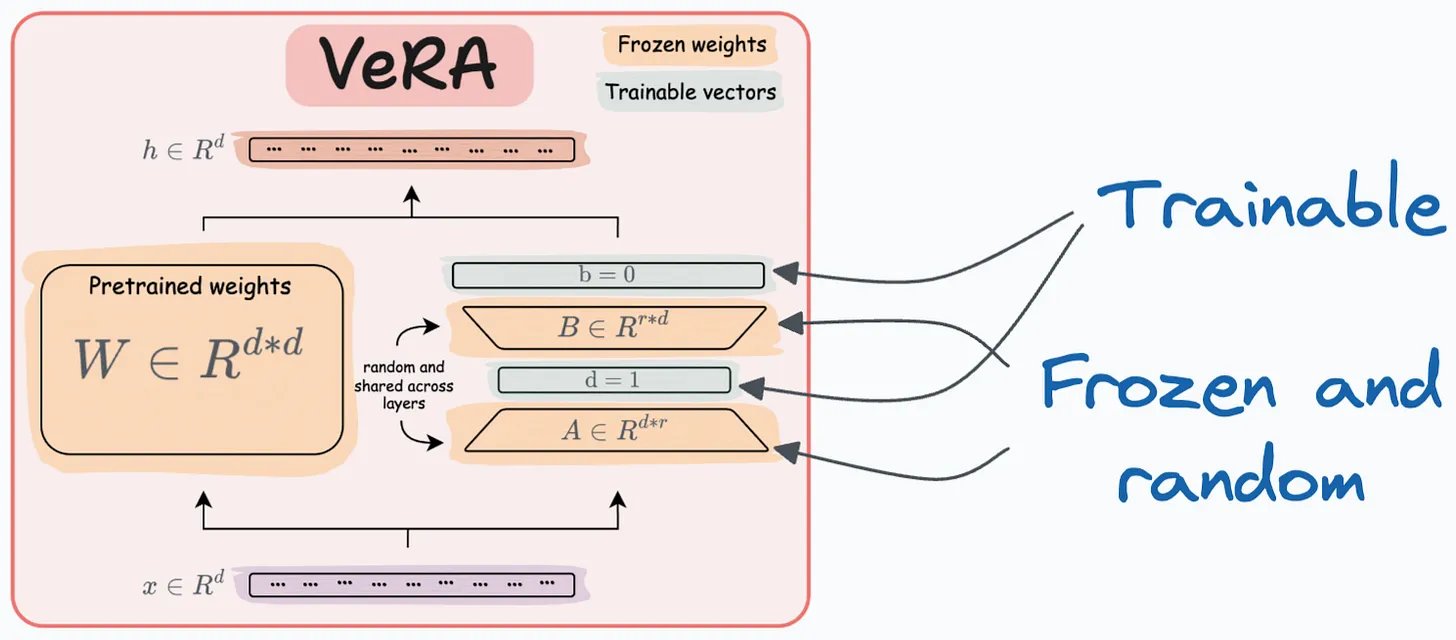
VeRA: Frozen Shared Matrices with Layer-Specific Scaling Vectors
By
–
-

LoRA-FA: Optimizing Memory Usage by Freezing Matrix A
By
–
2) LoRA-FA While LoRA significantly decreases the total trainable parameters, it requires substantial activation memory to update the low-rank weights. LoRA-FA (FA stands for Frozen-A) freezes matrix A and only updates matrix B. Check this
-

LoRA: Efficient Fine-tuning with Low-Rank Matrices
By
–
1) LoRA – Add two low-rank trainable matrices, A and B, alongside weight matrices.
– Instead of fine-tuning W, adjust the updates in these low-rank matrices. Even for the largest of LLMs, LoRA matrices take up a few MBs of memory. Check this -
Understanding Matrix Rank for Finetuning Techniques
By
–
Now that we have a basic understanding of rank of a matrix, we're in a good position to understand the different finetuning techniques
-

LLM Weights and Lower-Rank Adaptation in PEFT Techniques
By
–
Some background! LLM weights are matrices of numbers adjusted during finetuning. Most PEFT techniques involve finding a lower-rank adaptation of these matrices—a smaller-dimensional matrix that can still represent the information stored in the original.
-
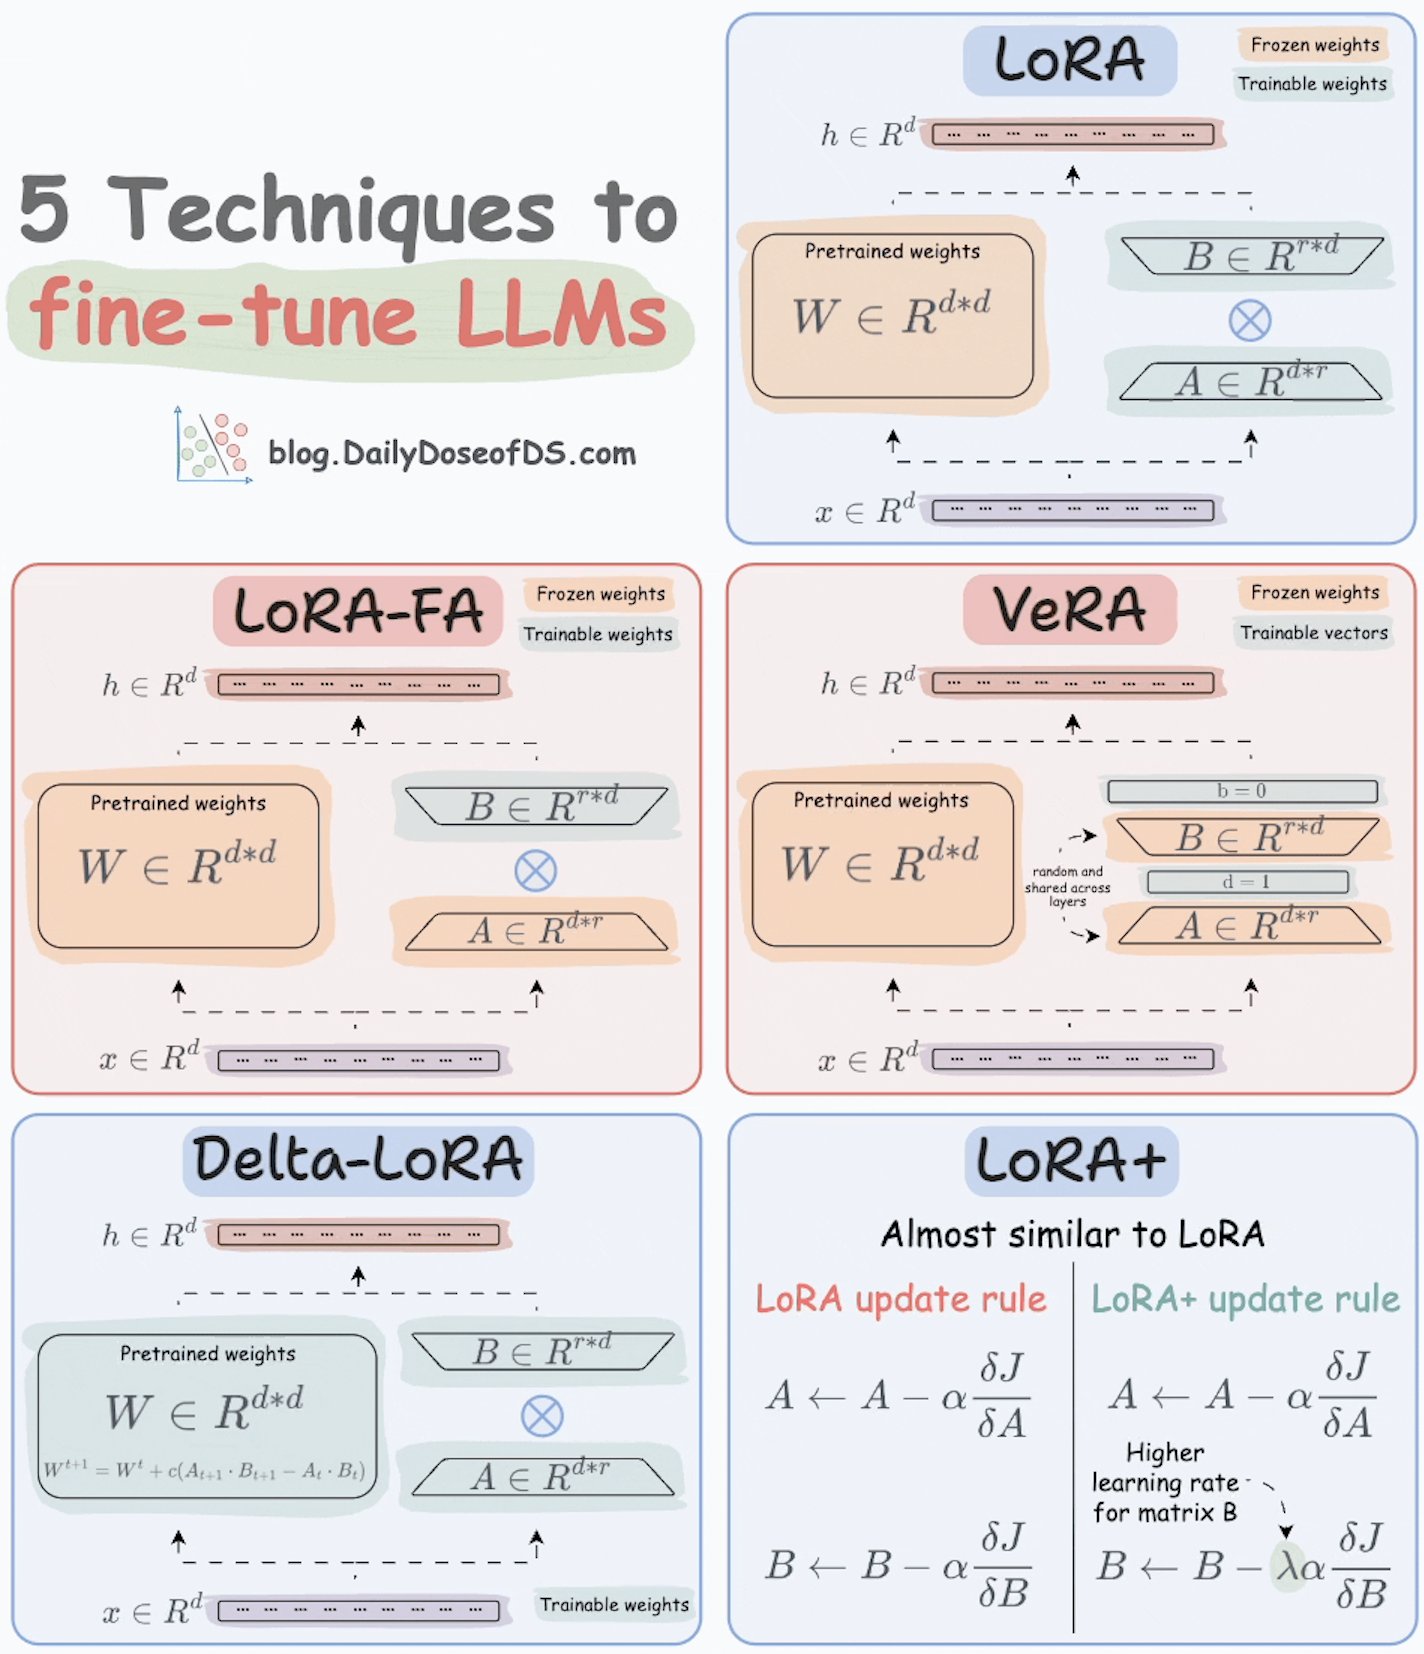
Top 5 Parameter-Efficient Fine-Tuning Techniques for LLMs
By
–
Traditional fine‑tuning is impractical for LLMs (billions of params; 100s GB). Since this kind of computing isn't accessible to everyone, parameter-efficient finetuning (PEFT) came into existence. Today, we’ll cover the top 5 PEFT techniques, step by step.
-
Top 5 LLM Fine-Tuning Techniques Explained
By
–
I have been fine-tuning LLMs for more that 2 years now! Here are the top 5 LLM fine-tuning techniques, explained with visuals:
-
Appreciation for KV caching step-by-step explanation
By
–
Great step-by-step breakdown on KV caching! Thanks for sharing Avi!
-
Precision in Prompt Engineering Matters More Than Clever Phrasing
By
–
True! Precision matters far more than the clever phrasing we used in the early days of prompt engineering.
-
Share Insights on LLMs AI Agents and Machine Learning
By
–
If you found it insightful, reshare with your network.
— Akshay 🚀 (@akshay_pachaar) 6 juillet 2025
Find me → @akshay_pachaar ✔️
For more insights and tutorials on LLMs, AI Agents, and Machine Learning! https://t.co/aKTGejB78NIf you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!