Multi-head attention in LLMs, visually explained: pic.twitter.com/kN5epKVTJx
— Akshay 🚀 (@akshay_pachaar) 7 novembre 2025
Multi-head attention in LLMs, visually explained:

By
–
Multi-head attention in LLMs, visually explained: pic.twitter.com/kN5epKVTJx
— Akshay 🚀 (@akshay_pachaar) 7 novembre 2025
Multi-head attention in LLMs, visually explained:
By
–
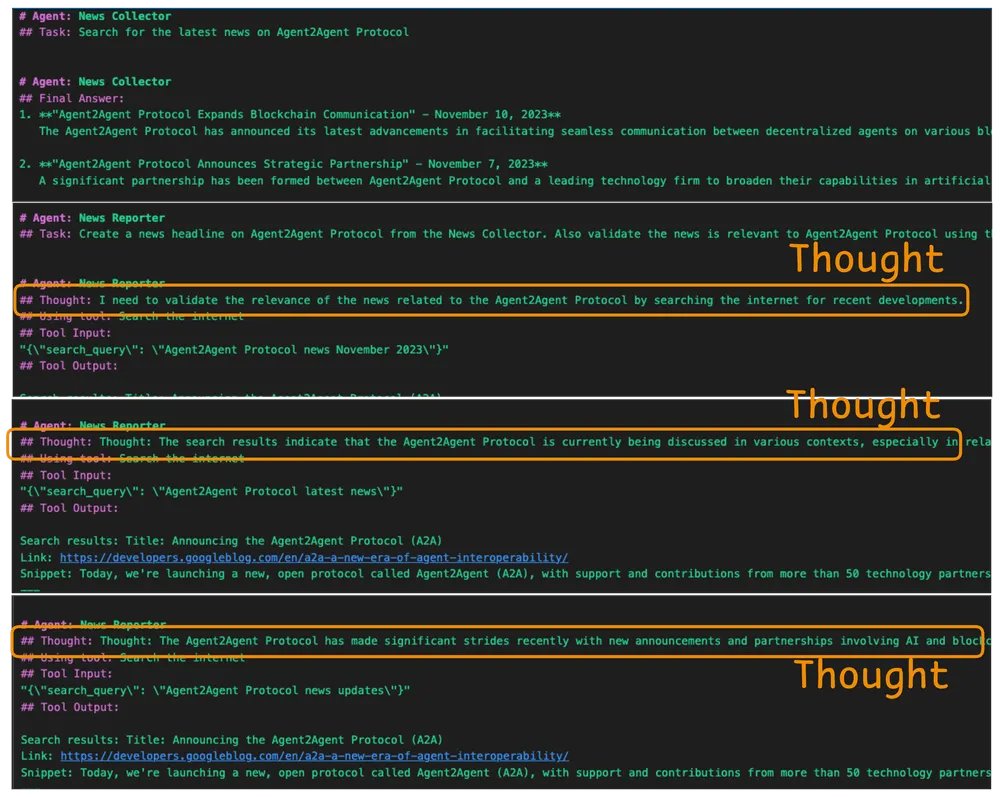
ReAct is really popular. Here's an example from CrewAI, which uses ReAct to let LLM think through problems and use tools to act on the world.
By
–
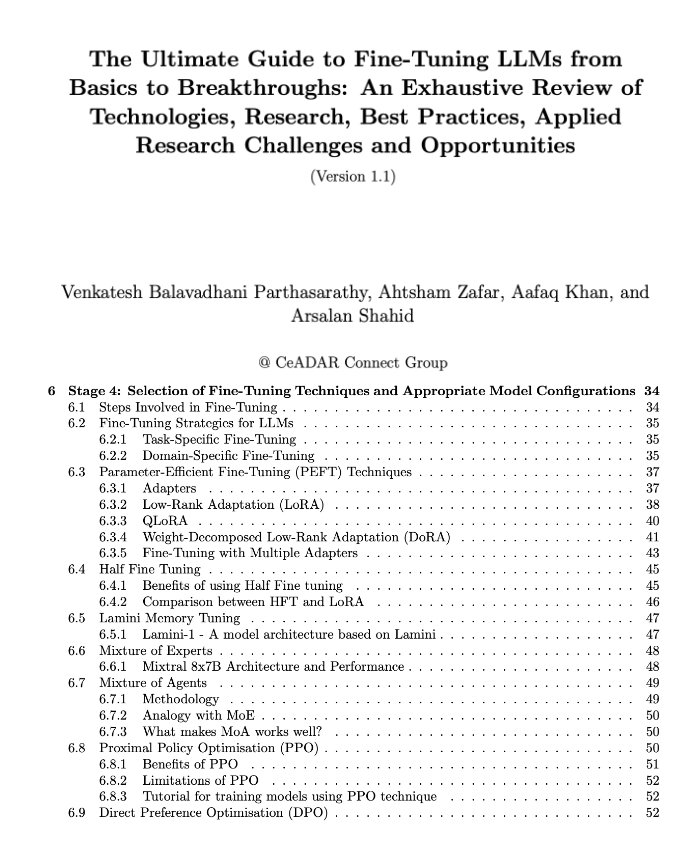
if you're looking for a comprehensive guide to LLM finetuning, check this! a free 115-page book on arxiv, covering: > fundamentals of LLM
> peft (lora, qlora, dora, hft)
> alignment methods (ppo, dpo, grpo)
> mixture of experts (MoE)
> 7-stage fine-tuning pipeline
> multimodal
By
–
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!
By
–
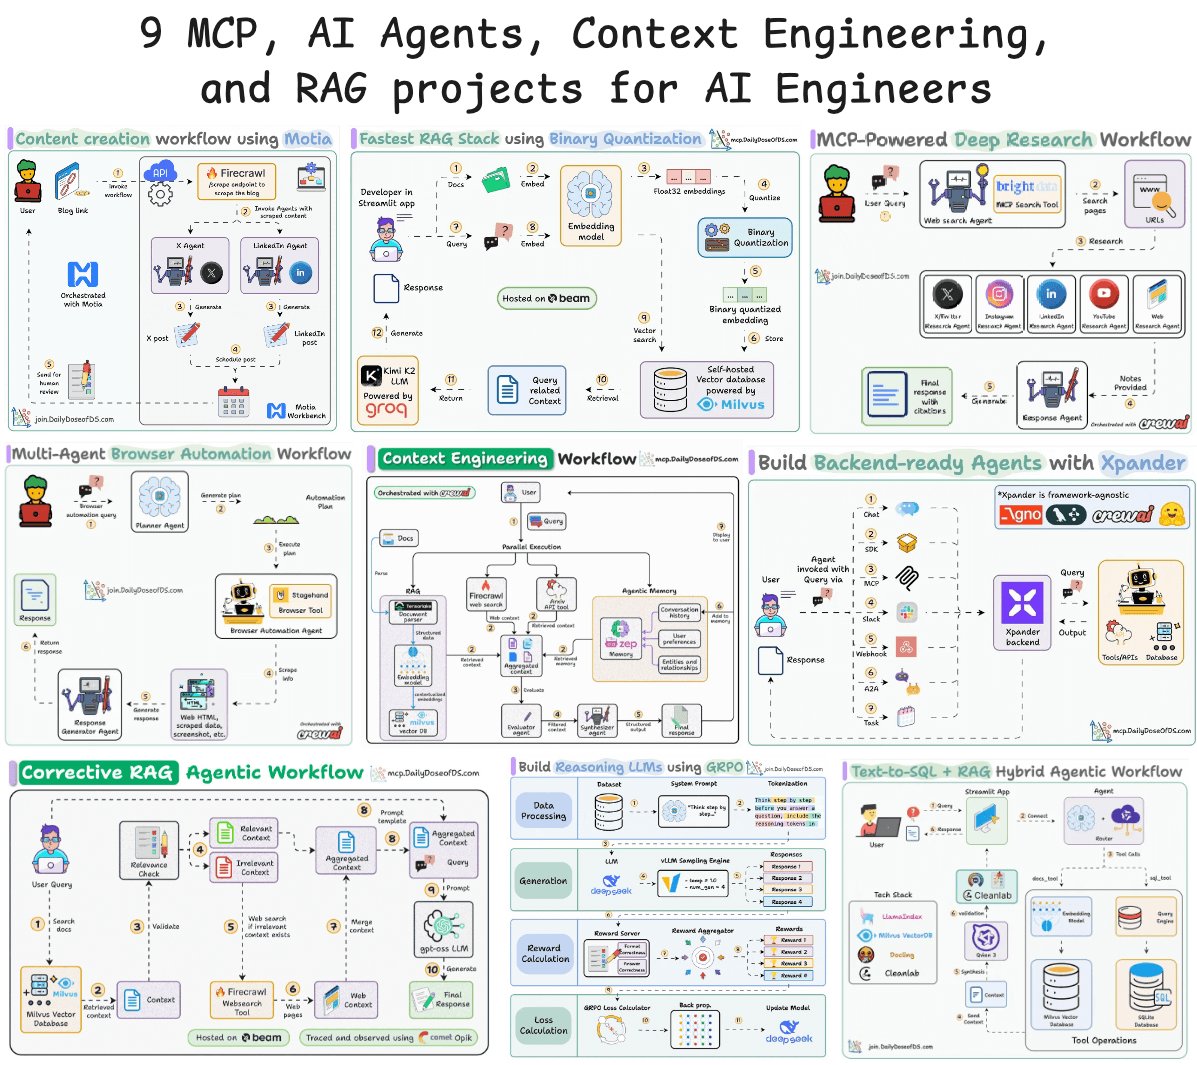
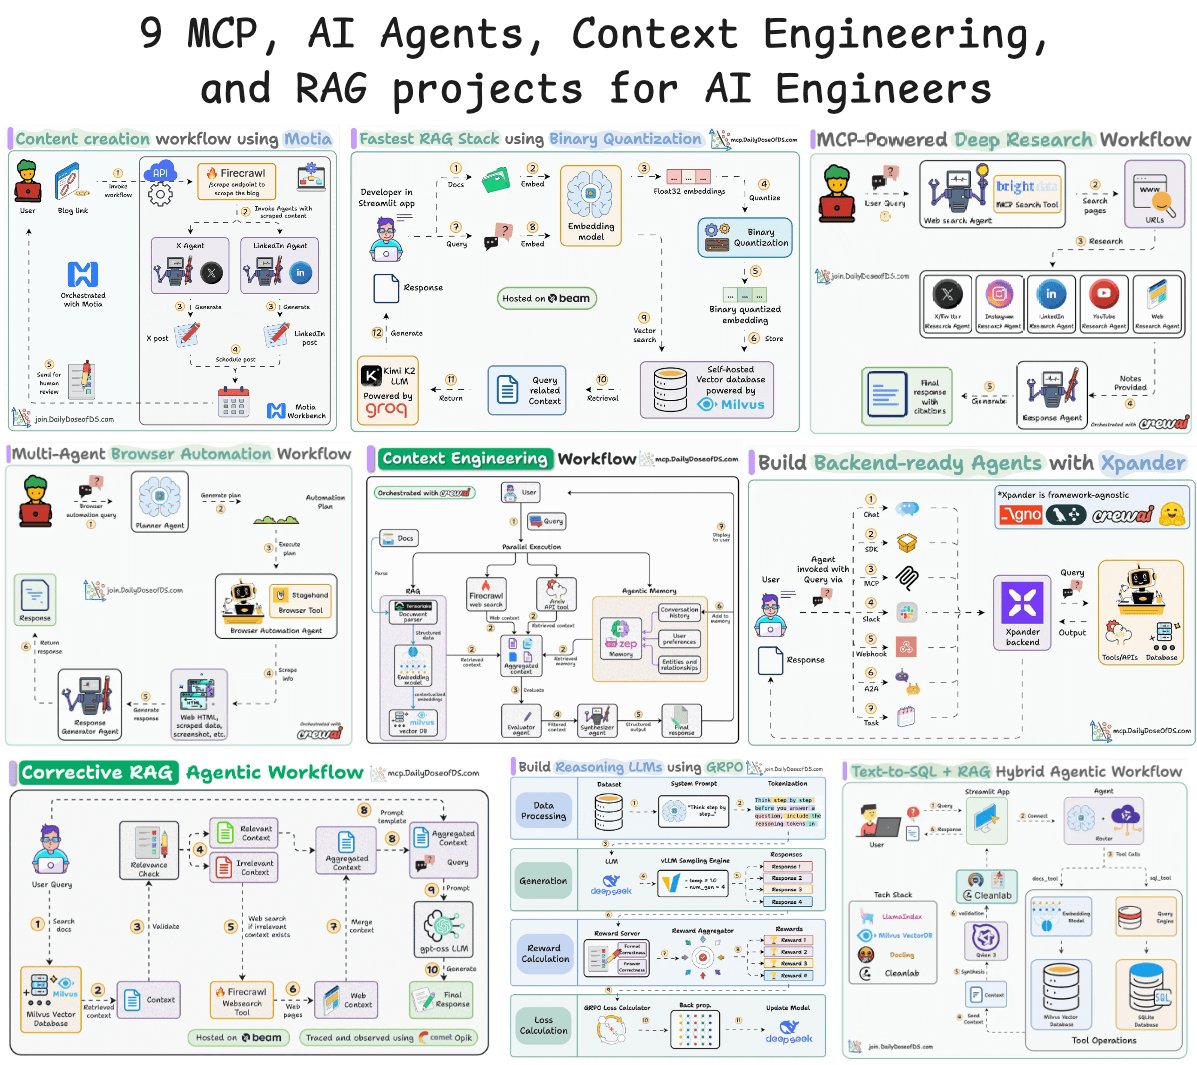
Find all these projects in our AI Engineering Hub, along with 90+ hands-on projects: https://
github.com/patchy631/ai-e
ngineering-hub
… (don't forget to star )
By
–
9 MCP, Agents, and RAG projects for AI engineers:
By
–
How far do you think that would be ? Karpathy in his recent interview said AGI is at least a decade away.
By
–
Memory is bigger than agents, whoever solves this wins the race to AGI

By
–
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!