Well said.
The real impact of AI shows up when it’s applied to the unglamorous parts of the business and quietly makes them work better.
We’ve been calling that Boring AI for a reason.
@ai21labs
-
The Real Impact of AI: Boring AI Making Business Operations Better
By
–
-
Real AI Automation Works Invisibly in Background
By
–
When AI is real automation, it disappears into the background. We’ve been calling that 'Boring AI' for a reason.
-
Boring AI: Agents for Operational Work and Business Outcomes
By
–
@rohanpaul_ai We totally agree. The real value of AI is in quietly taking on the boring, operational work that keeps businesses running. That’s exactly what we’re building with Boring AI: agents designed for accuracy, reliability and outcomes, not hype. Check out our work:
-
Jamba2: Open Source Model for February On-Device Applications
By
–
Model to try out in February: Jamba2. Fully open source under Apache 2.0, includes 3B (dense) model for on-device apps, intended for grounded QA workflows that don't call for the heavy “thinking token” overhead of reasoning models. Further details:
-
Jamba2: Open Source Model for On-Device QA Applications
By
–
Model to try out in February: Jamba2. Fully open source under Apache 2.0, includes 3B (dense) model for on-device apps, intended for grounded QA workflows that don't call for the heavy “thinking token” overhead of reasoning models. Further details:
-
Investigation: From Confident Gibberish to Scheduler Fix
By
–
5/5 Wrote up the complete investigation-from confident gibberish to the scheduler fix. Includes the false starts (suspected CUDA bugs), the breakthrough (request tracking), and lessons for anyone running stateful models at scale. Read the blog:
-
vLLM v0.14.0: Scheduler bug fix for Mamba token allocation
By
–
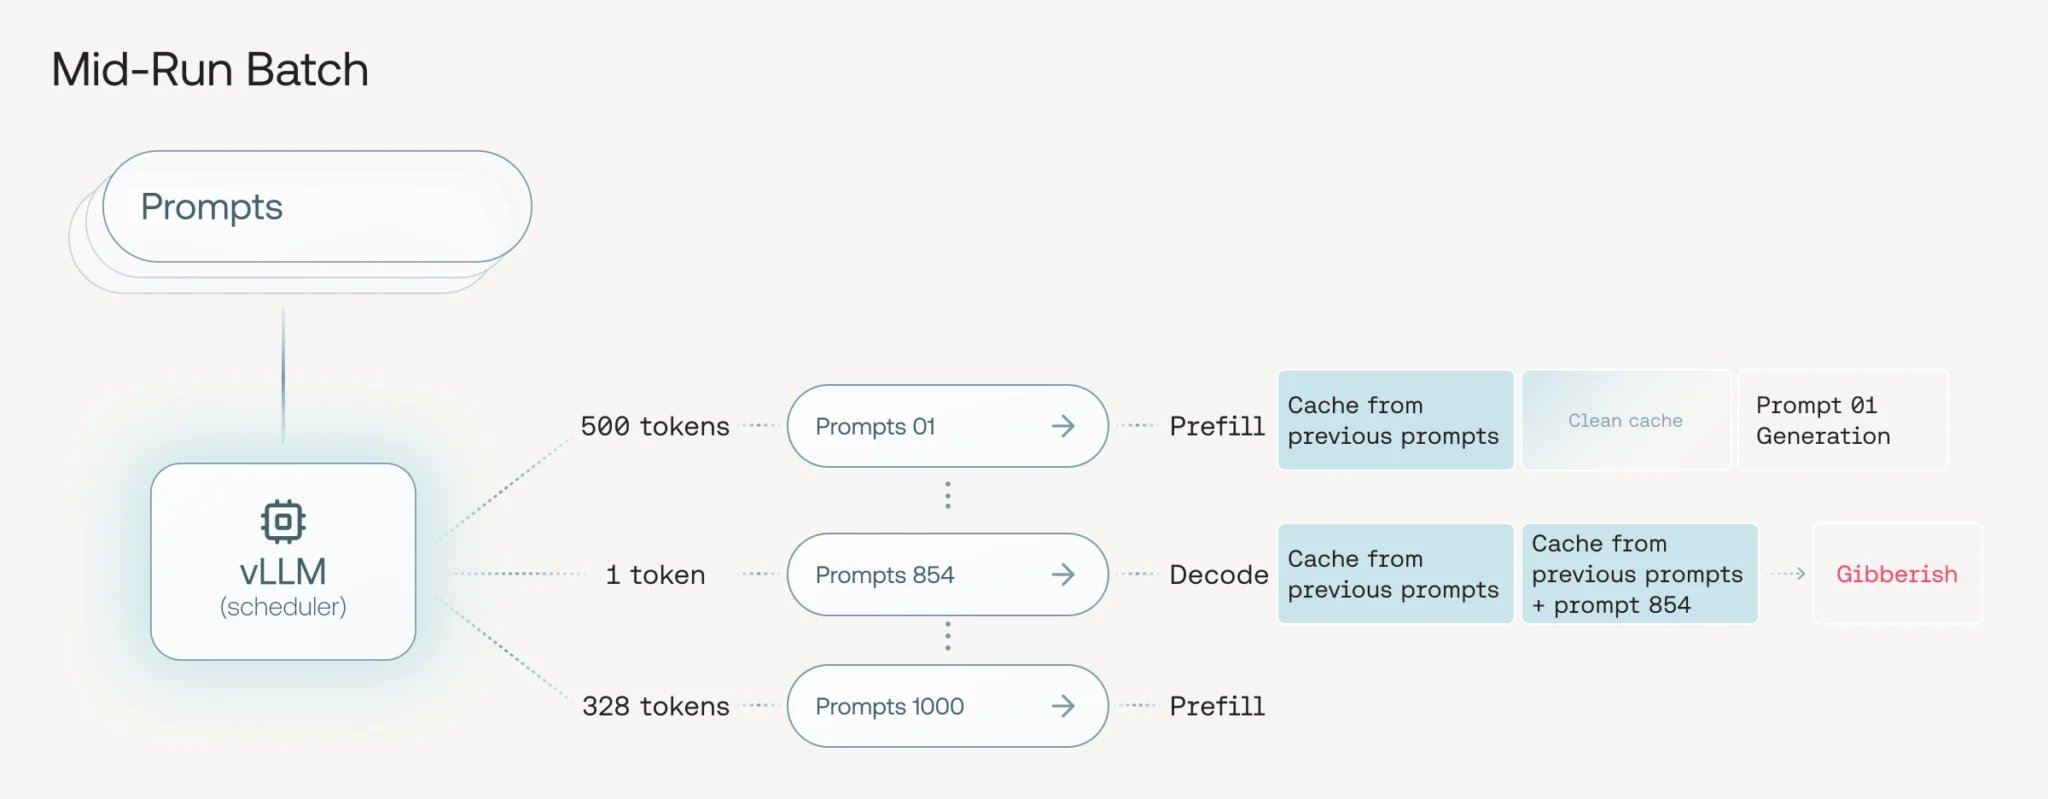
4/5 The confusion: Scheduler saw "1 token allocated" and assumed decode. But 1 token can also mean "new request that hit token budget limits." Now fixed: check whether it's the request's first-ever token, not the allocation size. In vLLM v0.14.0 – update if running Mamba.
-
SSM Recurrence Security: Mamba State Propagation vs Attention Safety
By
–
3/5 SSMs are recurrent, each token depends on previous state. Mamba decode reads state → updates it. Misclassified request reads garbage → propagates recursively through all tokens. Attention writes K/V first, then attends. Safe even if misclassified.
-
GPU Memory Utilization Bug: Token Classification Mismatch
By
–
2/5 Used gpu_memory_utilization=0.2 to reproduce quickly, but this happens naturally when the scheduler runs out of token budget and GPU blocks get recycled. New request gets 1 token → misclassified as "decode" But num_computed_tokens=0 → should be "prefill".
-
Debugging vLLM: Silent Corruption Bug in Jamba RL Training
By
–
1/5 Debugging vLLM: The silent corruption bug
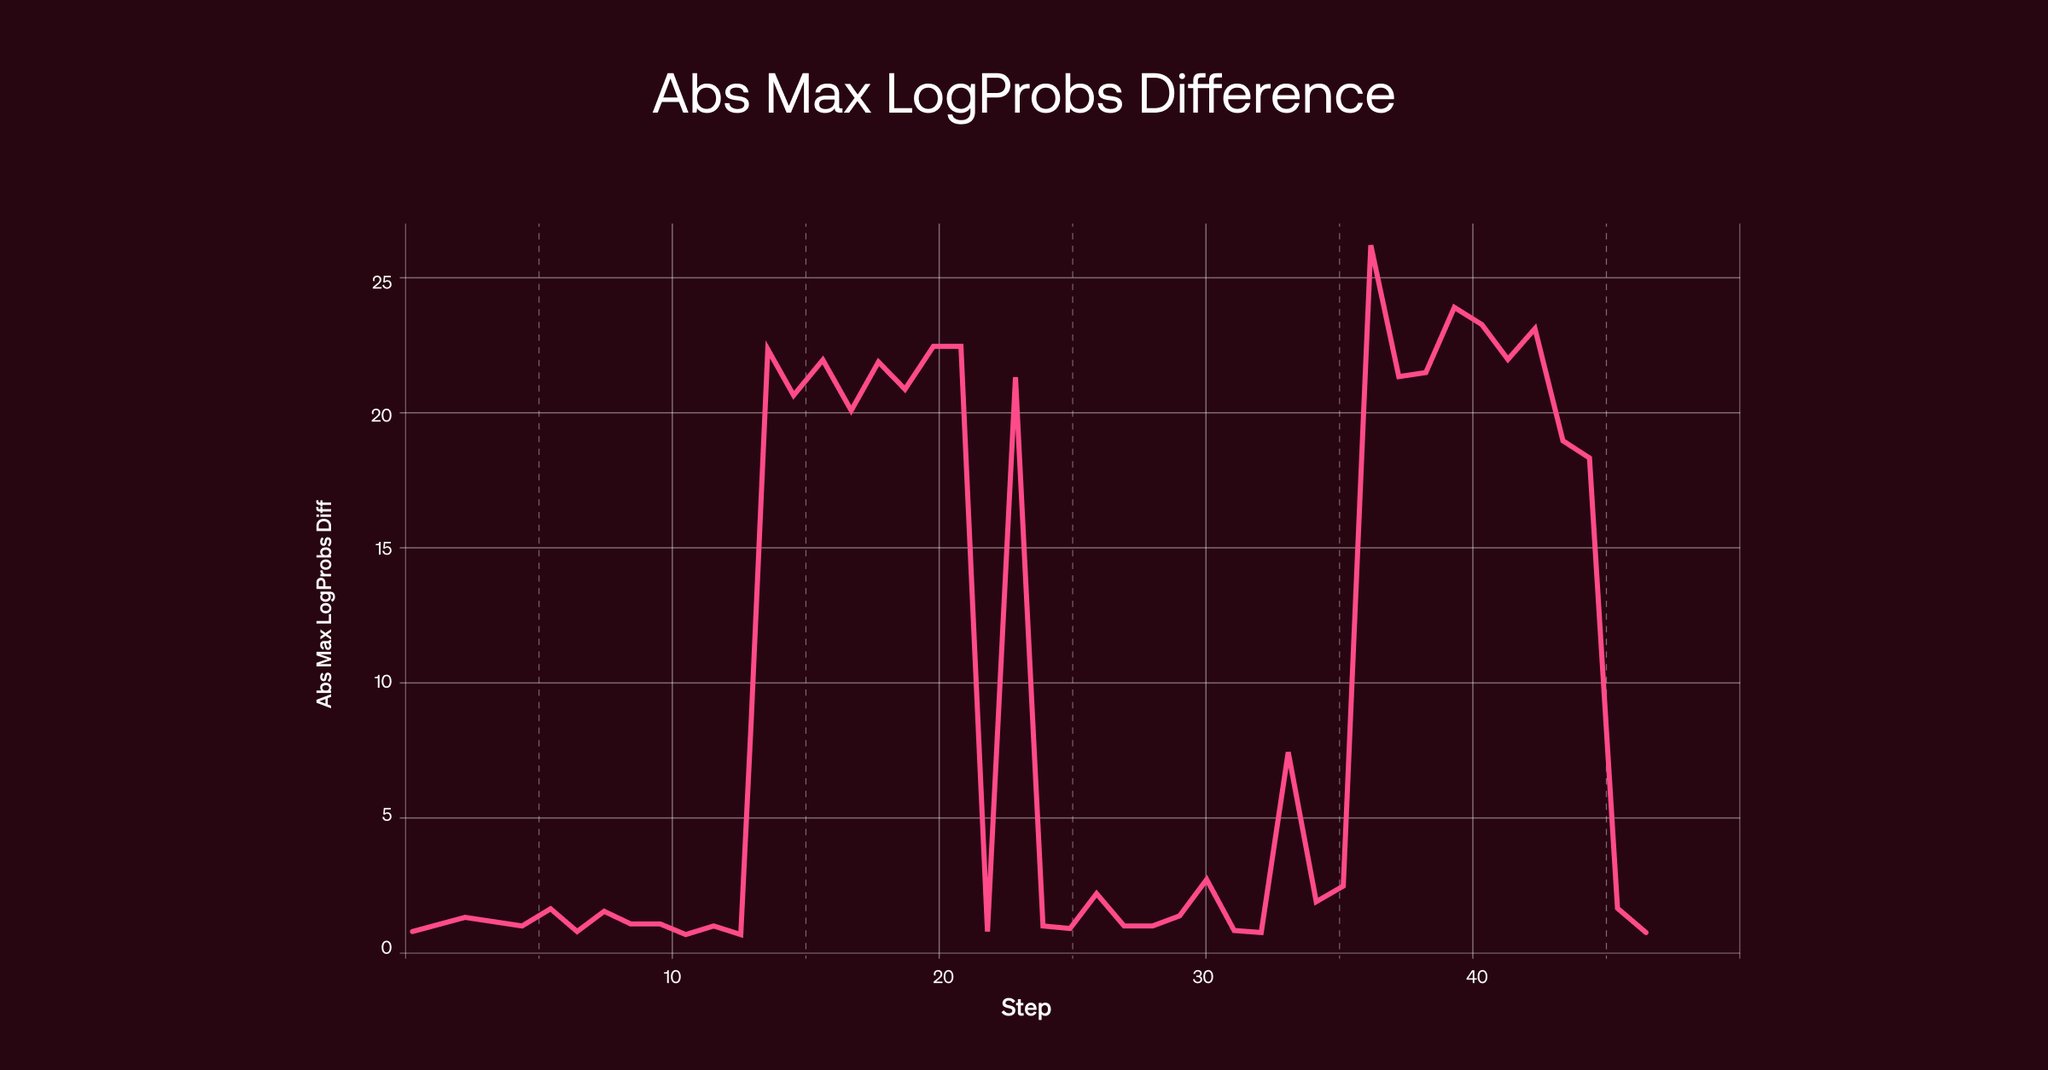
1/1000 Jamba generations collapsed into confident gibberish during RL training. No crashes, no errors, just wrong outputs with high logprobs. The culprit? A scheduler edge case that only triggers under memory pressure.