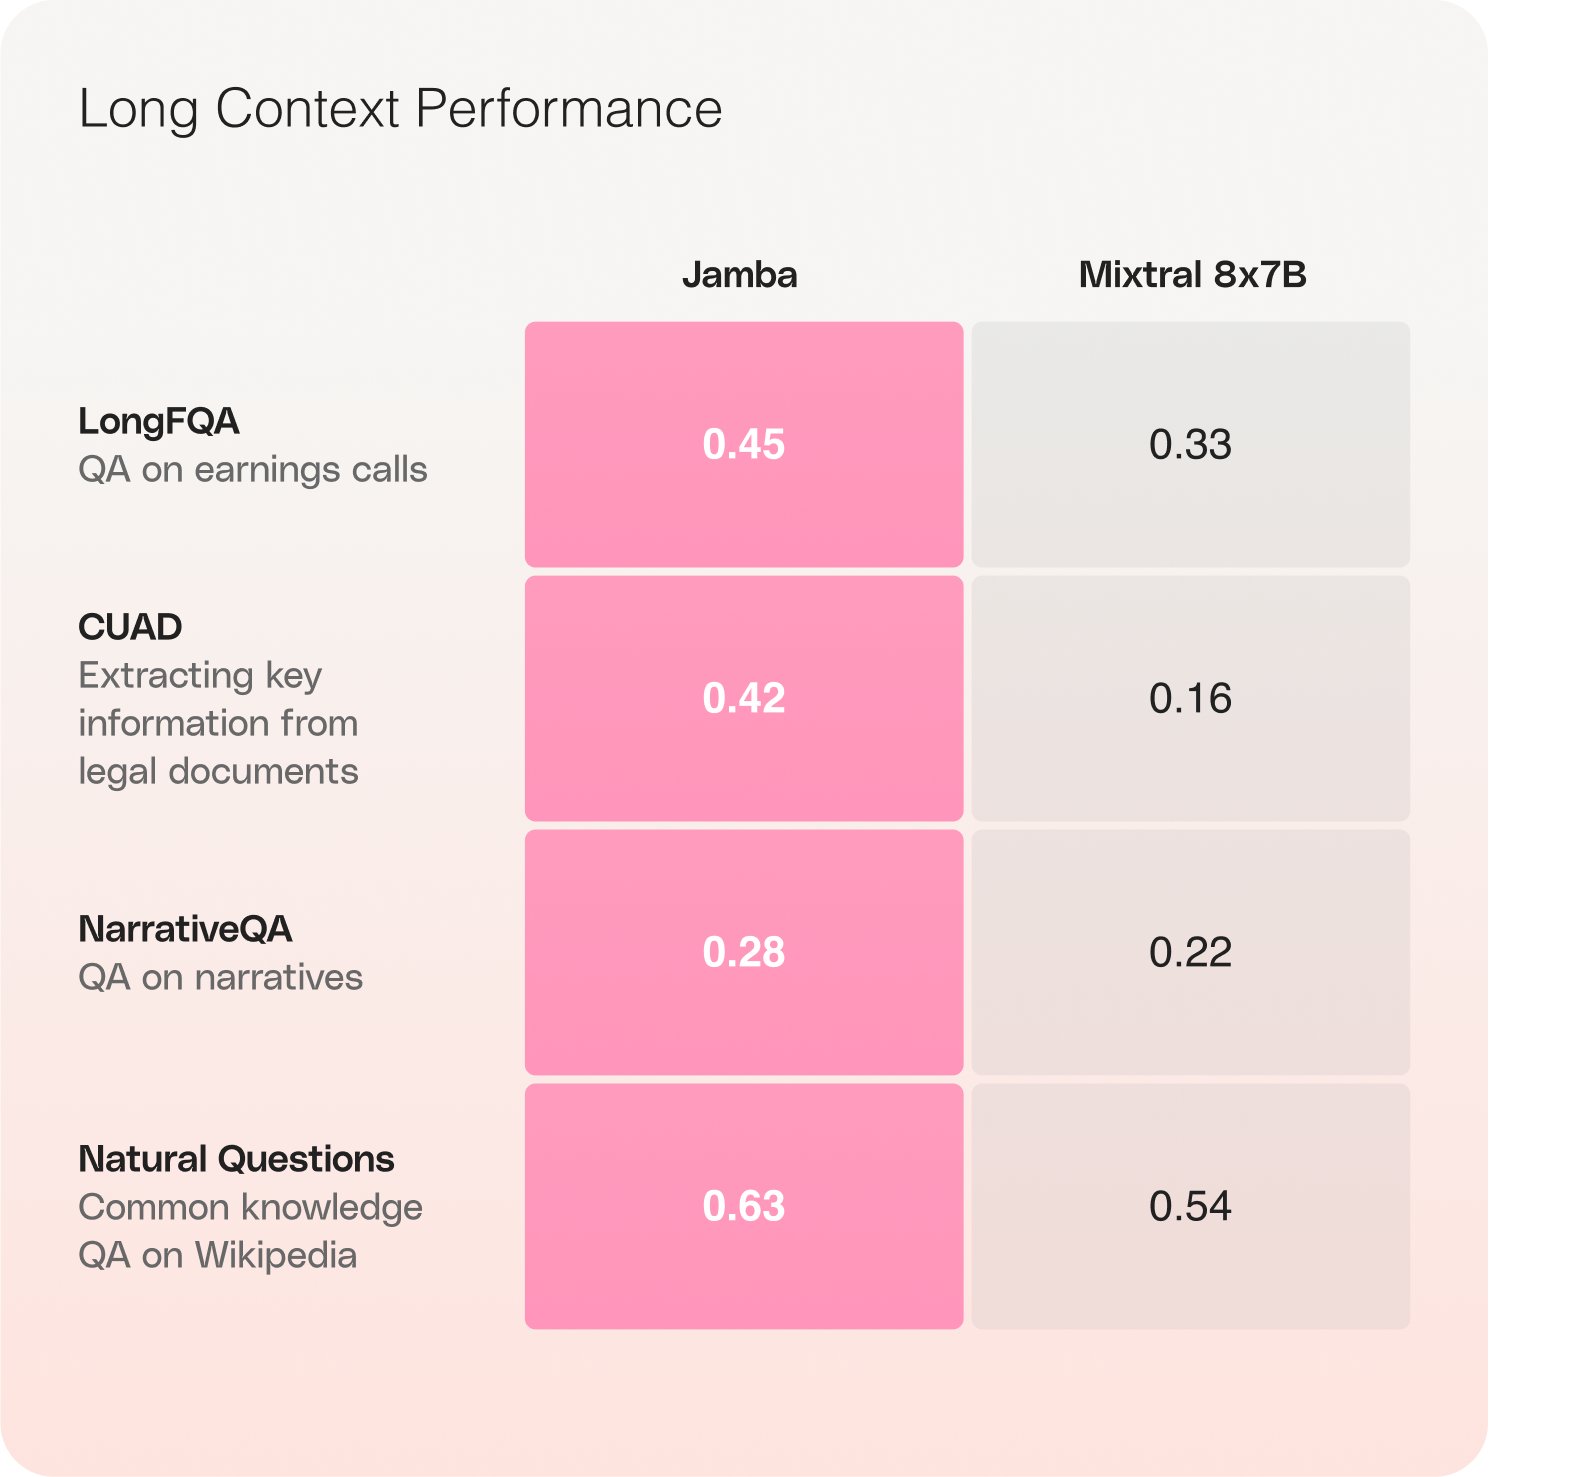
(3/4) Jamba-Instruct results on long-context QA benchmarks, conducted using the same method outlined in section 5.2.2 of our Jamba base model whitepaper.
@ai21labs
-
Jamba-Instruct Outperforms Competitors on Performance Benchmarks
By
–
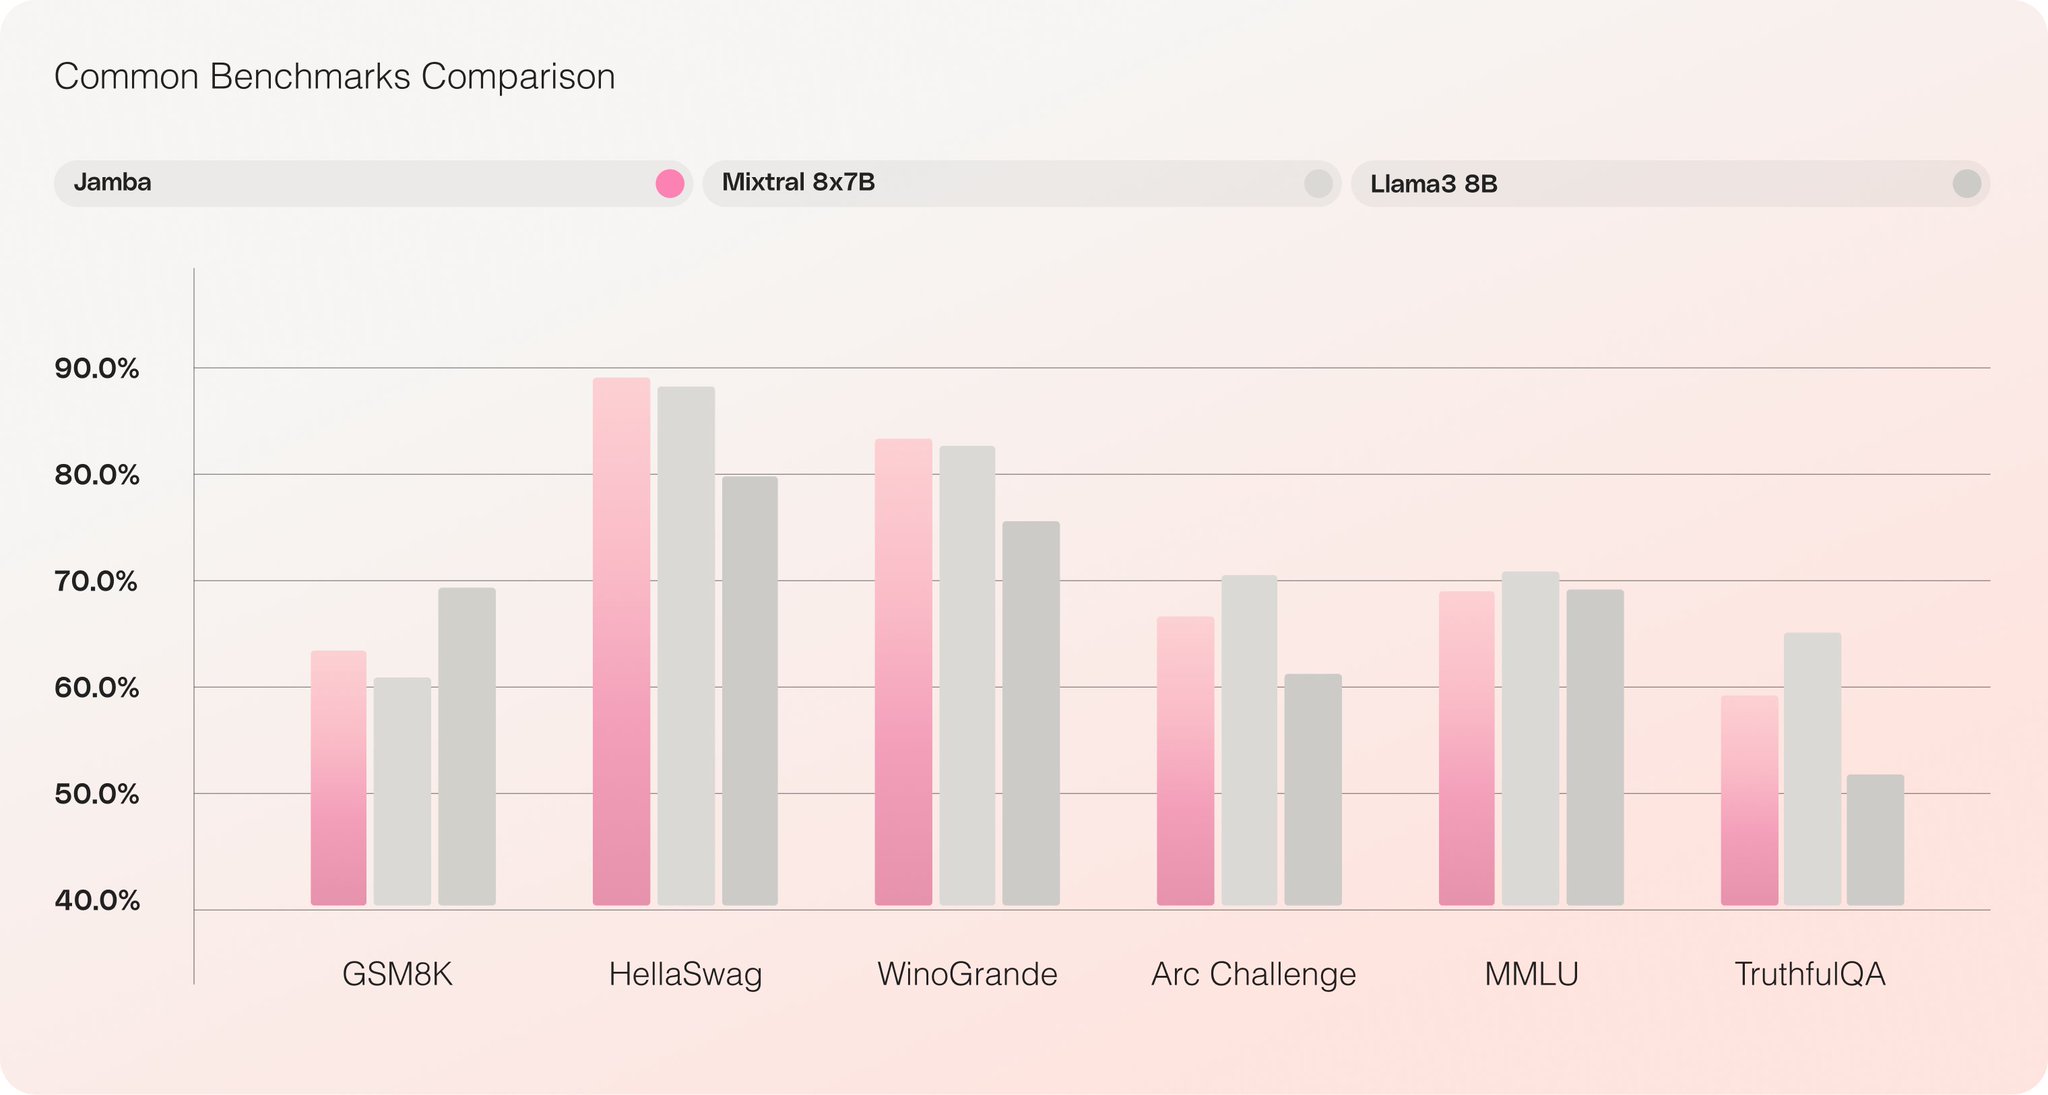
(2/4) Jamba-Instruct outperforms or rivals other instruction-tuned competitors across common performance benchmarks.
-
AI21 Labs Releases Jamba-Instruct Enterprise Model
By
–
We just released Jamba-Instruct! Built from our groundbreaking SSM-Transformer Jamba architecture, Jamba-Instruct brings the same technological innovation to the enterprise via an aligned model. With leading quality benchmarks, a 256K context window, and the most competitive
-
Building Great RAG Solutions with AI21’s Contextual Answers
By
–
Building a RAG solution is easy. Building a great one is not. In our guest blog on @streamlit
, our team explores the intricacies of how AI21's Contextual Answers Task-Specific Model & our RAG Engine generate context-based answers grounded in your proprietary organizational data. -
Jamba Whitepaper: Hybrid SSM-Transformer Architecture Details
By
–
The Jamba whitepaper details our in-depth ablations on this novel hybrid SSM-Transformer architecture, and how we chose to interleave Mamba, Transformer and MoE.
-
Scaling Mamba: Addressing Training Instability with Layer Adjustments
By
–
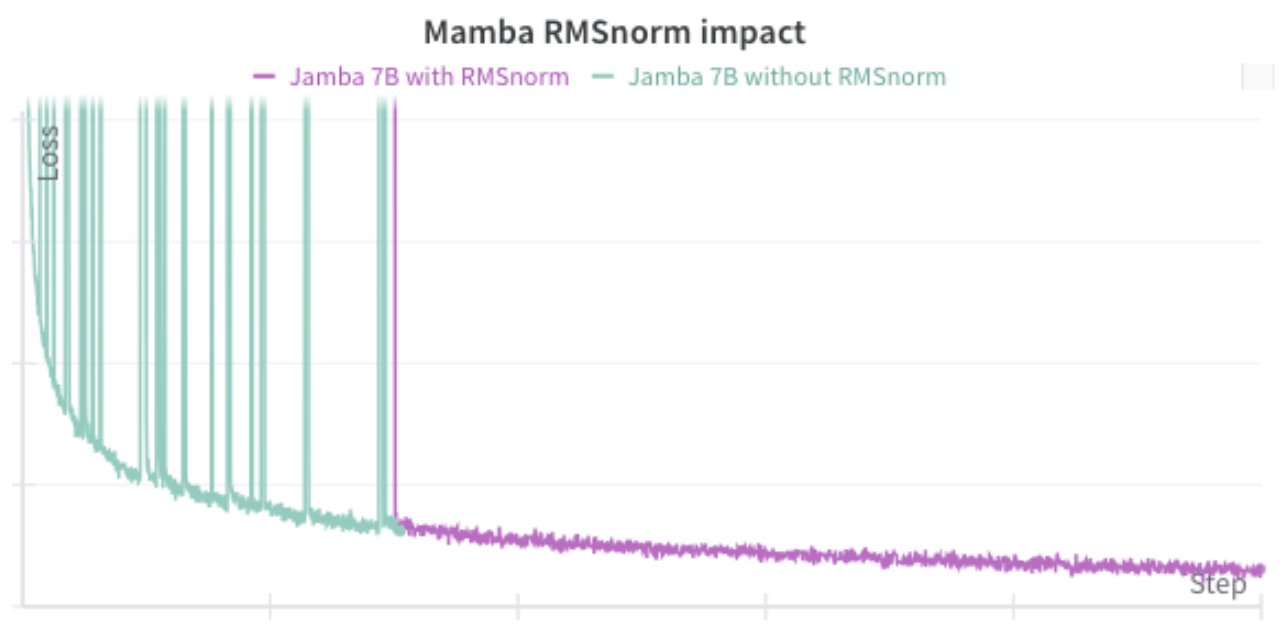
We found that scaling Mamba to substantial sizes isn’t trivial and causes unstable training. We had to make some adjustments to the Mamba layers to stabilize them, as can be seen in the graph below (training loss before & after the change) 6/6
-

Jamba’s Impressive Long-Context Performance with Minimal Attention Layers
By
–
Jamba was trained to handle contexts of up to 256K. Jamba has excellent performance in the needle-in-a-haystack evaluation, which is especially interesting given its use of only 4 attention layers. It also outperforms Mixtral on most long-context benchmarks. 4/6
-
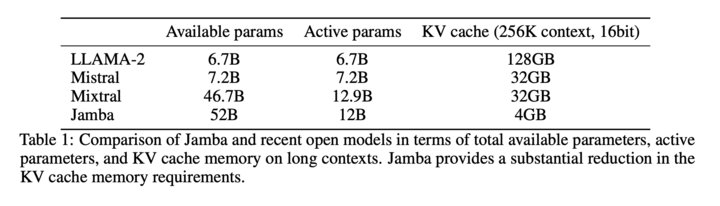
Jamba combines Transformer, Mamba, MoE for efficient scaling
By
–
Combining Transformer, Mamba & MoE allows flexibility in balancing low memory usage, high throughput, and high quality. Jamba’s KV cache – which becomes a limiting factor when scaling context in pure Transformers – is 8x smaller compared to a pure Transformer. 5/6
-
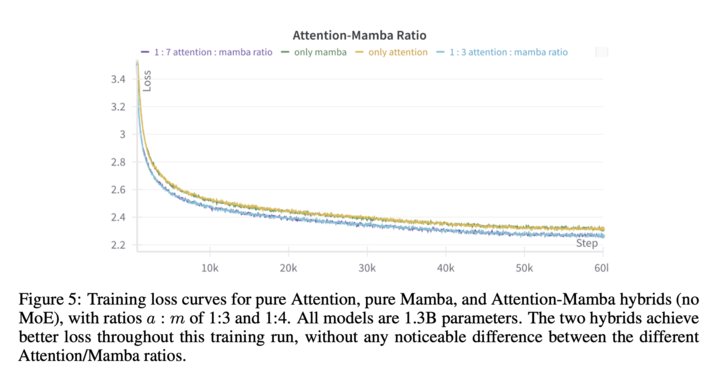
Jamba Hybrid Model Outperforms Pure Attention and Mamba Architectures
By
–
We see that the hybrid Jamba model outperforms both pure attention and pure Mamba models. The ratio of attention-to-Mamba layers of either 1:3 or 1:7 performs comparably, but given that a 1:7 ratio is more compute-efficient, we opt for it in our model. 2/6
-
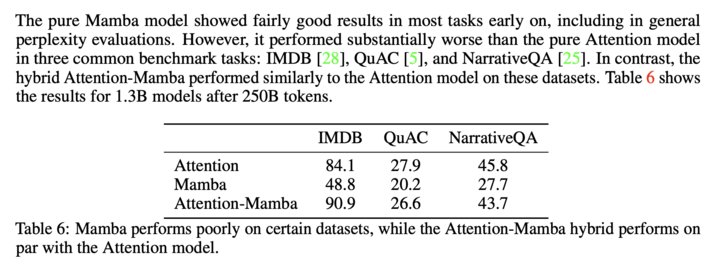
Mamba Models Struggle with In-Context Learning Compared to Attention
By
–
We noticed that pure Mamba models struggle to develop in-context learning capabilities. E.g., they performed substantially worse than the pure attention model in 3 common benchmarks while the attention–Mamba exhibits similar results to just Transformers. 3/6