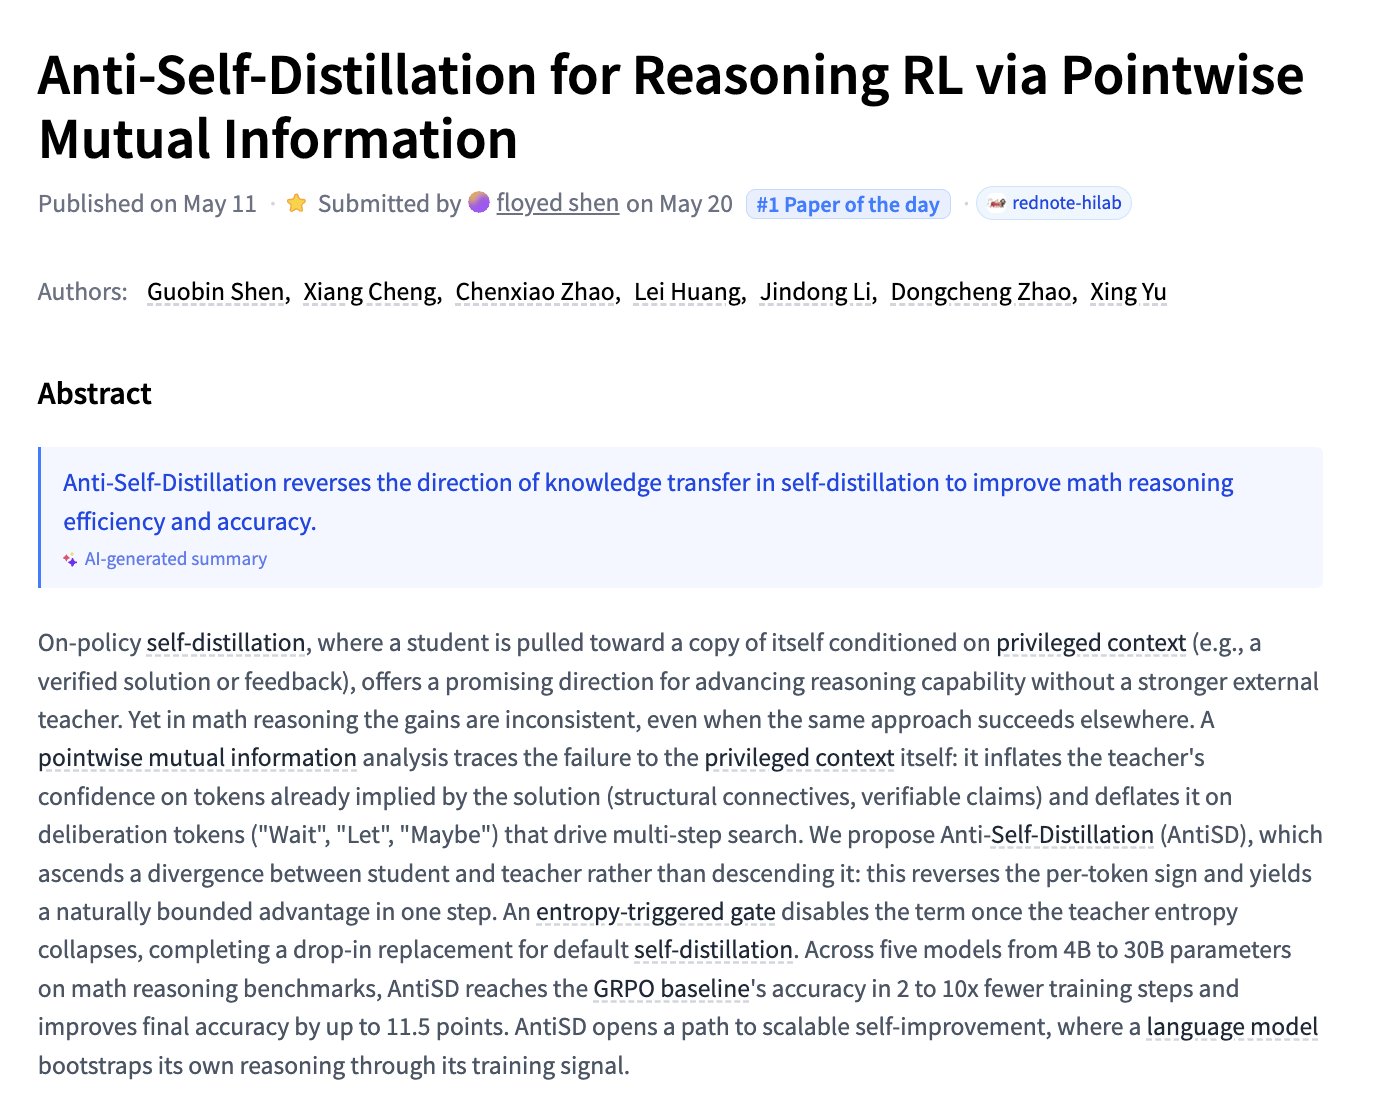
Anti-Self-Distillation for Reasoning RL via Pointwise Mutual Information
@_akhaliq
-
Nvidia Announces LongLive-2.0 for Long Video Generation
By
–
Nvidia presents LongLive-2.0
— AK (@_akhaliq) 19 mai 2026
An NVFP4 Parallel Infrastructure for Long Video Generation pic.twitter.com/kGTa0gegb9Nvidia presents LongLive-2.0 An NVFP4 Parallel Infrastructure for Long Generation
-
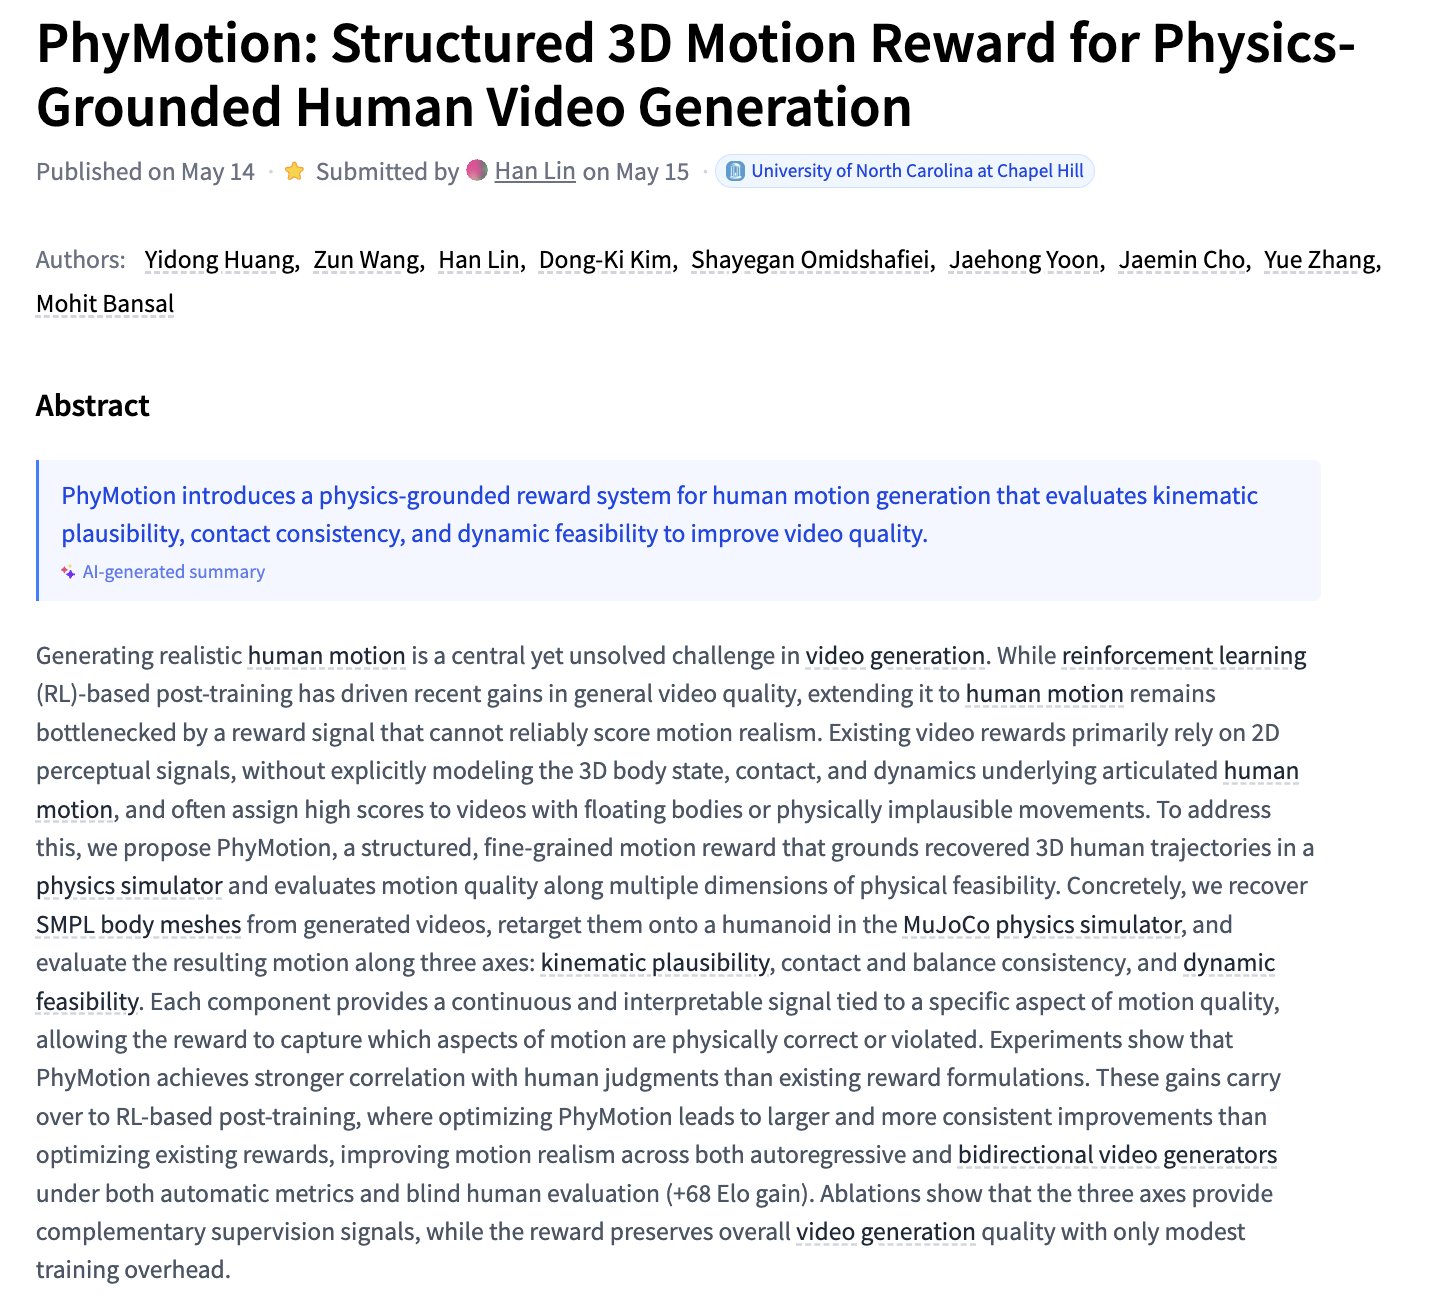
PhyMotion: Structured 3D Motion Reward for Physics-Grounded Human Video Generation
By
–
PhyMotion Structured 3D Motion Reward for Physics-Grounded Human Generation
-
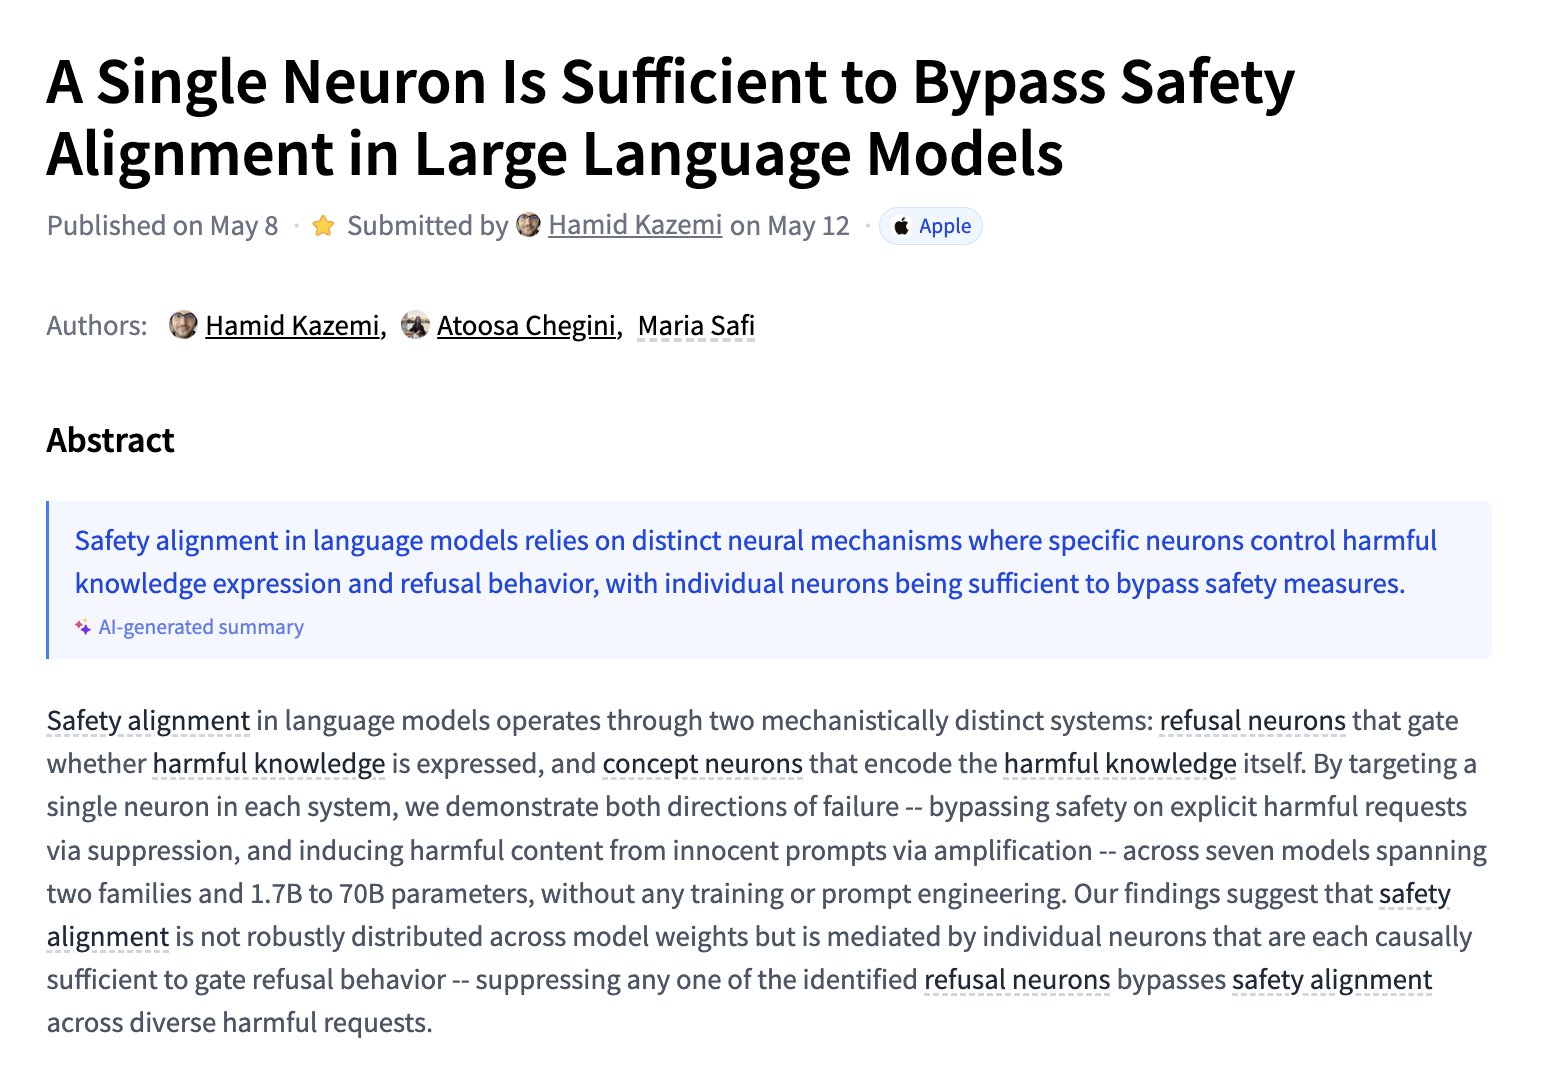
Single Neuron Can Bypass LLM Safety Alignment
By
–
A Single Neuron Is Sufficient to Bypass Safety Alignment in Large Language Models
-
AnyFlow: New Video Diffusion Model with On-Policy Flow Map Distillation
By
–
AnyFlow
— AK (@_akhaliq) 14 mai 2026
Any-Step Video Diffusion Model with On-Policy Flow Map Distillation pic.twitter.com/rXWlrNhv0KAnyFlow Any-Step Diffusion Model with On-Policy Flow Map Distillation
-
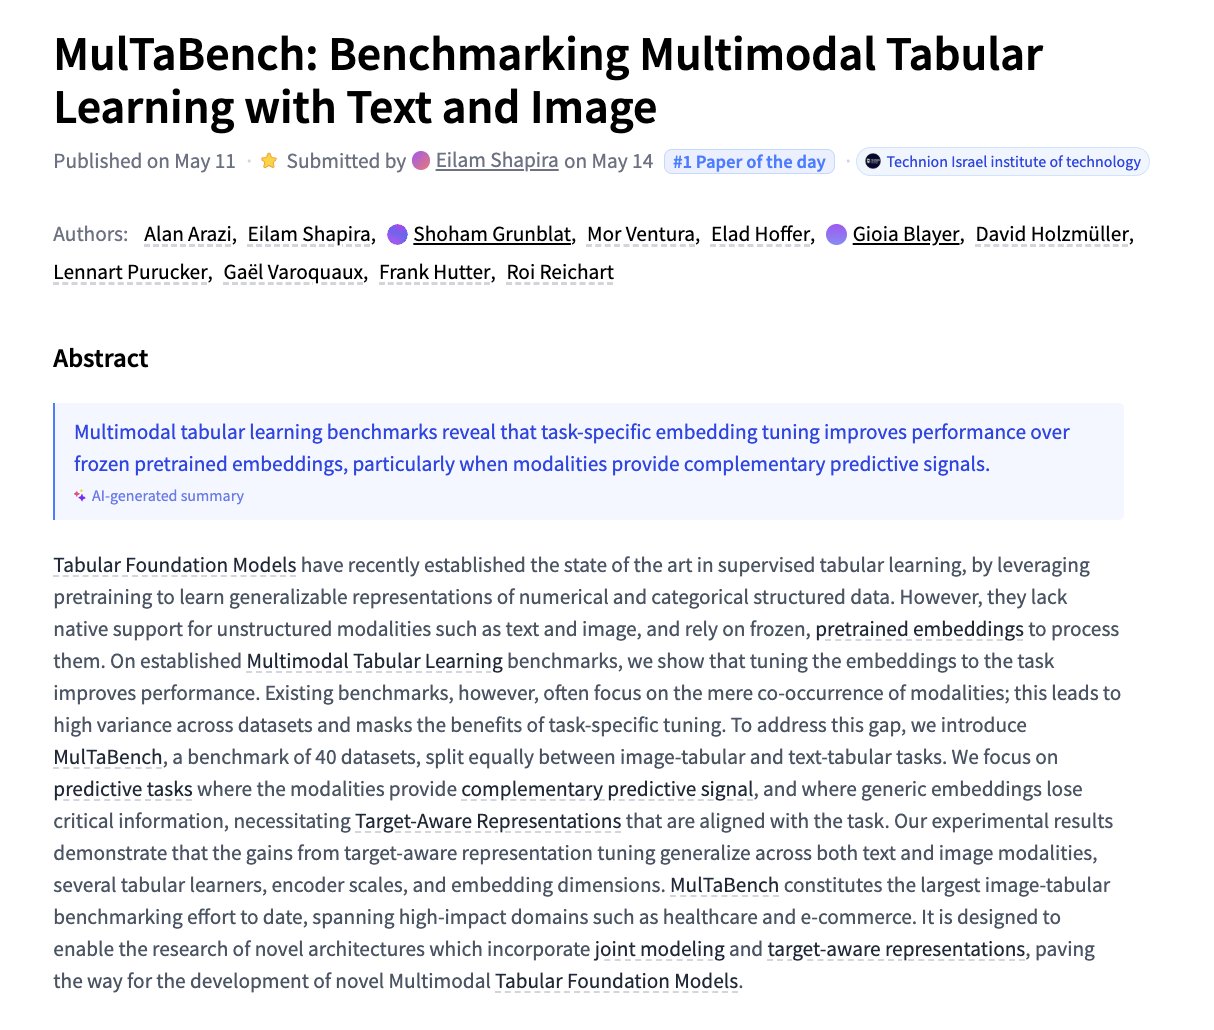
MulTaBench: A New Benchmark for Multimodal Tabular Learning
By
–
MulTaBench Benchmarking Multimodal Tabular Learning with Text and Image
-
CausalCine: Real-Time Autoregressive Generation for Multi-Shot Video Narratives
By
–
CausalCine Real-Time Autoregressive Generation for Multi-Shot Narratives
-
Do Enterprise Systems Need Learned World Models?
By
–
Do Enterprise Systems Need Learned World Models? The Importance of Context to Infer Dynamics
-
Meta-RL with Rubric-guided Policy Decomposition Research
By
–
RubricEM Meta-RL with Rubric-guided Policy Decomposition beyond Verifiable Rewards
-

EgoMemReason: A Memory-Driven Benchmark for Egocentric Video Understanding
By
–
EgoMemReason A Memory-Driven Reasoning Benchmark for Long-Horizon Egocentric Understanding