KnowRL Boosting LLM Reasoning via Reinforcement Learning with Minimal-Sufficient Knowledge Guidance paper: https://
huggingface.co/papers/2604.12
627
…
@_akhaliq
-
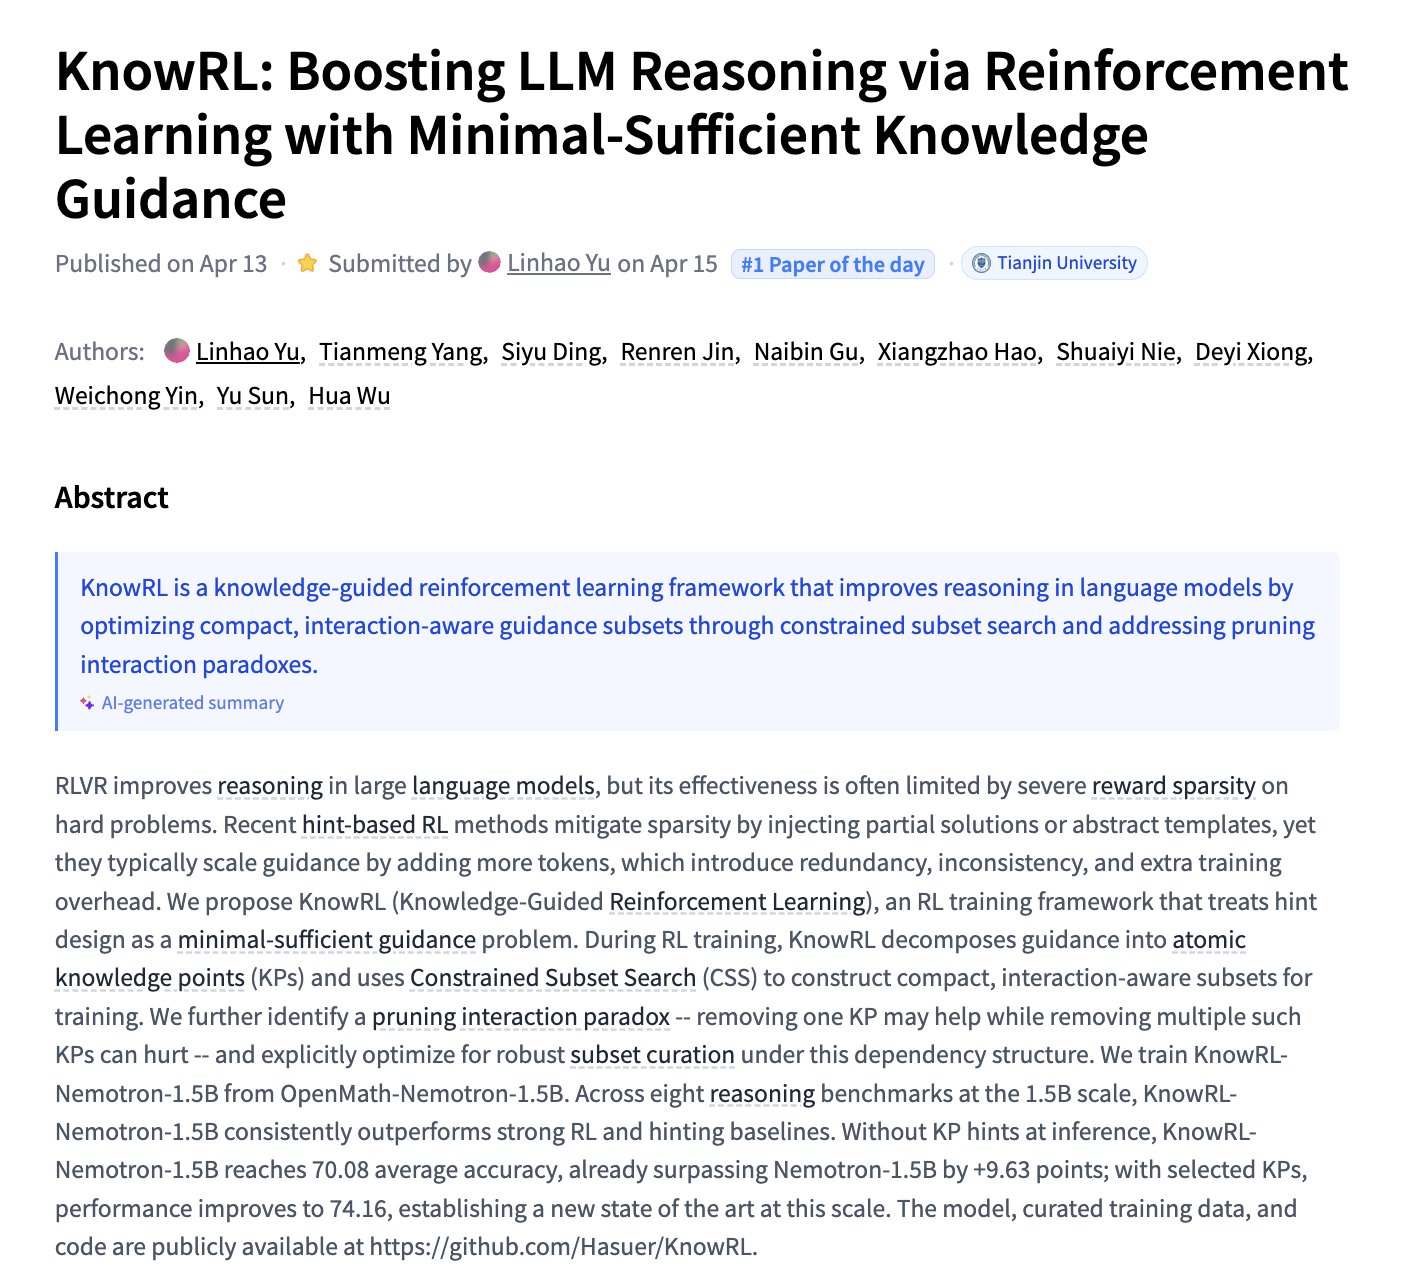
KnowRL Boosts LLM Reasoning via Reinforcement Learning with Knowledge Guidance
By
–
-
ClawGUI: Unified Framework for Training and Deploying GUI Agents
By
–
ClawGUI
— AK (@_akhaliq) 15 avril 2026
A Unified Framework for Training, Evaluating, and Deploying GUI Agents
paper: https://t.co/VPMTifMWGK pic.twitter.com/xISqw6h3pQClawGUI A Unified Framework for Training, Evaluating, and Deploying GUI Agents paper: https://
huggingface.co/papers/2604.11
784
… -
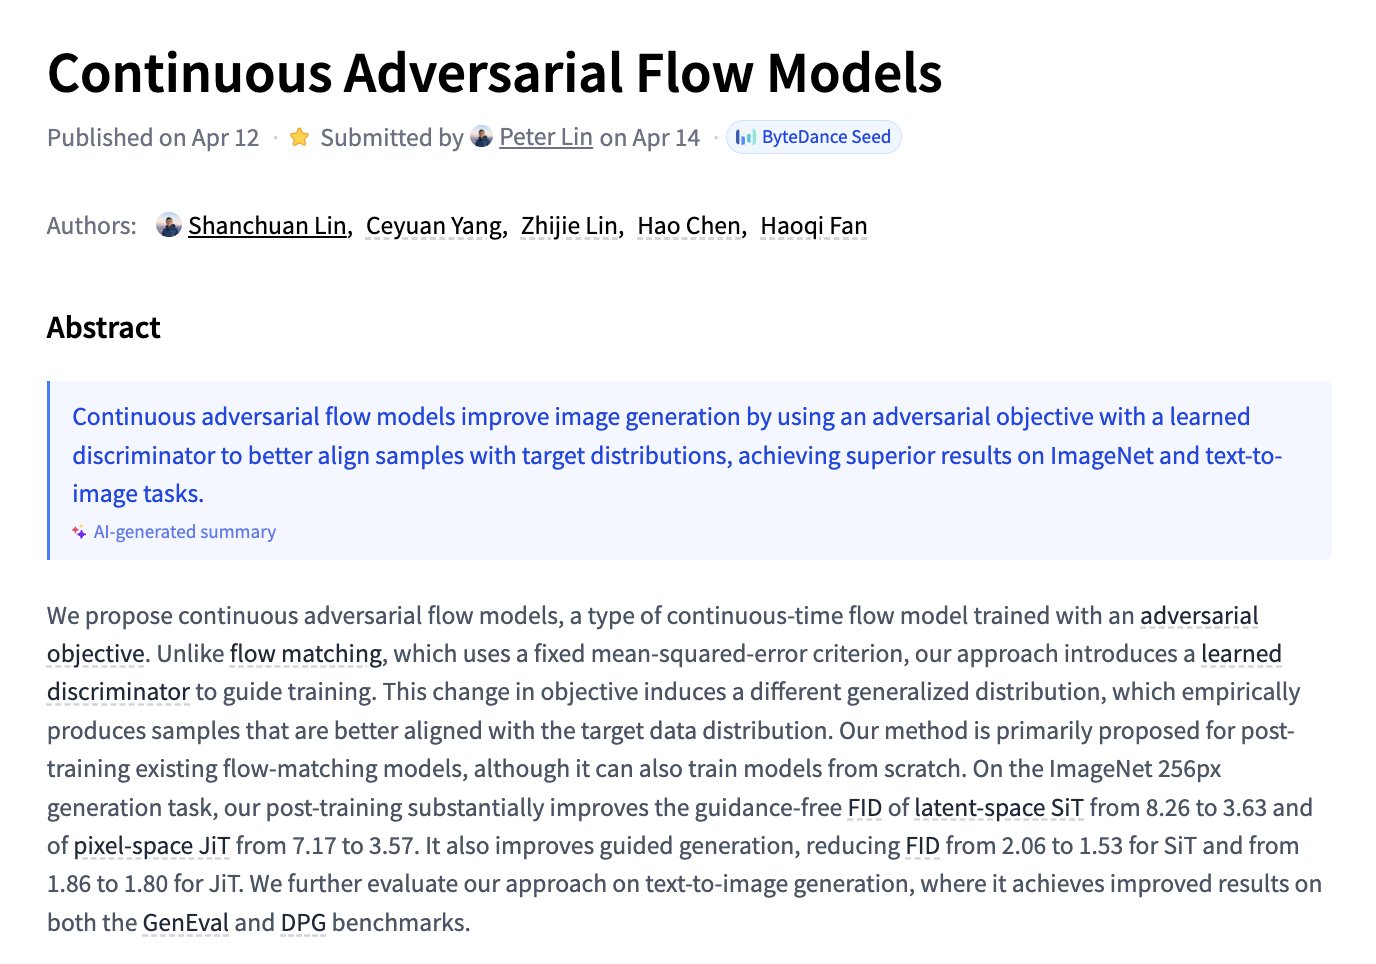
Continuous Adversarial Flow Models New Research Paper
By
–
Continuous Adversarial Flow Models paper: https://
huggingface.co/papers/2604.11
521
… -

Gradio Super Mario Theme Released for Blocks and Interface
By
–
Gradio Super Mario theme is out To use this theme, set theme='hmb/super-mario' in the launch() method of gr.Blocks() or gr.Interface(). You can append an @ and a semantic version expression, e.g. @>=1.0.0,<2.0.0 to pin to a given version of this theme example app:
-
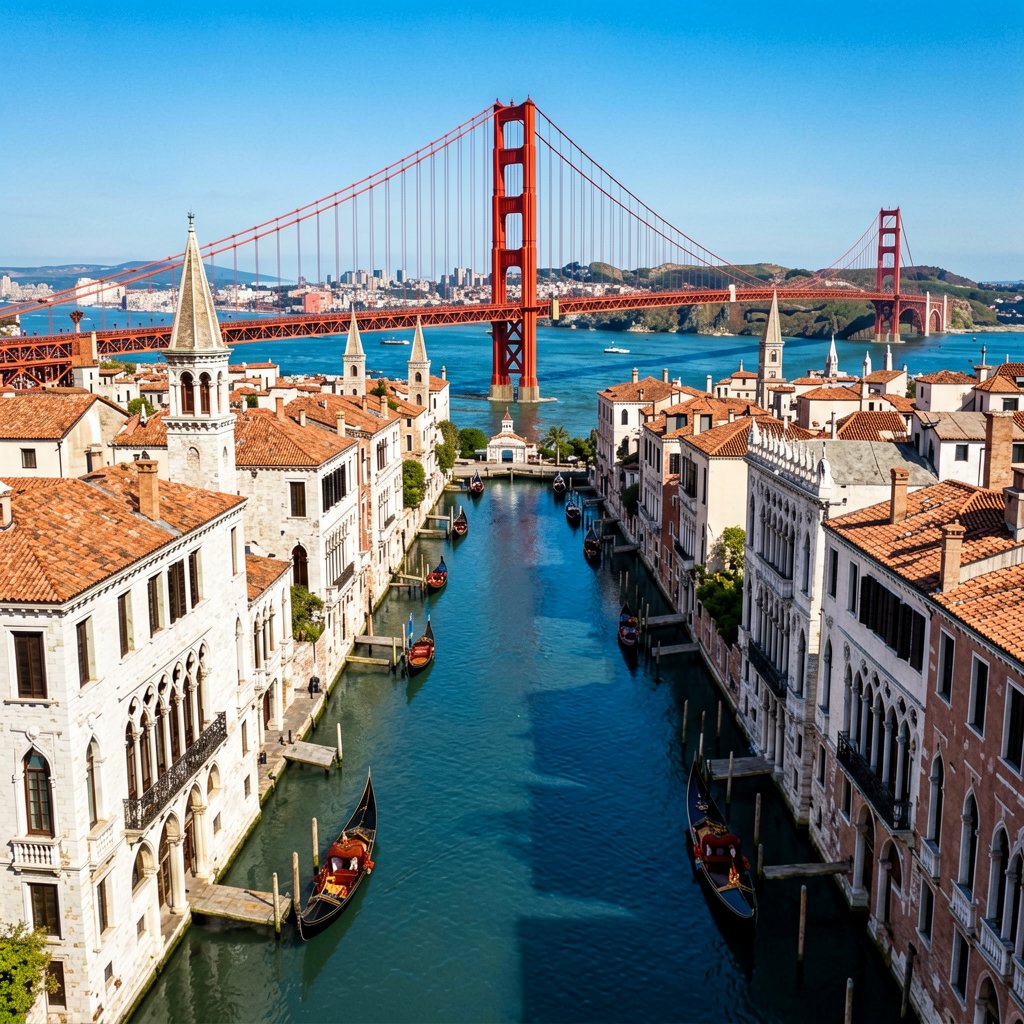
ERNIE-Image-Turbo Generates Venice Sci-Fi Imagery
By
–
ERNIE-Image-Turbo SF but venice app: https://
huggingface.co/spaces/akhaliq
/ERNIE-Image-Turbo
… -
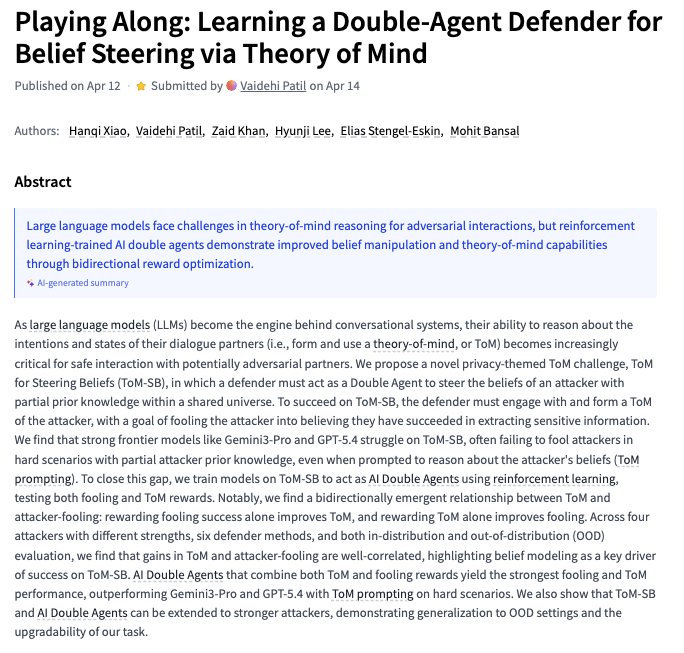
Double-Agent Defender for Belief Steering via Theory of Mind
By
–
Playing Along Learning a Double-Agent Defender for Belief Steering via Theory of Mind paper: https://
huggingface.co/papers/2604.11
666
… -
OmniShow Unifies Multimodal Conditions for HOI Video Generation
By
–
OmniShow
— AK (@_akhaliq) 14 avril 2026
Unifying Multimodal Conditions for Human-Object Interaction Video Generation
paper: https://t.co/6r4EVKx31z pic.twitter.com/Iz8mA2WDwEOmniShow Unifying Multimodal Conditions for Human-Object Interaction Generation paper: https://
huggingface.co/papers/2604.11
804
… -
Survey on Attention Sink in Transformers: Utilization and Mitigation
By
–
Attention Sink in Transformers A Survey on Utilization, Interpretation, and Mitigation paper: https://
huggingface.co/papers/2604.10
098
… -

Memory-Enhanced Dynamic Reward Shaping in RL Research
By
–
The Past Is Not Past Memory-Enhanced Dynamic Reward Shaping paper: https://
huggingface.co/papers/2604.11
297
… -
QuanBench+: Unified Benchmark for LLM-Based Quantum Code Generation
By
–
QuanBench+ A Unified Multi-Framework Benchmark for LLM-Based Quantum Code Generation paper: https://
huggingface.co/papers/2604.08
570
…