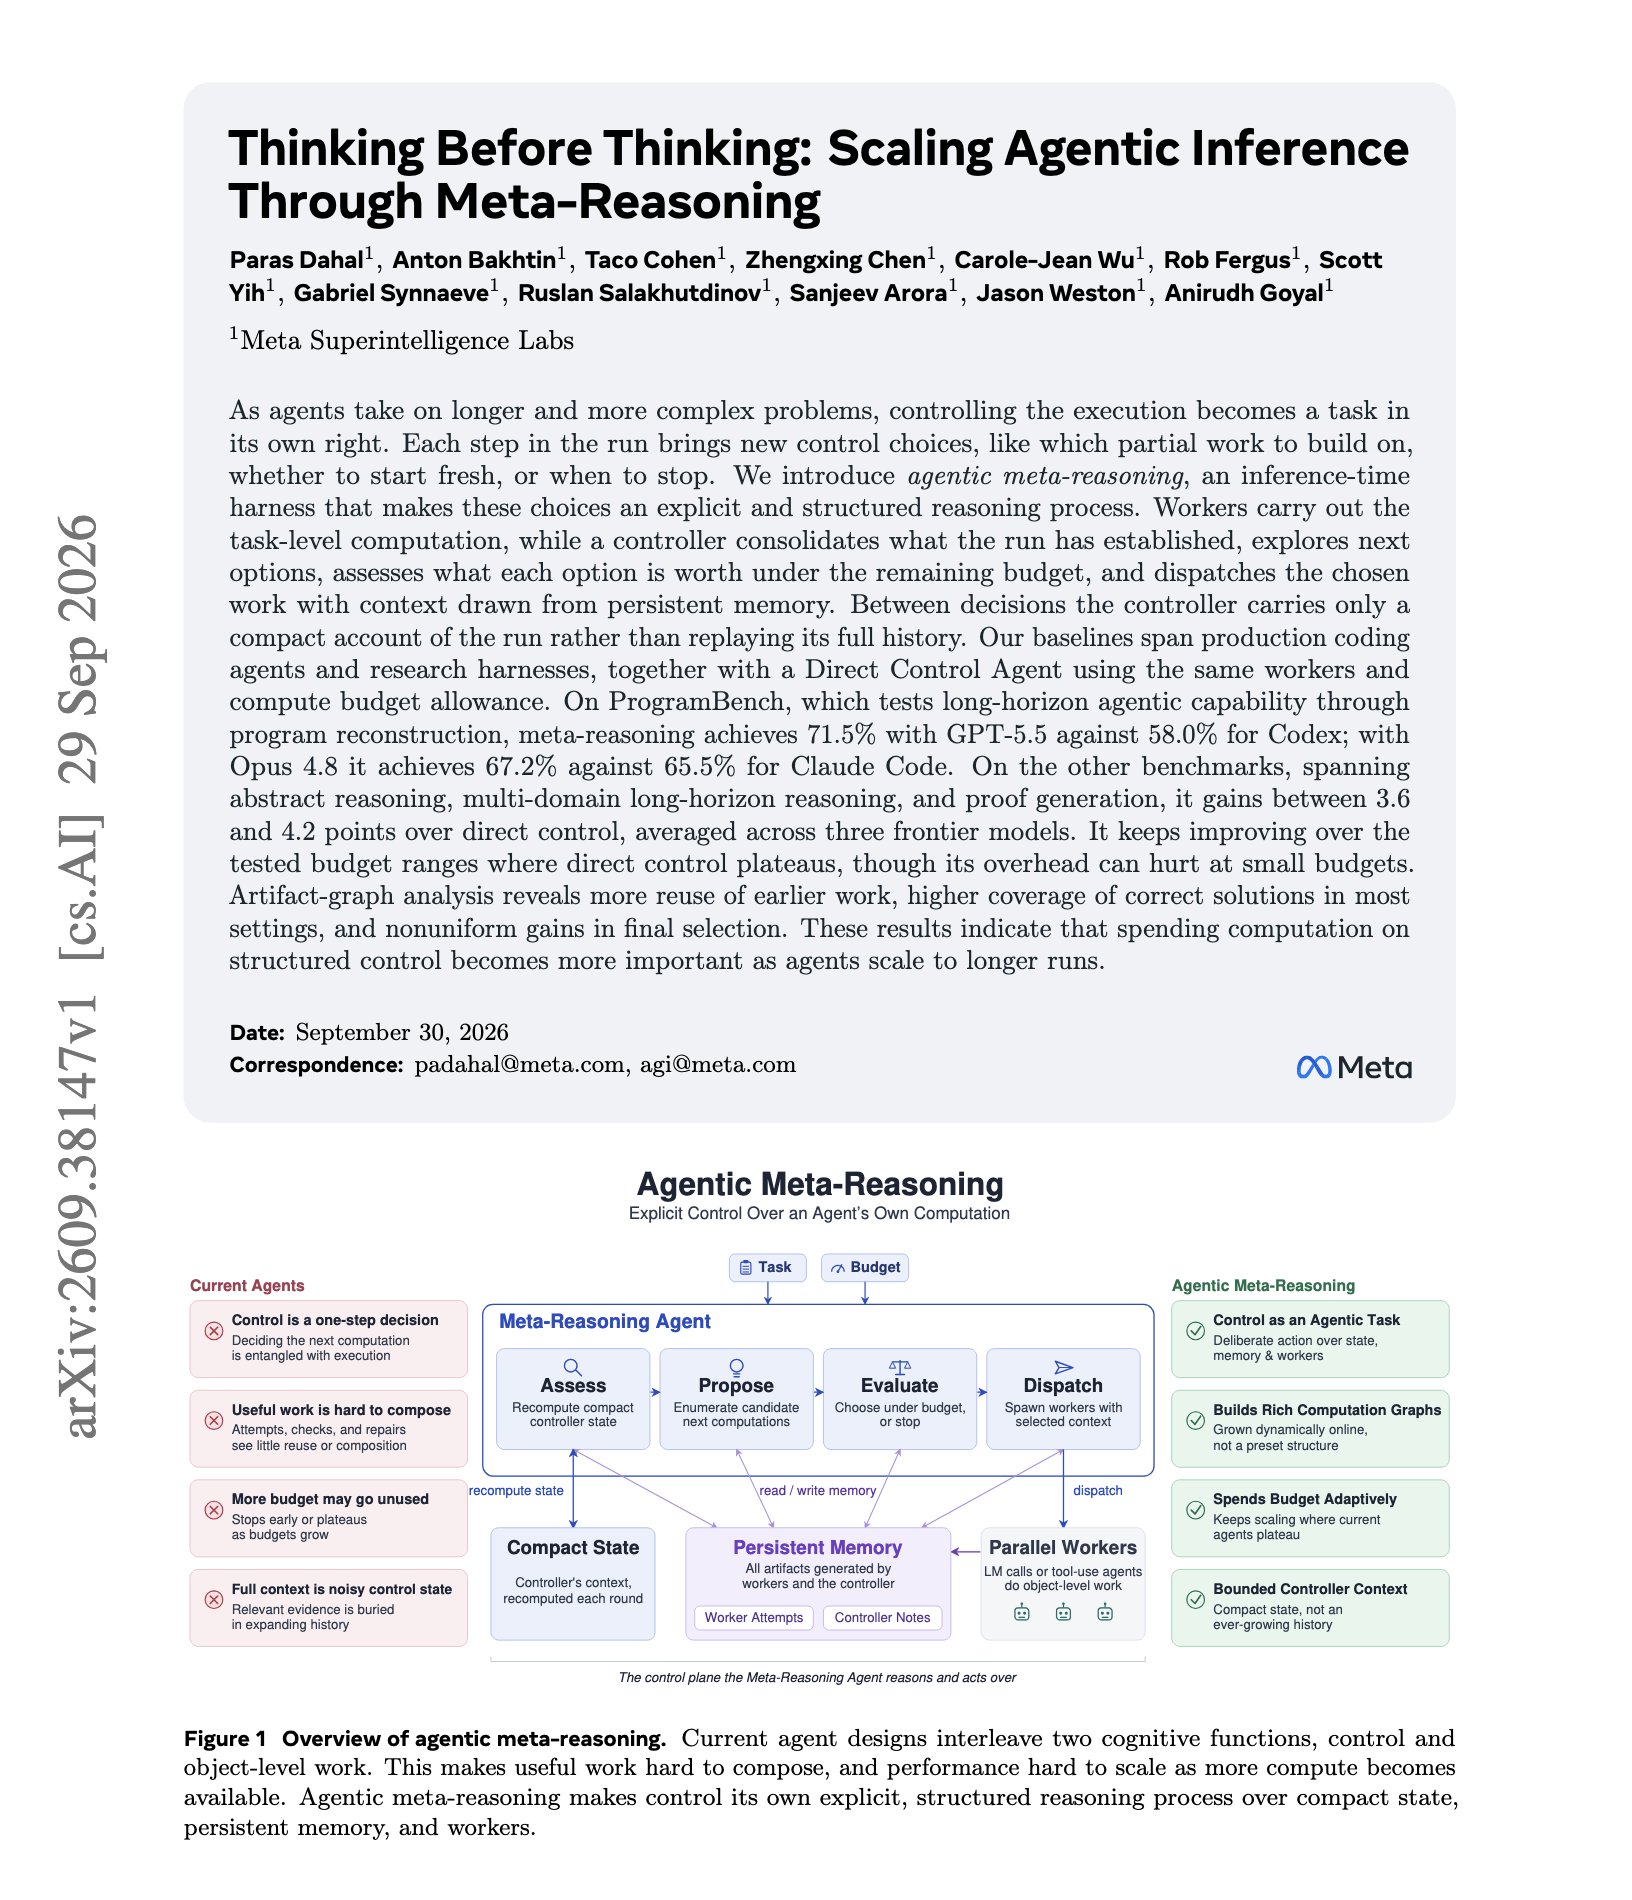
Super interesting paper from Meta Superintelligence Labs on controlling long agent runs. They use the same workers and same budget, and ProgramBench goes from 63.7% to 71.5% with GPT-5.5 when a dedicated controller decides what work to run next. Codex scores 58.0%. Here is how
Meta paper on controlling long agent runs with benchmarks
By
–