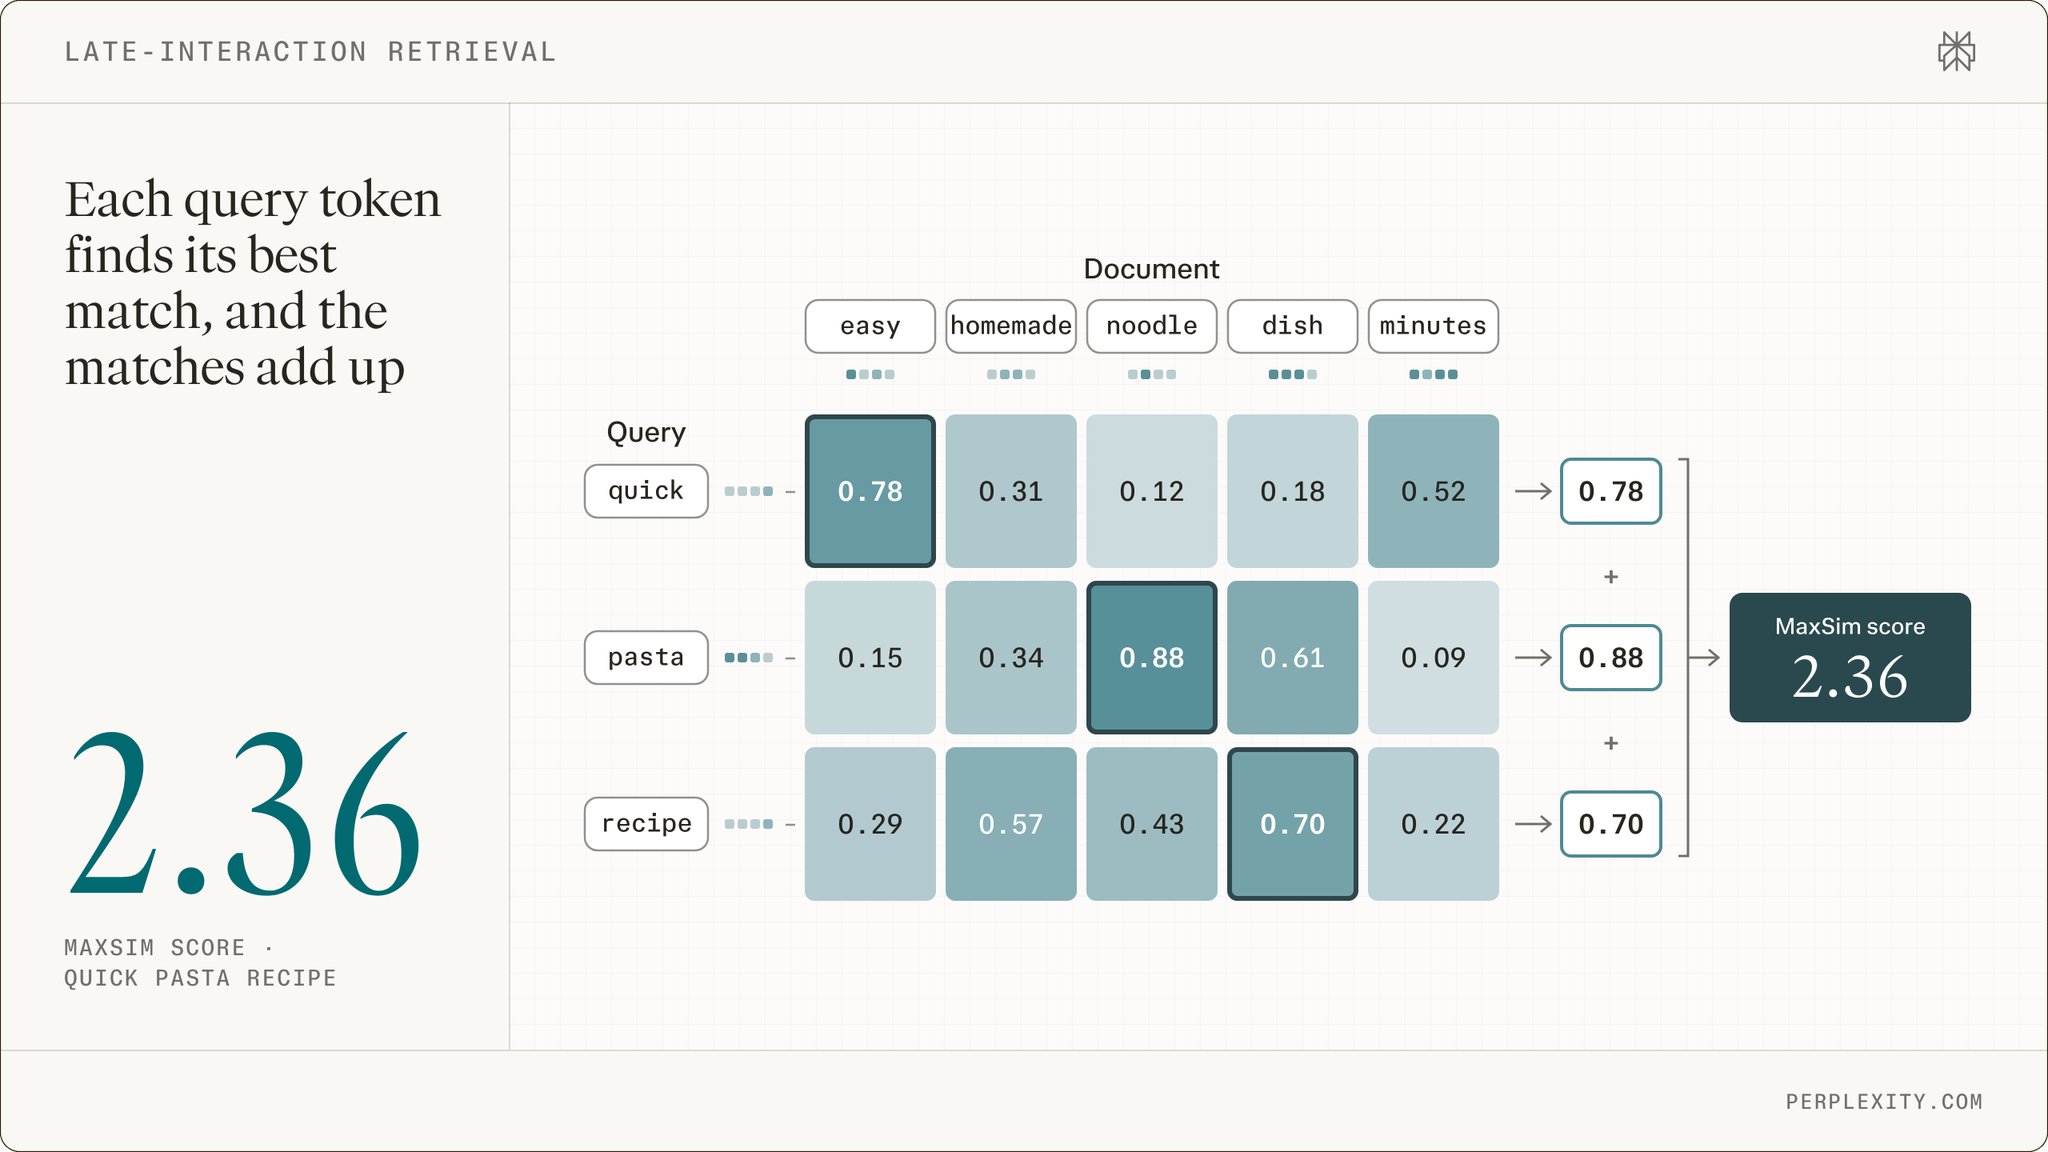
Dense embedding models compress each document into one vector, which loses detail as pages get longer or more visual. pplx-embed-v2-late keeps a 128-dimensional vector per token and scores with MaxSim, so each query token is matched to its closest token in the document.
Per-token late-interaction embeddings with MaxSim scoring
By
–