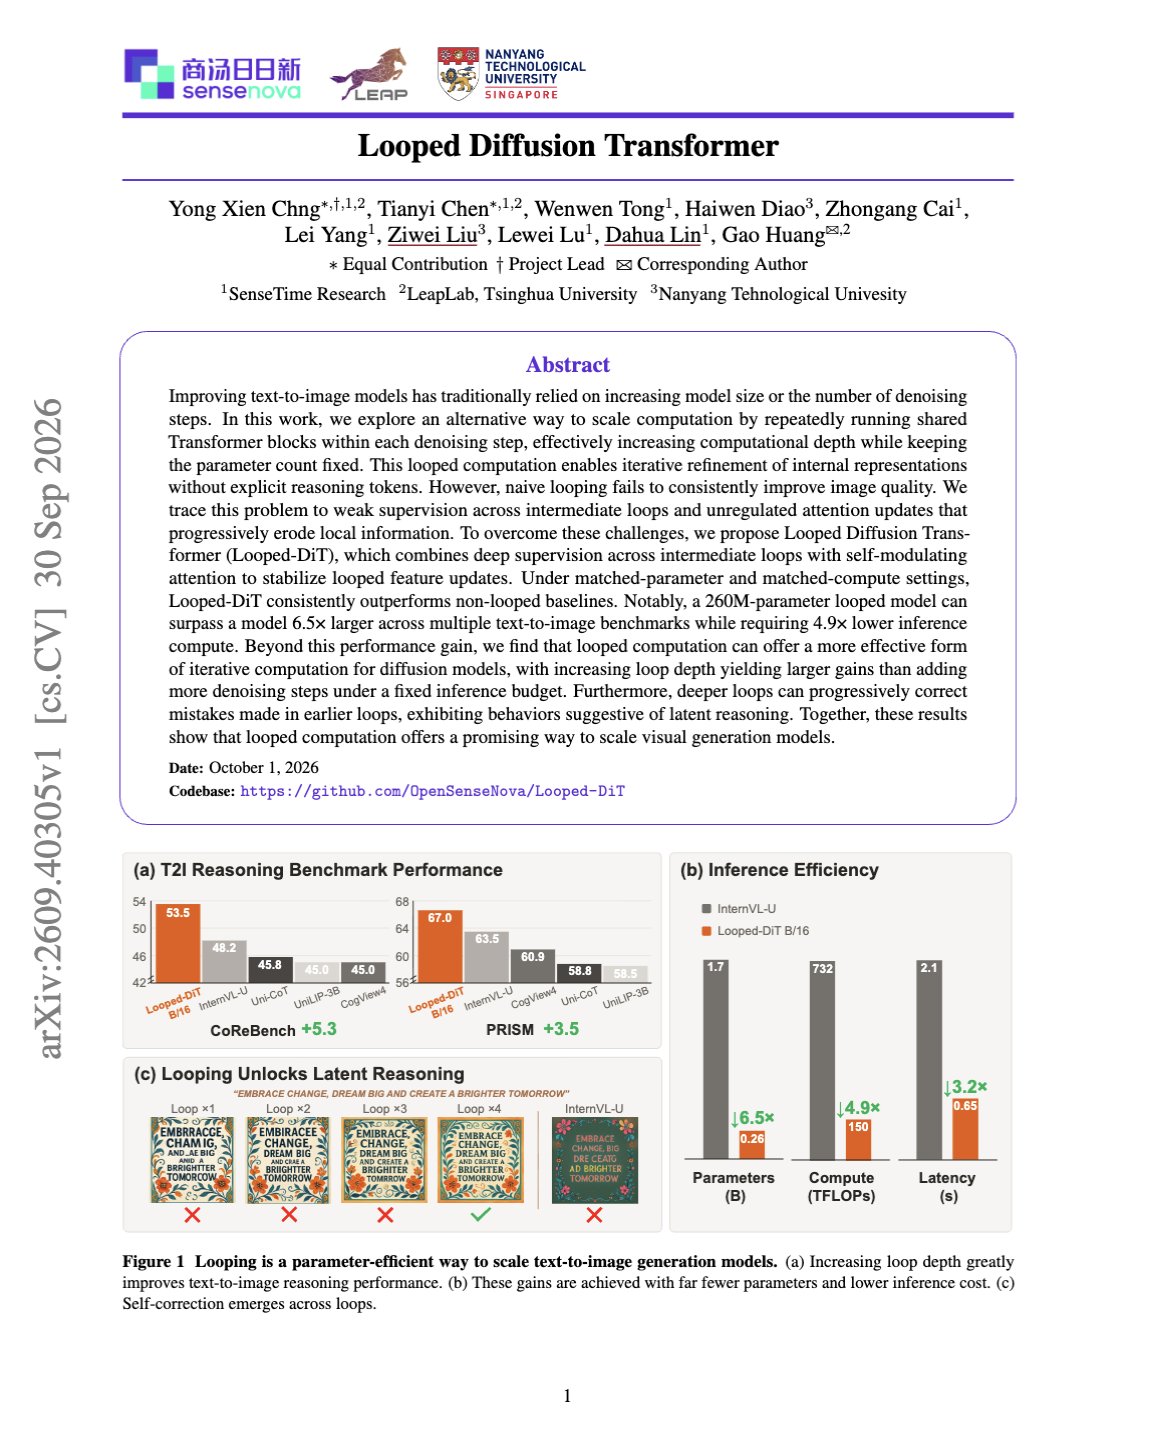
"Looped Diffusion Transformer" This new paper reuses the same Transformer blocks multiple times within each denoising step, repeatedly updating the hidden state to improve the prediction without increasing the model’s parameter count at inference-time. The found that a 260M
Looped Diffusion Transformer reuses blocks per denoising step
By
–