LA FILTRACIÓN DE LLaMA… Hace unos días Meta anunció un nuevo modelo del lenguaje tipo GPT-3, que siendo de menor tamaño (65B parameters), mostraba un rendimiento similar en muchas tareas. Y Meta quiso dar acceso libre a los investigadores. Y se ha filtrado… [1/n]
RESEARCH
-
MIT Researchers Train Logic-Aware Models Against Bias
By
–
Ask a LLM if they “think” they’re biased. Guess what they’ll say. MIT researchers trained logic-aware language models to mitigate stereotypical sentence reasoning bias using textual entailment: https://
bit.ly/3IR4OTK -
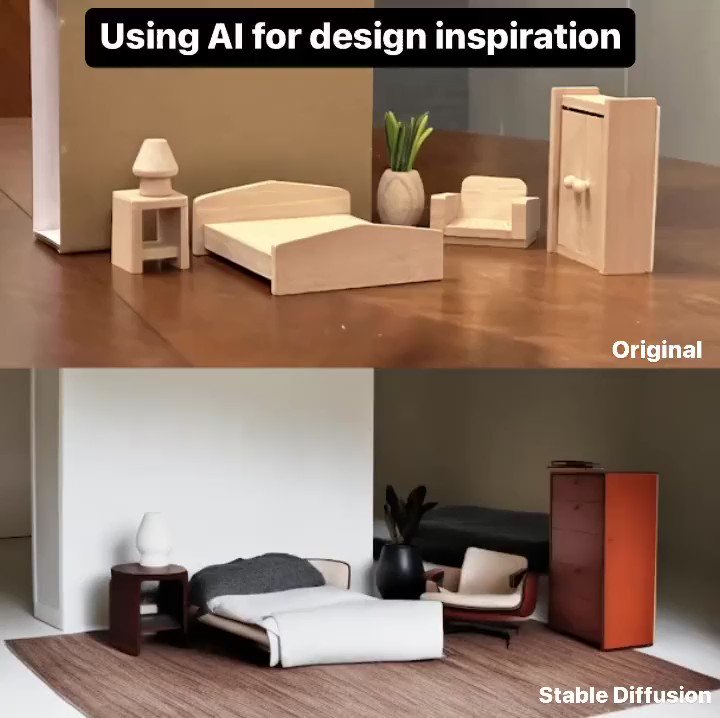
Using AI for Design Inspiration and Creative Applications
By
–
Using #AI for design inspiration
— Ronald van Loon (@Ronald_vanLoon) 4 mars 2023
via @karenxcheng#AI #MachineLearning #ArtificialIntelligence #ML #MI #DL #EmergingTech
cc: @ronald_vanloon @yvesmulkers @pbalakrishnarao @levie pic.twitter.com/qH3MEWAWkhUsing #AI for design inspiration
via @karenxcheng #AI #MachineLearning #ArtificialIntelligence #ML #MI #DL #EmergingTech cc: @ronald_vanloon @yvesmulkers @pbalakrishnarao @levie -
Berkeley AI Lab recognized as most impactful academic research
By
–
.
@berkeley_ai is the most impactful AI research lab in academia according to this metric. Go bears. https://
x.com/zetavector/sta
/zetavector/status/1631590029926494211
… -
One Step Closer to Human-Like Artificial Intelligence
By
–
One Step Closer to #AI With a Human-Like Mind
by @AlxMcFarland @UniteAi Read more: https://
buff.ly/3yabkkC #MachineLearning #ArtificialIntelligence #Technology #NeuralNetwork cc: @ronald_vanloon @kuriharan @pbalakrishnarao -
Master Deep Learning and Transfer Learning with Kaggle Grand Masters
By
–
Want better #DeepLearning results? Join #KaggleGrandMaster @ybabakhin
, Martin Barus & #MLEngineer #AdamValenta to level up your #TransferLearning skills + get tips on tuning #DeepLearningPipelines. See you at @FIT_CTU on 6.3.23 @ 18:00. http://
ow.ly/mRyY50N8UKe #HydrogenTorch -
Synthetic Data Benefits for Artificial Intelligence Development
By
–
Can Synthetic #Data Make #AI Better? Discover the Benefits of Synthetic #Data
by @joshinav @BBNTimes_en Learn more: https://
buff.ly/3tCfPlj #BigData #DataScience #MachineLearning cc: @wil_bielert @patrickgunz_ch @johnlegere -
RLHF Resources: OpenAI and Hugging Face Learning Materials
By
–
Here are some resources which you can further research on RLHF: Open AI's blog: http://
openai.com/blog/instructi
on-following/
…… Hugging Face blog: https://
huggingface.co/blog/rlhf -
SFT Model Training with Reward Function Iterations
By
–
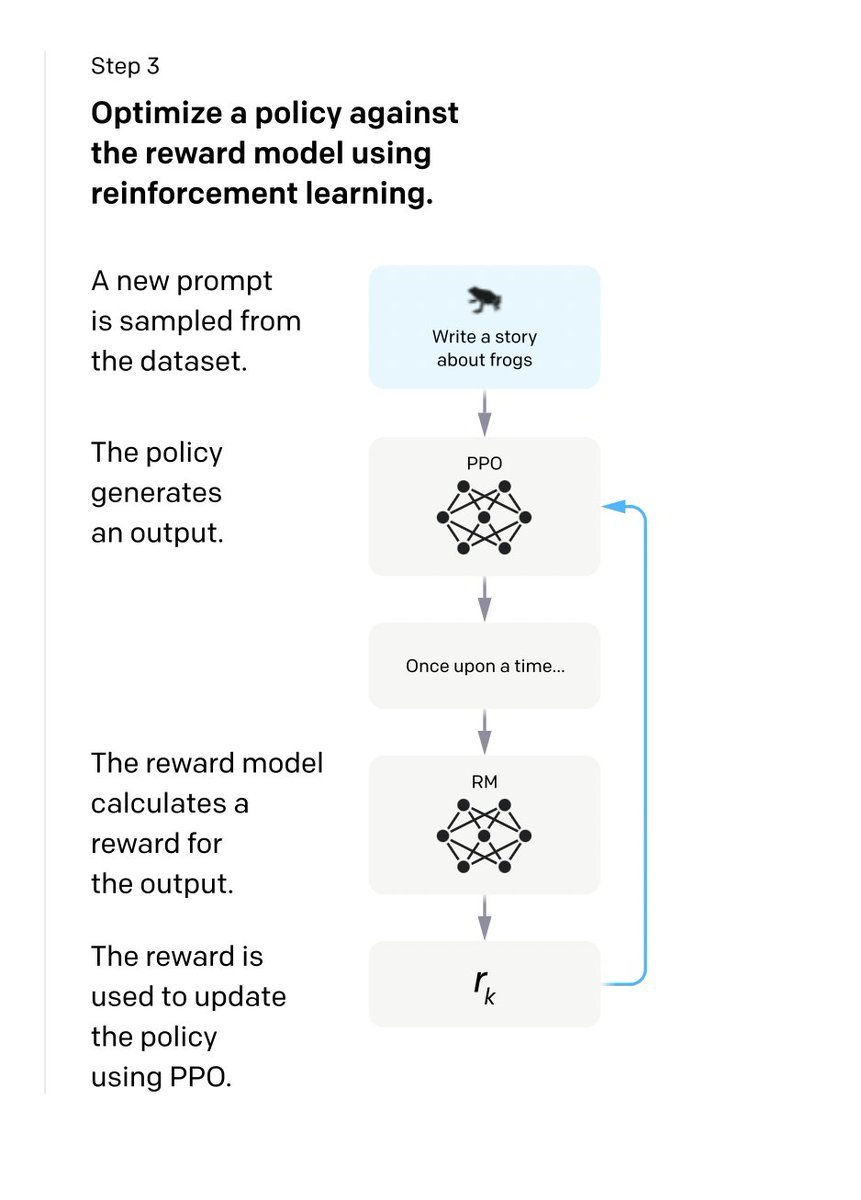
Step3: Sample a Prompt from the dataset, give that to the SFT model and get the generated response. Use the RF model to calculate the reward of the response and use that to update the Model. Iterate over it. That's how they have developed it. 9/9
-
Using Reward Models and PPO to Fine-tune Language Models
By
–
Now we don't need Humans to rank the responses. We have RM which will take care of that. The final step is to use this RM as a reward function and fine-tune the SFT model to maximize the reward using Proximal Policy Optimization which is Reinforcement Learning Algorithm 8/9