Markets, justice systems and the scientific method are all great examples of mechanism design. Now we need a mechanism to share knowledge and reason with it on a global scale. Web search and chatbots don't cut it.
RESEARCH
-

Neural Systems Understanding: Can It Explain the Brain?
By
–
Can an emerging field called ‘neural systems understanding’ explain the brain? https://
bit.ly/4bLIoju
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
AI Models Need Avogadro’s Number of Parameters to Be Real
By
–
You're not doing real AI if your model doesn't have at least Avogadro's number of parameters.
-
KV-Cache Optimization Techniques for Efficient LLM Inference
By
–
Follow @GiulianoLiguori for more on leveraging technology for business growth and insights from 'The Digital Edge' https://
bit.ly/3u4pILl. Read more about it https://
marktechpost.com/2024/07/28/thi
s-ai-paper-from-china-introduces-kv-cache-optimization-techniques-for-efficient-large-language-model-inference/
… -
Breakthrough in AI Technology Promises More Powerful and Accessible Solutions
By
–
5/5 Future Implications: This breakthrough could lead to more powerful and accessible AI technologies, driving further advancements in the field. #FutureOfAI #TechTrends
-
KV Cache Optimization Applications in NLP and Data Analysis
By
–
4/5 Practical Applications: From natural language processing to real-time data analysis, KV cache optimization has far-reaching implications across various AI applications. #NLP #AIApplications
-
LLM Optimizations Enhance Efficiency for Complex Data Tasks
By
–
3/5 Enhanced Efficiency: These optimizations allow LLMs to handle larger datasets and more complex tasks with greater speed and accuracy. #AIResearch #DataScience
-
KV Cache Optimization for Efficient LLM Inference
By
–
2/5 KV Cache Optimization: By improving key-value cache mechanisms, large language models (LLMs) can achieve more efficient inference, reducing latency and computational costs. #TechInnovation #MachineLearning
-
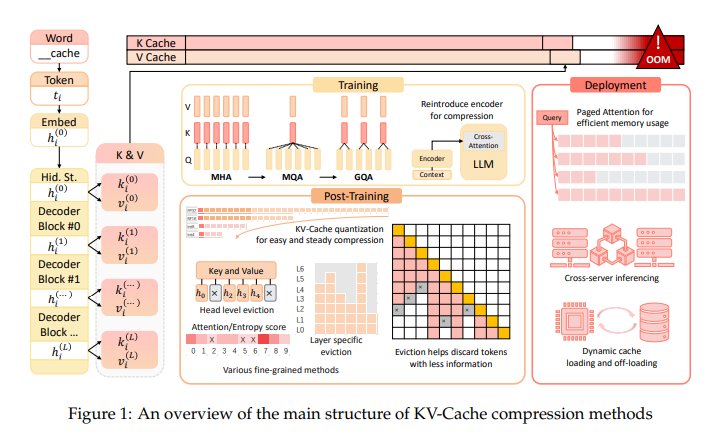
KV Cache Optimization for Efficient LLM Inference
By
–
1/5 Exploring KV Cache Optimization for Efficient LLM Inference This fascinating article from @MarkTechPost delves into AI advancements from China, focusing on optimizing KV cache techniques. #AI #LLM #Innovation
-
Measuring Information Gain: Luck versus Skill
By
–
It's based on measuring the change in information resulting from your choices. If there's an improvement in information higher than expected, you're lucky. If you choose something that is expected to increase information a lot, you're skillful.