if you find this area exciting, there is some fascinating concurrent work which examines the problem of inferring training *distributions* from LLMs: https://
x.com/iamgroot42/sta
tus/1934636691639472630
… (cc @chhaviyadav_ @kamalikac et al!)
RESEARCH
-
Inferring Training Distributions from Large Language Models
By
–
-
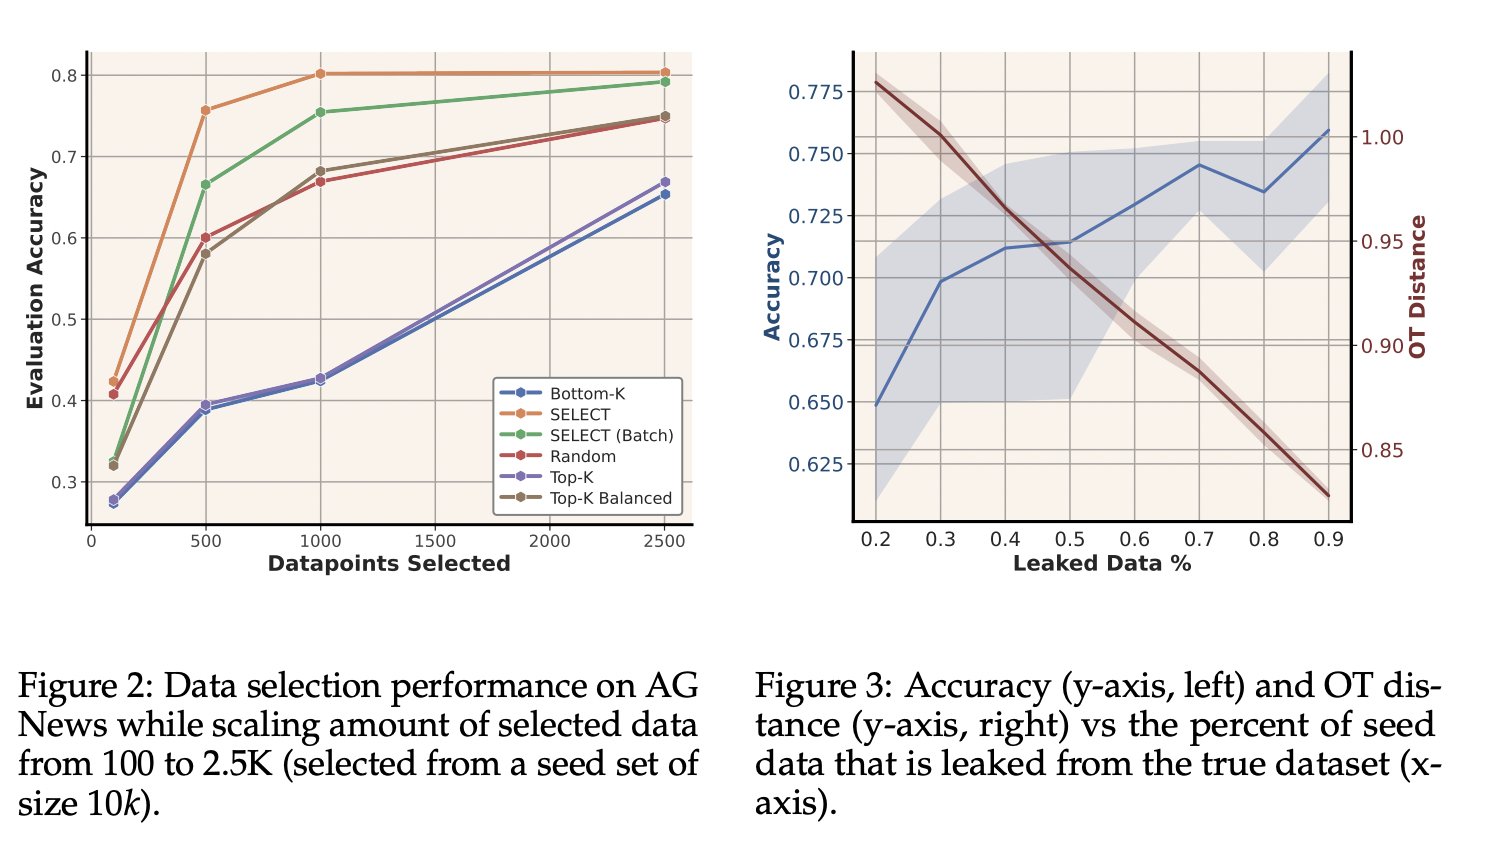
Embeddings Recovery with Minimal Data Requirements
By
–
there are some other nice properties: – we can get good performance with very little data
– we recover embeddings that "look" like the original dataset
– when some percentage of the original data is available, we generally select that data first -

AdamW Weight Decay Obfuscation Effects on Neural Networks
By
–
a random detail that I found cool is that AdamW seems to "obfuscate" weights a bit better than Adam or vanilla SGD guessing this is bc weight decay does something nonlinear during optimization, which decreases the amount of information available in weights
-

SELECT: Training Models with Limited Data Access
By
–
…but it works we try a bunch of baselines like selecting data based on likelihood or even the top-k per-class our method (SELECT) can train a model to similar performance, with access only to model weights and some web data
-
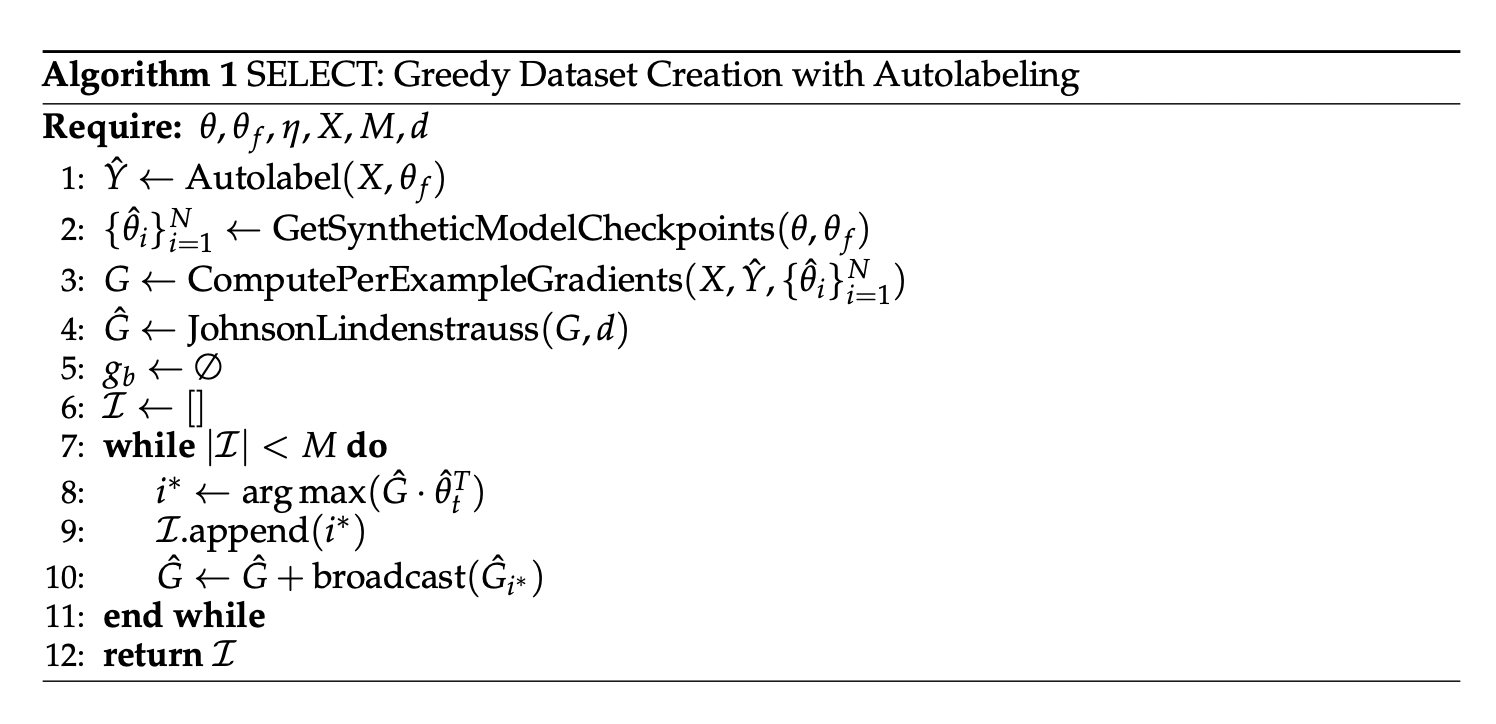
Scaling Per-Example Gradients: Algorithm Efficiency Improvements
By
–
our algorithm is a bit complicated, mostly because computing per-example gradients is hard to do at scale so we make some efficiency improvements:
– computing grads w vmap
– only using last-layer grads (which are still big, in the case of LMs)
– projecting them to a smaller dim -
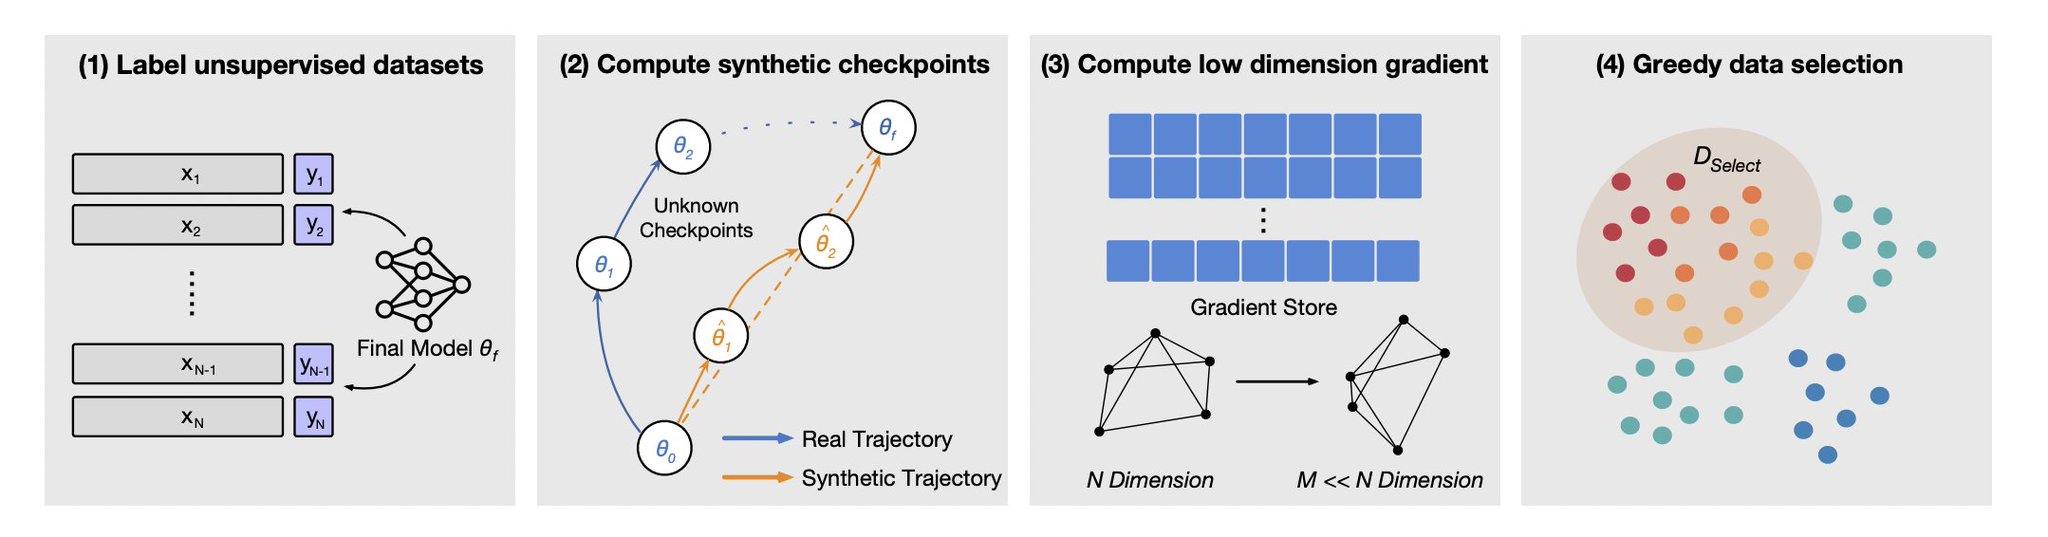
Finetuning AI Models: Gradient-Based Data Selection Strategy
By
–
to do this, you need TWO sets of model weights: the initial model and a finetune this is realistic. open-weights models often come with two checkpoints instead of one-shot generating data from weights, we select data from the web with gradients that point along the model diff
-
Reverse Engineering Training Data From Language Model Weights
By
–
NEW RESEARCH: Approximating Language Model Training Data from Weights ever wonder how much information is available in an open-weights model? DeepSeek R1 weights are 1.2 TB… what can we learn from all those bits? our method reverses LLM finetuning to recover data:
-
Top OpenAI Researchers Reject Meta’s $100M Offers Signaling AGI Race
By
–
Comment l’AGI pourrait-elle ne pas être proche, si même les meilleurs chercheurs d’OpenAI refusent des salaires de 100 millions de dollars de la part de meta ?
-
FastDiffusion course teaches comprehensive diffusion model knowledge
By
–
If you finish the fastdiffusion course you'll know a *lot* about diffusion 😀
-
Karpathy’s Presentation: Must-Read AI Content
By
–
Thank you @karpathy and @garrytan for sharing this incredible presentation. It's the best thing I've read all year. You can download Andrej's full presentation here: