India ranks #1 globally in AI skill penetration (Stanford AI Index 2024). Score of 2.8, ahead of the US at 2.2. We have the talent. Now we have the compute. The only direction is forward. (7/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha
RESEARCH
-
Sarvam-105B: Indian AI model outperforms DeepSeek-R1
By
–
Sarvam-105B trained in India, on Indian data, on Indian infrastructure. Scored 96.7 on AIME 2025. Outperformed DeepSeek-R1 on certain benchmarks. A model worth BILLIONS — built for ₹246 crore. (6/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha
-
Indian AI Companies Develop 105B LLM and Multimodal Models
By
–
What's running on these GPUs? #SarvamAI building a 105B parameter model. #BharatGen training multimodal LLMs. http://
Gnani.AI building voice models for 12 Indian languages. All Made in India. (5/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 -
India launches 60% discounted GPU access for startups researchers
By
–
The rate? ₹65/hour for a GPU. Compare that to the global rate of ₹150-180/hour for an H100. That's a 60% discount. For any startup, PhD student, MSME, or researcher in India. (4/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha @GoI_MeitY
-
Focus Groups Limiting Innovation: The Faster Horses Problem
By
–
That's what happens when your focus group is from the 1880s and they tell you to build faster horses
-

Anima Anandkumar Joins UN Scientific Advisory Board
By
–
✨ Introducing the members of @ScienceBoard_UN! 🌍 @AnimaAnandkumar is the Bren Professor at @Caltech, previously at @nvidia and @awscloud. She is a leading voice on artificial intelligence, machine learning, and AI-for-science. 📣 Read more: tinyurl.com/2nb4w55s
→ View original post on X — @animaanandkumar, 2026-03-12 13:00 UTC
-

Sax Institute Uses AI Analytics for Public Health Research
By
–
Discover how the Sax Institute uses analytics and AI to securely connect researchers with the data they need. Now, evidence can move faster from research into real‑world public health action http://
2.sas.com/6015B6E6w7 -
Practical Linear Algebra for Data Science with Python Applications
By
–
Practical Linear Algebra for #DataScience — From Core Concepts to Applications Using #Python — http://
amzn.to/3WWJKR4
————
#DataScientist #AI #ML #MachineLearning #Mathematics -
Naive Bayes Classification Explained with Python Code and Resources
By
–
Naive Bayes Classification, explained with Python code: https://
github.com/taspinar/siml/
blob/master/notebooks/Naive_Bayes.ipynb
…
++
Learn more in this book: http://
amzn.to/312hAHF
————
#DataScience #MachineLearning #AI #ML #Algorithms #Statistics #DataScientist #Mathematics -
LLM2Vec-Gen: Frozen LLMs Generate Better Embeddings Through Reasoning
By
–
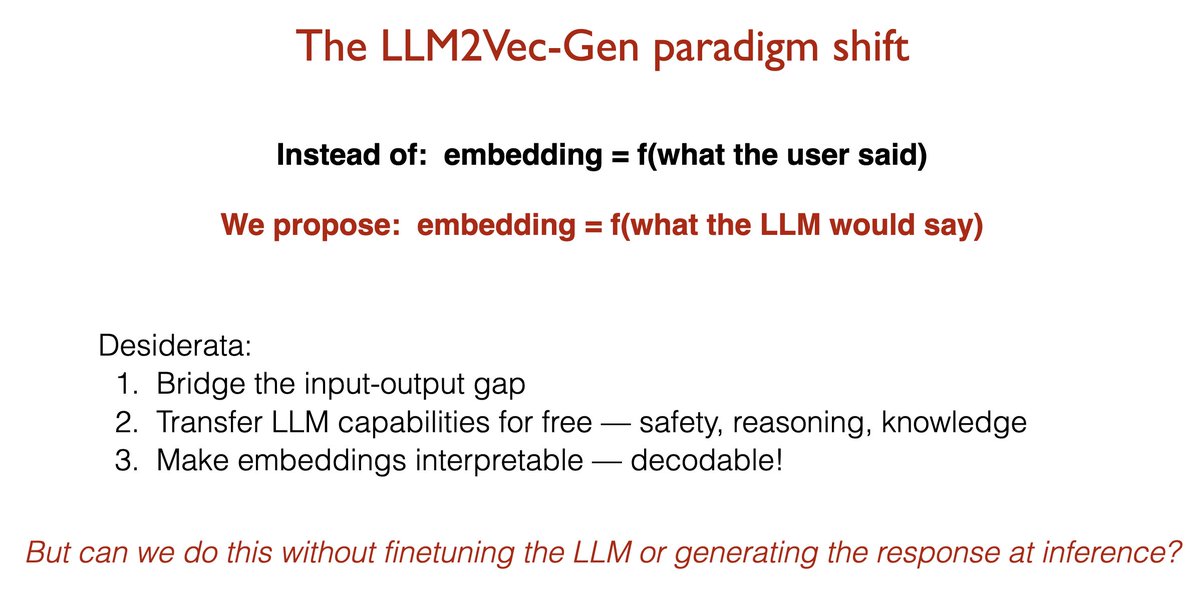
LLM2Vec-Gen represents a major paradigm shift for embeddings/retrieval. Why encode the query when the LLM already knows what to look for and can directly produce an embedding for it? Best part: it’s self-supervised, and it does all of this while the LLM remains completely frozen. Think about it: "solve x² + 3x − 4 = 0" has zero reasoning in it. But the LLM's response does. By encoding the response, the embedding captures the reasoning — and the better the LLM reasons, the better the embedding. This is why our results scale with model size. As LLMs get smarter, our embeddings automatically get better. LLM2Vec-Gen is also the first demonstration of the promise of @ylecun's JEPA for text embeddings. The alignment loss is JEPA — predict in representation space, not token space. The reconstruction loss goes beyond — it keeps embeddings decodable. This paradigm shift opens new frontiers: 🔬 Can we build a full JEPA for language where the teacher and student are the same LLM? ⚡ Can LLMs reason in compressed space without ever generating text? 🤖 Can agents reason in compression tokens and carry that directly into retrieval? 💬 Can agents talk to each other in compression tokens instead of text — dense, fast, and still human-readable? LLM2Vec-Gen is a first step toward all four. Vaibhav Adlakha (@vaibhav_adlakha) Your LLM already knows the answer. Why is your embedding model still encoding the question? 🚨Introducing LLM2Vec-Gen: your frozen LLM generates the answer's embedding in a single forward pass — without ever generating the answer. Not only that, the frozen LLM can decode the embedding back into text. 🏆 SOTA self-supervised embeddings 🛡️ Free transfer of instruction-following, safety, and reasoning — https://nitter.net/vaibhav_adlakha/status/2032065008603951187#m
→ View original post on X — @hugo_larochelle, 2026-03-12 12:37 UTC