Real-Time Generation with Pyramid Attention Broadcast discuss: https://
huggingface.co/papers/2408.12
588
… We present Pyramid Attention Broadcast (PAB), a real-time, high quality and training-free approach for DiT-based video generation. Our method is founded on the observation that
MULTIMODAL AI
-

Real-Time Video Generation with Pyramid Attention Broadcast
By
–
-
Show-o: Unified Transformer for Multimodal Understanding and Generation
By
–
Show-o
— AK (@_akhaliq) 23 août 2024
One Single Transformer to Unify Multimodal Understanding and Generation
discuss: https://t.co/haGX7CKOYp
We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies… pic.twitter.com/UosIpqiuYHShow-o One Single Transformer to Unify Multimodal Understanding and Generation discuss: https://
huggingface.co/papers/2408.12
528
… We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies -

Scalable Autoregressive Image Generation with Mamba Architecture
By
–
Scalable Autoregressive Image Generation with Mamba discuss: https://
huggingface.co/papers/2408.12
245
… model: https://
huggingface.co/hp-l33/aim We introduce AiM, an autoregressive (AR) image generative model based on Mamba architecture. AiM employs Mamba, a novel state-space model characterized by its -
Meta Introduces Sapiens: Foundation Models for Human Vision Tasks
By
–
Meta presents Sapiens
— AK (@_akhaliq) 23 août 2024
Foundation for Human Vision Models
discuss: https://t.co/0hDjPL6p4T
We present Sapiens, a family of models for four fundamental human-centric vision tasks – 2D pose estimation, body-part segmentation, depth estimation, and surface normal prediction. Our… pic.twitter.com/gghxSKylcPMeta presents Sapiens Foundation for Human Vision Models discuss: https://
huggingface.co/papers/2408.12
569
… We present Sapiens, a family of models for four fundamental human-centric vision tasks – 2D pose estimation, body-part segmentation, depth estimation, and surface normal prediction. Our -

Video-Foley: Two-Stage Video-To-Sound Generation for Temporal Events
By
–
-Foley Two-Stage Video-To-Sound Generation via Temporal Event Condition For Foley Sound discuss: https://
huggingface.co/papers/2408.11
915
… Foley sound synthesis is crucial for multimedia production, enhancing user experience by synchronizing audio and video both temporally and -
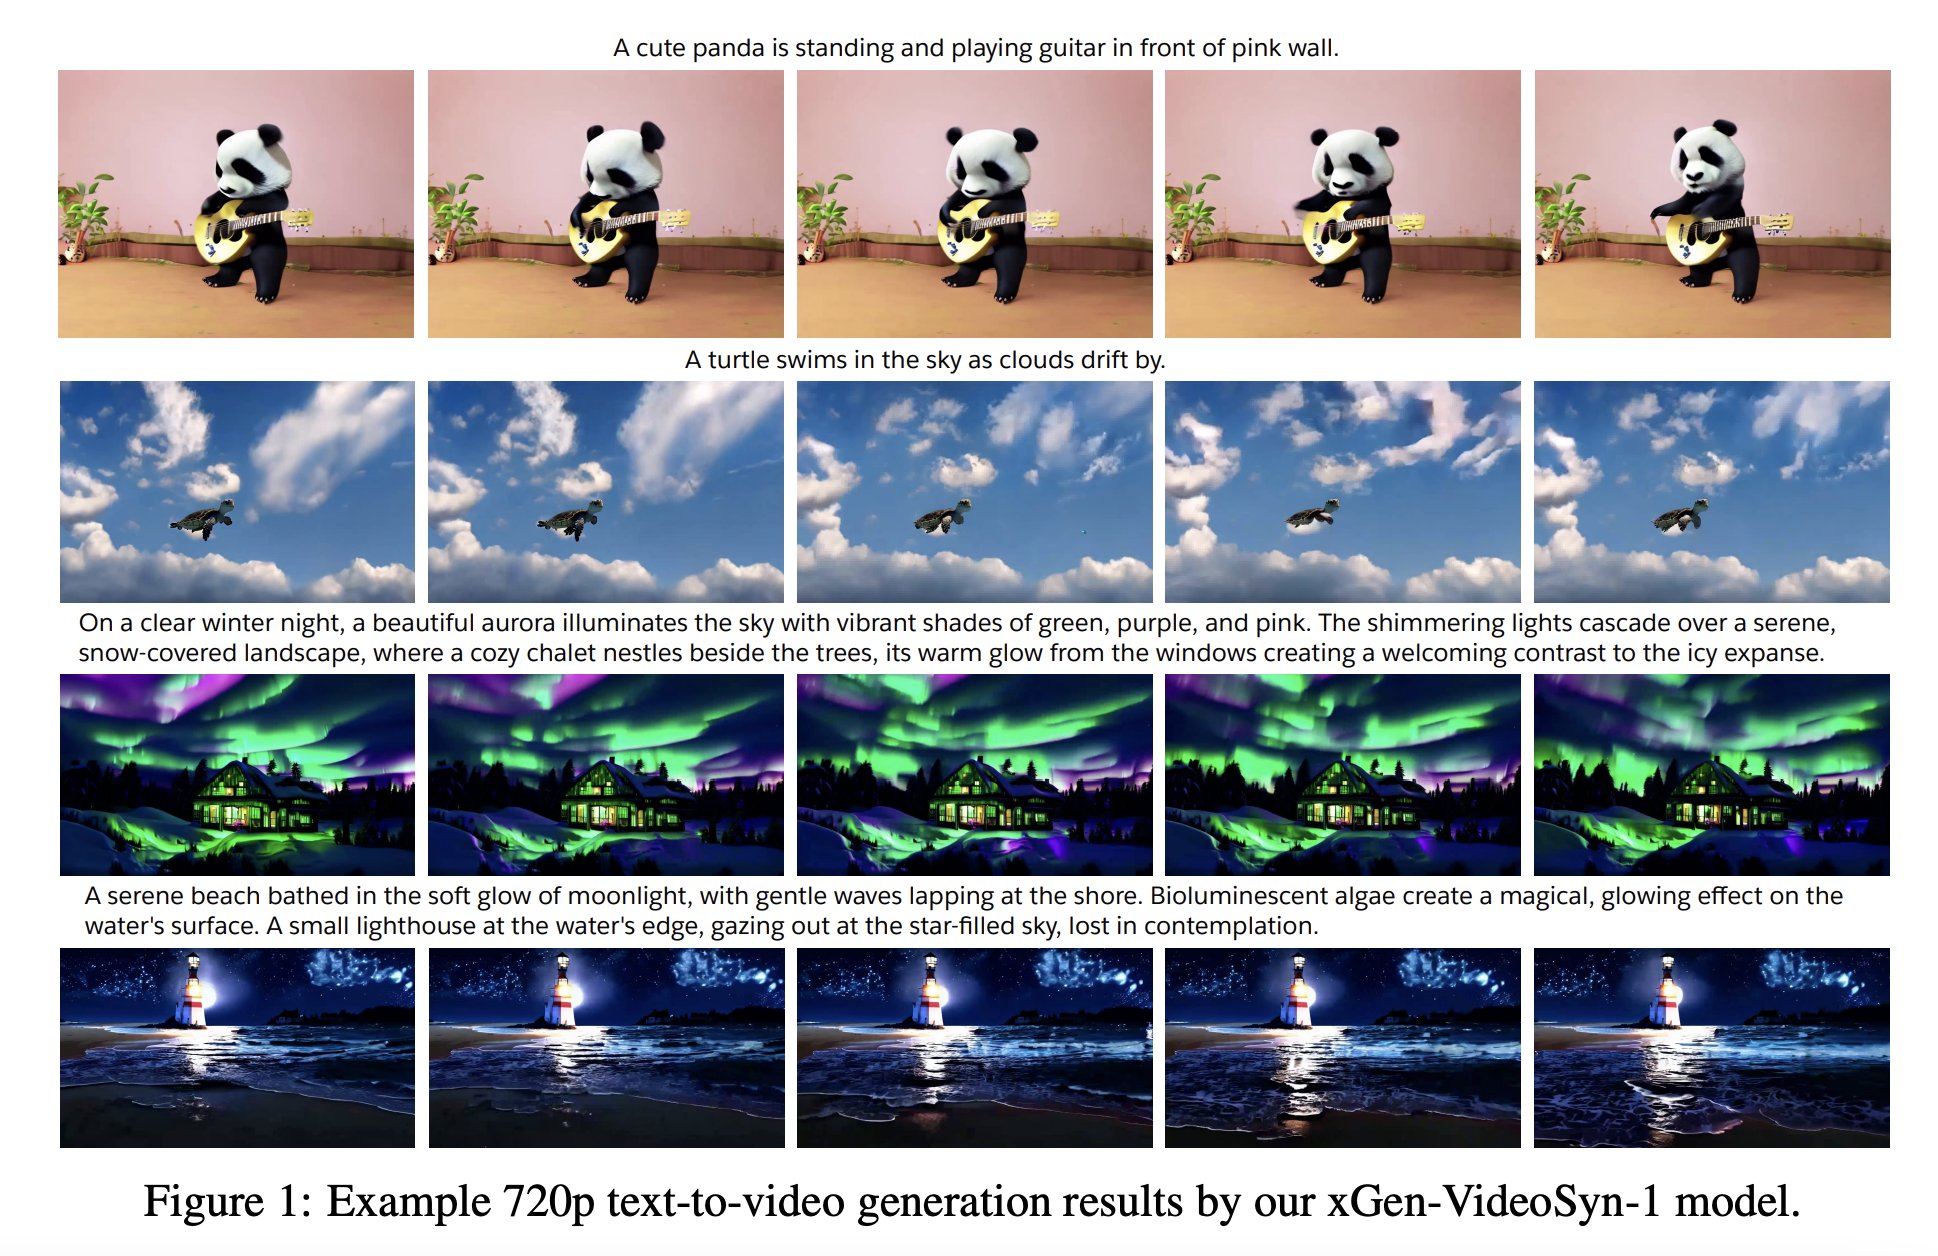
Salesforce xGen-VideoSyn-1: Advanced Text-to-Video Synthesis Model
By
–
Salesforce presents xGen-VideoSyn-1 High-fidelity Text-to-Video Synthesis with Compressed Representations discuss: https://
huggingface.co/papers/2408.12
590
… We present xGen-VideoSyn-1, a text-to-video (T2V) generation model capable of producing realistic scenes from textual descriptions. -

Midjourney tests new ‘Describe’ feature for image prompting
By
–
Midjourney is experimenting with Describe feature It gives 4 different prompts based on the uploaded image. Not sure if it is available to subscribers but it is an "Experimental" feature.
-
Midjourney, OpenAI, Microsoft Launch Major AI Updates
By
–
Big News:
• Midjourney: New editing tool and 25 free images for new users.
• OpenAI: Fine-tune GPT-4o with 1M free tokens/day till Sept 23.
• Microsoft: 3 new Phi-3.5 models with near state-of-the-art performance. #Microsoft #OpenAI #Midjourney #ChatGPT #AIImages -
Tutorial on using AI image generation with pose control
By
–
Étape 2 : ajoutez des prompts de texte, des préréglages, téléchargez une image pour le contrôle de la pose
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 22 août 2024
⁃ cliquez sur pose image
⁃ Ajoutez un prompt
⁃ activez le mode Raw
Et cliquez sur générer https://t.co/wMupcSMEZP pic.twitter.com/DKNTxGvlzPÉtape 2 : ajoutez des prompts de texte, des préréglages, téléchargez une image pour le contrôle de la pose ⁃ cliquez sur pose image ⁃ Ajoutez un prompt ⁃ activez le mode Raw Et cliquez sur générer http://
link.nex.art/deep -
NEX AI Multimodal Image Generation and Editing Tool
By
–
J’utilise NEX / @_NEXOfficial
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 22 août 2024
Générez ce que vous voulez comme vous le souhaitez avec une variété de commandes multimodales.
Affinez la pose, la couleur et les personnages.
Essayez gratuitement : https://t.co/wMupcSNcPn pic.twitter.com/0UyFoIWFm4J’utilise NEX / @_NEXOfficial Générez ce que vous voulez comme vous le souhaitez avec une variété de commandes multimodales. Affinez la pose, la couleur et les personnages. Essayez gratuitement : http://
link.nex.art/deep